
Introduction
If at any time you have participated in data science contests, you should be aware of the critical role that ensemble modeling plays. In reality, Ensemble modeling is said to offer one of the most compelling ways to build highly accurate predictive models. The availability of bagging and reinforcement Algorithms further embellish this method to produce an astonishing level of precision.
Therefore, the next time you create a predictive model, consider using this algorithm. I would definitely pat myself on the back for this suggestion.. Y, if you already master this method, genial. I'd love to hear your expertise on ensemble modeling in the comment section below..
Otherwise, I share some of the most frequently asked questions about ensemble modeling. If at any time you want to examine anyone's knowledge of the set, you may dare to ask these questions and check your knowledge. At the same time, these are some of the easiest questions, so you can't dare to be wrong.
What are the common questions (associated with ensemble models)?
After analyzing several data science forums, I have identified the 5 Common Questions Associated with Ensemble Modeling. These questions are very relevant to data scientists who are new to ensemble modeling.. Here are the questions:
- What is a set model?
- What are bagging, reinforcement and stacking?
- Can we assemble several models of the same ML algorithm?
- How can we identify the weights of different models?
- What are the benefits of the ensemble model?
Let's analyze each question in detail.
1. What is a set model?
Let's try to understand it by solving a ranking challenge.
Trouble: set rules for sorting spam emails
Solution: We can generate several rules for the classification of spam emails, let's see some of them:
- Unwanted mail
- Have a total extension of less than 20 words.
- Have only image (promotional images)
- Have specific keywords like “earn money and grow” Y “reduce your fat”
- More words spelled in the email
- No spam
- DataPeaker domain email
- Email from family members or anyone in the email address book
Above, I have listed some common rules for filtering spam emails. Do you think all these rules individually can predict the correct class?
Most of us would say no, And that's true! The combination of these rules will provide a solid prediction compared to the forecast made by individual rules.. This is the principle of ensemble modeling. The set model combines several 'individual models’ (multiple) together and offers superior predictive power.
If you want to relate this to real life, a group of people is likely to make better decisions compared to individuals, especially when group members come from multiple backgrounds. The same goes for machine learning. Simply, un conjunto es una técnica de supervised learningSupervised learning is a machine learning approach where a model is trained using a set of labeled data. Each input in the dataset is associated with a known output, allowing the model to learn to predict outcomes for new inputs. This method is widely used in applications such as image classification, speech recognition and trend prediction, highlighting its importance in... para combinar múltiples students / weak models to produce a strong apprentice. The assembly model works best when we assemble models with low correlation.
A good example of how ensemble methods are commonly used to solve data science problems is the random forest algorithm (that has several CART models). It works better compared to the individual CART model when categorizing a new object where each tree gives “votes” for that class and the forest chooses the classification that has the most votes (over all the trees in the forest). In case of regression, takes the average of outputs from different trees.
You can also follow this post “Set Learning Basics Explained in Plain English” to learn more about ensemble modeling.
2. What are bagging, reinforcement and stacking?
Let's look at each of these individually and try to understand the differences between these terms.:
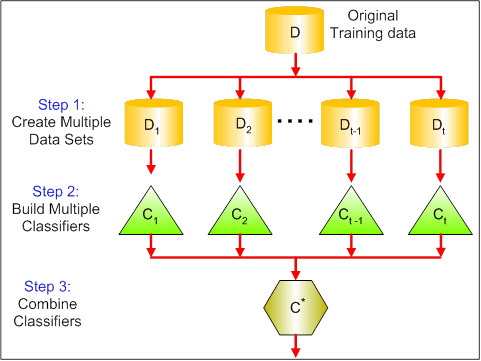
Harpillera (Bootstrap Aggregating) is a set method. First, creamos muestras aleatorias del conjunto de datos de trainingTraining is a systematic process designed to improve skills, physical knowledge or abilities. It is applied in various areas, like sport, Education and professional development. An effective training program includes goal planning, regular practice and evaluation of progress. Adaptation to individual needs and motivation are key factors in achieving successful and sustainable results in any discipline.... (subsets of the training data set). After, we construct a classifier for each sample. In summary, the results of these multiple classifiers are combined through average or majority voting. Bagging helps reduce variance error.
Impulse provides sequential learning of predictors. The first predictor is learned across the entire data set, while the following is learned in the training set based on the performance of the previous.. That start by classifying the original data set and giving the same weight to each observation. If classes are incorrectly predicted using the first student, then the missing classified observation is given greater weight. Being an iterative procedure, continues adding classifier learners until a limit on the number of models or precision is met. Impulse has shown better predictive accuracy than bagging, but it also tends to overfit the training data. 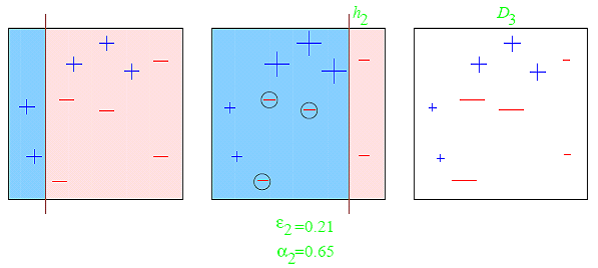
The most common example of booster is AdaBoost and Gradient Boosting. You can also check these posts for more information about how to boost algorithms..
Piled up works in two phases. First, we use multiple base classifiers to predict the class. Secondly, a new student is used to combine their predictions in order to reduce the generalization error. 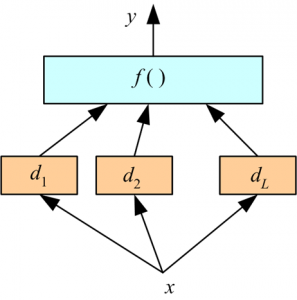
3. Can we assemble multiple models of the same ML algorithm?
Yes, we can combine multiple models of the same ML algorithms, but combining multiple predictions generated by different algorithms regularly would give you better predictions. It is due to diversification or independent nature compared to each other. As an example, the predictions of a random forest, a KNN and a Naive Bayes can be combined to create a more robust final set of predictions compared to combining three random forest models. The key to creating a powerful ensemble is the diversity of models. A set with two techniques that are very equivalent in nature will perform poorly than a more diverse set of models..
Example: Let's say we have three models (A, B y C). A, B and C have a prediction precision of the 85%, 80% Y 55% respectively. But A and B are found to be highly correlated when C is poorly correlated with A and B. Should we combine A and B? No, We should not, because these models are highly correlated. Therefore, we will not combine these two, since this set will not help reduce any generalization errors. I would rather combine A and C or B and C.
4. How can we identify the weights of different models for the set?
One of the most common challenges with ensemble modeling is finding optimal weights for base ensemble models. In general, we assume the same weight for all models and take the average of the predictions. But, Is this the best way to face this challenge?
There are several methods to find the optimal weight to combine all the basic students. These methods provide a fair understanding of how to find the correct weight. Then, I list some of the methods:
- Find the collinearity between the base students and based on this table, then identify base models to assemble. Thereafter, look at the cross-validation score (score ratio) of the identified base models to find the weight.
- Find the algorithm to return the optimal weight for basic students. Puede consultar el post Cómo hallar pesos óptimos de aprendices de conjunto usando una red neuronalNeural networks are computational models inspired by the functioning of the human brain. They use structures known as artificial neurons to process and learn from data. These networks are fundamental in the field of artificial intelligence, enabling significant advancements in tasks such as image recognition, Natural Language Processing and Time Series Prediction, among others. Their ability to learn complex patterns makes them powerful tools.. para ver el método para hallar el peso óptimo.
- We can also solve the same problem using methods like:
You can also see the winning response from the data science contests / Kaggle to understand other methods to meet this challenge.
5. What are the benefits of the ensemble model?
There are two main advantages of Ensemble models:
- Best prediction
- More stable model
The aggregate opinion of various models is less noisy than that of other models. In finance, call “Diversification”: una cartera mixta de muchas acciones será mucho menos variableIn statistics and mathematics, a "variable" is a symbol that represents a value that can change or vary. There are different types of variables, and qualitative, that describe non-numerical characteristics, and quantitative, representing numerical quantities. Variables are fundamental in experiments and studies, since they allow the analysis of relationships and patterns between different elements, facilitating the understanding of complex phenomena.... que una sola de las acciones. This is also why your models will be better with sets of models rather than individual ones.. One of the precautions with ensemble models is that they fit too tightly., even though bagging takes care of it to a great extent.
Final note
In this post, we have analyzed the 5 Frequently asked questions about Ensemble models. By answering these questions, we have discussed about "Ensemble Models", "Ensemble methods", "Why should we assemble multiple models?”, "Methods to identify the optimal weight for the set" and to finish "Benefits". I suggest you look at the 5 best data science quiz solutions and see their joint approaches for better understanding and lots of practice. It will help you understand what works and what doesn't.
Was this post helpful to you? Have you tried anything else to find optimal weights or identify the appropriate base student? I'll be happy to hear from you in the comment section below..





