
Introduction
E-commerce has revolutionized the way we shop. That phone you've been saving to buy for months? It's just a search and a few clicks away. Items are delivered within days (Sometimes even the next day!).
For online retailers, there are no restrictions related to inventory management or space management. They can sell as many different products as they want. Physical stores can keep only a limited number of products due to the limited space they have available.
I remember when I used to order books at my local bookstore, and it used to take more than a week to arrive. It seems like a story from ancient times now!
Source: http://www.yeebaplay.com.br
But online shopping has its own caveats. One of the biggest challenges is verifying the authenticity of a product. Is it as good as advertised on the ecommerce site? Will the product last more than a year? Are the opinions of other customers really true or are they misleading advertising? These are important questions customers should ask before wasting their money.
This is a great place to experiment and apply natural language processing techniques. (PNL). This article will help you understand the importance of taking advantage of online product reviews with the help of Topic Modeling.
Check out the articles below in case you need a quick refresher on theme modeling:
Table of Contents
- Importance of online reviews
- Problem Statement
- Why is the modeling of themes for this task?
- Python implementation
- Read data
- Data preprocessing
- Building an LDA model
- Viewing themes
- Other methods to take advantage of online reviews
- Whats Next?
Importance of online reviews
Some days ago, I jumped into e-commerce and bought a smartphone online. It was within my budget and had a decent rating of 4.5 about 5.
Unfortunately, it turned out to be a bad decision as the backup battery was way below average. I didn't check the product reviews and made a hasty decision to buy it based solely on its ratings. And I know I'm not the only one who made this mistake!
Ratings alone do not give a complete picture of the products we want to buy, as I discovered to my detriment. Therefore, As a precautionary measure, I always recommend people to read the reviews of a product before deciding whether to buy it or not.
But then an interesting problem arises. What if the number of reviews is hundreds or thousands? It's just not feasible to go through all those reviews, truth? And this is where natural language processing triumphs.
State the problem statement
A problem statement is the seed from which your analysis sprouts. Therefore, it is really important to have a solid problem statement, clear and well defined.

How can we analyze a large number of online reviews using natural language processing (NLP)? Let's define this problem.
Online product reviews are a great source of information for consumers. From the sellers point of view, online reviews can be used to evaluate consumer feedback on the products or services they sell. But nevertheless, since these online reviews are often overwhelming in terms of numbers and information, an intelligent system, able to find key information (topics) from these reviews, will be of great help to both consumers and sellers. This system will have two purposes:
- Let consumers quickly extract key topics covered by reviews without having to go through all of them.
- Help sellers / retailers to get consumer feedback in the form of topics (drawn from consumer reviews)
To solve this task, we will use the concept of Theme Modeling (LDA) in Amazon Automotive Review data. You can download it from this Link. Similar data sets can be found for other product categories here.
Why should you use theme modeling for this task?
As the name suggests, topic modeling is a process of automatically identifying topics present in a text object and deriving hidden patterns exhibited by a text corpus. Theme templates are very useful for multiple purposes, including:
- Grouping of documents
- Organize large blocks of textual data
- Unstructured Text Information Retrieval
- Feature selection
A good theme model, when training in some text about the stock market, should result in topics like “offer”, “negotiation”, “dividend”, “exchange”, etc. The following image illustrates how a typical theme model works:

In our case, instead of text documents, we have thousands of product reviews online for the items listed in the 'Automotive' category. Our goal here is to extract a certain number of groups of important words from the reviews.. These groups of words are basically the topics that would help determine what consumers are really talking about in reviews..

Python implementation
In this section, we'll activate our Jupyter notebooks (Or any other IDE you use for Python!). Here we will work on the problem statement defined above to extract useful topics from our online reviews dataset using the concept of latent Dirichlet mapping. (LDA).
Note: As I mentioned in the introduction, I highly recommend reading this article to understand what LDA is and how it works.
Let's load all the necessary libraries first:
import nltk
from nltk import FreqDist
nltk.download('stopwords') # run this one time
import pandas as pd
pd.set_option("display.max_colwidth", 200)
import numpy as np
import re
import spacy

import gensim
from gensim import corpora

# libraries for visualization
import pyLDAvis
import pyLDAvis.gensim
import matplotlib.pyplot as plt
import seaborn as sns
%matplotlib inline
To import the data, first extract the data to your working directory and then use the read_json () pandas function to read it in a pandas data frame.
df = pd.read_json('Automotive_5.json', lines=True)
df.head()
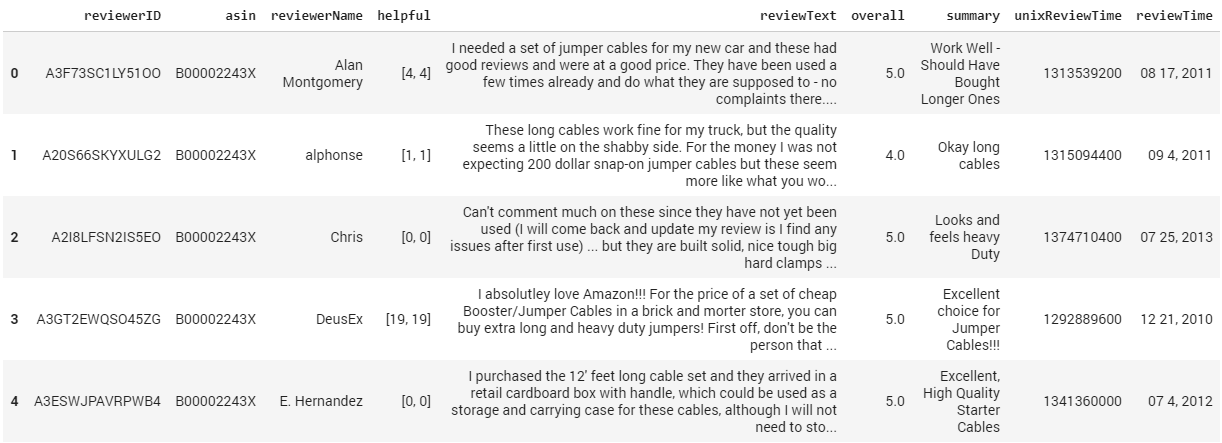
As you can see, the data contains the following columns:
- reviewerID – ID del revisor
- like in – Product ID
- reviewerName – reviewer name
- helpful – review utility rating, for instance, 2/3
- reviewText – review text
- in general – product rating
- abstract – review summary
- unixReviewTime – review time (unix hour)
- review time – review time (without processing)
For the scope of our analysis and this article, we will only use the reviews column, namely, reviewText.
Data preprocessing
Preprocessing and cleaning of data is an important step before any text mining task, in this step, we will eliminate the punctuation marks, the stopwords and we will normalize the revisions as much as possible. After each preprocessing step, it is good practice to check the most frequent words in the data. Therefore, definamos una función que trazaría un bar graphicThe bar chart is a visual representation of data that uses rectangular bars to show comparisons between different categories. Each bar represents a value and its length is proportional to it. This type of chart is useful for visualizing and analyzing trends, facilitating the interpretation of quantitative information. It is widely used in various disciplines, such as statistics, Marketing and research, due to its simplicity and effectiveness.... de n palabras más frecuentes en los datos.
# function to plot most frequent terms
def freq_words(x, terms = 30):
  all_words=" ".join([text for text in x])
  all_words = all_words.split()

  fdist = FreqDist(all_words)
  words_df = pd.DataFrame({'word':list(fdist.keys()), 'count':list(fdist.values())})

  # selecting top 20 most frequent words
  d = words_df.nlargest(columns="count", n = terms)
  plt.figure(figsize=(20,5))
  ax = sns.barplot(data=d, x= "word", y = "count")
  ax.set(ylabel="Count")
  plt.show()
Let's give this feature a try and find out what the most common words are in our review dataset.
freq_words(df['reviewText'])
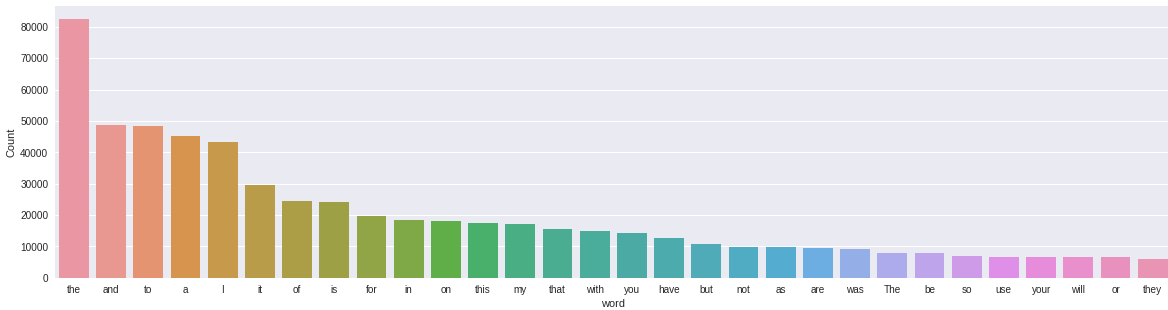
The most common words are “the”, “Y”, “to”, etc. These words are not that important to our task and they do not tell any story.. We have to get rid of these kinds of words. Before that, let's remove scores and numbers from our text data.
# remove unwanted characters, numbers and symbols
df['reviewText'] = df['reviewText'].str.replace("[^ a-zA-Z #]", " ")
Let's try to eliminate the stop words and the short words (<2 letters) of reviews.
from nltk.corpus import stopwords
stop_words = stopwords.words('english')
# function to remove stopwords
def remove_stopwords(rev):
    rev_new = " ".join([i for i in rev if i not in stop_words])
    return rev_new

# remove short words (length < 3)
df['reviewText'] = df['reviewText'].apply(lambda x: ' '.join([w for w in x.split() if len(w)>2]))

# remove stopwords from the text
reviews = [remove_stopwords(r.split()) for r in df['reviewText']]

# make entire text lowercase
reviews = [r.lower() for r in reviews]
Let's trace the most frequent words again and see if the most significant words have come out.
freq_words(reviews, 35)
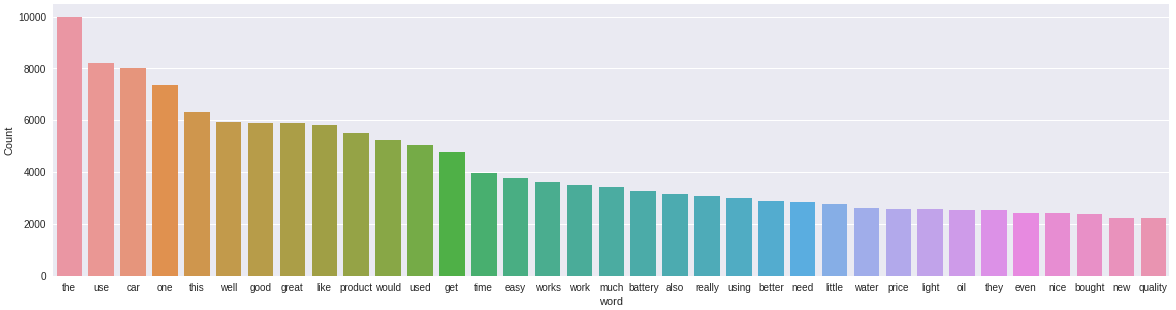
We can see some improvements here. Terms such as “battery”, “price”, “product”, “oil”, which are quite relevant to the Automotive category. But nevertheless, we still have neutral terms like 'the', 'this', 'much', 'them’ that are not so relevant.
To further remove noise from text, we can use the lemmatization from the spaCy library. Reduce any given word to its basic form, thus reducing multiple forms of a word to a single word.
!python -m spacy download en # one time run
nlp = spacy.load('en', disable=['parser', 'ner'])

def lemmatization(texts, tags=['NOUN', 'ADJ']): # filter noun and adjective
       output = []
       for sent in texts:
             doc = nlp(" ".join(sent))
             output.append([token.lemma_ for token in doc if token.pos_ in tags])
       return output
Let's tokenize the reviews and then lemmatize the tokenized reviews.
tokenized_reviews = pd.Series(reviews).apply(lambda x: x.split())
print(tokenized_reviews[1])
['these', 'long', 'cables', 'work', fine, 'truck', 'quality', 'seems', 'little', 'shabby',
'side', 'for', 'money', 'expecting', 'dollar', 'snap', 'jumper', 'cables', 'seem', 'like',
'would', 'see', 'chinese', 'knock', 'shop', 'like', 'harbor', 'freight', 'bucks']
reviews_2 = lemmatization(tokenized_reviews)
print(reviews_2[1]) # print lemmatized review
['long', 'cable', fine, 'truck', 'quality', 'little', 'shabby', 'side', 'money', 'dollar',
'jumper', 'cable', 'chinese', 'shop', 'harbor', 'freight', 'buck']
As you can see, we have not only lemmatized the words, but we have also filtered only nouns and adjectives. Let's remove the tokens from slogan reviews and trace the most common words.
reviews_3 = []
for i in range(len(reviews_2)):
    reviews_3.append(' '.join(reviews_2[i]))

df['reviews'] = reviews_3

freq_words(df['reviews'], 35)
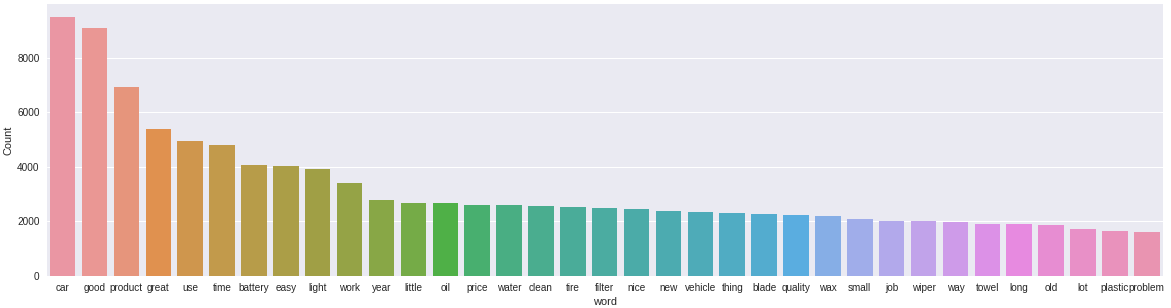
It seems that now the most frequent terms in our data are relevant. Now we can go ahead and start building our theme model.
Building an LDA model
We will start by creating the dictionary of terms of our corpus, donde a cada término único se le asigna un indexThe "Index" It is a fundamental tool in books and documents, which allows you to quickly locate the desired information. Generally, it is presented at the beginning of a work and organizes the contents in a hierarchical manner, including chapters and sections. Its correct preparation facilitates navigation and improves the understanding of the material, making it an essential resource for both students and professionals in various areas....
dictionary = corpora.Dictionary(reviews_2)
Later, we will convert the list of revisions (reviews_2) in an Matrix of document terms using the dictionary prepared above.
doc_term_matrix = [dictionary.doc2bow(rev) for rev in reviews_2]
# Creating the object for LDA model using gensim library
LDA = gensim.models.ldamodel.LdaModel

# Build LDA model
lda_model = LDA(corpus=doc_term_matrix, id2word=dictionary, num_topics=7, random_state=100,
                chunksize=1000, passes=50)
The above code will take a while. Note that I have specified the number of themes as 7 for this model using the num_topics parameter. You can specify any number of themes using the same parameter.
We print the topics that our LDA model has learned.
lda_model.print_topics()
[(0, '0.030*"car" + 0.026*"oil" + 0.020*"filter" + 0.018*"engine" + 0.016*"device" + 0.013*"code"
+ 0.012*"vehicle" + 0.011*"app" + 0.011*"change" + 0.008*"bosch"'),
(1, '0.017*"easy" + 0.014*"install" + 0.014*"door" + 0.013*"tape" + 0.013*"jeep" + 0.011*"front" +
0.011*"mat" + 0.010*"side" + 0.010*"headlight" + 0.008*"fit"'),
(2, '0.054*"blade" + 0.045*"wiper" + 0.019*"windshield" + 0.014*"rain" + 0.012*"snow" +
0.012*"good" + 0.011*"year" + 0.011*"old" + 0.011*"car" + 0.009*"time"'),
(3, '0.044*"car" + 0.024*"towel" + 0.020*"product" + 0.018*"clean" + 0.017*"good" + 0.016*"wax" +
0.014*"water" + 0.013*"use" + 0.011*"time" + 0.011*"wash"'),
(4, '0.051*"light" + 0.039*"battery" + 0.021*"bulb" + 0.019*"power" + 0.018*"car" + 0.014*"bright"
+ 0.013*"unit" + 0.011*"charger" + 0.010*"phone" + 0.010*"charge"'),
(5, '0.022*"tire" + 0.015*"hose" + 0.013*"use" + 0.012*"good" + 0.010*"easy" + 0.010*"pressure" +
0.009*"small" + 0.009*"trailer" + 0.008*"nice" + 0.008*"water"'),
(6, '0.048*"product" + 0.038*"good" + 0.027*"price" + 0.020*"great" + 0.020*"leather" +
0.019*"quality" + 0.010*"work" + 0.010*"review" + 0.009*"amazon" + 0.009*"worth"')]
The fourth theme Theme 3 has terms like “towel”, “clean up”, “cera”, “Water”, which indicates that the topic is closely related to car washing. Similar, Theme 6 seems to have to do with the overall value of the product, since it has terms like “price”, “quality” Y “value”.
Viewing themes
To visualize our themes in a two-dimensional space we will use the pyLDAvis library. This visualization is interactive in nature and shows topics along with the most relevant words.
# Visualize the topics
pyLDAvis.enable_notebook()
vis = pyLDAvis.gensim.prepare(lda_model, doc_term_matrix, dictionary)
vis

The full code is available here.
Other methods to take advantage of online reviews
In addition to modeling themes, there are many other NLP methods used to analyze and understand online reviews. Some of them are listed below:
- Text summary: Summarize reviews in a paragraph or a few bullet points.
- Entity recognition: Extract entities from reviews and identify which products are most popular (or unpopular) among consumers.
- Identify emerging trends: According to the timestamp of the reviews, new and emerging themes or entities can be identified. It would allow us to discover which products are becoming popular and which are losing their grip on the market..
- Sentiment analysis: For retailers, understanding the sentiment of reviews can be helpful in improving your products and services.
Whats Next?
Information retrieval saves us the trouble of reviewing product reviews one by one. It gives us a clear idea of what other consumers are talking about the product.
But nevertheless, does not tell us if the reviews are positive, neutral or negative. This becomes an extension of the information retrieval problem where we not only have to extract the issues, but also determine the feeling. This is an interesting task that we will cover in the next article..
Final notes
Topic modeling is one of the most popular NLP techniques with various real-world applications, as dimensionality reduction, text summary, recommendation engine, etc. The purpose of this article was to demonstrate the application of LDA in crowd generated plain text. data. I encourage you to implement the code in other data sets and share your findings.
If you have any suggestions, questions or anything else you want to share regarding theme modeling, feel free to use the comment section below.
If you are looking to enter the field of natural language processing, then we have a video course designed for you covering text preprocessing, theme modeling, recognition of named entities, deep learningDeep learning, A subdiscipline of artificial intelligence, relies on artificial neural networks to analyze and process large volumes of data. This technique allows machines to learn patterns and perform complex tasks, such as speech recognition and computer vision. Its ability to continuously improve as more data is provided to it makes it a key tool in various industries, from health... para PNL y muchos más temas.





