
Overview
- Comprender la arquitectura de Apache HiveHive is a decentralized social media platform that allows its users to share content and connect with others without the intervention of a central authority. Uses blockchain technology to ensure data security and ownership. Unlike other social networks, Hive allows users to monetize their content through crypto rewards, which encourages the creation and active exchange of information.... y su funcionamiento.
- We will learn to perform some basic operations in Apache Hive.
Introduction
Most data scientists use SQL queries to explore the data and get insights from it.. Now, since the volume of data is growing at such a high rate, we need new dedicated tools to handle large volumes of data.
Initially, Hadoop emerged and became one of the most popular tools for processing and storing big data. But developers had to write complex map reduction code to work with Hadoop. This is Facebook's Apache Hive he came to rescue. It is another tool designed to work with Hadoop. We can write SQL-like queries in the hive and in the backend it converts them into map reduction jobs.
In this article, we will see the architecture of the hive and its operation. También aprenderemos cómo realizar operaciones simples como crear una databaseA database is an organized set of information that allows you to store, Manage and retrieve data efficiently. Used in various applications, from enterprise systems to online platforms, Databases can be relational or non-relational. Proper design is critical to optimizing performance and ensuring information integrity, thus facilitating informed decision-making in different contexts.... y una tabla, load data, modify the table.
Table of Contents
- What is Apache Hive?
- Arquitectura Apache Hive
- Apache Hive job
- Data types in Apache Hive
- Create and delete database
- Create and drop table
- Load data into table
- Modify table
- Advantage / Disadvantages of Hive
What is Apache Hive?
Apache Hive is a data storage system developed by Facebook to process a large amount of structure data in Hadoop. We know that to process the data using Hadoop, we need to fix complex map reduction functions, which is not an easy task for most developers. Hive makes this job very easy for us.
It uses a scripting language called HiveQL which is almost similar to SQL. Then, we just have to write SQL-like commands and in the Hive backend it will automatically convert them to map reduction jobs.
Arquitectura Apache Hive
Let's take a look at the following diagram showing the architecture.
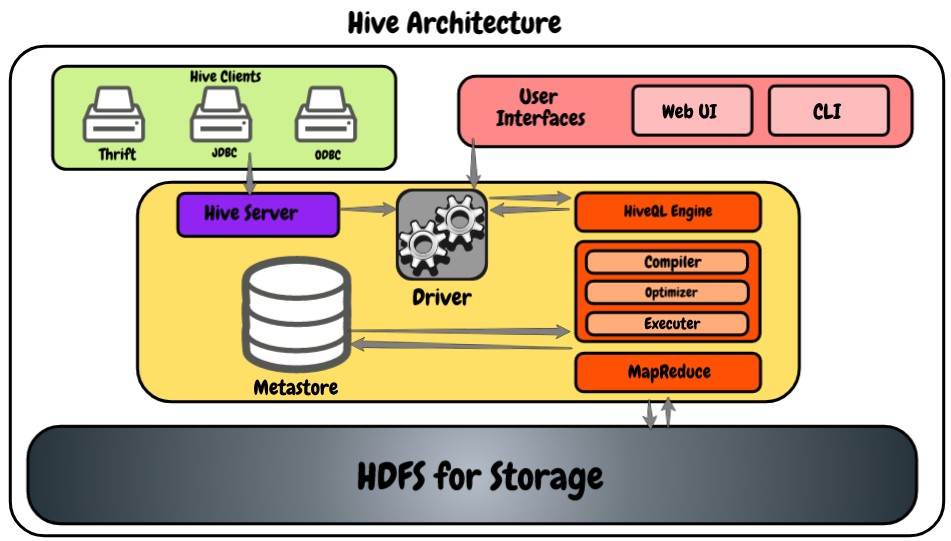
- Hive customers: It allows us to write Hive applications using different types of clients, as the saving server, the JDBC driver for Java and Hive applications, and it is also compatible with applications that use the ODBC protocol.
- Beehive services: As a developer, if we want to process any data, we need to use hive services like hive CLI (Command line interface). Besides that hive, also provides a web-based interface to run the hive applications.
- Hive driver: It is capable of receiving queries from multiple resources like thrift, JDBC and ODBS using hive server and directly from hive CLI and web-based user interface. After receiving inquiries, transfers them to the compiler.
- HiveQL engine: Receives the query from the compiler and converts the SQL-like query to map reduction jobs.
- Meta store: Here Hive stores the meta information about the databases as the table schema, the data types of the columns, la ubicación en el HDFSHDFS, o Hadoop Distributed File System, It is a key infrastructure for storing large volumes of data. Designed to run on common hardware, HDFS enables data distribution across multiple nodes, ensuring high availability and fault tolerance. Its architecture is based on a master-slave model, where a master node manages the system and slave nodes store the data, facilitating the efficient processing of information.., etc.
- HDFS: Es simplemente el Distributed File SystemA distributed file system (DFS) Allows storage and access to data on multiple servers, facilitating the management of large volumes of information. This type of system improves availability and redundancy, as files are replicated to different locations, reducing the risk of data loss. What's more, Allows users to access files from different platforms and devices, promoting collaboration and... de Hadoop que se utiliza para almacenar los datos. I highly recommend that you read this article to learn more about HDFS: Introduction to the Hadoop ecosystem
Apache Hive job
Now, Let's take a look at how Hive works on the Hadoop framework.
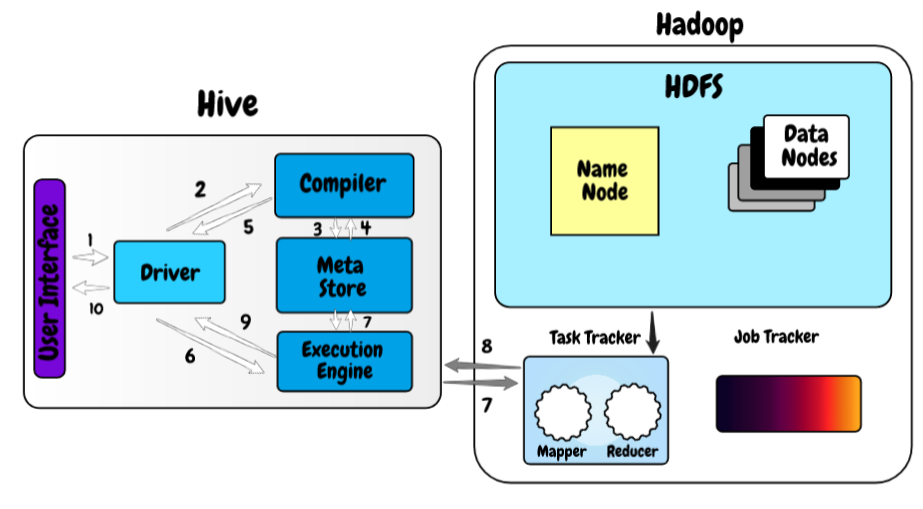
- In the first step, we write the query using the web interface or the command line interface of the hive. Sends it to the controller to execute the query.
- In the next step, the controller sends the received query to the compiler where the compiler checks the syntax.
- And once the syntax check is done, request metadata from meta store.
- Now, metadata provides information such as the database, boards, column data types in response to compiler query.
- The compiler again checks all the requirements received from the meta store and sends the execution plan to the controller.
- Now, the controller sends the execution plan to the HiveQL process engine, where the engine converts the query into the map reduction job.
- Once the query becomes the map reduction job, sends the task information to Hadoop where query processing begins and, at the same time, updates metadata about map reduction job in meta store.
- Once the processing is done, the runtime receives the query results.
- The runtime transfers the results to the controller and, Finally, sends them to the hive user interface from where we can see the results.
Data types in Apache Hive
Hive data types are divided into the following 5 different categories:
- numeric type: TINYINT, SMALLINT, INT, BIGINT
- Date types / time: HOUR, DATE, BREAK
- Types of strings: STRING, VARCHAR, CHAR
- Complex types: STRUCTURE, MAP, UNION, ARRAY
- Miscellaneous types: BOOLEO, TRACKS
Here is a little description of some of them.
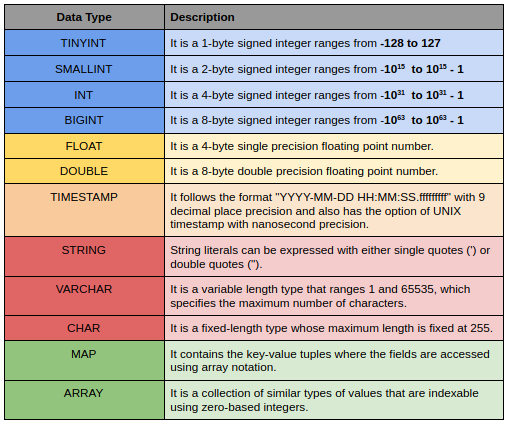
Create and delete database
Creating and deleting a database is very simple and similar to SQL. We need to assign a unique name to each of the hive databases. If the database already exists, will show a warning and to suppress this warning you can add the keywords IF IT DOESN'T EXIST after the database keyword.
CREATE DATABASE <<database_name>> ;
Deleting a database is also very simple, you just need to write a delete database and database name be abandoned. If you try to delete the database that does not exist, will give you the SemanticException error.
DROP DATABASE <<database_name>> ;
Create table
We use the create table statement to create a table and the complete syntax is as follows.
CREATE TABLE IF NOT EXISTS <<database_name.>><<table_name>>
                           (column_name_1 data_type_1,
                            column_name_2 data_type_2,
                            .
                            .
                            column_name_n data_type_n)
                            ROW FORMAT DELIMITED FIELDS
                            TERMINATED BY 't'
                            LINES TERMINATED BY 'n'
                            STORED AS TEXTFILE;
If you are already using the database, you don't need to write database_name.table_name. Then, you can only type the table name. In the case of Big Data, most of the time we import the data from external files so here we can predefine the delimiter used in the file, line terminator and we can also define how we want to store the table.
There is 2 different types of hive boards Internal and external boards. Check out this article to learn more about the concept: Table types in Apache Hive: a quick overview
Load data into table
Now, the tables have been created. Time to load the data into it. We can load the data from any local file on our system using the following syntax.
LOAD DATA LOCAL INPATH <<path of file on your local system>>
                       INTO TABLE
                       <<database_name.>><<table_name>> ;
When we work with a large amount of data, there is a possibility of having unmatched data types in some of the rows. Then, the hive will not throw any errors, instead it will fill in null values instead. This is a very useful feature, as uploading big data files to the hive is an expensive process and we don't want to upload the entire dataset just because we have few files.
Modify table
In the hive, we can make various modifications to existing tables, how to rename tables, add more columns to table. The commands to modify the table are very similar to the SQL commands.
Here is the syntax for renaming the table:
ALTER TABLE <<table_name>> RENAME TO <<new_name>> ;
Syntax for adding more table columns:
## to add more columns
ALTER TABLE <<table_name>> ADD COLUMNS
                           (new_column_name_1 data_type_1,
                            new_column_name_2 data_type_2,
                            .
                            .
                            new_column_name_n data_type_n) ;
Advantage / Disadvantages of Apache Hive
- Uses SQL as a query language that is already familiar to most developers, so it facilitates its use.
- It is highly scalable, you can use it to process any data size.
- Supports multiple databases like MySQL, derby, Postgres and Oracle for your metadata store.
- Supports multiple data formats and also allows indexing, partition and group to optimize queries.
- It can only handle cold data and is useless when it comes to real-time data processing.
- It is comparatively slower than some of its competitors. If your use case is primarily about batch processing, Hive is fine.
Final notes
In this article, we have seen the Apache Hive architecture and how it works and some of the basic operations to get started. In the next article in this series, veremos algunos de los conceptos más complejos e importantes de partición y groupingThe "grouping" It is a concept that refers to the organization of elements or individuals into groups with common characteristics or objectives. This process is used in various disciplines, including psychology, Education and biology, to facilitate the analysis and understanding of behaviors or phenomena. In the educational field, for instance, Grouping can improve interaction and learning among students by encouraging work.. en una colmena.
If you have any questions related to this article, let me know in the comment section below.





