
When the day was coming to an end, I thought about fitting into another meeting. Two analysts on my team had been working to create a dataset for one of the predictive models we wanted to build.. Combined work experience (in predictive models) among analysts it was ~ 5 years. I was hoping to get through the meeting and go out for the day.
Then, the meeting started. Five minutes after the meeting and I knew the meeting will take a lot longer than I initially thought!!
The reason? Let's review the discussion as it happened:
Kunal: How many rows do you have in the dataset?
Analyst 1: (After reviewing the dataset) X rows
Kunal: How many lines are you waiting?
Analyst 1 Y 2: Blank look on their faces
Kunal: How many events / data points expected in period / every month?
Analyst 1 Y 2: …. (None of them had a clue)
The number of rows in the dataset seemed higher to me. Analysts had clearly overlooked it, because they did not compare it to commercial expectations (or they didn't have it in the first place). When deepening, we found that some events had multiple rows in the data sets and, therefore, a greater number of rows.
A high percentage of analysts would have gone through a similar experience at some point in their career..
Sometimes, either due to timeline pressures or for some other reason, we overlook doing basic sanity checks on the dataset we are working on. Despite this, ignoring data accuracy in the early stages of the project can be very costly and, therefore, in general it is important to highlight being paranoid in relation to the accuracy of the data.
As usual, I follow a simple framework to check the accuracy of the data points. In this post, I will share the procedure that I usually use to verify the sanity of the data. The frame goes from top to bottom, what fits well. If you have obvious errors in your data sets, will be evident at the beginning of the procedure.
Note that the remaining post assumes you are working on a structured dataset. For unstructured data sets, even though the principles would still apply, the procedure would change.
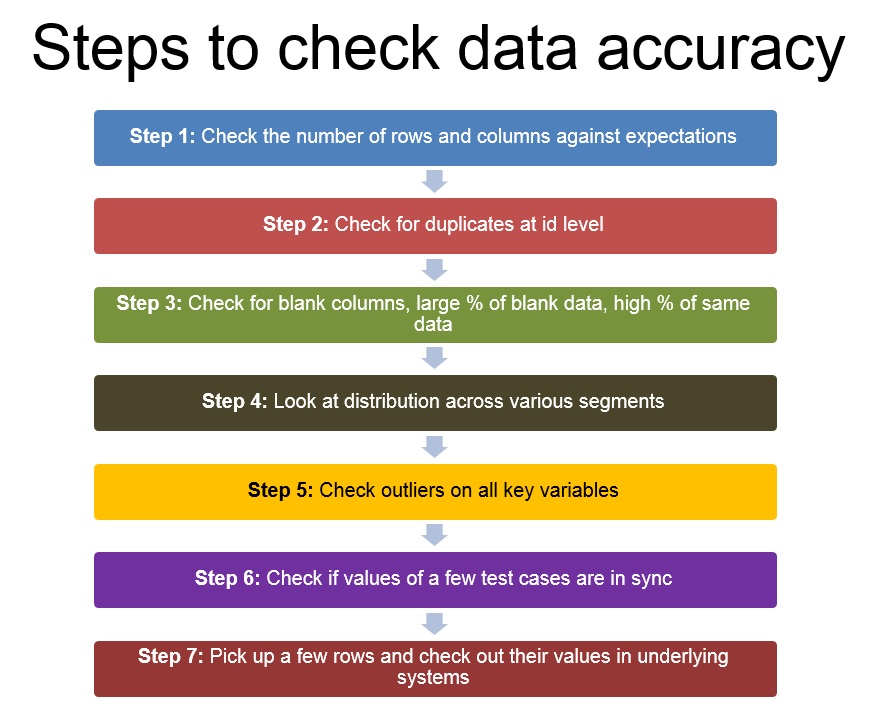
Paso 1: check number of columns and rows with expectations
The first step as soon as you get any dataset would be to check if you have all the required rows and columns. The number of columns would be dictated by the number of hypotheses you have and the variables you would need to test / refute these hypotheses.
Besides, the number of rows would be dictated by the number of events expected in the selected period. The simplest benchmark would be based on your business understanding.
Paso 2: Check for duplicates at the identification level (and not for the whole row)
Once you are sure all the columns are present and the number of rows looks within the expected range, quickly check for duplicates at your ID level (or the level at which the rows must be unique; could be a combination of variables)
Paso 3: check for blank columns, large percentage of blank data, high% of the same data
Now that you know that all the columns are there and that there are no duplicates, look for columns that are completely blank. This can happen in case some join fails or in case there is some error in data extraction. If none of the columns are blank, look at the% blank cases for each column and the frequency distributions to find out if the same data repeats in more cases than expected.
Paso 4: observe the distribution in various segments; check business understanding and use pivot tables
This step continues where it ends 3. Instead of looking at the frequencies of the data points individually, look at your distributions. Do you expect a normal distribution, bipolar the uniform? Does the layout look like what you expected?
Paso 5. Check for outliers in all key variables, especially calculated ones
Once the distributions look good, look for outliers. Especially in cases where you have calculated columns. Are Extreme's values close to what you wanted?? Make sure there are no divisions by zero, you have limited the values you would like.
Paso 6: check if the values of some test cases are in sync
Once you have checked all the columns individually, check if they are synchronized with each other. Check if the different dates of the cases are in chronological order (p. Not., Do the balances, spending and credit limit are in sync with each other for your credit card customers?
Paso 7: pick some rows and check their values on the underlying systems
Once all the above steps have been done, it's time to check some samples by querying the underlying systems or databases. If there was any error in the data, ideally you should have already identified it. This step only ensures that the data is as it was on the underlying systems.
Please note that some of these errors can be detected through the use of logs provided by your tool. Looking at the logs in a general way provides a lot of information about errors and warnings.
These were the steps I used to verify the accuracy of the data and, as usual, help me detect obvious errors in the data. Apparently, they are not the solution to all possible errors, but they should give you a good starting point and a good direction. What do you think of this frame? Are there other frameworks / methods you use to verify the accuracy of the data? If so, add them in the comments below.





