
This post was released as part of the Data Science Blogathon
What is fuzzy string matching?
Fuzzy string matching is the technique of finding strings that partially and not exactly match a given string. When a user misspells a word or partially enters a word, fuzzy string matching helps find the correct word, as we see in search engines.
The algorithm behind fuzzy string matching is not limited to observing the equivalence of two strings, rather it quantifies how close two strings are to each other. This is generally done using a distance metric known as 'edit distance'. This determines how close two strings are by identifying the minimum alterations required to convert one string to another.. There are different types of edit distances that can be used such as the Levenshtein distance, Hamming distance, Jaro's distance, etc.
Let's illustrate how the Levenshtein distance is calculated.
Example 1:
Chain 1 = ‘Put’
Chain 2 = ‘Pat’
The Levenshtein distance would be 1, since we can convert the string 1 In the chain 2 replacing 'u’ with 'a'.
Example 2:
Chain 1 = ‘Sol’
Chain 2 = ‘Saturn’
The Levenshtein distance would be 3, since we can convert the string 1 In the chain 2 through 3 inserts: ‘a’, ‘t’ y ‘r’.
Fuzzy String Matching in Python:
Comparing strings in Python
To compare two strings in Python, we can execute the following code:
Str1 = "Back"
Str2 = "Book"
Result = Str1 == Str2
print(Result)
The above code will give a result like 'False’ since the two strings are not the same.
Levenshtein distance in Python
Levenshtein distance in Python using the Python package 'Levenshtein'.
import Levenshtein as lev
Str1 = "Back"
Str2 = "Book"
lev.distance(Str1.lower(),Str2.lower())
The above code will give an output of 2, we can convert the string 1 In the chain 2 by 2 replacements.
FuzzyWuzzy and Python
FuzzyWuzzy is a Python package that can be used for string matching. We can run the following command to install the package:
pip install fuzzywuzzy
Like the Levenshtein package, FuzzyWuzzy has a linkage function that calculates the standard Levenshtein distance similarity linkage between two sequences.
from fuzzywuzzy import fuzz
Str1 = "Back"
Str2 = "Book"
Ratio = fuzz.ratio(Str1.lower(),Str2.lower())
print(Ratio)
The output of the following code gives 50, since the Levehshtein bond is calculated by dividing the Levenshtein distance by the maximum of the chain length 1 and the chain 2.
Let's calculate the motive for another set of strings.
from fuzzywuzzy import fuzz
Str1 = "My name is Ali"
Str2 = "Ali is my name"
Ratio = fuzz.ratio(Str1.lower(),Str2.lower())
print(Ratio)
The output of the code gives 50, which indicates that even though the words are the same, word order matters when calculating the proportion.
Partial linking using FuzzyWuzzy
Partial linking helps us to match substrings. This takes the shortest string and compares it to all substrings of the same length.
Str1 = "My name is Ali"
Str2 = "My name is Ali Abdaal"
print(fuzz.partial_ratio(Str1.lower(),Str2.lower()))
The output of the code gives 100 as partial_ratio () just check if any of the strings is a substring of the other.
This linking could be very useful if, as an example, we are trying to match a person's name between two data sets. In the first data set, the string has the person's first and last name, and in the second data set, the chain has the name, the person's middle and last name. The proportion would be 100 because the first string is a substring of the second string.
Token classification ratio using FuzzyWuzzy
In the token ranking ratio, strings are tokenized and preprocessed by converting them to lowercase and removing punctuation. Subsequently, strings are alphabetically arranged and joined. Post this, the Levenshtein distance similarity bond is computed between the strings.
Str1 = "My name is Ali"
Str2 = "Ali is my name"
print(fuzz.token_sort_ratio(Str1,Str2))
The output of the code gives 100, since the token sort ratio is found after sorting the strings alphabetically and, therefore, the original order of the words does not matter.
Token set ratio using FuzzyWuzzy
The token pool proportion performs a pool operation that extracts the common tokens instead of just tokenizing the strings, sort and then paste the tokens again. Extra or repeated words of the same do not matter.
Str1 = "My name is Ali"
Str2 = "Ali is my name name"
print(fuzz.token_sort_ratio(Str1,Str2))
print(fuzz.token_set_ratio(Str1,Str2))
The output of the token classification binding becomes 85, while that of the token set binding reaches 100, since token set binding does not take repeated words into account.
Let's illustrate another example of token set binding for a more in-depth explanation.
Str_A = 'Read the sentence - My name is Ali'
Str_B = 'My name is Ali'
ratio = fuzz.token_set_ratio(Str_A, Str_B)
print(ratio)
The output of the above code gives us 100. This is because, underhood, token set binding has a more flexible approach. After deleting the common strings (‘My name is Ali’), discover the fuzz binding for the following pairs and then return the maximum value among the three:
- common string and common string with rest of string one
- common string and common string with rest of string two
- common string with remainder of one and common string with remainder of two
Procedure module using FuzzyWuzzy
If we have a list of strings and we want to find the closest matching string from the list with a given string, we can take advantage of the ‘procedure’ module.
from fuzzywuzzy import process
query = 'My name is Ali'
choices = ['My name Ali', 'My name is Ali', 'My Ali']
# Get a list of matches ordered by score, default limit to 5
process.extract(query, choices)
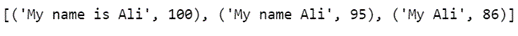
If we want to extract the top match, we can execute the following code:
process.extractOne(query, choices)
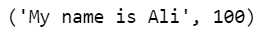
About the Author
Nibedita completed her Master of Chemical Engineering from IIT Kharagpur in 2014 and today she works as a senior consultant at AbsolutData Analytics. In your current position, works on the creation of solutions based on AI / ML for clients in a range of industries.
The media shown in this post is not the property of DataPeaker and is used at the author's discretion.





