
Overview:
This KNN article is for:
Understand the representation and prediction of the closest K algorithm (KNN).
Understand how to choose K-value and distance metric.
Required Data Preparation Methods and Pros and Cons of KNN Algorithm.
Python and pseudocode implementation.
Introduction:
K El algoritmo del vecino más cercano se incluye en la categoría de supervised learningSupervised learning is a machine learning approach where a model is trained using a set of labeled data. Each input in the dataset is associated with a known output, allowing the model to learn to predict outcomes for new inputs. This method is widely used in applications such as image classification, speech recognition and trend prediction, highlighting its importance in... y se usa para clasificación (more commonly) and regression. It is a versatile algorithm that is also used to impute missing values and resample data sets.. As the name suggests (K nearest neighbor), consider K nearest neighbors (data points) to predict the class or continuous value for the new data point.
Learning the algorithm is:
1. Instance-based learning: aquí no aprendemos ponderaciones de los datos de trainingTraining is a systematic process designed to improve skills, physical knowledge or abilities. It is applied in various areas, like sport, Education and professional development. An effective training program includes goal planning, regular practice and evaluation of progress. Adaptation to individual needs and motivation are key factors in achieving successful and sustainable results in any discipline.... para predecir la salida (as in model-based algorithms), instead we use full training instances to predict unseen data output.
2. Lazy learning: the model is not learned using training data before and the learning process is postponed to a time when the prediction is requested in the new instance.
3. in parametric: A KNN, there is no predefined form of mapping function.
How does KNN work?
-
Beginning:
Considere la siguiente figure"Figure" is a term that is used in various contexts, From art to anatomy. In the artistic field, refers to the representation of human or animal forms in sculptures and paintings. In anatomy, designates the shape and structure of the body. What's more, in mathematics, "figure" it is related to geometric shapes. Its versatility makes it a fundamental concept in multiple disciplines..... Let's say we have plotted data points from our training set in a two-dimensional feature space. As shown, we have a total of 6 data points (3 red and 3 blue). Red data points belong to ‘class1’ and the blue data points belong to 'class2'. And the yellow data point in a feature space represents the new point for which a class is to be predicted. Obviously, we say it belongs to ‘class1’ (Red dots)
Why?
Because your closest neighbors belong to that class!!
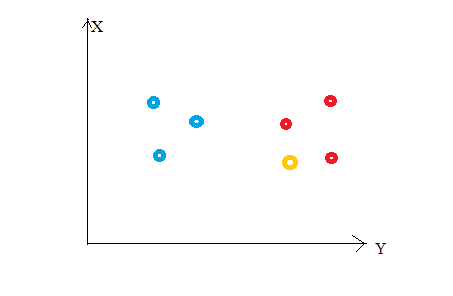
Yes, this is the principle behind K Neighbors Neighbors. Here, the closest neighbors are those data points that have a minimum distance in feature space from our new data point. And K is the number of data points that we consider in our implementation of the algorithm. Therefore, distance metric and K value are two important considerations when using KNN algorithm. Euclidean distance is the most popular distance metric. You can also use the Hamming distance, the distance from manhattan, the Minkowski distance according to your needs. To predict class / continuous value for a new data point, considers all data points in the training data set. Find the closest neighbors (data points) ‘K’ of the new data points in the feature space and their class labels or continuous values.
Later:
For classification: a class label assigned to the most K closest neighbors in the training data set is considered a predicted class for the new data point.
For regression: la media o medianThe median is a statistical measure that represents the central value of a set of ordered data. To calculate it, the data is organized from lowest to highest and the number in the middle is identified. If there are an even number of observations, the two core values are averaged. This indicator is especially useful in asymmetric distributions, since it is not affected by extreme values.... de los valores continuos asignados a K vecinos más cercanos del conjunto de datos de entrenamiento es un valor continuo predicho para nuestro nuevo punto de datos
-
Model representation
Here, we don't learn the weights and store them, rather the entire training data set is stored in memory. Therefore, the model representation for KNN is the complete training data set.
How to choose the value of K?
K is a crucial parameter in the KNN algorithm. Some suggestions for choosing K Value are:
1. Using error curves: The figure below shows the error curves for different K values for the training and test data.
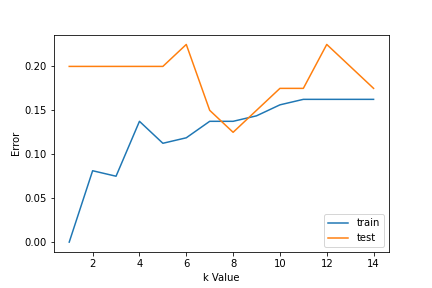
At low K values, there is data overfitting / high variance. Therefore, the test error is high and the train error is low. And K = 1 in the train data, the error is always zero, because the closest neighbor to that point is that point itself. Therefore, although the training error is low, the test error is high with lower K values. This is called overfitting.. As we increase the value of K, test error is reduced.
But after a certain value of K, bias is introduced / mismatch and test error increases. Then, we can say that initially the error of the test data is high (due to variance), then it goes down and stabilizes and with a further increase in the value of K, again increases (due to bias). The value of K when the test error stabilizes and is low is considered the optimal value for K. From the error curve above, we can choose K = 8 for the implementation of our KNN algorithm.
2. What's more, knowledge of the domain is very useful to choose the K value.
3. The value of K must be odd when considering binary classification (two classes).
Data preparation required:
1. Data scale: to locate the data point in multidimensional feature space, it would be useful if all the features are on the same scale. Therefore, the standardizationStandardization is a fundamental process in various disciplines, which seeks to establish uniform standards and criteria to improve quality and efficiency. In contexts such as engineering, Education and administration, Standardization makes comparison easier, interoperability and mutual understanding. When implementing standards, cohesion is promoted and resources are optimised, which contributes to sustainable development and the continuous improvement of processes.... o estandarización de los datos ayudará.
2. Dimensionality reduction: KNN may not work well if there are too many functions. Therefore, dimensionality reduction techniques such as feature selection and principal component analysis can be implemented.
3. Missing value treatment: if from M characteristics data are missing from a characteristic for a particular example in the training set, then we cannot locate or calculate the distance from that point. Therefore, it is necessary to delete that row or imputation.
Python implementation:
K Nearest Neighbor Algorithm Implementation Using Python's Scikit-Learn Library:
Paso 1: obtain and prepare data
import pandas as pd
import numpy as np
import matplotlib.pyplot as plt
from sklearn.datasets import make_classification
from sklearn.model_selection import train_test_split
from sklearn.preprocessing import StandardScaler
from sklearn.neighbors import KNeighborsClassifier
from sklearn import metrics
After loading important libraries, we create our data using sklearn.datasets with 200 samples, 8 features and 2 lessons. Later, the data is divided into the train (80%) and test data (20%) and are scaled using StandardScaler.
X,Y=make_classification(n_samples= 200,n_features=8,n_informative=8,n_redundant=0,n_repeated=0,n_classes=2,random_state=14)
X_train, X_test, y_train, y_test = train_test_split(X, Y, test_size= 0.2,random_state=32)
sc= StandardScaler()
sc.fit(X_train)
X_train= sc.transform(X_train)
sc.fit(X_test)
X_test= sc.transform(X_test)
X.shape
(200, 8)
Paso 2: Find the value of K
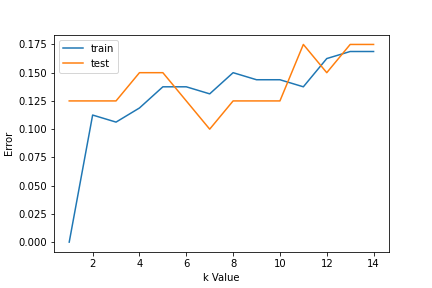
To choose the K value, we use error curves and K value with optimal variance, and the bias error is chosen as the K value for prediction purposes. With the error curve plotted below, we choose K = 7 for prediction
error1= []
error2= []
for k in range(1,15):
    knn= KNeighborsClassifier(n_neighbors=k)
    knn.fit(X_train,y_train)
    y_pred1= knn.predict(X_train)
    error1.append(np.mean(y_train!= y_pred1))
    y_pred2= knn.predict(X_test)
    error2.append(np.mean(y_test!= y_pred2))
# plt.figure(figsize(10,5))
plt.plot(range(1,15),error1,label="train")
plt.plot(range(1,15),error2,label="test")
plt.xlabel('k Value')
plt.ylabel('Error')
plt.legend()
Paso 3: Predict:
In step 2, we have chosen that the value of K is 7. Now we substitute that value and get the precision score = 0,9 for test data.
knn= KNeighborsClassifier(n_neighbors=7)
knn.fit(X_train,y_train)
y_pred= knn.predict(X_test)
metrics.accuracy_score(y_test,y_pred)
0.9
Pseudocode for K Nearest Neighbor (classification):
This is a pseudocode to implement the KNN algorithm from scratch:
- Load training data.
- Prepare the data using the scale, treating missing values and reducing dimensionality as needed.
- Find the optimal value for K:
- Predict a class value for new data:
- Calculate the distance (X, Xi) of i = 1,2,3,…., N.
where X = new data point, Xi = training data, distance based on chosen distance metric. - Order these distances in increasing order with the corresponding train data.
- From this ordered list, select rows' K’ superior.
- Find the most frequent class of these rows ‘K’ chosen. This will be your planned class.
- Calculate the distance (X, Xi) of i = 1,2,3,…., N.
The media shown in this article is not the property of DataPeaker and is used at the author's discretion.





