
This article was published as part of the Data Science Blogathon
Introduction
Red neuronal recurrenteRecurrent neural networks (RNN) are a type of neural network architecture designed to process data streams. Unlike traditional neural networks, RNNs use internal connections that allow information from previous entries to be remembered. This makes them especially useful in tasks such as natural language processing, Machine translation and time series analysis, where context and sequence are central to the... (RNN) was one of the best concepts introduced that could make use of memory elements in our red neuronalNeural networks are computational models inspired by the functioning of the human brain. They use structures known as artificial neurons to process and learn from data. These networks are fundamental in the field of artificial intelligence, enabling significant advancements in tasks such as image recognition, Natural Language Processing and Time Series Prediction, among others. Their ability to learn complex patterns makes them powerful tools... Before that, we had a neural network that could propagate back and forth to update weights and reduce errors in the network. But, as we know, many problems in the real world are temporary in nature and highly time dependent.
Many language apps are always sequential and the next word in a sentence depends on the previous one. These problems were solved by a simple RNN. But if we understand RNN, we appreciate the fact that even RNN can't help us when we want to keep track of the words that were previously used in our sentence. In this article, I will discuss some of the main drawbacks of RNN and why we use a better model for most language based applications.
Understanding backpropagation through time (BPTT)
RNN uses a technique called BackpropagationBackpropagation is a fundamental algorithm in the training of artificial neural networks. It is based on the principle of gradient descent, allowing you to adjust the weights of the network to minimize error in predictions. Through the propagation of the error from the output layer to the previous layers, This method optimizes network learning, improving your ability to generalize to unseen data.... over time to backpropagate through the network to adjust its weights so that we can reduce the error in the network. Got his name “through time”, since in RNN we deal with sequential data and each time we go back it is like going back in time to the past. Here is how BPTT works:
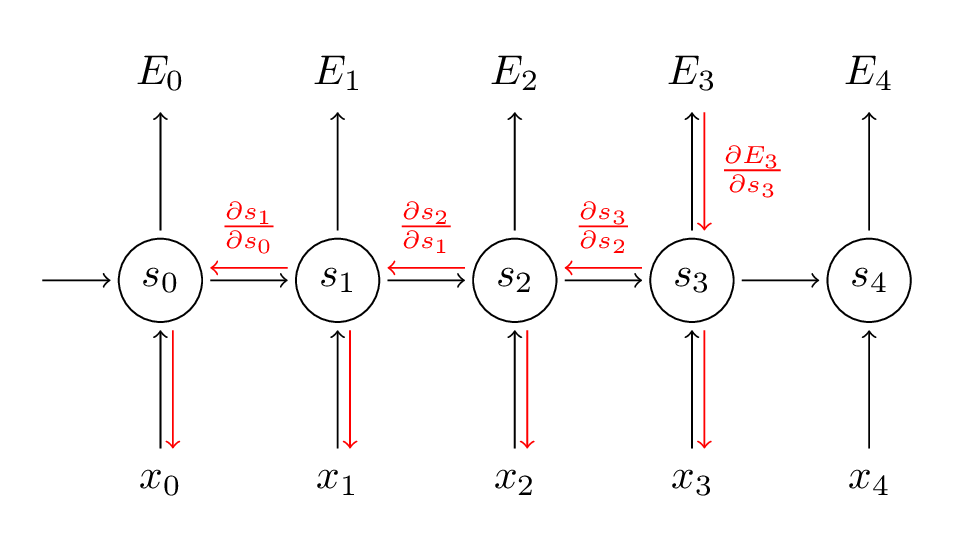
Source: (http://www.wildml.com/2015/10/recurrent-neural-networks-tutorial-part-3-backpropagation-through-time-and-vanishing-gradients/)
In step BPTT, we calculate the partial derivative at each weight in the network. Then, if we are in time t = 3, then we consider the derivative of E3 with respect to that of S3. Now, x3 is also connected to s3. Then, its derivative is also considered. Now, if we see that s3 is connected to s2, then s3 depends on the value of s2 and here the derivative of s3 with respect to s2 is also considered. This acts as a chain rule and we accumulate all the dependency with its derivatives and use it to calculate the error.
At E3 we have a gradientGradient is a term used in various fields, such as mathematics and computer science, to describe a continuous variation of values. In mathematics, refers to the rate of change of a function, while in graphic design, Applies to color transition. This concept is essential to understand phenomena such as optimization in algorithms and visual representation of data, allowing a better interpretation and analysis in... which is of S3 and its equation at that moment is:
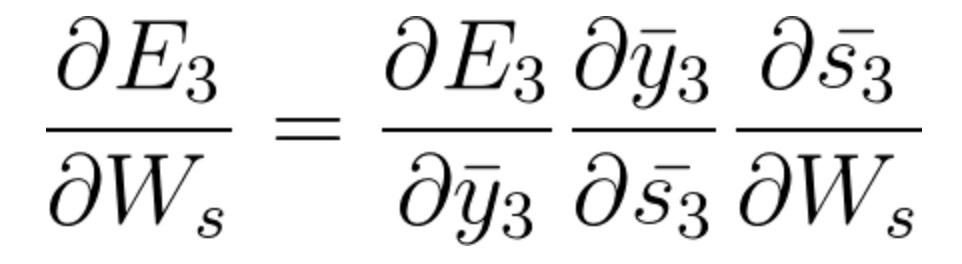
Now we also have s2 associated with s3 so,
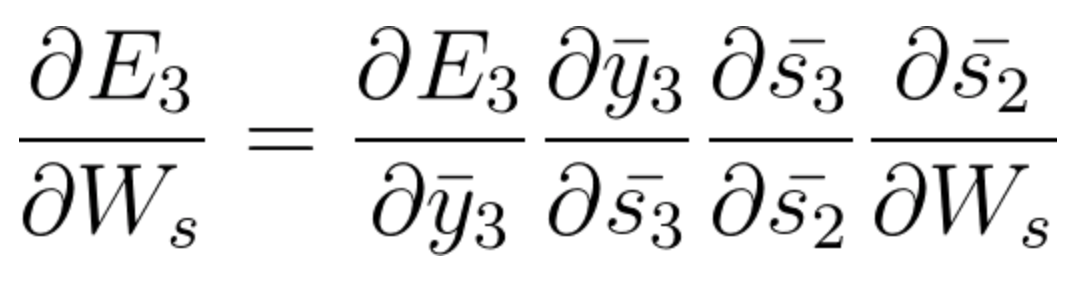
And s1 is also associated with s2 and, Thus, now everything s1, s2, s3 and has an effect on E3,
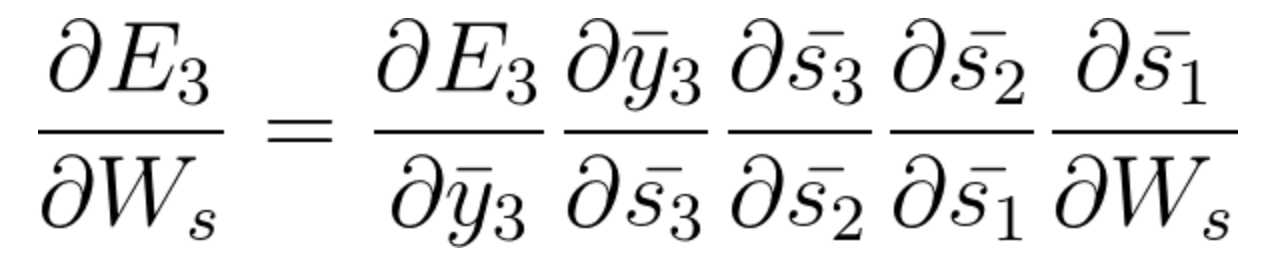
By accumulating everything, we end up obtaining the following equation that has contributed Ws to that network at time t = 3,
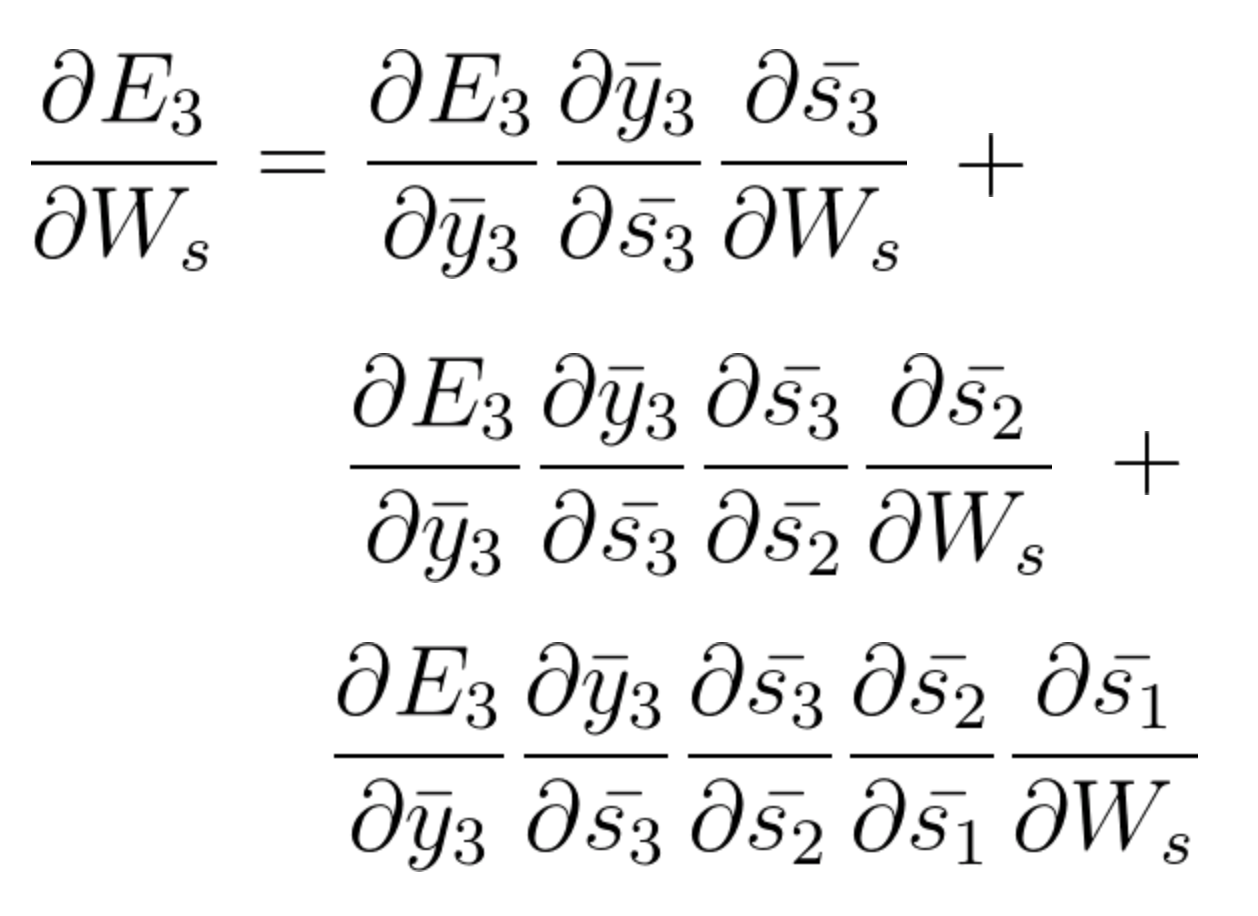
The general equation for which we fit Ws in our BPTT network can be written as,
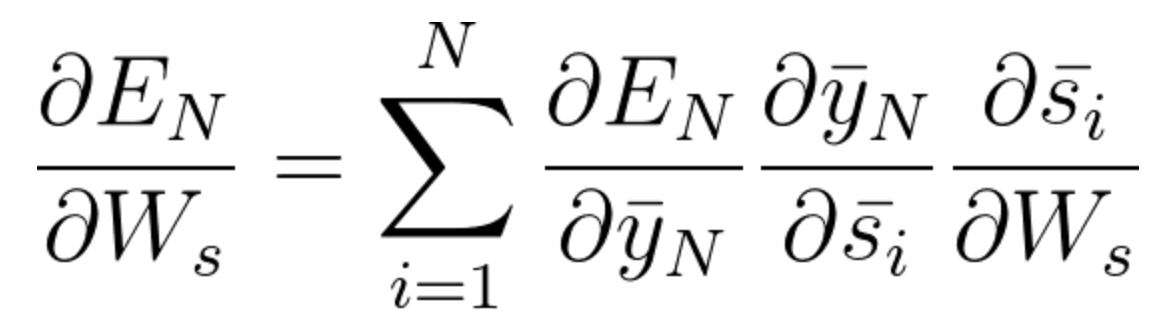
Now, as we have noticed, Wx is also associated with the network. Then, by doing the same, we can usually write,
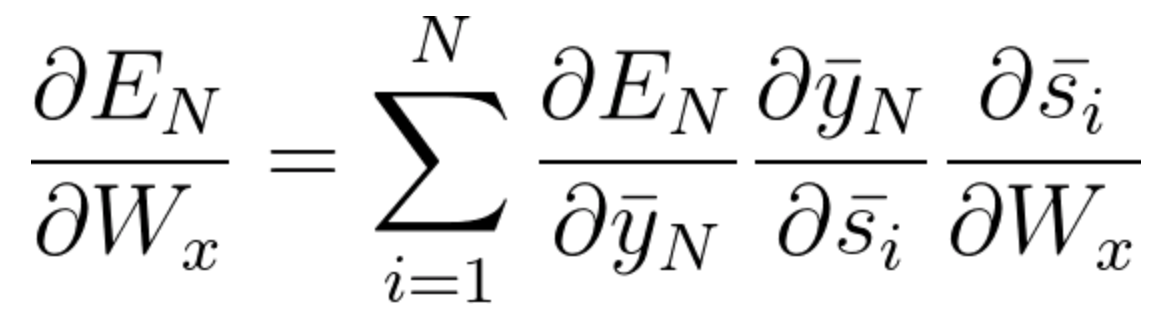
Now that you have understood how BPTT works, it's basically about how RNN adjusts its weights and reduces the error. Now, the main flaw here is that this is basically only for a small network with 4 covers. But imagine if we had hundreds of layers and, at once, let's say t = 100, we would end up calculating all the partial derivatives associated with the network and this is a huge multiplication and this can reduce the overall value to a very small value or minute value such that it may be useless to correct the error. This problem is called Gradient problem disappearing.
Gradient problem disappearing
As we all know, in RNN to predict an output we will use a wake functionThe activation function is a key component in neural networks, since it determines the output of a neuron based on its input. Its main purpose is to introduce nonlinearities into the model, allowing you to learn complex patterns in data. There are various activation functions, like the sigmoid, ReLU and tanh, each with particular characteristics that affect the performance of the model in different applications.... sigmoidea so that we can get the probability output for a particular class. As we saw in the previous section when it comes to saying E3, there is a long-term dependency. The problem occurs when we take the derivative and the derivative of the sigmoid is always below 0.25 Y, Thus, when we multiply many derivatives together according to the chain rule, we end up with a leak value such that we cannot use them for the error calculation. .
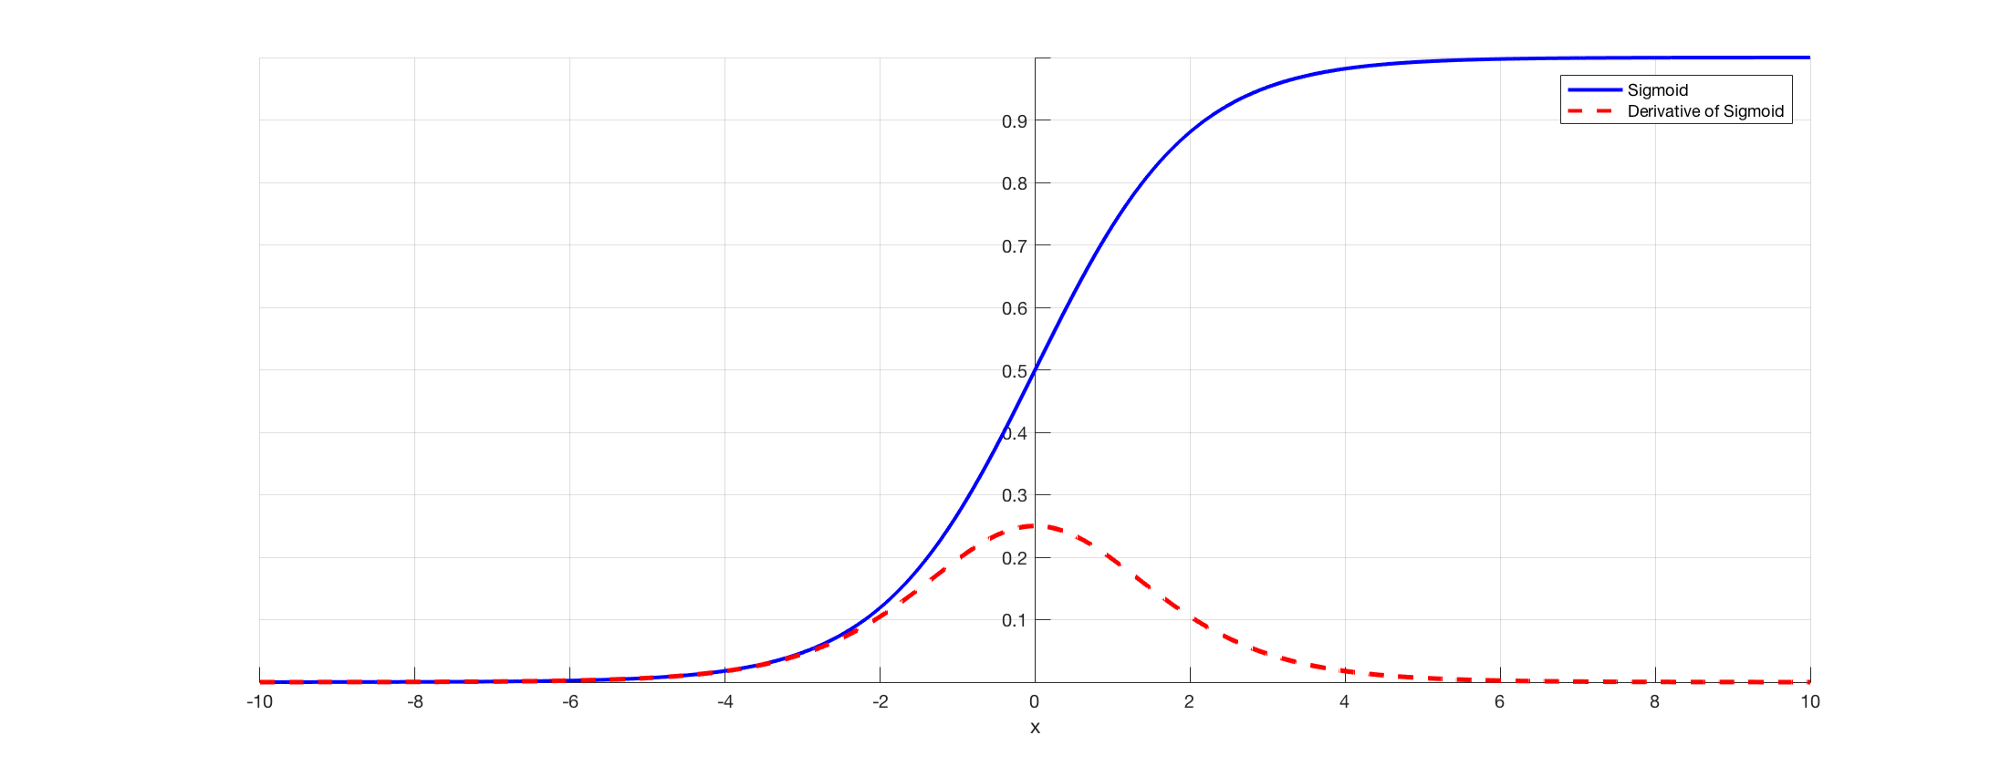
Source: (https://towardsdatascience.com/the-vanishing-gradient-problem-69bf08b15484)
Therefore, weights and biases will not update correctly and, as the layers continue to increase, we fell further into this and our model does not work properly and generates inaccuracies throughout the network.
Some ways to solve this problem are to initialize the weight array correctly or opt for something like a resumeThe ReLU activation function (Rectified Linear Unit) It is widely used in neural networks due to its simplicity and effectiveness. Defined as ( f(x) = max(0, x) ), ReLU allows neurons to fire only when the input is positive, which helps mitigate the problem of gradient fading. Its use has been shown to improve performance in various deep learning tasks, making ReLU an option... instead of sigmoid or tanh functions.
Explosive gradient problem
Gradient explosion is a problem where the value of the gradient becomes very large and this happens often when we initialize larger weights and we could end up with NaN. If our model suffered from this problem, we can't update the weights at all. But fortunately, gradient cropping is a process we can use for this. At a predefined threshold value, we cut the gradient. This will prevent the gradient value from exceeding the threshold and we will never end up with large numbers or NaN.
Long-term dependence on words
Now, let's consider a sentence like, "The clouds are in the ____". Our RNN model can easily predict ‘Sky’ here and this is due to the context of the clouds and very soon it comes as an input to your previous layer. But it may not always be so.
Picture if we had a sentence like: “Jane was born in Kerala. Jane used to play for the women's soccer team and has also topped the state level exams. Jane speaks ____ fluently “.
This is a very long sentence and the problem here is that, as human, I can say that, since Jane was born in Kerala and passed her state exam, it is obvious that you should master the “malayalam” very fluently. But, How does our machine know about this? At the point where the model wants to predict words, you may have forgotten the context of Kerala and more about something else. This is the problem of long-term dependence on RNN.
Unidirectional in RNN
As we have previously commented, RNN takes data sequentially and word by word or letter by letter. Now, when we try to predict a particular word, we are not thinking in its future context. Namely, let's say we have something like: "The mouse is really good. The mouse is used to ____ to facilitate the use of computers “. Now, if we can travel bi-directionally and we can also see the future context, we can say that ‘Displacement’ is the appropriate word here. But, if it is unidirectional, our model has never seen computers, then, How do you know if we are talking about the animal mouse or the computer mouse?
These problems are solved later using language models like BERT, where we can enter complete sentences and use the self-attention mechanism to understand the context of the text.
Use long-term short-term memory (LSTM)
One way to solve the problem of leakage gradient and long-term dependence on RNN is to opt for LSTM networks. LSTM has an introduction to three doors called entry doors, exit and oblivion. In which the doors of oblivion take care of the information that needs to be allowed to pass through the network. Thus, we can have short and long term memory. We can pass the information through the network and retrieve it even at a much later stage to identify the prediction context. The following diagram shows the LSTM network.
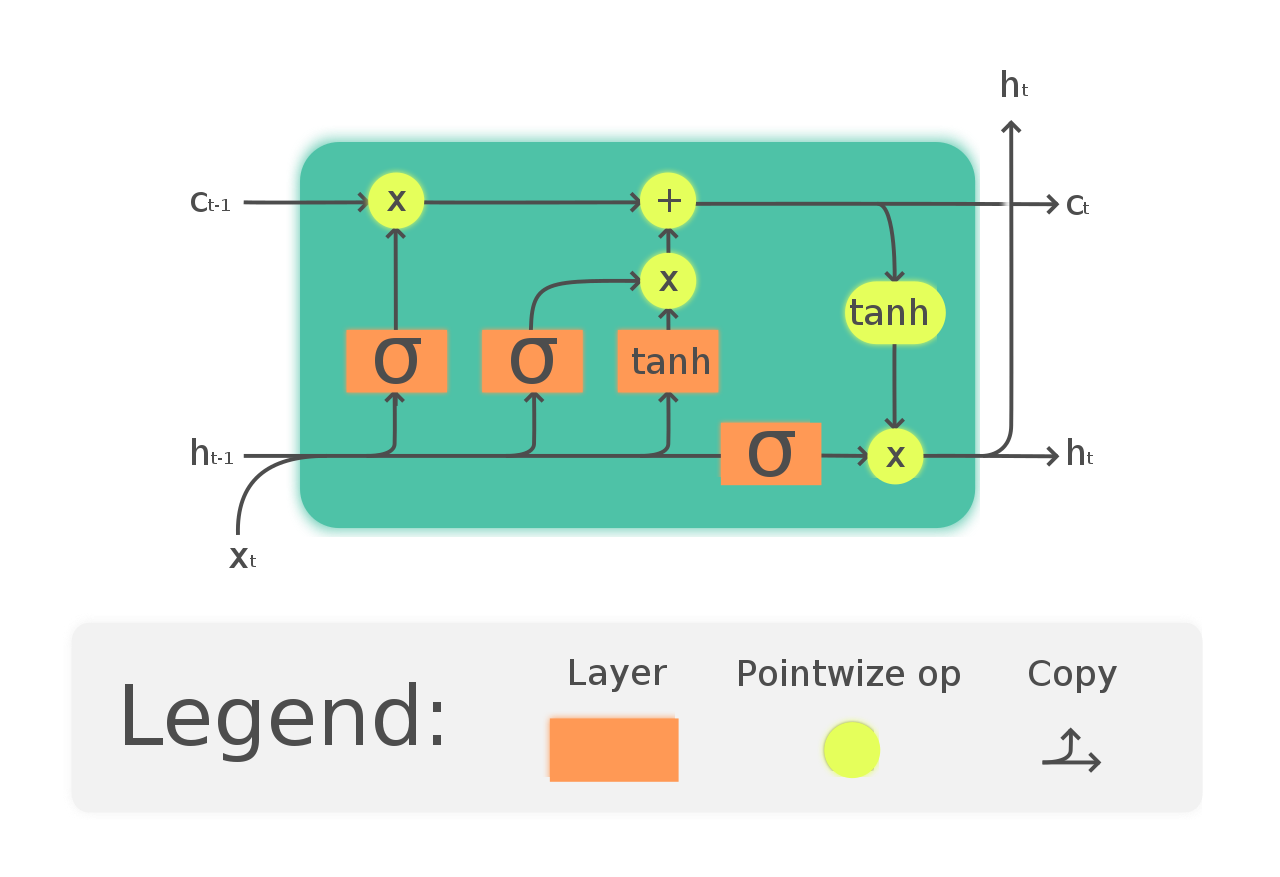
(https://en.wikipedia.org/wiki/Long_short-term_memory#/media/File:The_LSTM_Cell.svg)
Follow this tutorial for a better understanding and intuitive example of LSTM: https://towardsdatascience.com/illustrated-guide-to-lstms-and-gru-sa-step-by-step-explanation-44e9eb85bf21
Hopefully, now you have understood the problems of using an RNN and why we have opted for more complex networks like LSTM.
References
1.http: //www.wildml.com/2015/10/recurrent-neural-networks-tutorial-part-3-backpropagation-through-time-and-vanishing-gradients/
2. https://analyticsindiamag.com/what-are-the-challenges-of-training-recurrent-neural-networks/
3. https://towardsdatascience.com/the-vanishing-gradient-problem-69bf08b15484
4. https://en.wikipedia.org/wiki/Long_short-term_memory
5. https://www.udacity.com/course/deep-learning-nanodegree–nd101
6. Preview Image: https://unsplash.com/photos/Sot0f3hQQ4Y
Conclution
Feel free to connect with me at:
1. https://www.linkedin.com/in/siddharth-m-426a9614a/
2. https://github.com/Siddharth1698
The media shown in this article is not the property of DataPeaker and is used at the author's discretion.





