
In the previous article, we discuss the Hadoop ecosystem (link). We also talked about the two most used Hadoop tools, namely, PIGThe Pig, a domesticated mammal of the Suidae family, It is known for its versatility in agriculture and food production. Native to Asia, Its breeding has spread all over the world. Pigs are omnivores and have a high capacity to adapt to various habitats. What's more, play an important role in the economy, Providing meat, leather and other derived products. Their intelligence and social behavior are also ... Y HIVEHive is a decentralized social media platform that allows its users to share content and connect with others without the intervention of a central authority. Uses blockchain technology to ensure data security and ownership. Unlike other social networks, Hive allows users to monetize their content through crypto rewards, which encourages the creation and active exchange of information..... Both languages have their followers and there is no specific preference between the two, in general. But nevertheless, in cases where the team using these tools is more programming oriented, sometimes PIG is chosen over HIVE, as it gives them more freedom during encoding. In cases where the team is not very expert in programming, HIVE is probably a better option, given its similarity to SQL queries. Queries about PIG are written in PIG latin. In this article we will introduce you to PIG Latin using a simple practical example.
PIG installation
The PIG engine runs on the client's server. It is simply an interpreter that converts your simple code into complex map reduction operations. It is mapreduceMapReduce is a programming model designed to efficiently process and generate large data sets. Powered by Google, This approach breaks down work into smaller tasks, which are distributed among multiple nodes in a cluster. Each node processes its part and then the results are combined. This method allows you to scale applications and handle massive volumes of information, being fundamental in the world of Big Data.... is now managed on the distributed Hadoop network. Note that the whole network won't even know that the query was run from a PIG engine. PIG only remains in the UI and is intended to make coding easier for the user.
Follow the steps below in your shell to install PIG:
To install Pig On Red Hat compatible systems:
$ sudo yum install pig
To install Pig on SLES systems:
$ sudo zypper install pig
To install Pig on Ubuntu and other Debian systems:
$ sudo apt-get install pig
If you are thinking of running Pig on Windows, you should just make a virtual machine run on linux and then work on it. You can use VMWare Player or Oracle VirtualBox to start one.
After installing the PIG package, you can start with the grunt shell.
To start the Grunt Shell (MRv1):
$ export PIG_CONF_DIR=/usr/lib/pig/conf
$ export PIG_CLASSPATH=/usr/lib/hbase/hbase-0.94.2-cdh4.2.1-security.jar:/usr/lib/
zookeeper"Zookeeper" is a simulation video game released in 2001, where players take on the role of a zookeeper. The main mission is to manage and care for various species of animals, ensuring your well-being and the satisfaction of visitors. Throughout the game, Users can design and customize their zoo, facing challenges including food, the habitat and health of animals..../zookeeper-3.4.5-cdh4.2.1.jar
$ pig
2012-02-08 23:39:41,819 [main] INFO  org.apache.pig.Main -
Logging error messages to: /home/arvind/pig-0.9.2-cdh4b1/bin/pig_1328773181817.log
2012-02-08 23:39:41,994 [main] INFO
org.apache.pig.backend.hadoop.executionengine.HExecutionEngine -
Connecting to hadoop file system at: hdfsHDFS, o Hadoop Distributed File System, It is a key infrastructure for storing large volumes of data. Designed to run on common hardware, HDFS enables data distribution across multiple nodes, ensuring high availability and fault tolerance. Its architecture is based on a master-slave model, where a master node manages the system and slave nodes store the data, facilitating the efficient processing of information..://localhost/
...
grunt>

To start the Grunt Shell (YARNYARN is a package manager for JavaScript that allows the efficient installation and management of dependencies in development projects. Powered by Facebook, It is characterized by its speed and security compared to other managers. YARN uses a cache system to optimize installations and provides a lock file to ensure consistency of dependency versions across different development environments....):
$ export PIG_CONF_DIR=/usr/lib/pig/conf
$ export PIG_CLASSPATH=/usr/lib/hbase/hbase-0.94.2-cdh4.2.1
-security.jar:/usr/lib/zookeeper/zookeeper-3.4.5-cdh4.2.1.jar
$ pig
...
grunt>
Once i see “snarl>”, you can start coding in PIG.
Case background
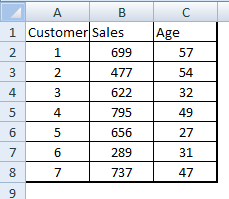
You are the analytics leader in a retail store called XYZ. XYZ keeps a record of all customers who shop at this store. Your task for this exercise is to create a new column called sales tax., what is he 5% of the sale. Later, filter the people for whom the tax amount is less than $ 35. Once this subset is done, choose the 2 main clients with the fewest number of clients. Below is a sample table for the retail store which is saved as a .csv.
Write a query in PIG Latin
Let's build this query step by step. Following are the steps you need to follow:
Paso 1 : Upload the dataset in the understandable format of PIG and temporary storage from where the PIG query can reference the table directly
Sales = LOAD 'dataset.csv' USING PigStorage (',') AS (Customer,Sales);
Note that the previous command does not load the variableIn statistics and mathematics, a "variable" is a symbol that represents a value that can change or vary. There are different types of variables, and qualitative, that describe non-numerical characteristics, and quantitative, representing numerical quantities. Variables are fundamental in experiments and studies, since they allow the analysis of relationships and patterns between different elements, facilitating the understanding of complex phenomena.... age. While working with Big Data, you need to be very specific about the variables you need to use and, Thus, make sure to choose only those variables that are important to you in your code.
Paso 2: create a new table with tax values.
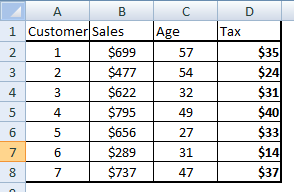
Tax = FOREACH Sales GENERATE Customer,Sales,Sales*0.05 as Tax : float;
The above command generates a new table called taxes that has the three columns. The table will now look similar to the following:
 Paso 3: Subset the entire table on the client with a tax value below $ 35.
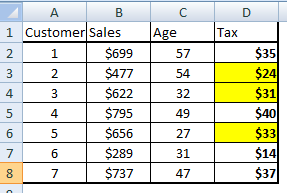
Lowtax = FILTER Tax BY Tax < $35;
The result of this command will be seen choose the yellow cells in the following table:
 Paso 4: Now we need to sort the subset table by Customer (ID) and choose the two main Clients.
sortedcust = ORDER Lowtax BY Customer;
top_two = LIMIT sortedcust 2;
Paso 5: store temporary file to permanent csv file
STORE sortedcust INTO 'salesreport' USING PIGSTORAGE (',');
In this step, our task is completed and you will get the required customer numbers with all the details. Then, the complete code that can be executed at once is shown:
Sales = LOAD 'dataset.csv' USING PigStorage (',') AS (Customer,Sales);
Tax = FOREACH Sales GENERATE Customer,Sales,Sales*0.05 as Tax : float;
Lowtax = FILTER Tax BY Tax < $35;
sortedcust = ORDER Lowtax BY Customer;
top_two = LIMIT sortedcust 2;
STORE sortedcust INTO 'salesreport' USING PIGSTORAGE (',');
Final notes
In this article, we learned how to write basic code in PIG Latin. But nevertheless, we have restricted this article to simple filtering and sorting statements, we will also talk about more complex mergers and other statements in some of the next articles.
Was the article helpful to you? Share with us any practical applications of PIG that you have found in your work. Let us know your thoughts on this item in the box below..





