
This article was published as part of the Data Science Blogathon
This article aims to compare four different algorithms of deep learningDeep learning, A subdiscipline of artificial intelligence, relies on artificial neural networks to analyze and process large volumes of data. This technique allows machines to learn patterns and perform complex tasks, such as speech recognition and computer vision. Its ability to continuously improve as more data is provided to it makes it a key tool in various industries, from health... and machine learning to build a spam detector and evaluate its performance. The data set we used came from a random sample of email subjects and bodies that contained both spam and harmful emails in numerous proportions, that we turn into slogans. Spam detection is one of the most effective deep learning projects, but it is also often a project where people lose the confidence to search for the simplest model for precision purposes. In this article, we are going to detect spam in mail using four different techniques and compare them to get the most accurate model.
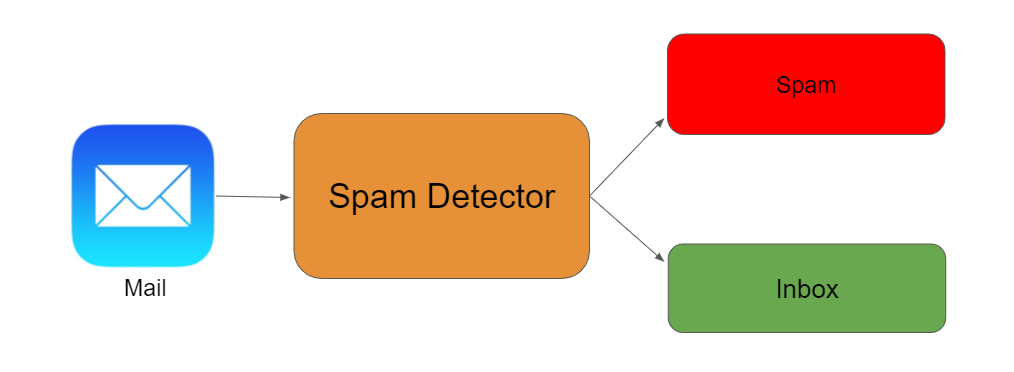
WHY SPAM DETECTION?
An email has become one of the most important types of communication. In 2014, it is estimated that there is 4,1 1 billion email accounts worldwide, and around 196 1 billion emails are sent day after day around the world. Spam is one of the main threats presented to email users. All email flows that were spam in 2013 are the 69,6%. Therefore, effective spam filtering technology is a significant contribution to the sustainability of cyberspace and our society. Since the importance of email is no less than that of your bank account containing 1Cr., Protecting it from spam or fraud is also mandatory.
Data preparation
To prepare the data, we follow the steps below:
1. Download spam and ham emails via Google takeaway as a box file.
2. Read mbox files in lists using the 'mailbox' package. Each item on the list contained an individual email. In the first iteration, we include 1000 Ham radio emails and 400 spam emails (we test different proportions after the first iteration).
3. Unpacked each email and concatenated its subject and body. We decided to include the email subject in our analysis as well because it is also a great indicator of whether an email is spam or ham..
4. Converted lists to data frames, joined spam and ham data frames, and mixed the resulting data frame.
5. Divide the data frame into test and stream data frames. The test data was the 33% from the original data set.
6. Divide mail text into taglines and apply TF-IDF transformation using CountVectorizer followed by TF-IDF transformer.
7. Four models were trained using data from trainingTraining is a systematic process designed to improve skills, physical knowledge or abilities. It is applied in various areas, like sport, Education and professional development. An effective training program includes goal planning, regular practice and evaluation of progress. Adaptation to individual needs and motivation are key factors in achieving successful and sustainable results in any discipline....:
- Bayes ingenuo
- Decision trees
- Support Vector Machine (SVM)
- Random forest
8. Using the trained models, predicted email label for test data set. Four metrics were calculated to measure the performance of the models as Accuracy, Precision, Recovery, F score, AUC.
CODE
1.Import the libraries
#import all the needed libraries
import mailbox
%matplotlib inline
import matplotlib.pyplot as plt
import csv
from textblob import TextBlob
import pandas
import sklearn
#import cPickle
import numpy as np
from sklearn.feature_extraction.text import CountVectorizer, TfidfTransformer
from sklearn.naive_bayes import MultinomialNB
from sklearn.svm import SVC, LinearSVC
from sklearn.metrics import classification_report, f1_score, accuracy_score, confusion_matrix
from sklearn.pipeline import Pipeline
from sklearn.grid_search import GridSearchCV
from sklearn.cross_validation import StratifiedKFold, cross_val_score, train_test_split
from sklearn.tree import DecisionTreeClassifier
from sklearn.learning_curve import learning_curve
#import metrics libraries
from sklearn.metrics import confusion_matrix
from sklearn.metrics import precision_score
from sklearn.metrics import recall_score
from sklearn.metrics import f1_score
from sklearn.metrics import roc_auc_score
2.Function to get email text from email body
def getmailtext(message): #getting plain text 'email body'
    body = None
    #check if mbox email message has multiple parts
    if message.is_multipart():
        for part in message.walk():
            if part.is_multipart():
                for subpart in part.walk():
                    if subpart.get_content_type() == 'text/plain':
                        body = subpart.get_payload(decode=True)
            elif part.get_content_type() == 'text/plain':
                body = part.get_payload(decode=True)
    #if message only has a single part
    elif message.get_content_type() == 'text/plain':
        body = message.get_payload(decode=True)
    #return mail text which concatenates both mail subject and body
    mailtext=str(message['subject'])+" "+str(body)
    return mailtext
3. Read the spam email file m-box
mbox = mailbox.mbox('Spam.mbox')

mlist_spam = []
#create list which contains mail text for each spam email message
for message in mbox:
    mlist_spam.append(getmailtext(message))
    #break
#read ham mbox email file
mbox_ham = mailbox.mbox('ham.mbox')

mlist_ham = []
count=0
#create list which contains mail text for each ham email message
for message in mbox_ham:

    mlist_ham.append(getmailtext(message))
    if count>601:
        break
    count+=1
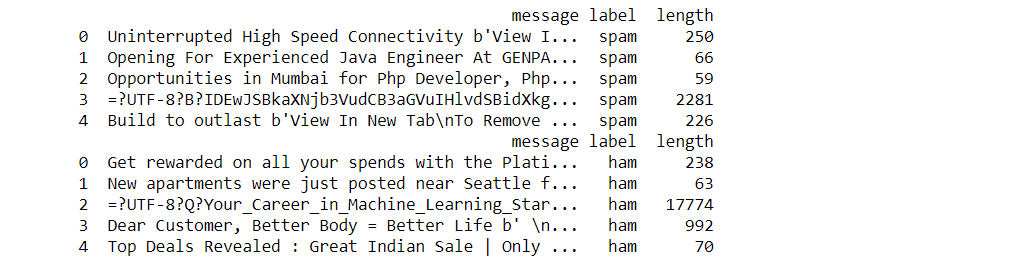
4. Create two data sets from spam emails / ham that contain information such as the text of the email, the mailing label and the length of the mailing.
#create 2 dataframes for ham spam mails which contain the following info-
#Mail text, mail length, mail is ham/spam label
import pandas as pd
spam_df = pd.DataFrame(mlist_spam, columns=["message"])
spam_df["label"] = "spam"

spam_df['length'] = spam_df['message'].map(lambda text: len(text))
print(spam_df.head())

ham_df = pd.DataFrame(mlist_ham, columns=["message"])
ham_df["label"] = "ham"

ham_df['length'] = ham_df['message'].map(lambda text: len(text))
print(ham_df.head())
5.Function to apply BOW and TF-IDF transformations
def features_transform(mail):
    #get the bag of words for the mail text
    bow_transformer = CountVectorizer(analyzer=split_into_lemmas).fit(mail_train)
    #print(len(bow_transformer.vocabulary_))
    messages_bow = bow_transformer.transform(mail)
    #print sparsity value
    print('sparse matrix shape:', messages_bow.shape)
    print('number of non-zeros:', messages_bow.nnz)
    print('sparsity: %.2f%%' % (100.0 * messages_bow.nnz / (messages_bow.shape[0] * messages_bow.shape[1])))
    #apply the TF-IDF transform to the output of BOW
    tfidf_transformer = TfidfTransformer().fit(messages_bow)
    messages_tfidf = tfidf_transformer.transform(messages_bow)
    #print(messages_tfidf.shape)
    #return result of transforms
    return messages_tfidf
6. Function to print the performance metrics of the associated model
#function which takes in y test value and y predicted value and prints the associated model performance metrics
def model_assessment(y_test,predicted_class):
    print('confusion matrix')
    print(confusion_matrix(y_test,predicted_class))
    print('accuracy')
    print(accuracy_score(y_test,predicted_class))
    print('precision')
    print(precision_score(y_test,predicted_class,pos_label="spam"))
    print('recall')
    print(recall_score(y_test,predicted_class,pos_label="spam"))
    print('f-Score')
    print(f1_score(y_test,predicted_class,pos_label="spam"))
    print('AUC')
    print(roc_auc_score(np.where(y_test=='spam',1,0),np.where(predicted_class=='spam',1,0)))
    plt.matshow(confusion_matrix(y_test, predicted_class), cmap=plt.cm.binary, interpolation='nearest')
    plt.title('confusion matrix')
    plt.colorbar()
    plt.ylabel('expected label')
    plt.xlabel('predicted label')
Let's start comparative analysis of four different models to get the highest performing algorithm.
1.Naive Bayes model
Bayes ingenuo with a bag of words approach using TF-IDFNaive Bayes is the simplest sort algorithm (quick to form, used regularly for spam detection). it is a popular method (baseline) for text categorization, the matter of judging documents as belonging to one category or the opposite (how to spam the legitimate, sports or politics, etc.) with word frequencies due to the characteristics.
Feature extraction using BOW:
TF-IDFTerm Frequency: the reverse frequency of the document uses all tokens within the dataset as vocabulary. The frequency of the term and the number of documents during which the token is produced are responsible for determining the inverse frequency of the document.. What this ensures is that, if a token occurs frequently during a document, that token will have a high TF but if that token occurs frequently within most documents, then reduce the IDF. Both these TF and IDF matrices for a selected document are multiplied and normalized to make the TF-IDF of a document.
CODE
#create and fit NB model
modelNB = MultinomialNB()
modelNB.fit(train_features,y_train)
#transform test features to test the model performance
test_features=features_transform(mail_test)
#NB predictions
predicted_class_NB=modelNB.predict(test_features)
#assess NB
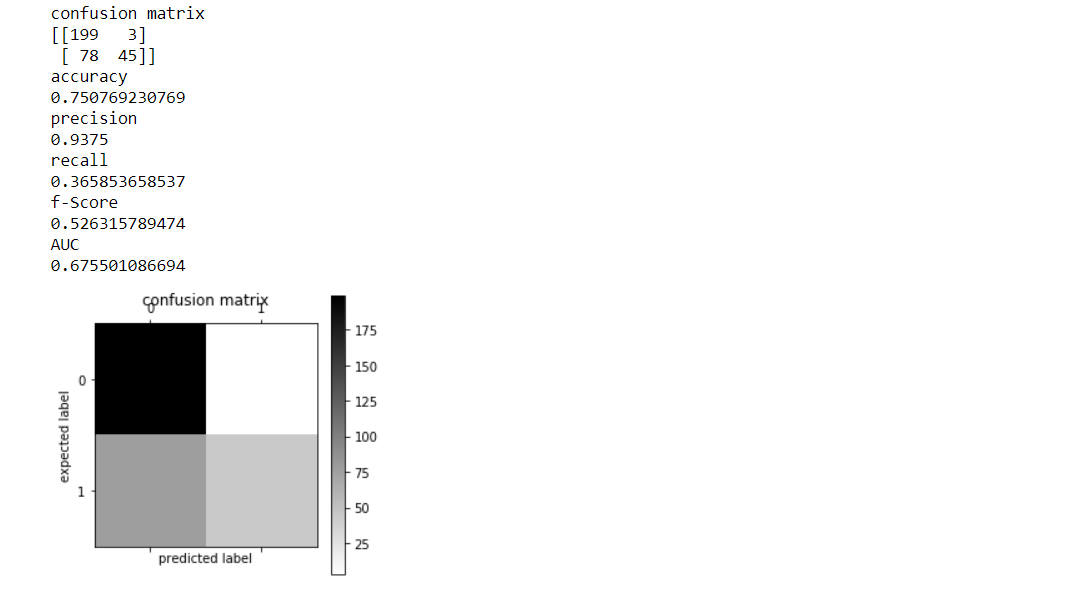
model_assessment(y_test,predicted_class_NB)
2.Decision tree model
Decision trees are used for classification and regression. The theory could be a measure to define this degree of disorganization during a system called Entropy. The entropy factor varies from sample to sample. The entropy is zero for the homogeneous sample, and for the sample of equal dividends, entropy is 1. Choose the division that has a minimum entropy compared to the nodeNodo is a digital platform that facilitates the connection between professionals and companies in search of talent. Through an intuitive system, allows users to create profiles, share experiences and access job opportunities. Its focus on collaboration and networking makes Nodo a valuable tool for those who want to expand their professional network and find projects that align with their skills and goals.... and other divisions. The smaller the entropy, greater.
CODE
#create and fit tree model
model_tree=DecisionTreeClassifier()
model_tree.fit(train_features,y_train)
#run model on test and print metrics
predicted_class_tree=model_tree.predict(test_features)
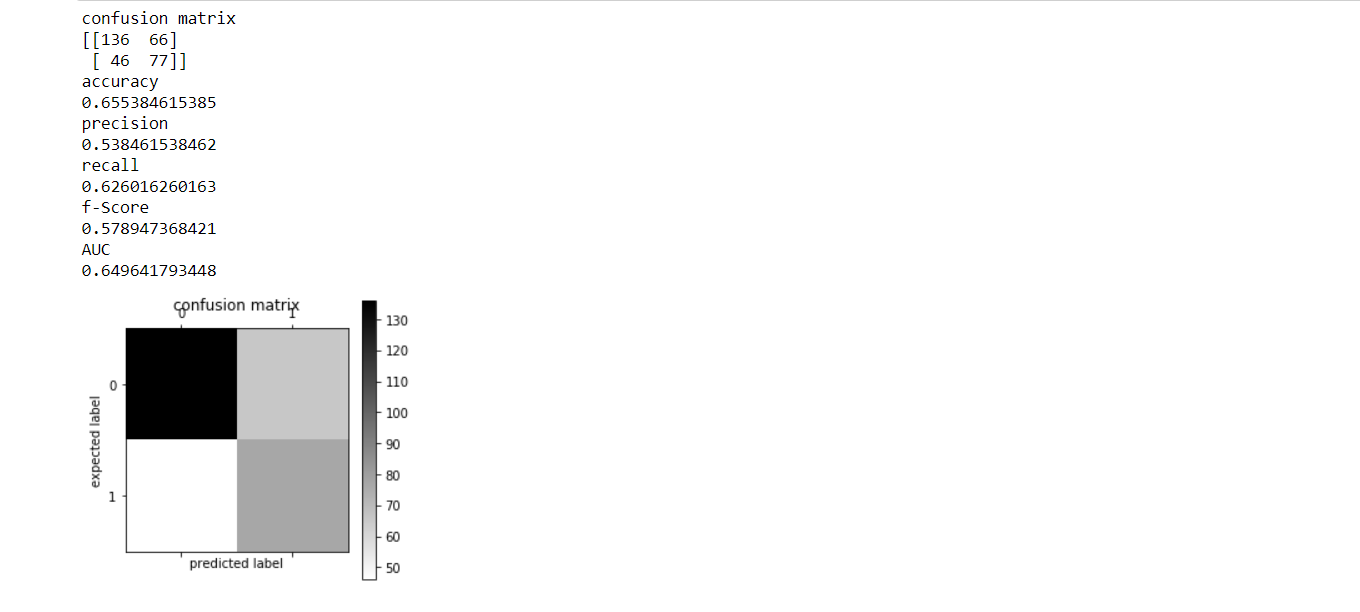
model_assessment(y_test,predicted_class_tree)
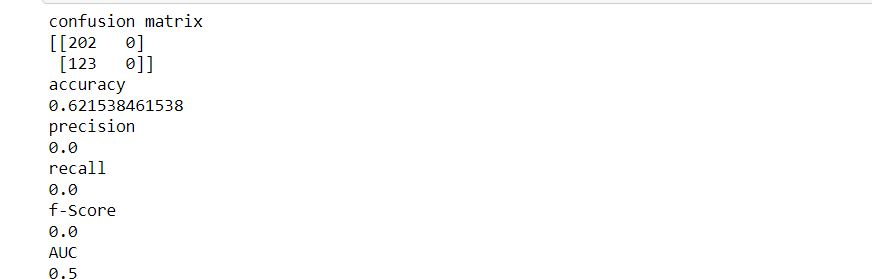
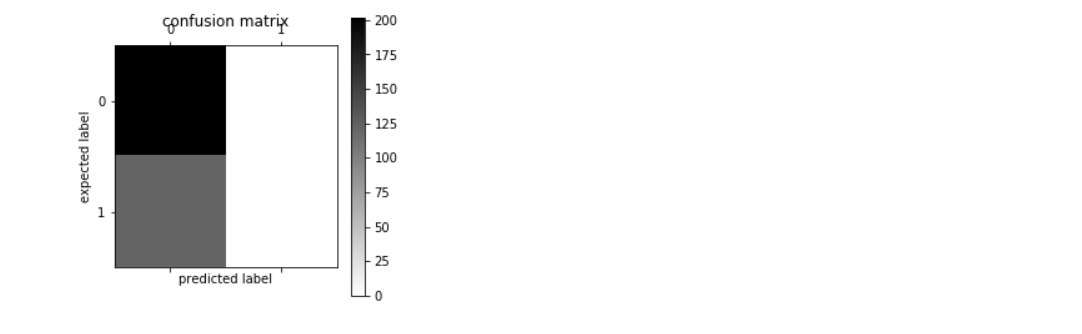
3. Support Vector Machine
Both classification and regression challenges work perfectly for this popular supervised machine learning algorithm. (SVM). But nevertheless, it is used mainly in classification problems. When we work with this algorithm, in n-dimensional space, we are going to plot each data item to some extent, so that the value of each characteristic is the value of a selected coordinate. Support Vector Machine could even be a border that better segregates the 2 lessons (hyperplane / line).
CODE
#create and fit SVM model
model_svm=SVC()
model_svm.fit(train_features,y_train)
#run model on test and print metrics
predicted_class_svm=model_svm.predict(test_features)
model_assessment(y_test,predicted_class_svm)
4. Random forest
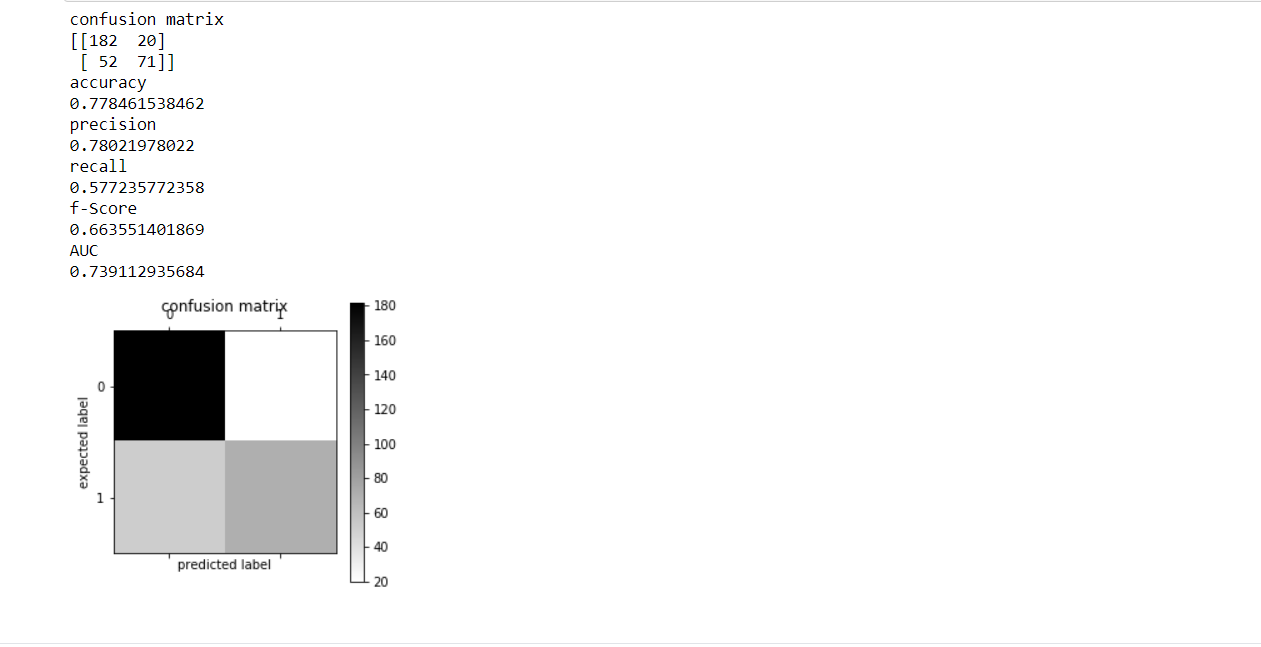
The random forest is like a bootstrap algorithm with a call tree model (CART). The last word prediction could be a function of each prediction. This final prediction can simply be the average of all predictions. Random forest provides significantly more accurate predictions when placed alongside simple CART models / CHAID or regression in many scenarios. These cases generally have a large number of predictor variables and a huge sample size.. This is often because it captures the variance of several input variables in a uniform time and allows a large number of observations to participate in the prediction..
CODE
from sklearn.set import RandomForestClassifier
#create and fit model
model_rf=RandomForestClassifier(n_estimators=20,criterion='entropy')
model_rf.fit(train_features,y_train)
#run model on test and print metrics
predicted_class_rf=model_rf.predict(test_features)
model_assessment(y_test,predicted_class_rf)
COMPARISON:-
Seeing the output of the 4 Models, you can easily compare and find its accuracy. According to the explanation above, decreasing order of precision is represented as:
MODEL ACCURACY
RANDOM FOREST 0.77846
NAIVE BAYS 0,75076
MODEL DECISION TREE 0.65538
SUPPORT VECTOR MACHINE 0.62153
RESULTS
The results are very clear that Random Forest is the most accurate method for detecting spam emails.. The reason for the same is its wide detour ability to find the best feature using its randomness. The model that cannot be used for such spam detection is SVM. The reason for the same is its small expansion. SVM may not have the ability to handle large amounts of data.
CONCLUSION
This article will help you in implementing a spam detection project with the help of deep learning. This is largely based on a comparative analysis of four different models. Stay tuned to Analytics Vidya for upcoming articles. You can use this as a reference. Feel free to put your contributions in the chatbox below. You can also ping me on LinkedIn at https://www.linkedin.com/in/shivani-sharma-aba6141b6/
The media shown in this article is not the property of DataPeaker and is used at the author's discretion.





