
Overview
- Introduction
- reduce execution time
- data set
- read data set
- management of categorical variables
- dependent and independent characteristic
- trainingTraining is a systematic process designed to improve skills, physical knowledge or abilities. It is applied in various areas, like sport, Education and professional development. An effective training program includes goal planning, regular practice and evaluation of progress. Adaptation to individual needs and motivation are key factors in achieving successful and sustainable results in any discipline.... models with CPU cores
- Final note
Introduction
“The 65.536 processors were inside the connection machine”
~ Philip Emeagwali
We all have a background in computer science, we use a computer on a daily basis and have a better understanding of what the computer is. Computers have hearts like humans, it's called CPU.
We all know the CPU, If that is not the case, the UPC is the central processing unit in the computer, or is it an electronic circuit that executes the various instructions that comprise a computer program. The CPU performs basic arithmetic, logic, etc.
Previous generations of CPUs were implemented as discrete components and numerous small ICs on one or more circuit boards. Over time, CPUs are changed, Are updated. They are implemented in an integrated circuit, with one or more CPUs on a single IC chip. There are many functions or operations that the computer performs, so it takes a long time, for that the scientist designed the multicore processors, it was a combination of microprocessor chips with multiple CPUs.
Multi-core processors are very fast, can work in a while. As a data scientist, we found that some of the python libraries are very slow and also long, slow down program execution, it takes a lot of time to run our machine learning models or deep learningDeep learning, A subdiscipline of artificial intelligence, relies on artificial neural networks to analyze and process large volumes of data. This technique allows machines to learn patterns and perform complex tasks, such as speech recognition and computer vision. Its ability to continuously improve as more data is provided to it makes it a key tool in various industries, from health.... If you want to see how many cores are in your computer, just open your PanelA panel is a group of experts that meets to discuss and analyze a specific topic. These forums are common at conferences, seminars and public debates, where participants share their knowledge and perspectives. Panels can address a variety of areas, from science to politics, and its objective is to encourage the exchange of ideas and critical reflection among the attendees.... Control and search system you will see all the information about your computer.
If we talk about the python panda library that is used in machine learning for data manipulation and data analysis, if we analyze a small amount of data it will not take so long to perform the operations, but what if our data set is large? without knowing it, it will take a long time to perform calculations on a large amount of data. Then, This is a big problem, that all data scientists face in their careers. What if we reduce this time? it is beneficial for us?
we will discuss below:
Reduce execution time
Above we have a short discussion about the CPU, then, what does it mean? It means that we use cores from the central processing unit to train our machine learning model. There is one of the parametersThe "parameters" are variables or criteria that are used to define, measure or evaluate a phenomenon or system. In various fields such as statistics, Computer Science and Scientific Research, Parameters are critical to establishing norms and standards that guide data analysis and interpretation. Their proper selection and handling are crucial to obtain accurate and relevant results in any study or project.... within the machine learning algorithm that we normally use, but we have no knowledge about it or not. I know the exact meaning of that, This sounds amazing!
These CPU cores are very important parts of the training of any machine learning model., this is also important when working with deep learning, because these CPU cores will be possible parallel programming or parallel execution of the program. We cannot train machine learning models with the help of GPUs, Thus, CPUs are more useful in this condition.
For faster machine learning training on any machine learning project, you can use these CPU cores as long as you have a large amount of data in the dataset to train the machine learning model.
Now, we see how we train the machine learning model using CPU cores to improve performance over the machine learning model:
Data set
To train this particular problem statement, we have to take the Wine_Quality data set, the reference link for this dataset is here.
To better understand this data set, you can check this link: Click here
Remember if you have to solve this particular problem with CPU cores, so you must have a simple dataset with a large data size.
The reason behind using this dataset is that it is a simple dataset with a large data size present within this dataset..
Let's see what is the size of this data:
Read data set
First, we have to read the wine quality dataset using pandas.
#importing pandas
df = pd.read_csv('wine_quality.csv')
df.head()

df.shape()

After running this code, can you see we have 6497 rows Y 13 columns in the wine quality data set.
Now, we verify the unique categories that are present within a quality variableIn statistics and mathematics, a "variable" is a symbol that represents a value that can change or vary. There are different types of variables, and qualitative, that describe non-numerical characteristics, and quantitative, representing numerical quantities. Variables are fundamental in experiments and studies, since they allow the analysis of relationships and patterns between different elements, facilitating the understanding of complex phenomena....,
unique_points= df['quality'].unique()
unique_points

As we see, there is 6, 5, 7, 8, 4, 3, 9 unique data points in the quality variable, where these data points are the wine quality measures.
Handel's categorical variables
# catogerical vars
next_df = pd.get_dummies(new_df,drop_first=True)
# display new dataframe
next_df

Dependent and independent characteristic
To apply the machine learning model, we have to divide the dependent and independent characteristics:
# independent features
x= next_df.drop(['quality','best quality'],axis=1)
# dependent feature
y= next_df['best quality']
Model training with CPU cores
Coming to execution now, we are doing it by applying some steps:
Paso 1: Using the RandomForestClassifier machine learning algorithm.
Paso 2: Using RepeatedStratifiedKFold for cross validation.
Paso 3: Train the model using the cross-validation score.
When we initialize all these things, time will be calculated based on this cross-validation score. Before checking the time we import the required modules:
Module import:
from time import time
# importing RepeatedStratifiedKFold
from sklearn.model_selection import RepeatedStratifiedKFold
from sklearn.ensemble import RandomForestClassifier
from sklearn.model_selection import cross_val_score
# importing RandomForestClassifier
Now, we check the time using the different CPU cores:
Here we use the RandomForestClassifie machine learning algorithm, when you check the parameters of RandomForestClassifier, you find that there is a n_jobs parameter.

n_jobs it is the parameter that will really help you to basically assign how many cores a particular system workout should take.
For instance, if we want to take n_jobs = 1 then will take 1 CPU core, yes take 2, it will take 2 CPU cores, and so on. When you want to use all CPU cores for training and you don't know how many cores are in the system, just use n_jobs = -1.
1 CPU Cores:
## CPU cores we use n_jobs
random = RandomForestClassifier(n_estimators = 100)
# creating object of RepeatedStratifiedKFold
cv = RepeatedStratifiedKFold(n_splits=5, n_repeats=3, random_state=4)
# starting execution time
start_time=time()
n_scores =cross_val_score(random,x,Y,scoring='accuracy', cv=cv, n_jobs=1)
# ending time of execution
end_time=time()
final_time = end_time-start_time
# display execution time
print('final execution time is : {}.format(final_time))

Here we see that with 1 core are needed around 10 seconds to run, and this is a huge time.
We do not write the n_jobs inside the RandomForestClassifier instead we write it in the cross_val_score because it helps us to do cross validation using RepeatedStratifiedKFold
Now, we use this same code with a little change for more cores:
2 CPU cores:
## CPU cores we use n_jobs
random = RandomForestClassifier(n_estimators = 100)
# creating object of RepeatedStratifiedKFold
cv = RepeatedStratifiedKFold(n_splits=5, n_repeats=3, random_state=4)
# starting execution time
start_time=time()
n_scores =cross_val_score(random,x,Y,scoring='accuracy', cv=cv, n_jobs=2) # 2 cores
# ending time of execution
end_time=time()
final_time = end_time-start_time
# display execution time
print('final execution time is : {}.format(final_time))

Yes, here you can see that what is the difference between 1 core and 2 cores, execution time is very different from 1 core.
3 CPU cores:
## CPU cores we use n_jobs
random = RandomForestClassifier(n_estimators = 100)
# creating object of RepeatedStratifiedKFold
cv = RepeatedStratifiedKFold(n_splits=5, n_repeats=3, random_state=4)
# starting execution time
start_time=time()
n_scores =cross_val_score(random,x,Y,scoring='accuracy', cv=cv, n_jobs=3)   # 3 cores
# ending time of execution
end_time=time()
final_time = end_time-start_time
# display execution time
print('final execution time is : {}.format(final_time))

Take all the cores:
## CPU cores we use n_jobs
random = RandomForestClassifier(n_estimators = 100)
# creating object of RepeatedStratifiedKFold
cv = RepeatedStratifiedKFold(n_splits=5, n_repeats=3, random_state=4)
# starting execution time
start_time=time()
n_scores =cross_val_score(random,x,Y,scoring='accuracy', cv=cv, n_jobs= -1) # all cores
# ending time of execution
end_time=time()
final_time = end_time-start_time
# display execution time
print('final execution time is : {}.format(final_time))

Core timing comparison:
## CPU cores we use n_jobs
for core in [1,2,3,4,5,6,7,8,9,10]:
    random = RandomForestClassifier(n_estimators = 100)
    # creating object of RepeatedStratifiedKFold
    cv = RepeatedStratifiedKFold(n_splits=5, n_repeats=3, random_state=4)
    # starting execution time
    start_time=time()
    n_scores =cross_val_score(random,x,Y,scoring='accuracy', cv=cv, n_jobs = core)
    # ending time of execution
    end_time=time()
    final_time = end_time-start_time
    # display execution time
    print('final execution time of core {} is : {}.format(core,final_time))
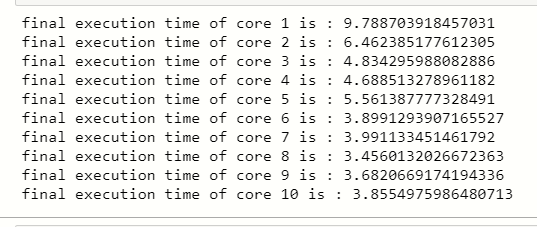
You can see that there is a big difference when we use 1 core to train our ML model and 10 cores for training the ML model.
Final notes
Hello there, in this article you learned the training of ML models using CPU cores, now is the time to implement this technique in your machine learning model to reduce execution time.
Hope you enjoy this article., Share it with your friends.
You can connect with me on LinkedIn: www.linkedin.com/in/mayur-badole-189221199
Check out my other articles: https://www.analyticsvidhya.com/blog/author/mayurbadole2407/
Thanks.
The media shown in this article is not the property of DataPeaker and is used at the author's discretion.





