
Note: this post was originally published on 13 September 2015 and updated the 11 September 2017
Overview
- Understand one of the most popular and simple machine learning classification algorithms, the Naive Bayes algorithm
- It is based on Bayes' theorem to calculate probabilities and conditional probabilities.
- Learn how to implement the Naive Bayes classifier in R and Python
Introduction
Here's a situation you've gotten yourself into Data science draft:
You are working on a classification hurdle and have generated your set of hypotheses, created characteristics and discussed the relevance of the variables. In an hour, stakeholders want to see the first cut of the model.
What are you going to do? Tienes cientos de cientos de puntos de datos y bastantes variables en tu conjunto de datos de trainingTraining is a systematic process designed to improve skills, physical knowledge or abilities. It is applied in various areas, like sport, Education and professional development. An effective training program includes goal planning, regular practice and evaluation of progress. Adaptation to individual needs and motivation are key factors in achieving successful and sustainable results in any discipline..... In such a situation, if i were in your place, would have used ‘Bayes ingenuo‘, that can be extremely fast in bonding with others classification algorithms. Works with Bayes' probability theorem to predict the class of unknown data sets.
In this post, I will explain the basics of this algorithm, so the next time you come across large data sets, can put this algorithm into action. At the same time, if you are a rookie in Python the R, you should not be overwhelmed by the presence of codes available in this post.
If you prefer to learn the Naive Bayes theorem from the basics to implementation in a structured way, you can enroll in this course free of charge:
Are you a beginner in Machine Learning? Do you intend to master machine learning algorithms like Naive Bayes? Aquí hay un curso completo que cubre el aprendizaje automático y los algoritmos de deep learningDeep learning, A subdiscipline of artificial intelligence, relies on artificial neural networks to analyze and process large volumes of data. This technique allows machines to learn patterns and perform complex tasks, such as speech recognition and computer vision. Its ability to continuously improve as more data is provided to it makes it a key tool in various industries, from health... in detail:
Project to apply Naive BayesProblem StatementHR analytics is revolutionizing the way HR departments operate, leading to higher efficiency and better results overall. Los recursos humanos han estado usando la analyticsAnalytics refers to the process of collecting, Measure and analyze data to gain valuable insights that facilitate decision-making. In various fields, like business, Health and sport, Analytics Can Identify Patterns and Trends, Optimize processes and improve results. The use of advanced tools and statistical techniques is essential to transform data into applicable and strategic knowledge.... during years. Despite this, the compilation, data processing and analysis has been largely manual and, dada la naturaleza de la dinámica de los recursos humanos y los KPIKPIs, o Key performance indicators, These are metrics used by organizations to evaluate their success in achieving specific goals. These indicators allow you to monitor progress and make informed decisions. There are different types of KPIs, which may vary depending on the sector and the strategic objectives of the company. Its correct implementation is essential to improve the efficiency and effectiveness of operations.... de recursos humanos, the focus has been restricting to human resources. Therefore, it's surprising hr departments have come to realize the usefulness of machine learning so late in the game. This is a possibility to test predictive analytics to identify workers most likely to be promoted. |
Table of Contents
- What is the Naive Bayes algorithm?
- How do Naive Bayes algorithms work?
- What are the pros and cons of using Naive Bayes?
- 4 Naive Bayes algorithm applications
- Steps to build a basic Naive Bayes model in Python
- Tips for Boosting the Power of the Naive Bayes Model
What is the Naive Bayes algorithm?
It's a classification technique based on Bayes theorem with an assumption of independence between predictors. In simple terms, a Naive Bayes classifier assumes that the presence of a particular feature in a class is unrelated to the presence of any other feature.
As an example, a fruit can be considered an apple if it is red, round and has approximately 3 inches in diameter. Even if these characteristics depend on each other or on the existence of other characteristics, All these properties contribute independently to the probability that this fruit is an apple and that is why it is known as ‘Naive’.
The Naive Bayes model is easy to build and particularly useful for very large data sets.. Along with the simplicity, Naive Bayes are known to outperform even highly sophisticated classification methods.
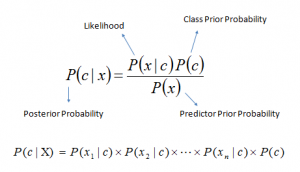
Bayes' theorem provides a way to calculate the posterior probability P (c | x) from P (c), P (x) y P (x | c). Look at the next equation:
 Above,
- PAG(c | x) is the posterior probability of class (C, objective) dice predictor (X, attributes).
- PAG(C) is the prior probability of class.
- PAG(x | c) is the probability which is the probability of predictor dice class.
- PAG(X) is the prior probability of predictor.
How does the Naive Bayes algorithm work?
Let's understand with an example. A continuación tengo un conjunto de datos de entrenamiento del clima y la variableIn statistics and mathematics, a "variable" is a symbol that represents a value that can change or vary. There are different types of variables, and qualitative, that describe non-numerical characteristics, and quantitative, representing numerical quantities. Variables are fundamental in experiments and studies, since they allow the analysis of relationships and patterns between different elements, facilitating the understanding of complex phenomena.... objetivo respectivo ‘Jugar’ (suggesting game possibilities). Now, we must categorize if the players will play or not according to the weather conditions. Let's follow the steps below to do it.
Paso 1: convert the data set to a frequency table
Paso 2: Create a probability table by finding the probabilities as the probability of Cloudy = 0.29 and the probability of playing is 0.64.
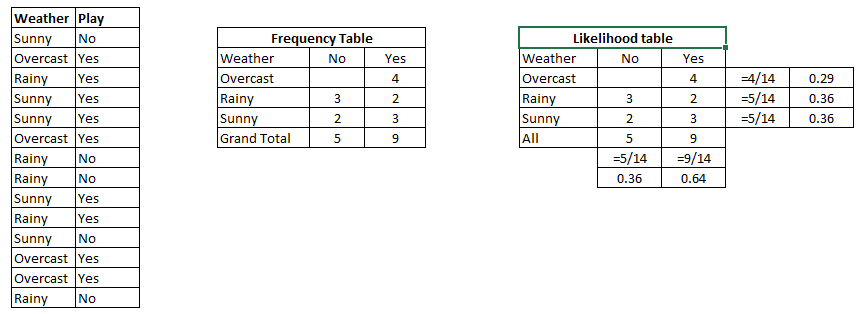
Paso 3: now, uses Ingenuo bayesiano equation to calculate the posterior probability for each class. The class with the highest posterior probability is the result of the prognosis.
Trouble: Players will play if the weather is sunny. Is this statement correct?
We can solve it using the posterior probability method previously discussed.
P (Yes | Sunny) = P (Sunny | Yes) * P (Yes) / P (Sunny)
Here we have P (Sunny | Yes) = 3/9 = 0.33, P (Sunny) = 5/14 = 0.36, P (Yes) = 9/14 = 0.64
Now, P (Yes | Sunny) = 0.33 * 0.64 / 0.36 = 0.60, which is more likely.
Naive Bayes uses an equivalent method to predict the probability of different classes based on various attributes. This algorithm is mainly used in text classification and with problems that have multiple classes.
What are the pros and cons of Naive Bayes?
Pros:
- It is easy and fast to predict the kind of test data set. Also works well in multi-class forecasting.
- When the assumption of independence is fulfilled, a Naive Bayes classifier performs better compared to other models such as logistic regression and requires less training data.
- Works fine for categorical input variables compared to numeric variables. For the numeric variable, a normal distribution is assumed (bell curve, which is a solid assumption).
Cons:
- If the categorical variable has a category (in the test data set), that was not observed in the training data set, then the model will assign a probability 0 (zero) and you won't be able to make a prediction. This is often referred to as “Zero frequency”. To fix this, we can use the smoothing technique. One of the simplest smoothing techniques is called Laplace estimation.
- Besides, Bayes ingenuo además se conoce como un mal estimatorThe "Estimator" is a statistical tool used to infer characteristics of a population from a sample. It relies on mathematical methods to provide accurate and reliable estimates. There are different types of estimators, such as the unbiased and the consistent, that are chosen according to the context and objective of the study. Its correct use is essential in scientific research, surveys and data analysis...., so the probability outputs of predict_test should not be taken too seriously.
- Another limitation of Bayes ingenuo is the assumption of independent predictors. In real life, it is almost impossible for us to obtain a set of predictors that are totally independent.
4 Applications of naive Bayes algorithms
- Real-time prediction: Naive Bayes is an avid and sure learning classifier that is fast. Therefore, could be used to make predictions in real time.
- Multiple class prediction: This algorithm is also well known for its multiple class prediction function.. Here we can predict the probability of multiple target variable classes.
- Text classification / spam filtering / sentiment analysis: Naive Bayes classifiers used primarily in text classification (due to a better result in multiple class problems and the rule of independence) have a higher success rate compared to other algorithms. Due, widely used in spam filtering (identify spam email) and sentiment analysis (in social media analysis, to identify the positive and negative feelings of customers).
- Recommender system: Naive Bayes classifier and Collaborative filtering together they build a recommendation system that uses machine learning and data mining techniques to filter invisible information and predict whether a user wants a certain resource or not
How to build a basic model using Naive Bayes in Python and R?
Again, scikit learn (Python library) will help here to build a Naive Bayes model in Python. There are three types of Naive Bayes model in the scikit-learn library:
-
Gaussiano: It is used in classification and assumes that the characteristics follow a normal distribution.
-
Multinomial: Used for discrete counts. As an example, let's say we have a text sorting hurdle. Here we can consider Bernoulli's essays, which is one step further and instead of “word that appears in the document”, have “count how often the word appears in the document”, you can think of it as “number of times the result number x_i is observed during the n trials ".
-
Bernoulli: The binomial model is useful if your feature vectors are binary (In other words, zeros and ones). An application would be the text classification with the 'bag of words' model’ where the 1 Y 0 son “the word appears in the document” Y “the word does not appear in the document”, respectively.
Python code:
Try the following code in the coding window and check your results on the go!!
R code:
require(e1071) #Holds the Naive Bayes Classifier
Train <- read.csv(file.choose())
Test <- read.csv(file.choose())

#Make sure the target variable is of a two-class classification problem only

levels(Train$Item_Fat_Content)

model <- naivebayes(Item_Fat_Content~., data = Train)
class(model)
pred <- predict(model,Test)
table(pred)
Previously, we analyze the basic Naive Bayes model, puede mejorar la potencia de este modelo básico ajustando los parametersThe "parameters" are variables or criteria that are used to define, measure or evaluate a phenomenon or system. In various fields such as statistics, Computer Science and Scientific Research, Parameters are critical to establishing norms and standards that guide data analysis and interpretation. Their proper selection and handling are crucial to obtain accurate and relevant results in any study or project.... y manejando las suposiciones de manera inteligente. Let's see the methods to boost the performance of the Naive Bayes model. I suggest you go through this document for more details on classifying text using Naive Bayes.
Tips for Boosting the Power of the Naive Bayes Model
Then, Here are some tips for boosting the potency of Bayes ingenuo Model:
- If continuous entities do not have normal distribution, we should use transformation or different methods to convert them to normal distribution.
- If the test data set has a zero frequency obstacle, apply “Laplace correction” smoothing techniques to predict the class of test data set.
- Remove correlated features, since highly correlated characteristics are voted twice in the model and can lead to exaggerated relevance.
- Naive Bayes classifiers have limited options for setting parameters such as alpha = 1 to smooth, fit_prior =[True|False] to learn the prior probabilities of the class or not and some other options (see details here). I would recommend focusing on data pre-processing and feature selection.
- Could you think of applying some classifier combination technique like set, bagging and reinforcement, but these methods would not help. In reality, “join, boost, pocket” will not help, since its objective is to reduce the variation. Naive Bayes has no variation to minimize.
Final notes
In this post, we analyze one of the supervised machine learning algorithms”Naive Bayes” which is mainly used for sorting. congratulations, if you have understood this post correctly, you have already taken the first step to master this algorithm. From now on, all you need is practice.
At the same time, I suggest you focus more on data preprocessing and feature selection before applying the Naive Bayes algorithm.0 In a future post, I will talk about classifying texts and documents using naive bayes in more detail.
Has this post been useful to you? Share your opinions / thoughts in the comment section below.
You can use the following resource at no cost to learn- Naive Bayes-





