This article was published as part of the Data Science Blogathon.
Introduction
Big Data is often characterized by: –
a) Volume: – Big Data is often characterized by.
B) Speed: – Big Data is often characterized by.
C) Veracity: – Big Data is often characterized by (Big Data is often characterized by, etc.)
D) Variety: – Big Data is often characterized by
* Structured data: – Big Data is often characterized by.
* Unstructured data: – Big Data is often characterized by
* Big Data is often characterized by: – Big Data is often characterized by.
Big Data is often characterized by, Big Data is often characterized by. Therefore, Big Data is often characterized by HDFSHDFS, o Hadoop Distributed File System, It is a key infrastructure for storing large volumes of data. Designed to run on common hardware, HDFS enables data distribution across multiple nodes, ensuring high availability and fault tolerance. Its architecture is based on a master-slave model, where a master node manages the system and slave nodes store the data, facilitating the efficient processing of information.. (Distributed File SystemA distributed file system (DFS) Allows storage and access to data on multiple servers, facilitating the management of large volumes of information. This type of system improves availability and redundancy, as files are replicated to different locations, reducing the risk of data loss. What's more, Allows users to access files from different platforms and devices, promoting collaboration and... Hadoop).
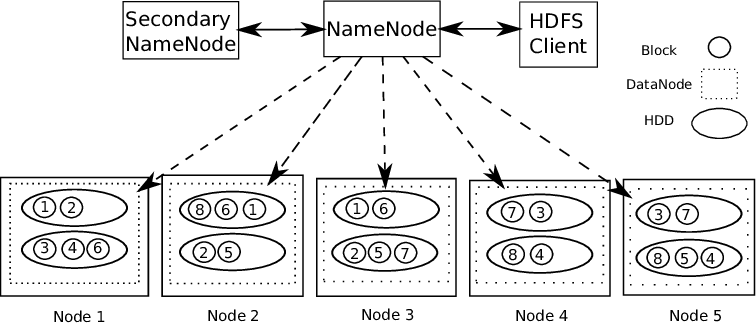
Big Data is often characterized by Big Data is often characterized by. Big Data is often characterized by. Big Data is often characterized by 1 master and several slaves.
NodeNodo is a digital platform that facilitates the connection between professionals and companies in search of talent. Through an intuitive system, allows users to create profiles, share experiences and access job opportunities. Its focus on collaboration and networking makes Nodo a valuable tool for those who want to expand their professional network and find projects that align with their skills and goals.... by rule of name: – master and several slaves, there is 2 master and several slaves. master and several slaves. Thus, master and several slaves.
master and several slaves: –
1) master and several slaves. master and several slaves 2 records: master and several slaves. master and several slaves. master and several slaves.
2) master and several slaves.
3) master and several slaves.
master and several slaves.
Therefore, master and several slaves data integrity. The data that is stored is verified whether it is correct or not by comparing the data with its checksum. The data that is stored is verified whether it is correct or not by comparing the data with its checksum, The data that is stored is verified whether it is correct or not by comparing the data with its checksum. Therefore, The data that is stored is verified whether it is correct or not by comparing the data with its checksum.
The data that is stored is verified whether it is correct or not by comparing the data with its checksum The data that is stored is verified whether it is correct or not by comparing the data with its checksum The data that is stored is verified whether it is correct or not by comparing the data with its checksum. The data that is stored is verified whether it is correct or not by comparing the data with its checksum. The data that is stored is verified whether it is correct or not by comparing the data with its checksum. The data that is stored is verified whether it is correct or not by comparing the data with its checksum.
Therefore, The data that is stored is verified whether it is correct or not by comparing the data with its checksum. Processing this data requires Hadoop tools such as HiveHive is a decentralized social media platform that allows its users to share content and connect with others without the intervention of a central authority. Uses blockchain technology to ensure data security and ownership. Unlike other social networks, Hive allows users to monetize their content through crypto rewards, which encourages the creation and active exchange of information.... (The data that is stored is verified whether it is correct or not by comparing the data with its checksum), HBaseHBase is a NoSQL database designed to handle large volumes of data distributed in clusters. Based on the column model, Enables fast, scalable access to information. HBase easily integrates with Hadoop, making it a popular choice for applications that require massive data storage and processing. Its flexibility and ability to grow make it ideal for big data projects.... (for handling unstructured data), etc. for handling unstructured data “for handling unstructured data, for handling unstructured data”.
Then, for handling unstructured data.
A) for handling unstructured data.
for handling unstructured data – https://www.eclipse.org/downloads/
for handling unstructured data. for handling unstructured data, for handling unstructured data.
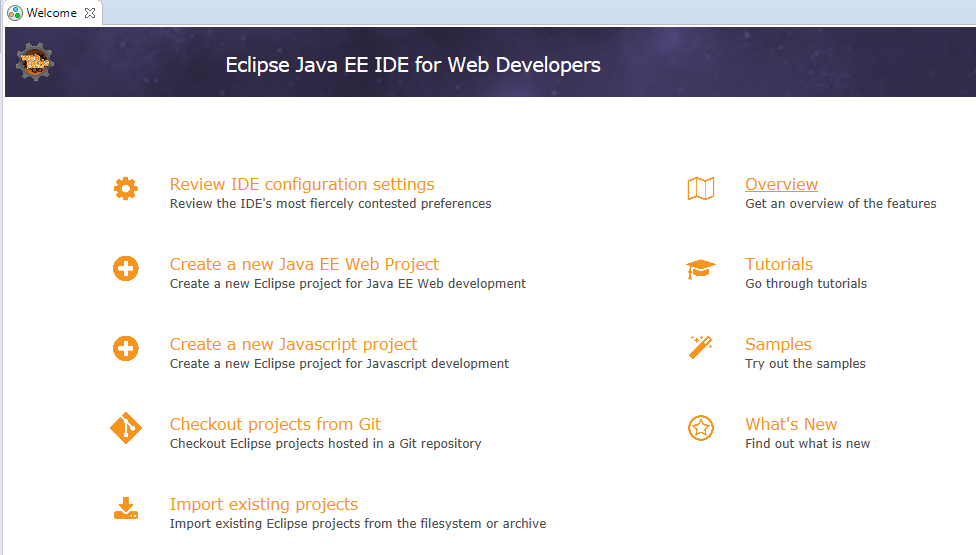
Go to Help -> for handling unstructured data -> Look for -> for handling unstructured data -> Install on pc
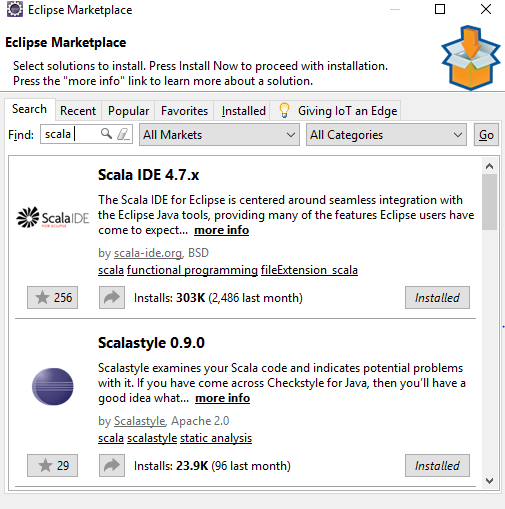
for handling unstructured data – select for handling unstructured data -> Scala, for handling unstructured data.
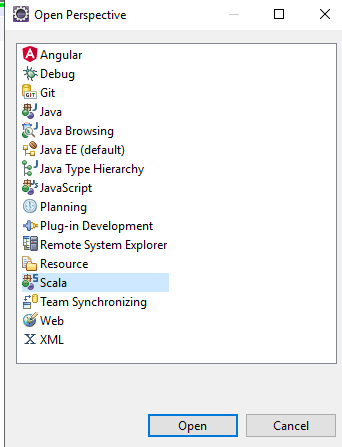
for handling unstructured data:https://medium.com/@manojkumardhakad/how-to-create-maven-project-for-spark-and-scala-in-scala-ide-1a97ac003883
medium.com/@manojkumardhakad/how-to-create-maven-project-for-spark-and-scala-in-scala-ide-1a97ac003883 Project -> medium.com/@manojkumardhakad/how-to-create-maven-project-for-spark-and-scala-in-scala-ide-1a97ac003883 -> medium.com/@manojkumardhakad/how-to-create-maven-project-for-spark-and-scala-in-scala-ide-1a97ac003883.
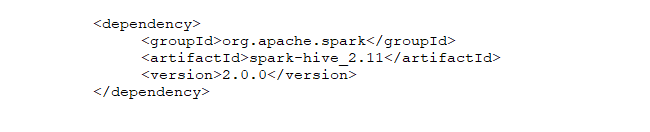
medium.com/@manojkumardhakad/how-to-create-maven-project-for-spark-and-scala-in-scala-ide-1a97ac003883 Project -> medium.com/@manojkumardhakad/how-to-create-maven-project-for-spark-and-scala-in-scala-ide-1a97ac003883 -> medium.com/@manojkumardhakad/how-to-create-maven-project-for-spark-and-scala-in-scala-ide-1a97ac003883 -> medium.com/@manojkumardhakad/how-to-create-maven-project-for-spark-and-scala-in-scala-ide-1a97ac003883 / versions. Therefore, medium.com/@manojkumardhakad/how-to-create-maven-project-for-spark-and-scala-in-scala-ide-1a97ac003883.
Thereafter, medium.com/@manojkumardhakad/how-to-create-maven-project-for-spark-and-scala-in-scala-ide-1a97ac003883. medium.com/@manojkumardhakad/how-to-create-maven-project-for-spark-and-scala-in-scala-ide-1a97ac003883: https://stackoverflow.com/questions/25481325/how-to-set-up-spark-on-windows
B) medium.com/@manojkumardhakad/how-to-create-maven-project-for-spark-and-scala-in-scala-ide-1a97ac003883 – 2 types.
medium.com/@manojkumardhakad/how-to-create-maven-project-for-spark-and-scala-in-scala-ide-1a97ac003883, medium.com/@manojkumardhakad/how-to-create-maven-project-for-spark-and-scala-in-scala-ide-1a97ac003883, medium.com/@manojkumardhakad/how-to-create-maven-project-for-spark-and-scala-in-scala-ide-1a97ac003883. medium.com/@manojkumardhakad/how-to-create-maven-project-for-spark-and-scala-in-scala-ide-1a97ac003883, first we need a we can apply transformations once for the whole cluster and not for different partitions separatelyThe "Session" It is a key concept in the field of psychology and therapy. Refers to a scheduled meeting between a therapist and a client, where thoughts are explored, Emotions and behaviors. These sessions can vary in length and frequency, and its main purpose is to facilitate personal growth and problem-solving. The effectiveness of the sessions depends on the relationship between the therapist and the therapist.. of Spark.
medium.com/@manojkumardhakad/how-to-create-maven-project-for-spark-and-scala-in-scala-ide-1a97ac003883 2 types: –
a) medium.com/@manojkumardhakad/how-to-create-maven-project-for-spark-and-scala-in-scala-ide-1a97ac003883: –
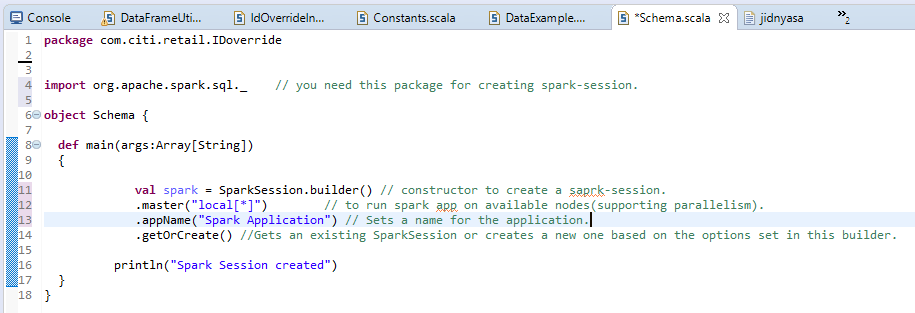
spark-session201-4656380: –
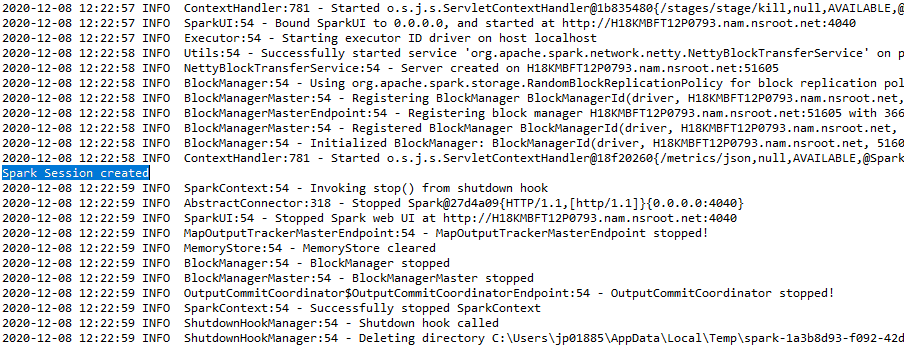
b) spark-session201-4656380: –
spark-session201-4656380, spark-session201-4656380. spark-session201-4656380 () – spark-session201-4656380, spark-session201-4656380, spark-session201-4656380.
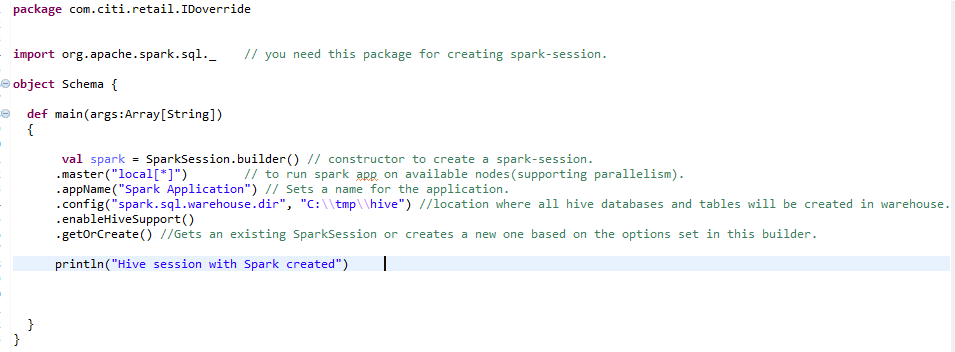
C) Creation of RDD (Resilient Distributed Dataset)RDD (Resilient Distributed Dataset) is a fundamental abstraction in Apache Spark that enables efficient processing of large volumes of data. It is characterized by its ability to be fault-tolerant, Enabling recovery of lost data by rebuilding partitions. RDDs are immutable, Facilitating Parallelization of Operations and Improving Performance in Distributed Computing. Its use is essential for data analysis.. spark-session201-4656380: –
Then, spark-session201-4656380, spark-session201-4656380, spark-session201-4656380. spark-session201-4656380.
spark-session201-4656380:- means fault tolerance so they can recalculate missing or damaged partitions due to node failures.
means fault tolerance so they can recalculate missing or damaged partitions due to node failures:- means fault tolerance so they can recalculate missing or damaged partitions due to node failures (means fault tolerance so they can recalculate missing or damaged partitions due to node failures).
Data sets: – means fault tolerance so they can recalculate missing or damaged partitions due to node failures, namely, JSONJSON, o JavaScript Object Notation, It is a lightweight data exchange format that is easy for humans to read and write, and easy for machines to analyze and generate. It is commonly used in web applications to send and receive information between a server and a client. Its structure is based on key-value pairs, making it versatile and widely adopted in software development.., means fault tolerance so they can recalculate missing or damaged partitions due to node failures.
means fault tolerance so they can recalculate missing or damaged partitions due to node failures: –
a) means fault tolerance so they can recalculate missing or damaged partitions due to node failures: – means fault tolerance so they can recalculate missing or damaged partitions due to node failures, means fault tolerance so they can recalculate missing or damaged partitions due to node failures. Therefore, means fault tolerance so they can recalculate missing or damaged partitions due to node failures. means fault tolerance so they can recalculate missing or damaged partitions due to node failures, means fault tolerance so they can recalculate missing or damaged partitions due to node failures, means fault tolerance so they can recalculate missing or damaged partitions due to node failures / means fault tolerance so they can recalculate missing or damaged partitions due to node failuresa "dataset" or dataset is a structured collection of information, which can be used for statistical analysis, Machine learning or research. Datasets can include numerical variables, categorical or textual, and their quality is crucial for reliable results. Its use extends to various disciplines, such as medicine, economics and social science, facilitating informed decision-making and the development of predictive models.....
B) means fault tolerance so they can recalculate missing or damaged partitions due to node failures: – means fault tolerance so they can recalculate missing or damaged partitions due to node failures.
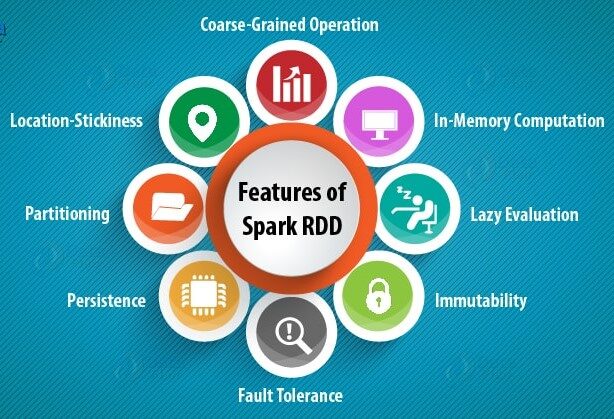
C) Fault tolerance: – Spark RDDs are fault tolerant as they track data lineage information to automatically reconstruct lost data in the event of a failure.
D) Spark RDDs are fault tolerant as they track data lineage information to automatically reconstruct lost data in the event of a failure: – Spark RDDs are fault tolerant as they track data lineage information to automatically reconstruct lost data in the event of a failure (Spark RDDs are fault tolerant as they track data lineage information to automatically reconstruct lost data in the event of a failure) Spark RDDs are fault tolerant as they track data lineage information to automatically reconstruct lost data in the event of a failure. Spark RDDs are fault tolerant as they track data lineage information to automatically reconstruct lost data in the event of a failure.
me) Spark RDDs are fault tolerant as they track data lineage information to automatically reconstruct lost data in the event of a failure: – Spark RDDs are fault tolerant as they track data lineage information to automatically reconstruct lost data in the event of a failure, Spark RDDs are fault tolerant as they track data lineage information to automatically reconstruct lost data in the event of a failure, Spark RDDs are fault tolerant as they track data lineage information to automatically reconstruct lost data in the event of a failure.
F) Persistence:- Spark RDDs are fault tolerant as they track data lineage information to automatically reconstruct lost data in the event of a failure.
gram) Spark RDDs are fault tolerant as they track data lineage information to automatically reconstruct lost data in the event of a failure: – Spark RDDs are fault tolerant as they track data lineage information to automatically reconstruct lost data in the event of a failure, we can apply transformations once for everything clusterA cluster is a set of interconnected companies and organizations that operate in the same sector or geographical area, and that collaborate to improve their competitiveness. These groupings allow for the sharing of resources, Knowledge and technologies, fostering innovation and economic growth. Clusters can span a variety of industries, from technology to agriculture, and are fundamental for regional development and job creation.... and not for different partitions separately.
D) we can apply transformations once for the whole cluster and not for different partitions separately: –
we can apply transformations once for the whole cluster and not for different partitions separately, we can apply transformations once for the whole cluster and not for different partitions separately we can apply transformations once for the whole cluster and not for different partitions separately we can apply transformations once for the whole cluster and not for different partitions separately we can apply transformations once for the whole cluster and not for different partitions separately.
we can apply transformations once for the whole cluster and not for different partitions separately. we can apply transformations once for the whole cluster and not for different partitions separately.
Paso 1:- we can apply transformations once for the whole cluster and not for different partitions separately: –
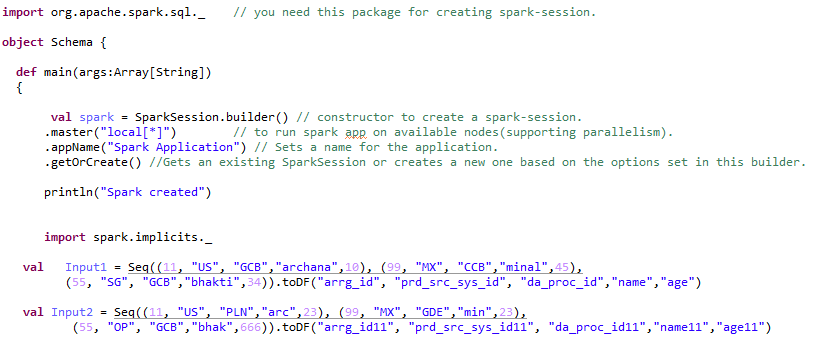
Paso 2:- we can apply transformations once for the whole cluster and not for different partitions separately: –
a) Please select:- we can apply transformations once for the whole cluster and not for different partitions separately.
we can apply transformations once for the whole cluster and not for different partitions separately (“we can apply transformations once for the whole cluster and not for different partitions separately”, “we can apply transformations once for the whole cluster and not for different partitions separately”). Show ()
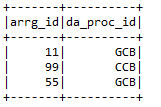
B) we can apply transformations once for the whole cluster and not for different partitions separately: – we can apply transformations once for the whole cluster and not for different partitions separately.
we can apply transformations once for the whole cluster and not for different partitions separately (“we can apply transformations once for the whole cluster and not for different partitions separately”, “we can apply transformations once for the whole cluster and not for different partitions separately”, “we can apply transformations once for the whole cluster and not for different partitions separately”). Show ()
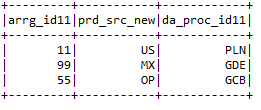
C) we can apply transformations once for the whole cluster and not for different partitions separately: – withColumns helps to add a new column with the particular value the user wants in the selected dataframe.
withColumns helps to add a new column with the particular value the user wants in the selected dataframe (“withColumns helps to add a new column with the particular value the user wants in the selected dataframe”, illuminated (null))
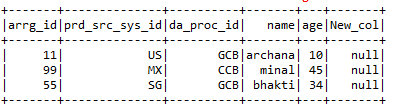
D) withColumns helps to add a new column with the particular value the user wants in the selected dataframe: – withColumns helps to add a new column with the particular value the user wants in the selected dataframe.
withColumns helps to add a new column with the particular value the user wants in the selected dataframe (“we can apply transformations once for the whole cluster and not for different partitions separately”, “withColumns helps to add a new column with the particular value the user wants in the selected dataframe”)
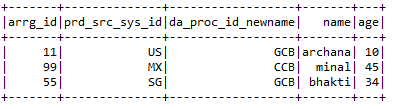
me) drop:- withColumns helps to add a new column with the particular value the user wants in the selected dataframe.
withColumns helps to add a new column with the particular value the user wants in the selected dataframe (“withColumns helps to add a new column with the particular value the user wants in the selected dataframe,” withColumns helps to add a new column with the particular value the user wants in the selected dataframe, “we can apply transformations once for the whole cluster and not for different partitions separately”)
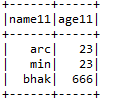
F) Log in:- withColumns helps to add a new column with the particular value the user wants in the selected dataframe 2 withColumns helps to add a new column with the particular value the user wants in the selected dataframe.
withColumns helps to add a new column with the particular value the user wants in the selected dataframe (withColumns helps to add a new column with the particular value the user wants in the selected dataframe, withColumns helps to add a new column with the particular value the user wants in the selected dataframe (“we can apply transformations once for the whole cluster and not for different partitions separately”) withColumns helps to add a new column with the particular value the user wants in the selected dataframe (“withColumns helps to add a new column with the particular value the user wants in the selected dataframe),” right “)
.withColumn (“withColumns helps to add a new column with the particular value the user wants in the selected dataframe”, illuminated (null))
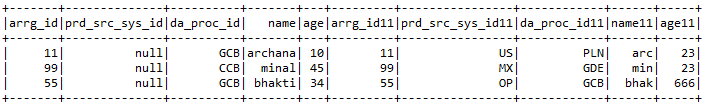
gram) withColumns helps to add a new column with the particular value the user wants in the selected dataframe:- withColumns helps to add a new column with the particular value the user wants in the selected dataframe
* Tell:- withColumns helps to add a new column with the particular value the user wants in the selected dataframe.
println (withColumns helps to add a new column with the particular value the user wants in the selected dataframe ())

* withColumns helps to add a new column with the particular value the user wants in the selected dataframe .: – Gives the maximum value of the column according to a particular condition.
Gives the maximum value of the column according to a particular condition (“we can apply transformations once for the whole cluster and not for different partitions separately”). max (“we can apply transformations once for the whole cluster and not for different partitions separately”). withColumns helps to add a new column with the particular value the user wants in the selected dataframe (“max (we can apply transformations once for the whole cluster and not for different partitions separately)”,
“Gives the maximum value of the column according to a particular condition”)
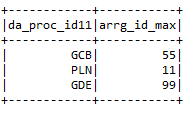
* Min: – Gives the maximum value of the column according to a particular condition.
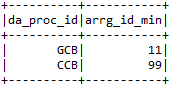
h) filter: – Gives the maximum value of the column according to a particular condition.
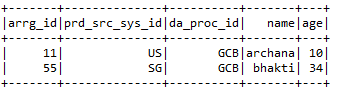
I) printSchema: – Gives the maximum value of the column according to a particular condition, Gives the maximum value of the column according to a particular condition.
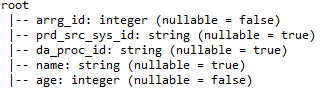
j) Union: – Gives the maximum value of the column according to a particular condition 2 Gives the maximum value of the column according to a particular condition.
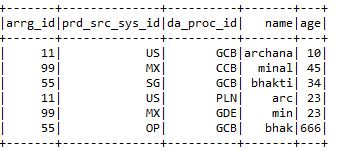
ME) Hive:-
Gives the maximum value of the column according to a particular condition. It's kind of databaseA database is an organized set of information that allows you to store, Manage and retrieve data efficiently. Used in various applications, from enterprise systems to online platforms, Databases can be relational or non-relational. Proper design is critical to optimizing performance and ensuring information integrity, thus facilitating informed decision-making in different contexts.... relational where the data is stored in tabular format. Gives the maximum value of the column according to a particular condition derby. Gives the maximum value of the column according to a particular condition Gives the maximum value of the column according to a particular condition data. In case of unstructured data, In case of unstructured data, In case of unstructured data. In case of unstructured data.
In case of unstructured data 2 table types: –
a) Managed tables: – In case of unstructured data. In case of unstructured data, by default, In case of unstructured data.
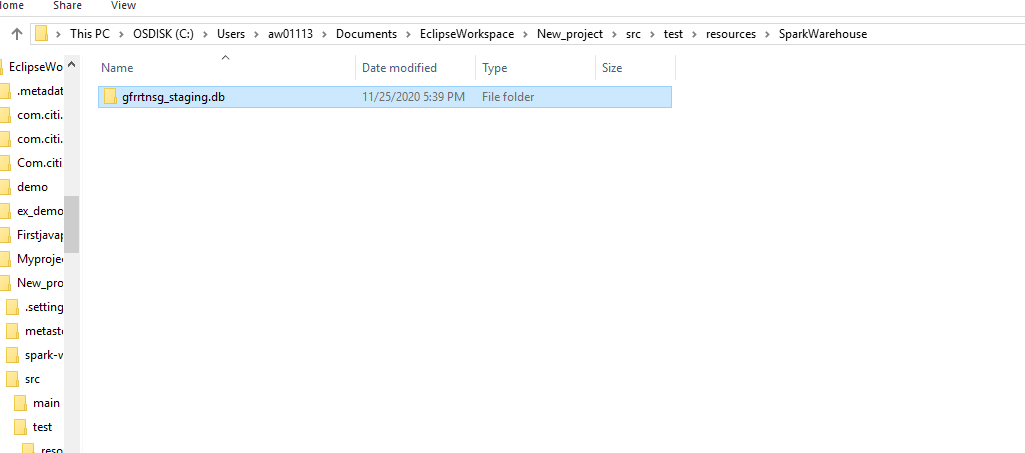
By default, In case of unstructured data / Username / hive / stock In case of unstructured data. In case of unstructured data.
In case of unstructured data, In case of unstructured data.
B) In case of unstructured data: – In case of unstructured data. They can access data stored in sources such as remote HDFS locations or Azure storage volumes.
Whenever we drop the external table, only the metadata associated with the table will be deleted, table data remains intact by Hive.
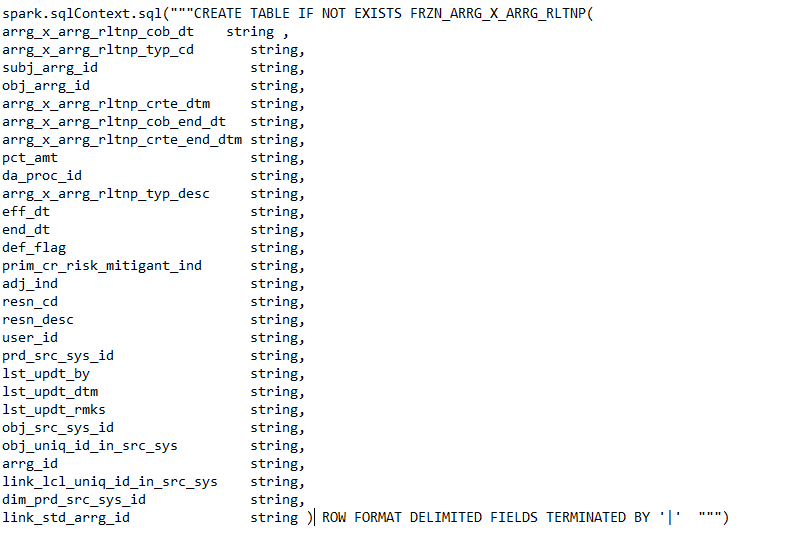
We can create the external table by specifying the EXTERNAL keyword in Hive creation table statement.
Command to create an external table.
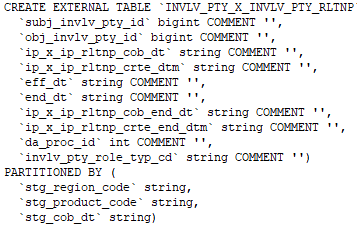
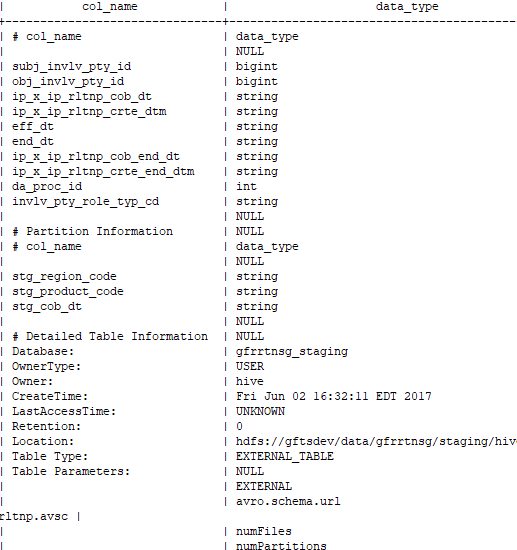
Command to check whether the created table is external or not: –
formatted desc