
This post was released as part of the Data Science Blogathon.
Overview
Introduction
Apache SparkApache Spark is an open-source data processing engine that enables the analysis of large volumes of information quickly and efficiently. Its design is based on memory, which optimizes performance compared to other batch processing tools. Spark is widely used in big data applications, Machine Learning and Real-Time Analytics, thanks to its ease of use and... It is a data processing framework that can quickly perform processing tasks on very large datasets and can also distribute data processing tasks across multiple computers, either by itself or in conjunction with other distributed IT tools. It's an ultra-fast unified analytics engine for big data and machine learning.
To support Python with Spark, Apache Spark community released a tool, PySpark. With PySpark, you can work with RDD in the Python programming language.
Spark's components are:
- Spark Core
- Spark SQL
- Spark Streaming
- Spark MLlib
- GraphX
- Spark R
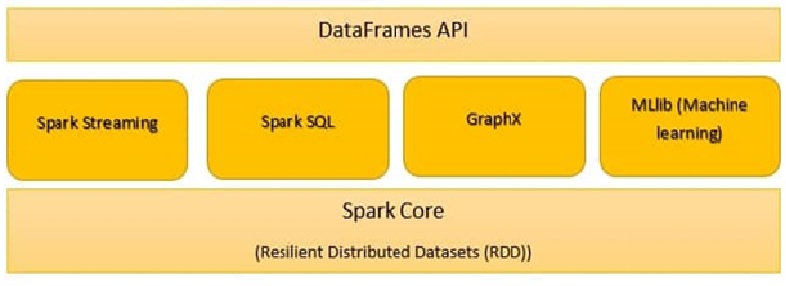
Spark Core
All the functionalities provided by Apache Spark are centered on top of Spark Core. Manage all the functionalities of E / S essential. Used for task dispatch and crash recovery. Spark Core is embedded with a special collection called RDD (resilient distributed data set). RDD is among the Spark abstractions. Spark RDD handles the partitioning of data across all nodes of a clusterA cluster is a set of interconnected companies and organizations that operate in the same sector or geographical area, and that collaborate to improve their competitiveness. These groupings allow for the sharing of resources, Knowledge and technologies, fostering innovation and economic growth. Clusters can span a variety of industries, from technology to agriculture, and are fundamental for regional development and job creation..... Keeps them in the cluster memory pool as a single unit. There are two operations done in RDD:
Transformation: It is a function that produces new RDDs from existing RDDs.
Action: In transformation, RDDs create each other. But when we want to work with the actual dataset, then, at that point, we use Action.
Spark SQL
The Spark SQL component is a distributed framework for processing structured data. Spark SQL works to enter structured and semi-structured information. It also enables powerful and interactive analytical applications on streaming and historical data.. DataFrames and SQL provide a common way to access a range of data sources. Its main characteristic is to be an optimizer based on costs and fault tolerance of medium query.
Spark Streaming
It is a plug-in to the Spark core API that enables scalable stream processing, High performance and fault tolerant of live data transmissions. Spark Streaming, bundles live data into small batches. It is then delivered to the batch system for processing.. It also provides fault tolerance characteristics.
Spark GraphX:
GraphX on Spark is an API for graphs and parallel execution of graphs. It is a network graphics analysis engine and data warehouse. In the graphs it is also possible to group, categorize, travel, search and find routes.
SparkR:
SparkR provides a distributed data frame implementation. Supports operations as selection, filtered out, aggregation, but in large data sets.
Spark MLlib:
Spark MLlib is used to perform machine learning on Apache Spark. MLlib consists of popular algorithms and utilities. MLlib on Spark is a scalable machine learning library that analyzes both high-quality and high-speed algorithm. Machine learning algorithms as regression, classification, groupingThe "grouping" It is a concept that refers to the organization of elements or individuals into groups with common characteristics or objectives. This process is used in various disciplines, including psychology, Education and biology, to facilitate the analysis and understanding of behaviors or phenomena. In the educational field, for instance, Grouping can improve interaction and learning among students by encouraging work.., pattern mining and collaborative filtering. Lower-level machine learning primitives, as the generic gradient descent optimization algorithm, they are also present in MLlib.
Spark.ml is the main machine learning API for Spark. Library Spark.ml offers a top-level API built on top of DataFrames to build ML pipelines.
Spark MLlib tools are provided below:
- ML Algorithms
- Characterization
- Pipelines
- Persistence
- Utilities
-
ML Algorithms
ML algorithms form the core of MLlib. These include common learning algorithms like classification, regression, collaborative grouping and filtering.
MLlib standardizes APIs to help combine multiple algorithms into a single pipeline or workflow. The key concepts are the Pipelines API, where the pipeline concept is inspired by the scikit-learn project.
Transformer:
A transformer is an algorithm that can transform a DataFrame into another DataFrame. Technically, a Transformer implements a transform method (), which converts one DataFrame to another, generally adding one or more columns. As an example:
A feature transformer can take a DataFrame, read a column (as an example, text), assign it to a new column (as an example, feature vectors) and generate a new DataFrame with mapped column attached.
A learning model can take a DataFrame, read the column containing the feature vectors, predict the label for each feature vector and generate a new DataFrame with predicted labels added as a column.
EstimatorThe "Estimator" is a statistical tool used to infer characteristics of a population from a sample. It relies on mathematical methods to provide accurate and reliable estimates. There are different types of estimators, such as the unbiased and the consistent, that are chosen according to the context and objective of the study. Its correct use is essential in scientific research, surveys and data analysis....:
An estimator is an algorithm that can be fitted to a DataFrame to produce a transformer. Technically, an Estimator implements a fit method (), which accepts a DataFrame and produces a Model, what is a transformer. As an example, a learning algorithm like LogisticRegression is an Estimator, and call fit () train a LogisticRegressionModel, what is a model and, therefore, a transformer.
Transformer.transform () and Estimator.fit () they are stateless. In the future, stateful algorithms can be compatible with alternative concepts.
Each instance of a Transformer or Estimator has a unique ID, which is useful for specifying parametersThe "parameters" are variables or criteria that are used to define, measure or evaluate a phenomenon or system. In various fields such as statistics, Computer Science and Scientific Research, Parameters are critical to establishing norms and standards that guide data analysis and interpretation. Their proper selection and handling are crucial to obtain accurate and relevant results in any study or project.... (described below).
-
Characterization
Characterization includes extraction, transformation, decrease in dimensionality and feature selection.
- Feature Extraction is about extracting features from raw data.
- Feature transformation includes scaling, renew or modify features
- Feature selection involves choosing a subset of must-have features from a large feature set.
-
Pipelines:
A pipeline chains multiple transformers and estimators to specify an AA workflow. It also provides tools to build, examine and adjust ML Pipelines.
In machine learning, it is common to run a sequence of algorithms to process and learn from the data. MLlib represents a workflow as PipelinePipeline is a term that is used in a variety of contexts, mainly in technology and project management. It refers to a set of processes or stages that allow the continuous flow of work from the conception of an idea to its final implementation. In the field of software development, for instance, A pipeline can include scheduling, Testing and deployment, thus guaranteeing greater efficiency and quality in the..., that it is a sequence of Pipeline Stages (Transformers and Estimators) to be executed in a specific order. We will use this simple workflow as a running example in this section.
Example: the pipeline sample shown below does the preprocessing of data in a specific order as given below:
1. Apply the String Indexer method to find the indexThe "Index" It is a fundamental tool in books and documents, which allows you to quickly locate the desired information. Generally, it is presented at the beginning of a work and organizes the contents in a hierarchical manner, including chapters and sections. Its correct preparation facilitates navigation and improves the understanding of the material, making it an essential resource for both students and professionals in various areas.... of the categorical columns
2. Apply OneHot encoding for categorical columns
3. Apply string indexer for column “label” from variableIn statistics and mathematics, a "variable" is a symbol that represents a value that can change or vary. There are different types of variables, and qualitative, that describe non-numerical characteristics, and quantitative, representing numerical quantities. Variables are fundamental in experiments and studies, since they allow the analysis of relationships and patterns between different elements, facilitating the understanding of complex phenomena.... de salida
4. VectorAssembler applies to both categorical columns and numeric columns. VectorAssembler is a transformer that combines a given list of columns into a single vector column.
The pipeline workflow will run the data modeling in the specific order above.
from pyspark.ml.feature import OneHotEncoderEstimator, StringIndexer, VectorAssembler
categoricalColumns = ['job', 'marital', 'education', 'default', 'housing', 'loan']
stages = []
for categoricalCol in categoricalColumns:
    stringIndexer = StringIndexer(inputCol = categoricalCol, outputCol = categoricalCol + 'Indexer')
    encoder = OneHotEncoderEstimator(inputCols=[stringIndexer.getOutputCol()], outputCols=[categoricalCol + "Vec"])
    stages += [stringIndexer, encoder]
label_stringIdx = StringIndexer(inputCol="deposit", outputCol="label")
stages += [label_stringIdx]
numericColumns = ['age', 'balance', 'duration']
assemblerInputs = [c + "Vec" for c in categoricalColumns] + numericColumns
Vassembler = VectorAssembler(inputCols = assemblerInputs, outputCol="features")
stages += [Vassembler]
from pyspark.ml import Pipeline pipeline = Pipeline(stages = stages) pipelineModel = pipeline.fit(df) df = pipelineModel.transform(df) selectedCols = ['label', 'features'] + cols df = df.select(selectedCols)
Data frame
Los marcos de datos proporcionan una API más fácil de utilizar que los RDD. DataFrame-based API for MLlib provides a consistent API across ML algorithms and in multiple languages. Data frameworks facilitate hands-on machine learning pipelines, in particular feature transformations.
from pyspark.sql import SparkSession spark = SparkSession.builder.appName('mlearnsample').getOrCreate() df = spark.read.csv('loan_bank.csv', header = True, inferSchema = True) df.printSchema() -
Persistence:
Persistence helps save and load algorithms, models and pipelines. This helps reduce time and efforts, since the model is persistent, can be loaded / reuse at any time when necessary.
from pyspark.ml.classification import LogisticRegression
lr = LogisticRegression(featuresCol="features", labelCol="label")
lrModel = lr.fit(train)
de pyspark.ml.evaluation import BinaryClassificationEvaluator
evaluador = BinaryClassificationEvaluator ()
print (‘Test Area Under ROC’, evaluator.evaluate (predictions))
predictions = lrModel.transform(test) predictions.select('age', 'label', 'rawPrediction', 'prediction').show() -
Utilities:
Utilities for linear algebra, statistics and data management. Example: mllib.linalg are the MLlib utilities for linear algebra.
Reference material:
https://spark.apache.org/docs/latest/ml-guide.html
Final notes
Spark MLlib is necessary if it comes to big data and machine learning. In this post, learned about the details of Spark MLlib, data frames and pipelines. In the future post, we will work on practical code to implement Pipelines and build data models using MLlib.





