
This article was published as part of the Data Science Blogathon.
Introduction
Data visualization in Python is perhaps one of the most used features for data science with Python today. Libraries in Python come with many different features that allow users to create highly custom graphics, elegant and interactive.
In this article, we will cover the use of Matplotlib, Seaborn, as well as an introduction to other alternative packages that can be used in Python visualization.
Inside Matplotlib and Seaborn, we'll cover some of the most widely used plots in the data science world for easy visualization.
Later in the article, we will go over another powerful feature in Python visualizations, la subtrama, and we covered a basic tutorial for creating subplots.
Useful packages for visualizations in python
Matplotlib
Matplotlib is a Python display library for 2D array diagrams. Matplotlib is written in Python and makes use of the NumPy library. Can be used in Python and IPython shells, Jupyter laptops and web application servers. Matplotlib comes with a wide variety of graphs like line, bar, dispersion, histogram, etc. that can help us deepen our understanding of trends, patterns and correlations. It was introduced by John Hunter in 2002.
Seaborn
Seaborn is a dataset-oriented library for performing statistical representations in Python. It is developed on matplotlib and to create different visualizations. It is integrated with pandas data structures. The library does the mapping and aggregation internally to create informative visuals. It is recommended to use a Jupyter interface / IPython and modo matplotlib.
Bokeh
Bokeh is an interactive display library for modern web browsers. It is suitable for streaming or large data assets and can be used to develop interactive charts and dashboards. There is a wide range of intuitive graphics in the library that can be leveraged to develop solutions. Works closely with PyData tools. The library is suitable for creating custom images according to the required use cases. Images can also be made interactive to serve as a hypothetical scenario model. All code is open source and available on GitHub.
Altair
Altair is a declarative statistical display library for Python. Altair API is easy to use and consistent, y está construida sobre la especificación Vega-Lite JSONJSON, o JavaScript Object Notation, It is a lightweight data exchange format that is easy for humans to read and write, and easy for machines to analyze and generate. It is commonly used in web applications to send and receive information between a server and a client. Its structure is based on key-value pairs, making it versatile and widely adopted in software development... The declarative library indicates that when creating any visual object, we need to define the links between the data columns and the channels (X axis, Axis y, size, color). With the help of Altair, informative images can be created with minimal code. Altair has a declarative grammar of both visualization and interaction.
tramadamente
plotly.py is an interactive display library, open source, high level, declarative and browser-based for Python. Contains a variety of useful visualization including scientific charts, 3D graphics, statistical graphs, financial charts, among others. Plot graphics can be viewed in Jupyter notebooks, standalone HTML files or hosted online. Plotly library offers options for interaction and editing. The robust API works perfectly in both web and local browser mode.
ggplot
ggplot is a Python implementation of the graphing grammar. Graphics grammar refers to mapping data to aesthetic attributes (color, shape, size) and geometric objects (points, lines, bars). The basic building blocks according to the grammar of graphs are data, geom (geometric objects), statistics (statistical transformations), scale, coordinate system and facet.
Using ggplot in Python allows you to develop informative visualizations incrementally, understanding the nuances of the data first and then adjusting the components to improve visual representations.
How to use the correct visualization?
To extract the required information from the different visual elements that we create, it is essential that we use the correct representation based on the type of data and the questions we are trying to understand. Then, we will look at a set of most used representations and how we can use them most effectively.
Bar graphic
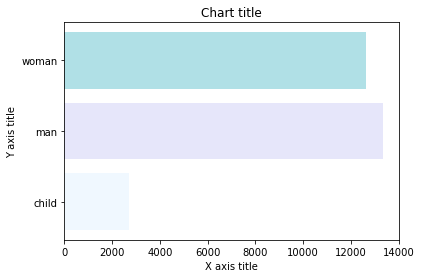
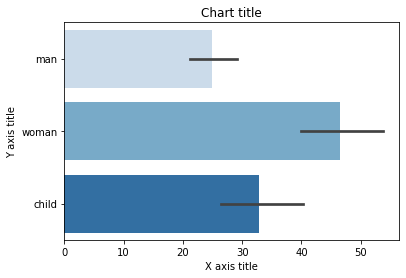
a bar graphicThe bar chart is a visual representation of data that uses rectangular bars to show comparisons between different categories. Each bar represents a value and its length is proportional to it. This type of chart is useful for visualizing and analyzing trends, facilitating the interpretation of quantitative information. It is widely used in various disciplines, such as statistics, Marketing and research, due to its simplicity and effectiveness.... se utiliza cuando queremos comparar valores métricos en diferentes subgrupos de datos. If we have a greater number of groups, a bar chart is preferred over a column chart.
Bar chart using Matplotlib
#Creating the dataset
df = sns.load_dataset('titanic')
df=df.groupby('who')['fare'].sum().to_frame().reset_index()

#Creating the bar chart
plt.barh(df['who'],df['fare'],color = ['#F0F8FF','#E6E6FA','#B0E0E6'])

#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')

#Show the plot
plt.show()
Bar chart with Seaborn
#Creating bar plot
sns.barplot(x = 'fare',y = 'who',data = titanic_dataset,palette = "Blues")
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
# Show the plot
plt.show()
Column chart
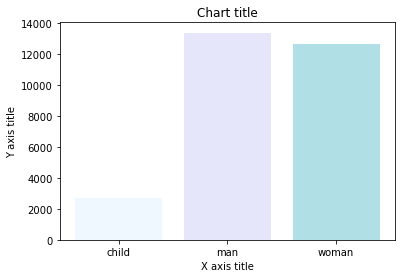
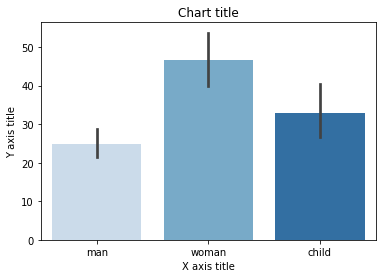
Column charts are mainly used when we need to compare a single category of data between individual sub-items, for instance, when comparing income between regions.
Column chart using Matplotlib
#Creating the dataset
df = sns.load_dataset('titanic')
df=df.groupby('who')['fare'].sum().to_frame().reset_index()
#Creating the column plot
plt.bar(df['who'],df['fare'],color = ['#F0F8FF','#E6E6FA','#B0E0E6'])
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
#Show the plot
plt.show()
Column chart with Seaborn
#Reading the dataset
titanic_dataset = sns.load_dataset('titanic')
#Creating column chart
sns.barplot(x = 'who',y = 'fare',data = titanic_dataset,palette = "Blues")
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
# Show the plot
plt.show()
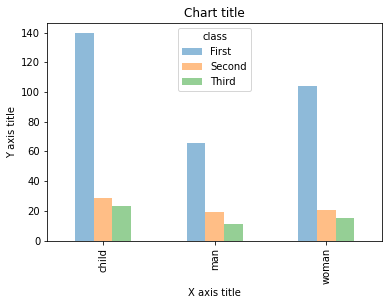
Clustered bar chart
A clustered bar chart is used when we want to compare the values in certain groups and subgroups.
Clustered bar chart using Matplotlib
#Creating the dataset
df = sns.load_dataset('titanic')
df_pivot = pd.pivot_table(df, values="fare",index="who",columns="class", aggfunc=np.mean)
#Creating a grouped bar chart
ax = df_pivot.plot(kind="bar",alpha=0.5)
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
# Show the plot
plt.show()
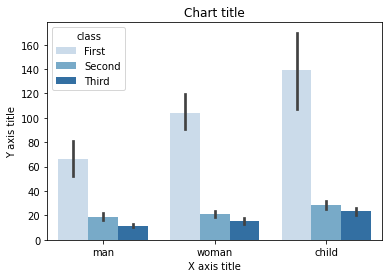
Bar chart grouped with Seaborn
#Reading the dataset
titanic_dataset = sns.load_dataset('titanic')
#Creating the bar plot grouped across classes
sns.barplot(x = 'who',y = 'fare',hue="class",data = titanic_dataset, palette = "Blues")
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
# Show the plot
plt.show()
Stacked bar chart
A stacked bar chart is used when we want to compare the total sizes of the available groups and the composition of the different subgroups.
Stacked bar chart using Matplotlib
# Stacked bar chart
#Creating the dataset
df = pd.DataFrame(columns=["A","B", "C","D"],
                  data=[["E",0,1,1],
                        ["F",1,1,0],
                        ["G",0,1,0]])

df.plot.bar(x='A', y =["B", "C","D"],  stacked=True,  width = 0.4,alpha=0.5)

#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')

#Show the plot
plt.show()
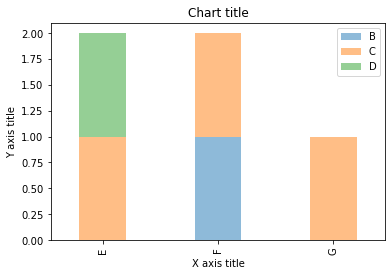
Stacked Bar Chart with Seaborn
dataframe = pd.DataFrame(columns=["A","B", "C","D"],
                  data=[["E",0,1,1],
                        ["F",1,1,0],
                        ["G",0,1,0]])
dataframe.set_index('A').T.plot(kind='bar', stacked=True)
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
# Show the plot
plt.show()
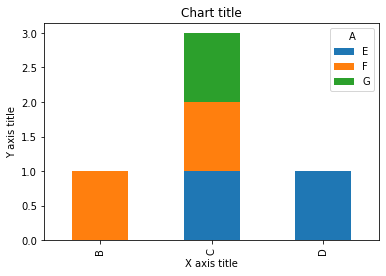
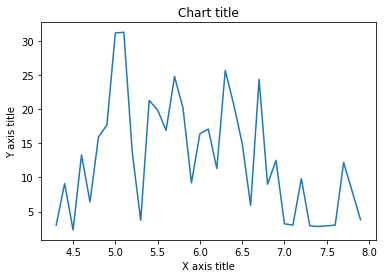
Line graph
Se utiliza un line graphThe line chart is a visual tool used to represent data over time. It consists of a series of points connected by lines, which allows you to observe trends, Fluctuations and patterns in the data. This type of chart is especially useful in areas such as economics, Meteorology and scientific research, making it easier to compare different data sets and identify behaviors across the board.. para la representación de puntos de datos continuos. This visual element can be used effectively when we want to understand the trend over time..
Line chart using Matplotlib
#Creating the dataset
df = sns.load_dataset("iris")
df=df.groupby('sepal_length')['sepal_width'].sum().to_frame().reset_index()
#Creating the line chart
plt.plot(df['sepal_length'], df['sepal_width'])
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
#Show the plot
plt.show()
Line chart with Seaborn
#Creating the dataset
cars = ['AUDI', 'BMW', 'NISSAN',
        'TESLA', 'HYUNDAI', 'HONDA']
data = [20, 15, 15, 14, 16, 20]
#Creating the pie chart
plt.pie(data, labels = cars,colors = ['#F0F8FF','#E6E6FA','#B0E0E6','#7B68EE','#483D8B'])
#Adding the aesthetics
plt.title('Chart title')
#Show the plot
plt.show()
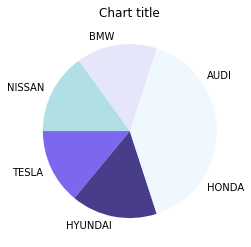
Pie chart
Pie charts can be used to identify proportions of the different components in a given whole..
Pie chart with Matplotlib
#Creating the dataset
cars = ['AUDI', 'BMW', 'NISSAN',
        'TESLA', 'HYUNDAI', 'HONDA']
data = [20, 15, 15, 14, 16, 20]
#Creating the pie chart
plt.pie(data, labels = cars,colors = ['#F0F8FF','#E6E6FA','#B0E0E6','#7B68EE','#483D8B'])
#Adding the aesthetics
plt.title('Chart title')
#Show the plot
plt.show()
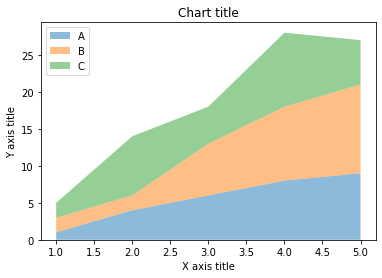
Area chart
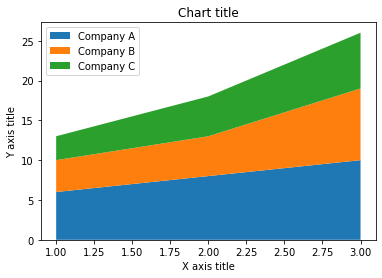
Area charts are used to track changes over time for one or more groups. Area charts are preferred over line charts when we want to capture changes over time for more than one group.
Area graph using Matplotlib
#Reading the dataset
x=range(1,6)
y =[ [1,4,6,8,9], [2,2,7,10,12], [2,8,5,10,6] ]
#Creating the area chart
ax = plt.gca()
ax.stackplot(x, Y, labels=['A','B','C'],alpha=0.5)
#Adding the aesthetics
plt.legend(loc ="upper left")
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
#Show the plot
plt.show()
Area chart using Seaborn
# Data
years_of_experience =[1,2,3]
salary=[ [6,8,10], [4,5,9], [3,5,7] ]
# Plot
plt.stackplot(years_of_experience,salary, labels=['Company A','Company B','Company C'])
plt.legend(loc ="upper left")
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
# Show the plot
plt.show()
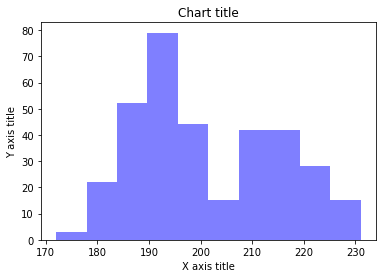
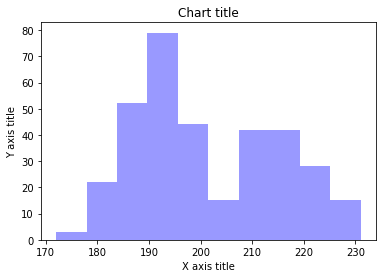
Column histogram
The histogramasHistograms are graphical representations that show the distribution of a dataset. They are constructed by dividing the range of values into intervals, O "Bins", and counting how much data falls in each interval. This visualization allows you to identify patterns, trends and variability of data effectively, facilitating statistical analysis and informed decision-making in various disciplines.... de columna se utilizan para observar la distribución de una sola variableIn statistics and mathematics, a "variable" is a symbol that represents a value that can change or vary. There are different types of variables, and qualitative, that describe non-numerical characteristics, and quantitative, representing numerical quantities. Variables are fundamental in experiments and studies, since they allow the analysis of relationships and patterns between different elements, facilitating the understanding of complex phenomena.... con pocos puntos de datos.
Column chart using Matplotlib
#Creating the dataset
penguins = sns.load_dataset("penguins")
#Creating the column histogram
ax = plt.gca()
ax.hist(penguins['flipper_length_mm'], color="blue",alpha=0.5, bins=10)
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
#Show the plot
plt.show()
Column chart with Seaborn
#Reading the dataset
penguins_dataframe = sns.load_dataset("penguins")
#Plotting bar histogram
sns.distplot(penguins_dataframe['flipper_length_mm'], kde = False, color="blue", bins=10)
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
# Show the plot
plt.show()
Line histogram
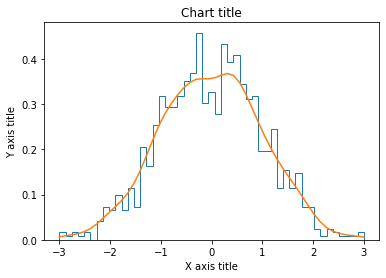
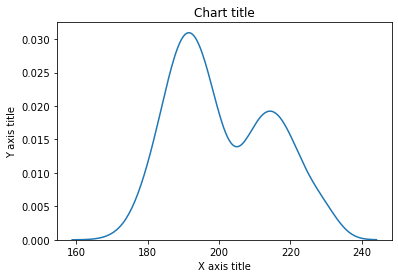
Line histograms are used to observe the distribution of a single variable with many data points.
Line Histogram Plot Using Matplotlib
#Creating the dataset
df_1 = np.random.normal(0, 1, (1000, ))
density = stats.gaussian_kde(df_1)
#Creating the line histogram
n, x, _ = plt.hist(df_1, bins=np.linspace(-3, 3, 50), histtype=u'step', density=True)
plt.plot(x, density(x))
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
#Show the plot
plt.show()
Line Histogram Chart with Seaborn
#Reading the dataset
penguins_dataframe = sns.load_dataset("penguins")
#Plotting line histogram
sns.distplot(penguins_dataframe['flipper_length_mm'], hist = False, where = True, label="Africa")
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
# Show the plot
plt.show()
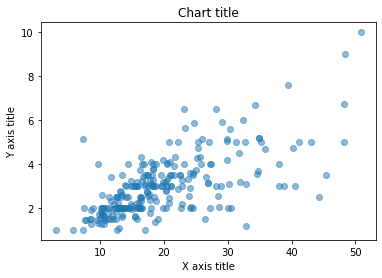
Scatter plot
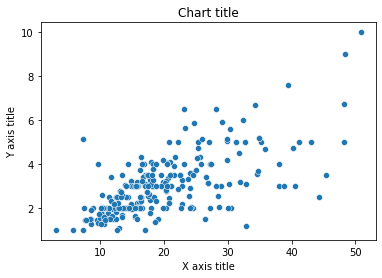
Scatter charts can be used to identify relationships between two variables. Can be used effectively in circumstances where the dependent variable can have multiple values for the independent variable.
Scatter plot using Matplotlib
#Creating the dataset
df = sns.load_dataset("tips")
#Creating the scatter plot
plt.scatter(df['total_bill'],df['tip'],alpha=0.5 )
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
#Show the plot
plt.show()
Scatter plot using Seaborn
#Reading the dataset
bill_dataframe = sns.load_dataset("tips")
#Creating scatter plot
sns.scatterplot(data=bill_dataframe, x="total_bill", y ="tip")
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
# Show the plot
plt.show()
Bubble chart
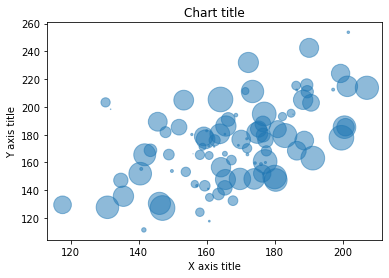
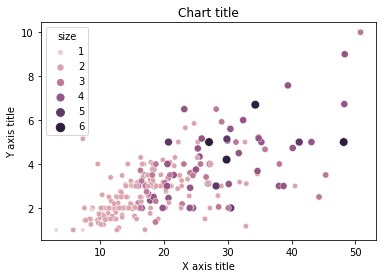
Scatter charts can be used to represent and show relationships between three variables.
Bubble chart with Matplotlib
#Creating the dataset
np.random.seed(42)
N = 100
x = np.random.normal(170, 20, N)
y = x + np.random.normal(5, 25, N)
colors = np.random.rand(N)
area = (25 * np.random.rand(N))**2
df = pd.DataFrame({
    'X': x,
    'Y': Y,
    'Colors': colors,
    "bubble_size":area})
#Creating the bubble chart
plt.scatter('X', 'Y', s="bubble_size",alpha=0.5, data=df)
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
#Show the plot
plt.show()
Bubble chart with Seaborn
#Reading the dataset
bill_dataframe = sns.load_dataset("tips")
#Creating bubble plot
sns.scatterplot(data=bill_dataframe, x="total_bill", y ="tip", hue="size", size="size")
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
# Show the plot
plt.show()
Box plot
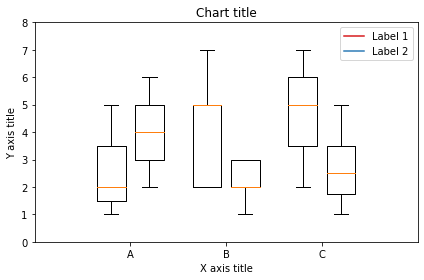
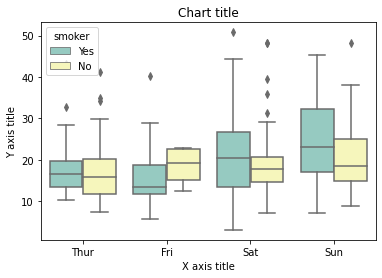
A box plot is used to show the shape of the distribution, its central value and its variability.
Box plot using Matplotlib
from past.builtins import xrange
#Creating the dataset
df_1 = [[1,2,5], [5,7,2,2,5], [7,2,5]]
df_2 = [[6,4,2], [1,2,5,3,2], [2,3,5,1]]
#Creating the box plot
ticks = ['A', 'B', 'C']
plt.figure()
bpl = plt.boxplot(df_1, positions=np.array(xrange(len(df_1)))*2.0-0.4, sym='', widths=0.6)
bpr = plt.boxplot(df_2, positions=np.array(xrange(len(df_2)))*2.0+0.4, sym='', widths=0.6)
plt.plot([], c="#D7191C", label="Label 1")
plt.plot([], c="#2C7BB6", label="Label 2")
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
plt.legend()
plt.xticks(xrange(0, len(ticks) * 2, 2), ticks)
plt.xlim(-2, len(ticks)*2)
plt.ylim(0, 8)
plt.tight_layout()
#Show the plot
plt.show()
Box plot using Seaborn
#Reading the dataset
bill_dataframe = sns.load_dataset("tips")
#Creating boxplots
ax = sns.boxplot(x="day", y ="total_bill", hue="smoker", data=bill_dataframe, palette="Set3")
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
# Show the plot
plt.show()
Waterfall chart
A waterfall chart can be used to explain the gradual transition in the value of a variable that is subject to increases or decreases.
#Reading the dataset
test = pd.Series(-1 + 2 * np.random.rand(10), index=list('abcdefghij'))
#Function for makig a waterfall chart
def waterfall(series):
    df = pd.DataFrame({'pos':np.maximum(series,0),'neg':np.minimum(series,0)})
    blank = series.cumsum().shift(1).fillna(0)
    df.plot(kind='bar', stacked=True, bottom=blank, color=['r','b'], alpha=0.5)
    step = blank.reset_index(drop=True).repeat(3).shift(-1)
    step[1::3] = np.nan
    plt.plot(step.index, step.values,'k')
#Creating the waterfall chart
waterfall(test)
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
#Show the plot
plt.show()
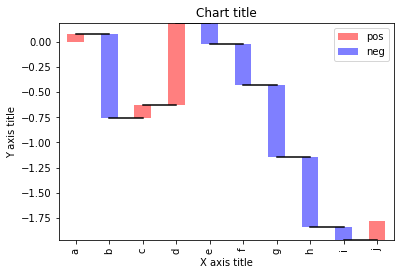
diagram of Venn
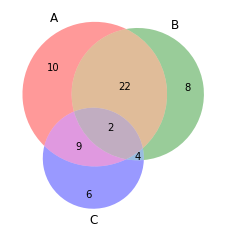
Venn diagrams are used to see the relationships between two or three sets of elements. Highlight the similarities and differences
from matplotlib_venn import venn3
#Making friend chart
friend3(subsets = (10, 8, 22, 6,9,4,2))
plt.show()
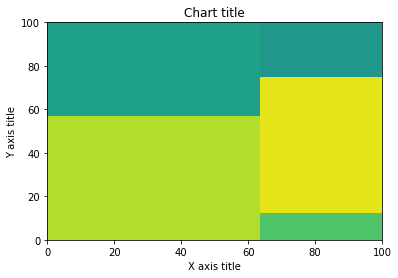
Tree map
Treemaps are mainly used to display data grouped and nested in a hierarchical structure and to observe the contribution of each component.
import squarify
sizes = [40, 30, 5, 25, 10]
squarify.plot(sizes)
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
# Show the plot
plt.show()
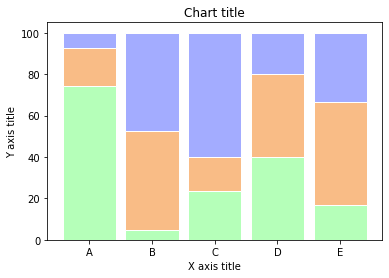
Bar graphic 100% stacked
You can take advantage of a stacked bar chart by 100% when we want to show the relative differences within each group for the different subgroups available.
#Reading the dataset
r = [0,1,2,3,4]
raw_data = {'greenBars': [20, 1.5, 7, 10, 5], 'orangeBars': [5, 15, 5, 10, 15],'blueBars': [2, 15, 18, 5, 10]}
df = pd.DataFrame(raw_data)
# From raw value to percentage
totals = [i+j+k for i,j,k in zip(df['greenBars'], df['orangeBars'], df['blueBars'])]
greenBars = [i / j * 100 for i,j in zip(df['greenBars'], totals)]
orangeBars = [i / j * 100 for i,j in zip(df['orangeBars'], totals)]
blueBars = [i / j * 100 for i,j in zip(df['blueBars'], totals)]
# plot
barWidth = 0.85
names = ('A','B','C','D','E')
# Create green Bars
plt.bar(r, greenBars, color="#b5ffb9", edgecolor="white", width=barWidth)
# Create orange Bars
plt.bar(r, orangeBars, bottom=greenBars, color="#f9bc86", edgecolor="white", width=barWidth)
# Create blue Bars
plt.bar(r, blueBars, bottom=[i+j for i,j in zip(greenBars, orangeBars)], color="#a3acff", edgecolor="white", width=barWidth)
# Custom x axis
plt.xticks(r, names)
plt.xlabel("group")
#Adding the aesthetics
plt.title('Chart title')
plt.xlabel('X axis title')
plt.ylabel('Y axis title')
plt.show()
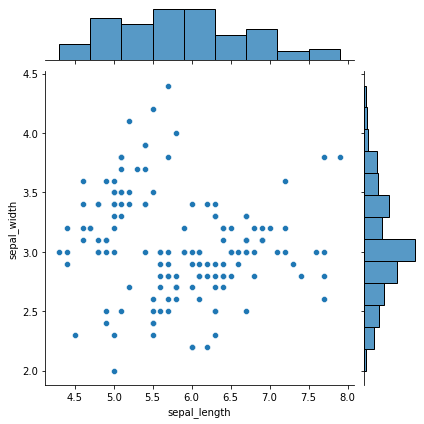
Marginal plots
Marginal plots are used to evaluate the relationship between two variables and examine their distributions. Such scatter plots that have histograms, box plotsBox Diagrams, Also known as box and whisker diagrams, are statistical tools that represent the distribution of a dataset. These diagrams show the median, quartiles and outliers, allowing data variability and symmetry to be visualized. They are useful in comparison between different groups and in exploratory analysis, making it easier to identify trends and patterns in the data.... o diagramas de puntos en los márgenes de los ejes xey respectivos
#Reading the dataset
iris_dataframe = sns.load_dataset('iris')
#Creating marginal graphs
sns.jointplot(x=iris_dataframe["sepal_length"], y = iris_dataframe["sepal_width"], kind='scatter')
# Show the plot
plt.show()
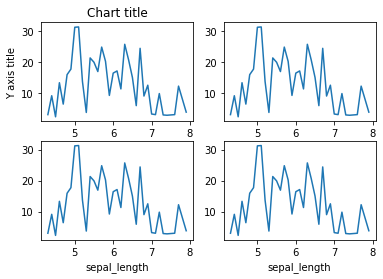
Subparcelas
Subframes are powerful displays that facilitate comparisons between frames
#Creating the dataset
df = sns.load_dataset("iris")
df=df.groupby('sepal_length')['sepal_width'].sum().to_frame().reset_index()
#Creating the subplot
fig, axes = plt.subplots(nrows = 2, ncols = 2)
ax=df.plot('sepal_length', 'sepal_width',ax=axes[0,0])
ax.get_legend().remove()
#Adding the aesthetics
ax.set_title('Chart title')
ax.set_xlabel('X axis title')
ax.set_ylabel('Y axis title')
ax=df.plot('sepal_length', 'sepal_width',ax=axes[0,1])
ax.get_legend().remove()
ax=df.plot('sepal_length', 'sepal_width',ax=axes[1,0])
ax.get_legend().remove()
ax=df.plot('sepal_length', 'sepal_width',ax=axes[1,1])
ax.get_legend().remove()
#Show the plot
plt.show()
In conclusion, there are a variety of different libraries that can be leveraged to their full potential by understanding the use case and requirement. Syntax and semantics vary from package to package and understanding the challenges and benefits of different libraries is essential. Happy viewing!
Científico de datos y entusiasta de la analyticsAnalytics refers to the process of collecting, Measure and analyze data to gain valuable insights that facilitate decision-making. In various fields, like business, Health and sport, Analytics Can Identify Patterns and Trends, Optimize processes and improve results. The use of advanced tools and statistical techniques is essential to transform data into applicable and strategic knowledge....
The media shown in this article is not the property of Analytics Vidhya and is used at the author's discretion.





