
Overview
- How do you divide a decision tree? What are the different split criteria when working with decision trees?
- Learn all about decision tree splitting methods here and master a popular machine learning algorithm
Introduction
Decision trees are simple to implement and equally easy to interpret. I often rely on decision trees like my machine learning algorithm, whether you're starting a new project or competing in a hackathon.
And decision trees are also an idea for newcomers to machine learning!! But the questions to ask (and know the answer) son:
- How do you divide a decision tree?
- What are the different split criteria?
- What is the difference between Gini and Information Gain?
If you are not sure even one of these questions, You have come to the right place! Decision Tree is a powerful machine learning algorithm that also serves as the foundation for other complex and widely used machine learning algorithms such as Random forest, XGBoost, Y LightGBM. You can imagine why it is important to learn about this topic!!
Today's programming libraries have made it easy to use any machine learning algorithm, but this comes at the cost of a hidden implementation, which is imperative to fully understand an algorithm. Another reason for this endless struggle is the availability of multiple ways to split the decision tree nodes, which increases the confusion.
Have you ever come across this fight? Couldn't find a solution? In this article, i will explain 4 Simple methods to split a nodeNodo is a digital platform that facilitates the connection between professionals and companies in search of talent. Through an intuitive system, allows users to create profiles, share experiences and access job opportunities. Its focus on collaboration and networking makes Nodo a valuable tool for those who want to expand their professional network and find projects that align with their skills and goals.... in a decision tree.
I assume familiarity with the basics of regression and decision trees. Here are two popular free courses to quickly learn or brush up on key concepts:
Basic Decision Tree Terminologies
Let's quickly review the key terminologies related to decision trees that I will use throughout the article..
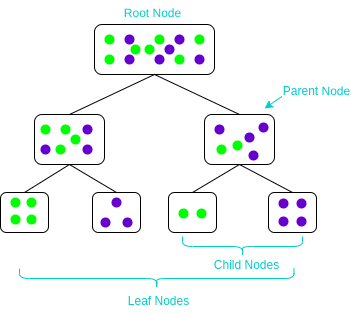
- Parent-child node: A node that is divided into subnodes is known as a main node, and these subnodes are known as child nodes. Since a node can be divided into several subnodes, one node can act as the parent node of many child nodes
- Root node: The highest node in a decision tree. It has no parent node. Represents the entire population or sample
- Leaf nodes / terminal: Nodes that do not have any child nodes are known as terminal nodes / leaf
What is node splitting in a decision tree and why is it done??
Before learning any topic, I think it is essential to understand why you are learning it. That helps to understand the goal of learning a concept. Then, Let's understand why learn about the division of nodes in decision trees.
Since everyone knows how widely decision trees are used, there's no denying the fact that learning about decision trees is a must. A decision tree makes decisions by dividing nodes into subnodes. This process is done several times during the training process until only homogeneous nodes remain.. And it's the only reason a decision tree can work so well. Therefore, node splitting is a key concept everyone should know.
The division of nodes, or just the division, is the process of dividing a node into multiple subnodes to create relatively pure nodes. There are several ways to do this, which can be divided into two categories based on the type of target variable:
- Continuous target variable
- Categorical objective variable
- Gini impurity
- Information gain
- Chi squared
In the next sections, we will see each division method in detail. Let's start with the first division method: variance reduction.
Decision tree division method n. ° 1: variance reduction
Variance reduction is a method of dividing the node that is used when the target variable is continuous, namely, regression problems. It is so called because it uses the variance as a measure to decide the characteristic at which node is divided into child nodes.
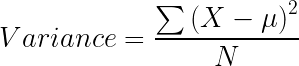
The variance is used to calculate the homogeneity of a node. If a node is completely homogeneous, then the variance is zero.
Here are the steps to split a decision tree by reducing the variance:
- For each division, individually calculate the variance of each child node
- Calculate the variance of each division as the weighted average variance of the child nodes
- Select the division with the lowest variance
- Perform the steps in 1 al 3 until completely homogeneous nodes are achieved.
The following video excellently explains the reduction in variance using an example:
Decision tree division method n. ° 2: information gain
Now, What if we have a variableIn statistics and mathematics, a "variable" is a symbol that represents a value that can change or vary. There are different types of variables, and qualitative, that describe non-numerical characteristics, and quantitative, representing numerical quantities. Variables are fundamental in experiments and studies, since they allow the analysis of relationships and patterns between different elements, facilitating the understanding of complex phenomena.... Categorical objective? Reducing the variance will not be enough.
Good, the answer is information gain. The information gain is used to divide the nodes when the target variable is categorical. It works on the concept of entropy and is given by:
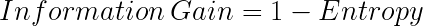
Entropy is used to calculate the purity of a node. The smaller the entropy value, the greater the purity of the node. The entropy of a homogeneous node is zero. How we subtract the entropy of 1, the information gain is greater for the purest nodes with a maximum value of 1. Now, Let's take a look at the formula for calculating entropy:
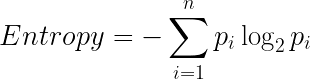
Steps to divide a decision tree using information gain:
- For each division, individually calculate the entropy of each child node
- Calculate the entropy of each division as the weighted average entropy of the secondary nodes
- Select the division with the lowest entropy or the highest information gain
- Until you achieve homogeneous nodes, repeat the steps 1-3
Here's a video on how to use information gain to split a decision tree:
Decision tree division method # 3: Gini impurity
Gini Impurity is a method to divide nodes when the target variable is categorical. It is the most popular and simple way to divide a decision tree. The value of the Gini impurity is:
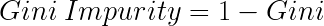
Waiting, What is gini?
Gini is the probability of correctly labeling a randomly chosen item if it was randomly labeled according to the label distribution at the node. Gini's formula is:
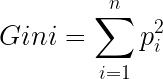
And Gini Impurity is:
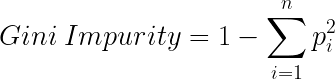
The lower the Gini impurity, the greater the homogeneity of the node. The Gini impurity of a pure node is zero. Now, you might be thinking we already know about information gain, then, Why do we need Gini Impurity?
Gini impurity is preferred to information gain because it does not contain logarithms that are computationally intensive.
Here are the steps to split a decision tree using Gini Impurity:
- Similar to what we did in obtaining information. For each division, individually calculate the Gini impurity of each child node
- CCalculate the Gini Impurity of each division as the weighted average Gini Impurity of the child nodes.
- Select the division with the lowest Gini Impurity value
- Until you achieve homogeneous nodes, repeat the steps 1-3
And here is Gini Impurity in video form:
Decision tree division method # 4: Chi squared
Chi-square is another method of dividing nodes in a decision tree for data sets that have categorical target values.. Can do two or more than two divisions. Works on the statistical significance of the differences between the parent node and the secondary nodes.
The chi-square value is:
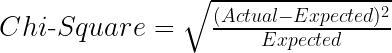
Here the Expected is the expected value for a class on a child node based on the distribution of classes on the parent node, Y Real is the real value of a class in a child node.
The above formula gives us the Chi-Square value for a class. Take the sum of the Chi-Square values for all classes in a node to calculate the Chi-Square for that node. The higher the value, the greater the differences between the parent and child nodes, namely, the greater the homogeneity.
These are the steps to divide a decision tree using Chi-Square:
- For each division, Individually calculate the Chi-Square value of each child node by taking the sum of the Chi-Square values for each class in a node.
- Calculate the Chi-Square value of each division as the sum of the Chi-Square values for all child nodes
- Select the division with the highest chi-square value
- Until you achieve homogeneous nodes, repeat the steps 1-3
Of course, there is a video explaining Chi-Cuadrado in the context of a decision tree:
Final notes
Now, know the different methods of dividing a decision tree. In the next steps, you can see our complete playlist on decision trees on youtube. Or you can take our for free decision trees course here.
I've also put together a list of great articles on decision trees below.:
If you found this article informative, Share it with your friends and comment below with your queries or thoughts.





