
Introduction
is an important component, as well as one of the most underrated steps in any data science project. EDA is essential for well-defined and structured data analysis and should be done prior to the machine learning modeling phase.
It involves finding ideas from the data after careful observation and further summarizing its main characteristics.. Generally, the real-life data we work with contains a lot “noise” Y, Thus, performing data analysis manually on such data sets becomes a complicated and tedious process.
Introductory Python tutorial: scientific calculation with pandas | by data analytics enthusiast | Half
Piton is one of the most widely used languages for Data science particularly due to the presence of various libraries and packages that facilitate data analysis.
Respectively, Pandas is one of the most popular Python libraries that helps present data in a way suitable for analysis through its Serie Y Data frame Data structures. Provides various functions and methods to simplify and speed up the data analysis process.
Here we use the data set "TITANIC" to carry out the practical implementation of all the functions.
First, we import the Numpy and pandas library and then read the dataset.

Now let's get started
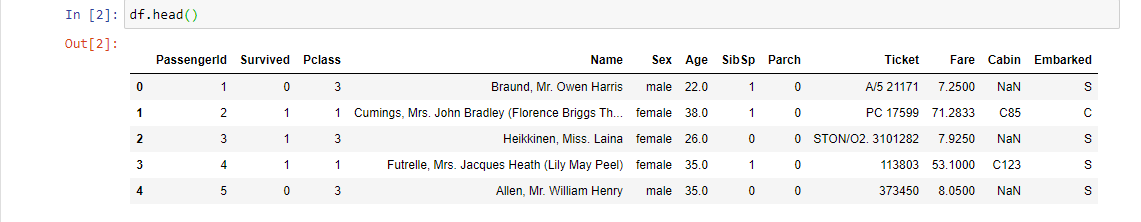
1. df.head (): By default, returns the first 5 data frame rows. To change the default value, you can insert a value in parentheses to change the number of rows returned.
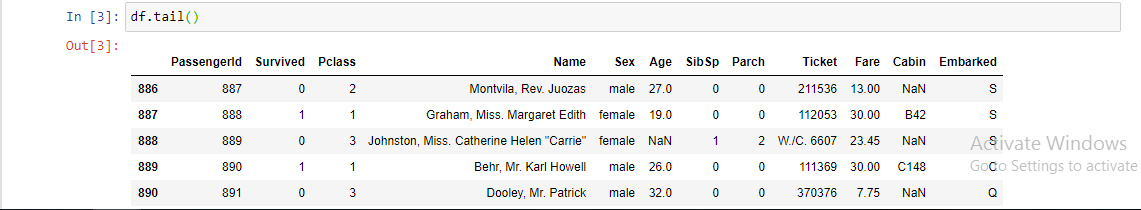
2. df.tail (): By default, returns the last 5 data frame rows. This function is used to get the last n rows. This function returns the last n rows of the object based on position.
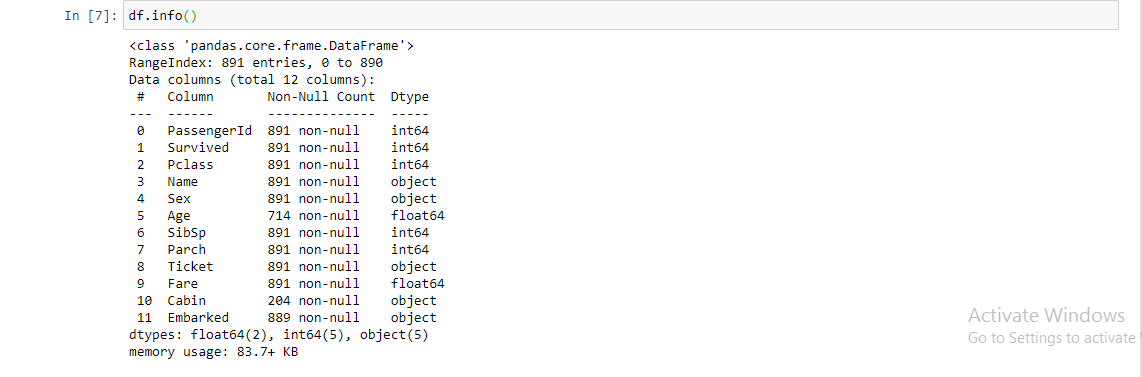
3. df.info (): Helps to get a quick overview of the dataset. This function is used to get a short summary of the data frame. This method prints information about a DataFrame, incluido el tipo de indexThe "Index" It is a fundamental tool in books and documents, which allows you to quickly locate the desired information. Generally, it is presented at the beginning of a work and organizes the contents in a hierarchical manner, including chapters and sections. Its correct preparation facilitates navigation and improves the understanding of the material, making it an essential resource for both students and professionals in various areas.... y los tipos de columna, non-null values and memory usage.
4. df. Shape: Muestra el número de dimensiones así como el tamaño en cada dimension"Dimension" It is a term that is used in various disciplines, such as physics, Mathematics and philosophy. It refers to the extent to which an object or phenomenon can be analyzed or described. In physics, for instance, there is talk of spatial and temporal dimensions, while in mathematics it can refer to the number of coordinates necessary to represent a space. Understanding it is fundamental to the study and.... Since the data frames are two-dimensional, the form it returns is the number of rows and columns.

5. df. size: Returns an int that represents the number of elements in this object. Returns the number of rows if it is Series; otherwise, returns the number of rows multiplied by the number of columns if it is DataFrame.

6. df.ndim: Returns the dimension of the frame / data series. 1 for one dimension (serie), 2 for two dimensions (data frame).

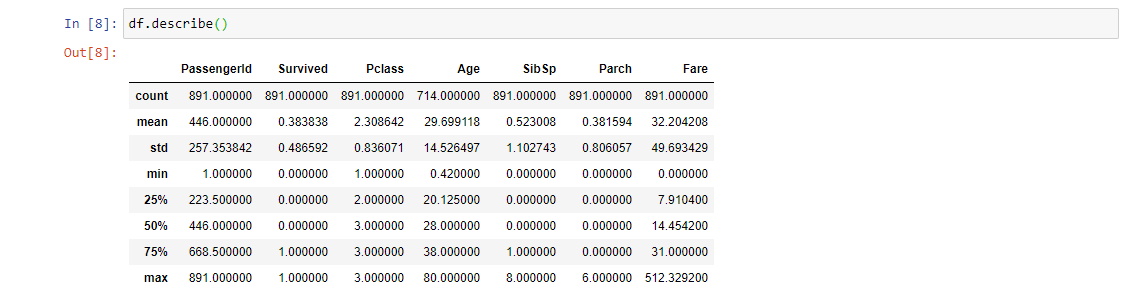
7. df.describe (): Returns a statistical summary of the numeric columns present in the data set. This method calculates some statistical measures such as the percentile, the mean and standard deviation of the numeric values of the Series or DataFrame.
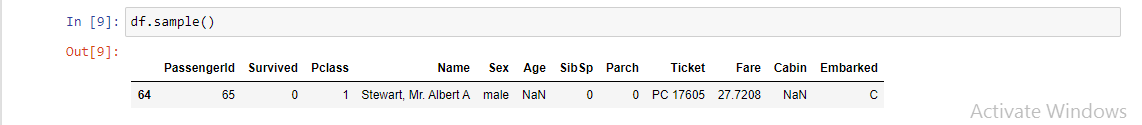
8. df.sample (): Used to randomly sample in a row or in a column. Allows you to randomly select values from a series or DataFrame. It is useful when we want to select a random sample from a distribution.
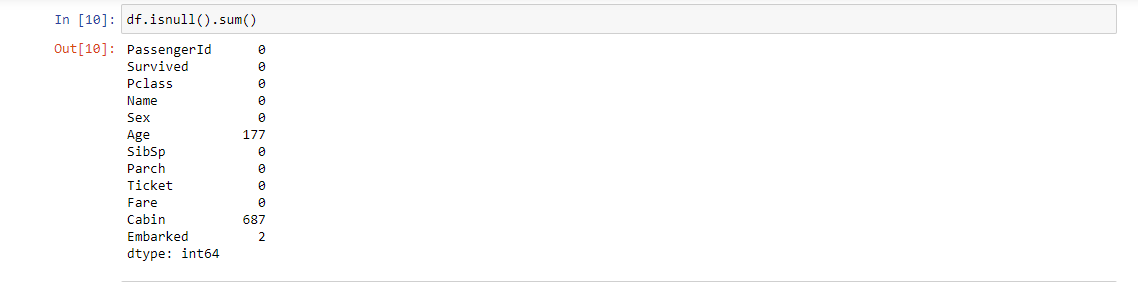
9. df.isnull () .sum (): Returns the number of missing values in each column.
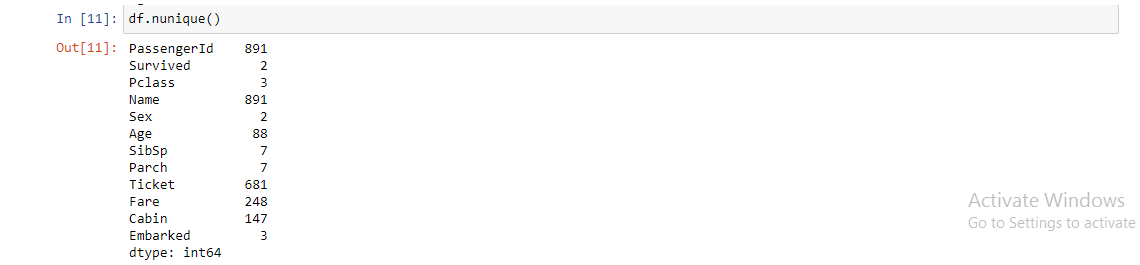
10. df.nunique (): Returns the number of unique elements in the object. Counts the number of unique entries in columns or rows. It is very useful in categorical characteristics, especially in cases where we do not know the number of categories in advance.
11. df.index: This function looks for a given element from the beginning of the list and returns the lowest index where the element appears.

12. df columns .: Returns the column labels of the data frame.

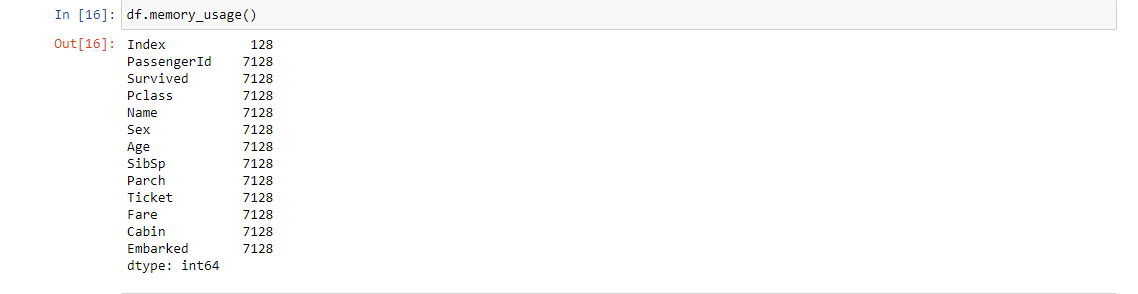
13. df.memory_usage (): Returns how much memory each column uses in bytes. It is useful especially when working with large data frames.
14. df.dropna (): This function is used to remove a row or column from a data frame that has a missing NaN or values.

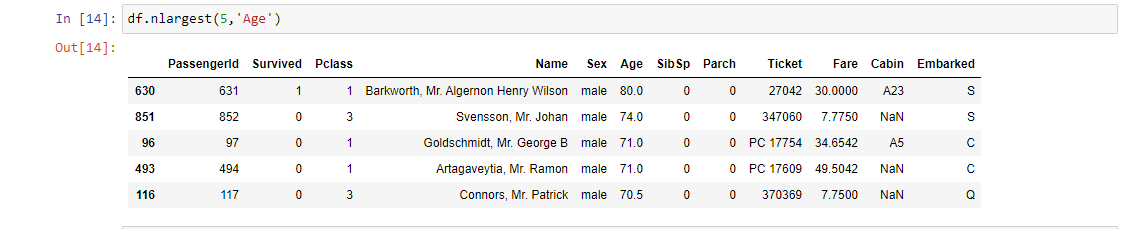
15. df.nlargest (): Returns the first North rows ordered by columns in descending order.
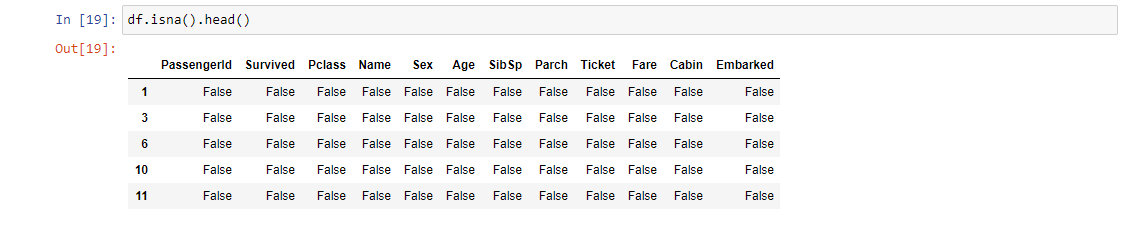
16. df.isna (): This function returns a data frame filled with boolean values with true indicating missing values.
17. df.duplicated (): Returns a Boolean string denoting duplicate rows.

18. value_counts (): This function is used to obtain a series containing counts of unique values. The resulting object will be in descending order so that the first element is the element that occurs most frequently. Exclude missing values by default. Esta función es útil cuando queremos verificar el problema del desequilibrio de clases para una variableIn statistics and mathematics, a "variable" is a symbol that represents a value that can change or vary. There are different types of variables, and qualitative, that describe non-numerical characteristics, and quantitative, representing numerical quantities. Variables are fundamental in experiments and studies, since they allow the analysis of relationships and patterns between different elements, facilitating the understanding of complex phenomena.... Categorical.

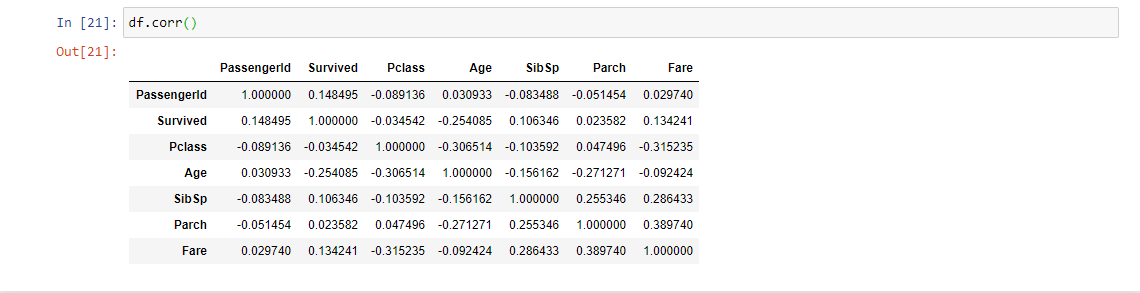
19. df.corr (): This function is used to find the pairwise correlation of all columns in the data frame. Missing values are automatically excluded. For any column of non-numeric data type in data frame, it is ignored. This function is useful while making feature selection by looking at the correlation between the features and the target variable or between the variables.
20. types of df.d: This function shows the data type of each column.
Final notes
Thank you for reading!
If you liked this and want to know more, visit my other articles on data science and machine learning by clicking the link
Feel free to contact me at Linkedin, Email.
Anything not mentioned or do you want to share your thoughts? Feel free to comment below and I'll get back to you.
Until then, stay home, stay safe to prevent the spread of COVID-19, And keep learning!
About the Author
Chirag Goyal
Nowadays, I am pursuing my Bachelor of Technology (B.Tech) in Computer Science and Engineering from Indian Institute of Technology Jodhpur (IITJ). I am very excited about machine learning, the deep learningDeep learning, A subdiscipline of artificial intelligence, relies on artificial neural networks to analyze and process large volumes of data. This technique allows machines to learn patterns and perform complex tasks, such as speech recognition and computer vision. Its ability to continuously improve as more data is provided to it makes it a key tool in various industries, from health... and artificial intelligence.
The media shown in this article is not the property of DataPeaker and is used at the author's discretion.





