
This article was published as part of the Data Science Blogathon
Introduction:
As we all know, Artificial Intelligence is being widely used around us: from reading the news on your mobile device or analyzing that complex data at your workplace, AI has improved speed, precision and effectiveness of human effort. Advances in AI have helped us achieve things we previously thought were not possible. Even having a pizza from your favorite restaurant at home is just a click away, thanks to AI.
In a nutshell, artificial intelligence means a computer or computer program that mimics human intelligence. It is achieved by learning how you think, learn, decides and works the human brain while solving a problem. The results of this study are then used as the basis for developing intelligent systems and software..
There is 4 types of learning:
● Supervised learningSupervised learning is a machine learning approach where a model is trained using a set of labeled data. Each input in the dataset is associated with a known output, allowing the model to learn to predict outcomes for new inputs. This method is widely used in applications such as image classification, speech recognition and trend prediction, highlighting its importance in....
● Unsupervised learning.
● Semi-supervised learning.
● Reinforced learning.
| Supervised | Unsupervised | Semi-supervised | Reinforced |
| Supervised learning is when the model is trained on a labeled data set. | The Unsupervised learningUnsupervised learning is a machine learning technique that allows models to identify patterns and structures in data without predefined labels. Through algorithms such as k-means and principal component analysis, This approach is used in a variety of applications, such as customer segmentation, anomaly detection and data compression. Its ability to reveal hidden information makes it a valuable tool in the... is when the model is trained on an unlabeled dataset, it is up to the algorithm to find underlying patterns in the data. | It falls between supervised and unsupervised learning, in this, some learning data is labeled and some is not. | The algorithm evaluates its performance based on feedback responses and reacts accordingly. |
This blog covers supervised and unsupervised AI learning, using Python and Iris dataset.
Table of Contents:
- Introduction
- Iris data set
- Supervised learning
- Decision tree
- Logistic regression
- Unsupervised learning
- Grouping of K-stockings
- Conclusion and references
Iris data set:
The data set contains 3 classes with 50 instances each and 150 total instances, where each class refers to a type of iris plant.
Class: Silky Iris, Iris Versicolor, Iris Virginica
The data format: (sepal length, sepal width, petal length, petal width)
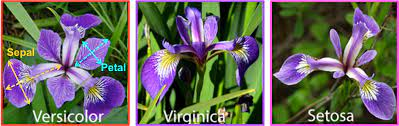
We will train our models based on these parametersThe "parameters" are variables or criteria that are used to define, measure or evaluate a phenomenon or system. In various fields such as statistics, Computer Science and Scientific Research, Parameters are critical to establishing norms and standards that guide data analysis and interpretation. Their proper selection and handling are crucial to obtain accurate and relevant results in any study or project.... and we will use them to predict the kinds of flowers.
Understanding the data:
Download the Iris dataset from https://www.kaggle.com/uciml/iris
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
iris =   pd.read_csv("Iris.csv") #Iris.csv is now a pandas dataframe
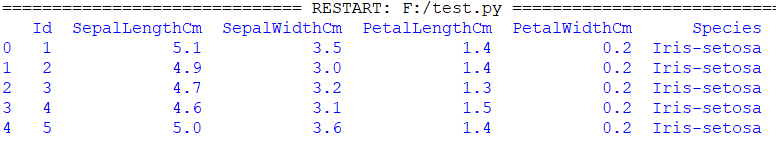
print(iris.head()) #prints first 5 values
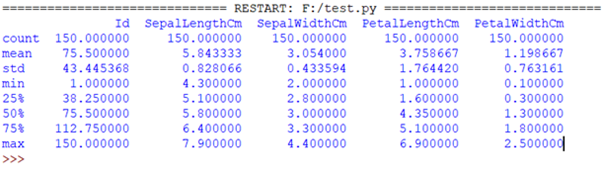
print(iris.describe()) #prints some basic statistical details like percentile,mean, std etc. of the data frame |
Visualizing the data using matplotlib:
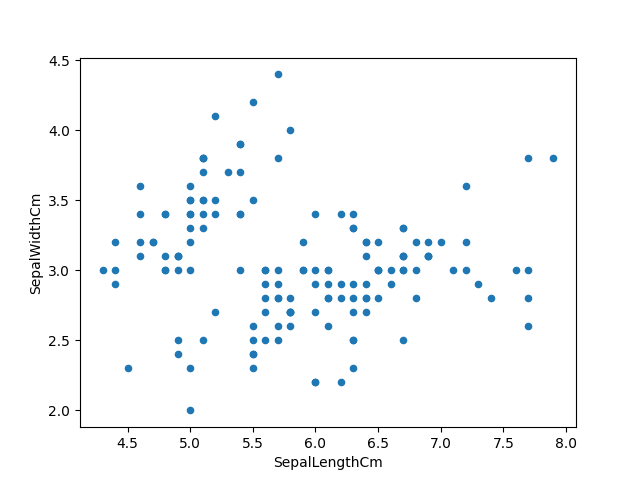
iris.plot(kind="scatter", x="SepalLengthCm", y ="SepalWidthCm") plt.show() |
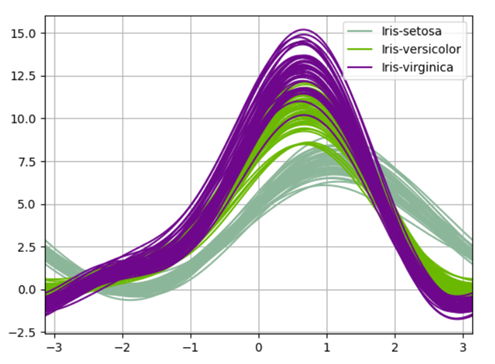
Data visualization using andrew's curves from pandas:
Andrews curves have the functional form:
f
x_4 without (2t) + x_5 cos (2t) +…
Where the coefficients x correspond to the values of each dimension"Dimension" It is a term that is used in various disciplines, such as physics, Mathematics and philosophy. It refers to the extent to which an object or phenomenon can be analyzed or described. In physics, for instance, there is talk of spatial and temporal dimensions, while in mathematics it can refer to the number of coordinates necessary to represent a space. Understanding it is fundamental to the study and... y t is linearly spaced between -pi and + pi. Each row of the frame corresponds to a single curve.
from pandas.plotting import andrews_curves
andrews_curves(iris.drop("Id", axis=1), "Species")
plt.show()
|
Dataset pre-processing:
Using a built-in library called 'train_test_split', which divides our data set into a proportion of 80:20. The 80% will be used to trainingTraining is a systematic process designed to improve skills, physical knowledge or abilities. It is applied in various areas, like sport, Education and professional development. An effective training program includes goal planning, regular practice and evaluation of progress. Adaptation to individual needs and motivation are key factors in achieving successful and sustainable results in any discipline...., evaluation and selection between our models and the 20% will be retained as a validation dataset.
from sklearn.model_selection import train_test_split x = iris.iloc[:, :-1].values #last column values excluded y = iris.iloc[:, -1].values #last column value from sklearn.model_selection import train_test_split x_train,x_test,y_train,y_test = train_test_split(x,Y,test_size=0.2,random_state=0) #Splitting the dataset into the Training set and Test set |
Supervised learning :
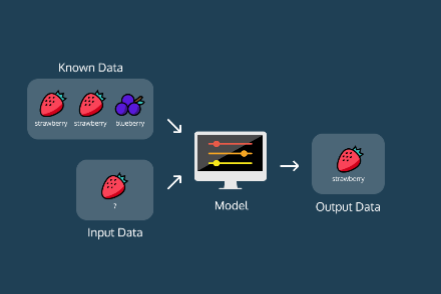
Supervised machine learning algorithms are trained to find patterns using a data set. The process is simple, takes what has been learned in the past and then applies it to new data. Supervised learning uses labeled examples to predict future patterns and events.
For instance, when we teach a child that 2 + 2 = 4 or we point to the image of any animal so that you know its name.
Supervised learning is in turn divided into:
● Classification: Classification predicts categorical class labels, that are discreet and messy. It is a two step process, consisting of a learning step and a classification step. There are various classification algorithms like: “Decision tree classifier”, “Random forest”, “Naive Bayes classifier”, etc.
● Regression: Regression is generally described as determining a relationship between two or more variables, how to predict a person's work based on input data X. Some of the regression algorithms are: “Logistic regression”, “Loop regression”, “Ridge regression”, etc. .
Decision tree classifier:
The general reason for using a decision tree is to create a training model that can be used to predict the class or value of the target variables by learning decision rules inferred from previous data. (training data).
Try to solve the problem using tree representation. Every nodeNodo is a digital platform that facilitates the connection between professionals and companies in search of talent. Through an intuitive system, allows users to create profiles, share experiences and access job opportunities. Its focus on collaboration and networking makes Nodo a valuable tool for those who want to expand their professional network and find projects that align with their skills and goals.... The tree's inner node corresponds to an attribute, and each leaf node corresponds to a class label.
Using the decision tree in the Iris dataset:
from sklearn.tree import   DecisionTreeClassifier
from sklearn.metrics import accuracy_score
classifier = DecisionTreeClassifier() classifier.fit(x_train, y_train) #training the classifier y_pred = classifier.predict(x_test) #making precdictions print(classification_report(y_test, y_pred)) #Summary of the predictions made by the classifier print(confusion_matrix(y_test, y_pred)) #to evaluate the quality of the output print('accuracy is',accuracy_score(y_pred,y_test)) #Accuracy score
|
Precision: accuracy of positive predictions.
Recovery: fraction of positives that were correctly identified.
F1 score: What percentage of positive predictions were correct?
macro avg – averaging the unweighted mean per label
weighted average: averaging the weighted average of support per label
Heat mapa "heat map" is a graphical representation that uses colors to show the density of data in a specific area. Commonly used in data analytics, Marketing and behavioral studies, This type of visualization allows you to identify patterns and trends quickly. Through chromatic variations, Heat maps make it easier to interpret large volumes of information, helping to make informed decisions.... for the confusion matrix:
import seaborn as sns cm = confusion_matrix(y_test, y_pred) #Transform to df cm_df = pd.DataFrame(cm,index = ['setosa','versicolor','virginica'], columns = ['setosa','versicolor','virginica']) plt.figure(figsize=(5.5,4)) sns.heatmap(cm_df, annot=True) plt.ylabel('True label')
plt.xlabel('Predicted label')
plt.show() |
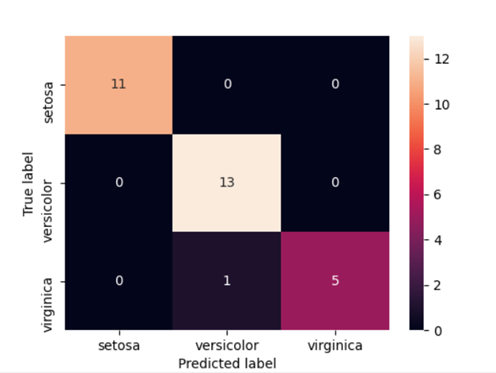
One idea we can get from the matrix is that the model was very accurate when classifying Setosa and Virginica (True positive / All = 1.0). But nevertheless, Versicolor's accuracy was lower (13/14 = 0,928).
Unsupervised learning:
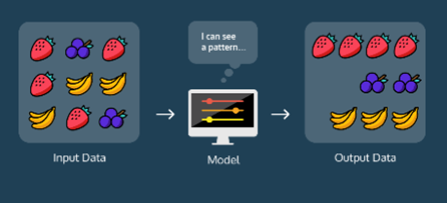
Unsupervised learning is used against data without historical labels. The system is not subject to a predetermined set of outputs, correlations between inputs and outputs or a “correct answer”. The algorithm must figure out what it is seeing for itself, since it doesn't have any waypoint storage. The goal is to explore the data and find some kind of patterns or structures.
Unsupervised learning can be classified into:
● Grouping: Clustering is the task of dividing the population or data points into multiple groups, so that the data points of one group are homogeneous with each other than those of different groups. There are numerous grouping algorithms, some of them are: “K-means clustering algorithms”, “medium change”, “hierarchical grouping”, etc.
● Association: An association rule is an unsupervised learning method used to find the relationships between variables in a large databaseA database is an organized set of information that allows you to store, Manage and retrieve data efficiently. Used in various applications, from enterprise systems to online platforms, Databases can be relational or non-relational. Proper design is critical to optimizing performance and ensuring information integrity, thus facilitating informed decision-making in different contexts..... Determine the set of elements that occur together in the data set.
Grouping of K-stockings:
The goal of the K-means clustering algorithm is to find clusters in the data, with the number of groups represented by the variableIn statistics and mathematics, a "variable" is a symbol that represents a value that can change or vary. There are different types of variables, and qualitative, that describe non-numerical characteristics, and quantitative, representing numerical quantities. Variables are fundamental in experiments and studies, since they allow the analysis of relationships and patterns between different elements, facilitating the understanding of complex phenomena.... K. The algorithm works iteratively to assign each data point to one of the K groups based on the characteristics that are provided.. .
The results of running a K-means on a data set are:
● Centroides K: centroids for each of the K groups identified in the data set.
● Labels for training data: full data set labeled to ensure that each data point is mapped to one of the clusters.
Using K-means clustering on the Iris dataset:
from sklearn.datasets import load_iris
from sklearn.cluster import KMeans
iris_data=load_iris() #loading iris dataset from sklearn.datasets iris_df = pd.DataFrame(iris_data.data, columns = iris_data.feature_names) #creating dataframe kmeans = KMeans(n_clusters=3,init="k-means++", max_iter = 100, n_init = 10, random_state = 0) #Applying Kmeans classifier y_kmeans = kmeans.fit_predict(x) print(kmeans.cluster_centers_) #display cluster centers plt.scatter(x[y_kmeans == 0, 0], x[y_kmeans == 0, 1],s = 100, c="red", label="Iris-silky") plt.scatter(x[y_kmeans == 1, 0], x[y_kmeans == 1, 1],s = 100, c="blue", label="Iris versicolor") plt.scatter(x[y_kmeans == 2, 0], x[y_kmeans == 2, 1],s = 100, c="green", label="Iris-virginica") #Visualising the clusters - On the first two columns plt.scatter(kmeans.cluster_centers_[:, 0], kmeans.cluster_centers_[:,1],s = 100, c="black", label="Centroids") #plotting the centroids of the clusters plt.legend() plt.show() |
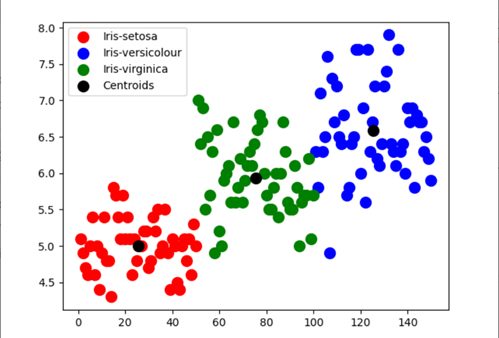
An idea that we can get from the Dispersion diagramThe scatter plot is a graphical tool used in statistics to visualize the relationship between two variables. It consists of a set of points in a Cartesian plane, where each point represents a pair of values corresponding to the variables analyzed. This type of chart allows you to identify patterns, Trends and possible correlations, facilitating data interpretation and decision-making based on the visual information presented.... is that the accuracy of the model to determine Setosa and Virginica is comparatively more to Versicolour.
Conclution:
We have explored and pre-processed the Iris dataset using sklearn. data set, as well as use the Iris.csv file. What's more, I learned about supervised and unsupervised learning and implemented the decision tree algorithm and the groupingThe "grouping" It is a concept that refers to the organization of elements or individuals into groups with common characteristics or objectives. This process is used in various disciplines, including psychology, Education and biology, to facilitate the analysis and understanding of behaviors or phenomena. In the educational field, for instance, Grouping can improve interaction and learning among students by encouraging work.. by K-means.
References:
https://www.kaggle.com/sixteenpython/machine-learning-with-iris-dataset
https://scikit-learn.org/stable/
https://certes.co.uk/types-of-artificial-intelligence-a-detailed-guide/
About the Author:
Hello reader, i'm yashi saxena, and I currently work at TCS as a systems engineer. TO THE, ML and NLP have always been my interest, so here I am making an effort to learn more about this field. You can connect with me on Linkedin: https://www.linkedin.com/in/yashi-saxena-7a9522194/
The media shown in this article is not the property of DataPeaker and is used at the author's discretion.





