
before continuing, let's briefly analyze Scraped off and later AutoScraper:
What is scraping?
Web scraping is a fundamental technique used to extract useful information such as contacts, emails, images, URL, etc ... of the websites. The other form of web scraping is crawling. Used when we need a large amount of structured and labeled data for industrial fundamentals. Web scraping software can directly access the world wide web using HTML protocols.
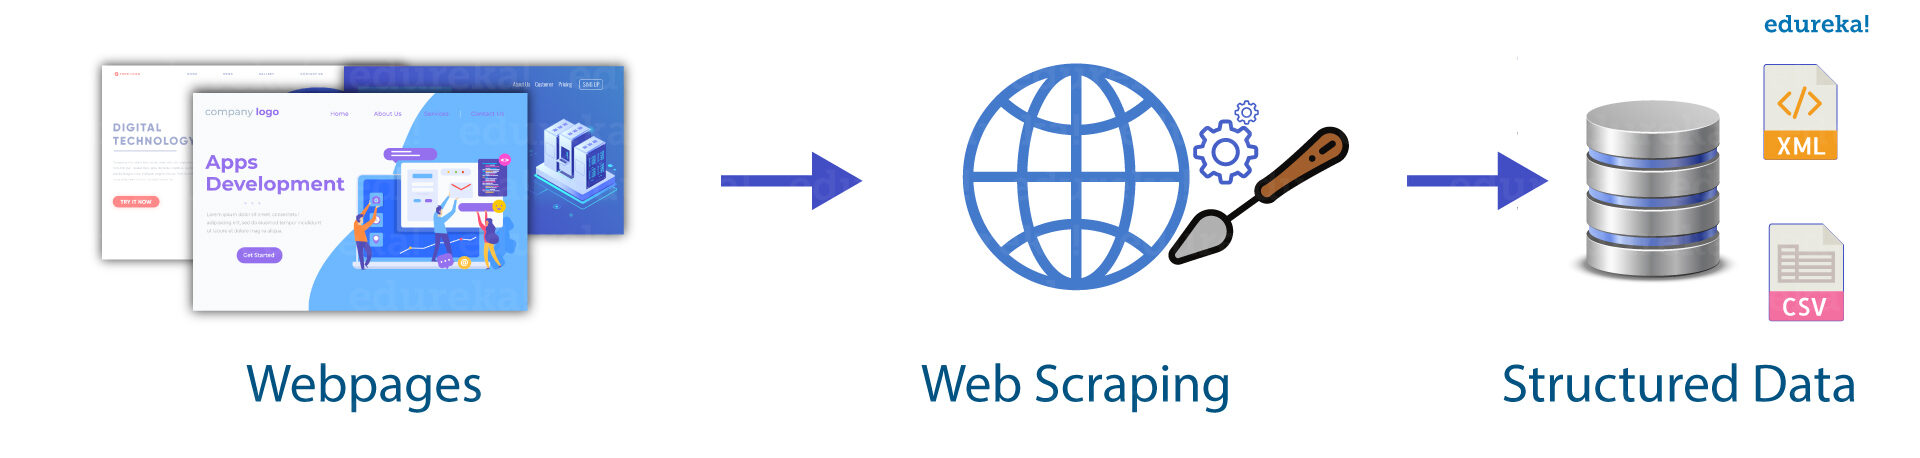
You know that new forms of web scraping involve observing the data feed on web servers, for instance, un archivo JSONJSON, o JavaScript Object Notation, It is a lightweight data exchange format that is easy for humans to read and write, and easy for machines to analyze and generate. It is commonly used in web applications to send and receive information between a server and a client. Its structure is based on key-value pairs, making it versatile and widely adopted in software development.. que se utiliza como transportador entre el cliente y el servidor web.
There are many large websites that Google, Facebook, Amazon, etc. provide APIs that allow you to access your data in a structured or tagged format.
Now, we briefly analyze the AutoScraper library:
What is AutoScraper?
When we talk about scraping, there are many things on the website that we want to remove, but writable scripts take a long time to remove data and it is a very long process, to overcome this problem, a group of Python developers develop a library. which will extract all the data from a website in an easy way. Then AutoScraper is web scraping python library used to scrape data from a website in a simple way, easy and fast. It has a user-friendly environment by this scraper you can easily interact with this library.
Uses website URLs and HTML content to extract reliable information and data.
Point to consider: learn scraping rules and return similar items in good format.
It's easy to remove website content that was easy to review as a title, price, Name, ratings, etc. Wait a minute! What will we do with the images? It is a great question that arises, we can give the image during the execution of the program😅. I am finding a way to remove images from websites. Let's analyze below:
First, let's go for the installation of this library:
Install AutoScraper
There are two ways to install AutoScraper:
Using pip: –
Enter the following code at the command prompt,
pip install autoscraper
or with the git repository,
clon de git https://github.com/brandonrobertz/autoscrape-py
cd autoscrape-py /
pip install.[all]
Now we import important modules:
Module import
# Importing AutoScraper
from autoscraper import AutoScraper
Here we import the AutoScraper class from the library.
Now we feed the URL to the AutoScraper function to continue scraping:
URL: – https://www.bookswagon.com/
Here we feed the ecommerce website url to the AutoScraper class to extract or scratch the book images.
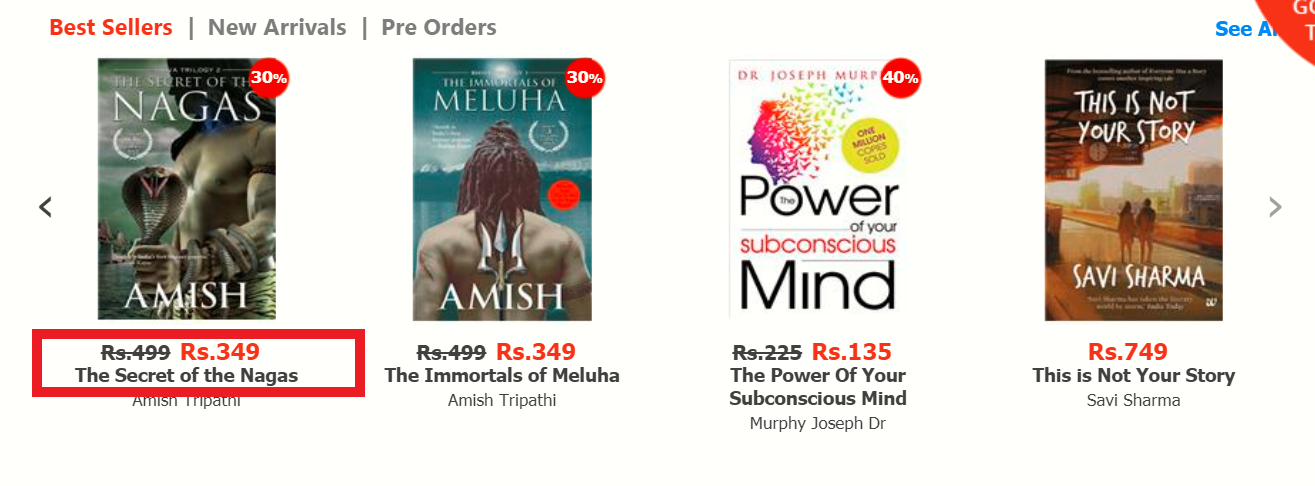
Now, before moving on, We first see the demo by scratching book titles and prices to get a basic and better understanding of the scratching code:
Scraping demo
Now, we will feed the list of items to scratch, so first we have to initialize the AutoScraper class with its object:
Wanted List:
create a list of items
# create a list of elements
items = ['Rs.349' , 'The Secret of the Nagas']
Object creation:
# create object
scrape = AutoScraper()
# feeding for scraping
final_result = scrape.build(URL,items)
# display result
print(final_result)
Time to delete the image
Now, have an idea about the web scraping code we discussed earlier, so we use this same method to scrape the images from the website with some changes. Therefore, we will discuss the method or technique to extract the images from the data. let's see next:
Paso 1:
In the first step, we have to right click the mouse and then select the inspect option from the menu list:
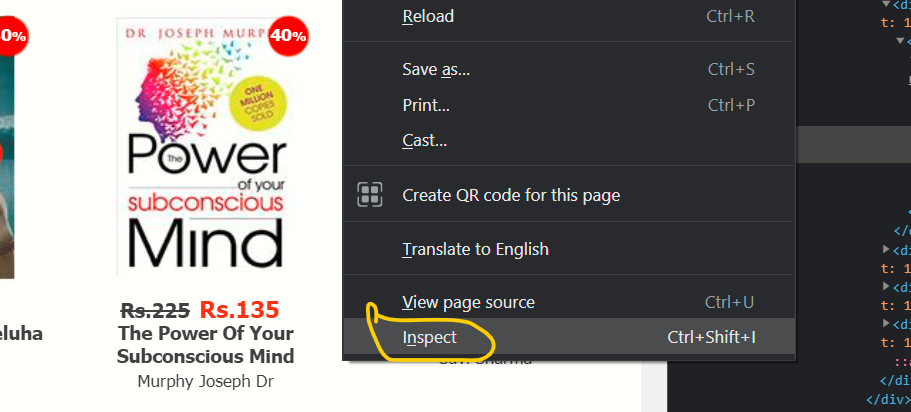
Paso 2:
After selecting the inspect option, a page of HTML content opens next to the screen, then it will hover over the book image; at that moment, notice on the HTML content page that you will find the Image url.
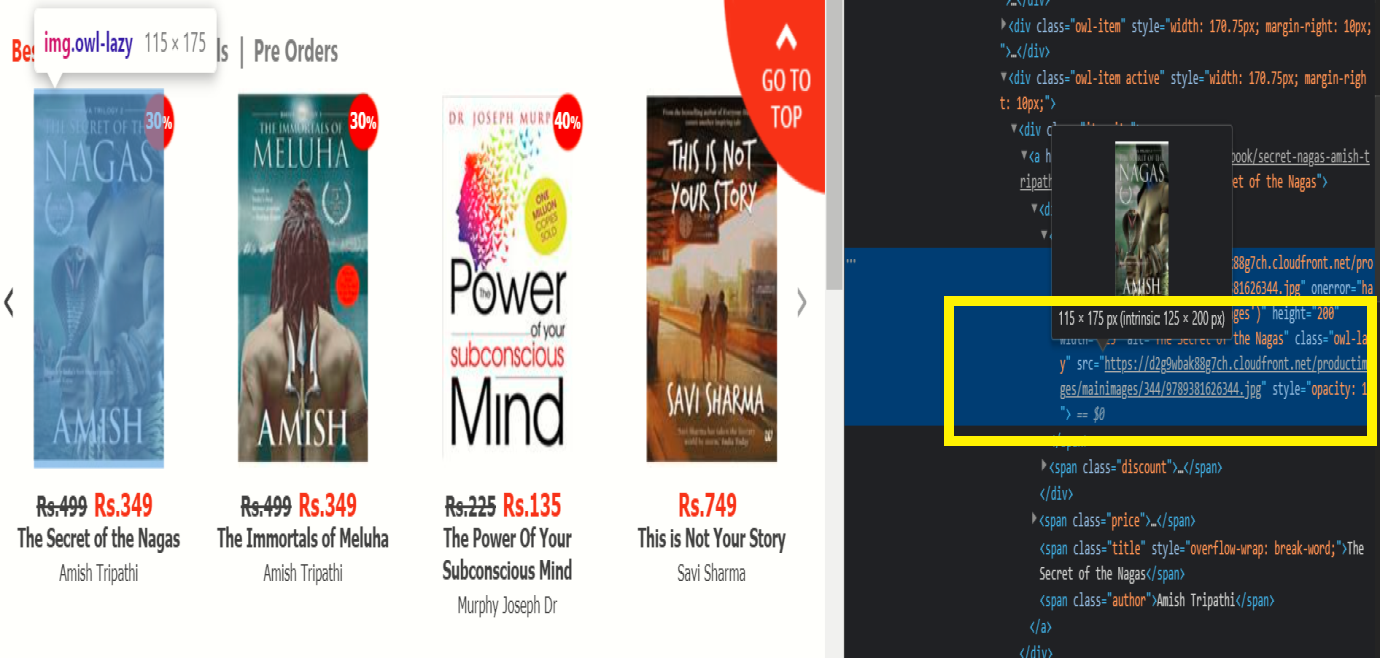
When you find the URL of the particular image, copy it and we will use it in the wish list. This is just the change that is required to scrape the images from the website.
Paso 3:
Now, we will configure that image URL along with the books that entered our wanted list,
item = ['https://d2g9wbak88g7ch.cloudfront.net/productimages/mainimages/344/9789381626344.jpg','This is Not Your Story']
After creating a list, we do the same process we did above:
# creating object
scrape = AutoScraper()
# building result
final_result = scrap.build( URL, item )
# display result
print(final_result)
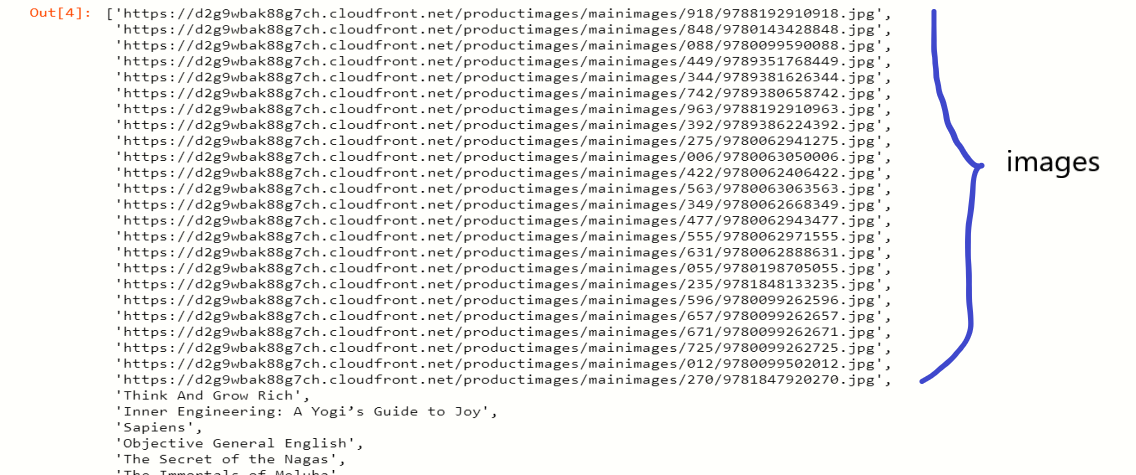
Note: use the url of the images to extract the images from the website
Then, this is the process to scrape images from any website.
Final note
Then, here we will discuss website image scraping, if you want to remove images from the website, use this technique. I am very surprised to use this AutoViz library. I hope you enjoyed this article and thank you for reading this article.
You can connect with me on Linkedin: Profile URL
Also read my other articles: https://www.analyticsvidhya.com/blog/author/mayurbadole2407/
Thank you.
The media shown in this article is not the property of DataPeaker and is used at the author's discretion.





