
Boost the algorithm in machine learning
Impulse can be called a set of algorithms whose main function is to turn weak students into strong students. They have become mainstream Data Science Industry because they have been in the machine learning community during years. The impulse was first entered by Freund and Schapire in the year 1997 with his Algoritmo AdaBoost, and since then, impulse has been a predominant technique for solving binary classification problems.
Why are boost algorithms so popular?
To know this, in simpler words. boost algorithms can outperform simpler algorithms like Random forest, decision trees or logistic regression. It is one of the main reasons for the increase in algorithm promotion by many machine learning competitors due to the fact that impulse algorithms are powerful.. Even so, can improve prediction accuracy of your model by a considerable number of factors. Many machine learning competitors use a single boost algorithm or multiple boost algorithms to solve respective problems.
Impulse algorithm explained
Impulse combine weak students to form a strong student, where a weak learner sets a classifier slightly correlated with the actual classification. Unlike a weak student, a strong learner is a classifier associated with the correct categories.
To know this, let's take on a scenario:
Suppose you build a Random forest model which gives you a precision of 75% in the validation data set and, then, decide to test some other model on the same data set. Suppose you try linear regression model and kNN on the same validation dataset, and now your model gives you an accuracy of 69% Y 92%, respectively. It is clear that the three models work in absolutely different ways and provide absolutely different results on the same data set..
Have you ever thought, instead of just using one of these models, what if we use a combination of all these models to make the final predictions?
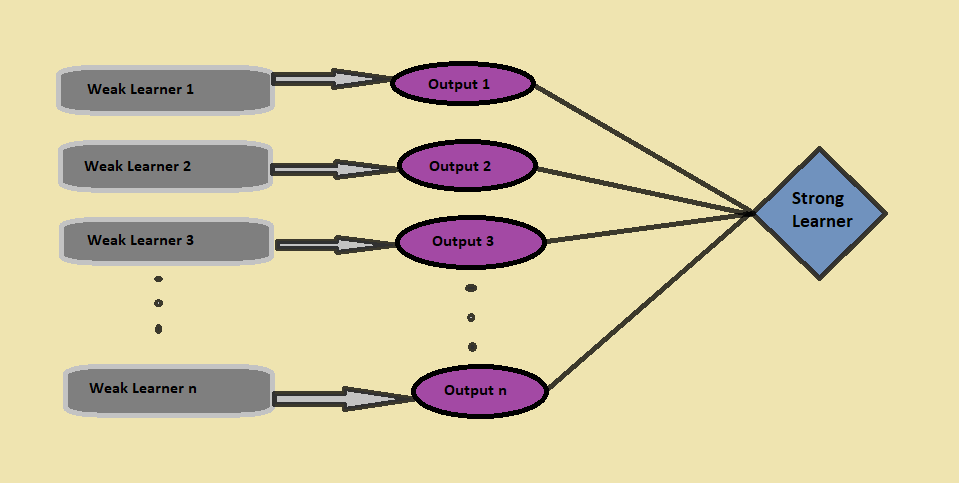
We will capture more information from the data by taking the average of predictions from these models.; Equivalently, the boost algorithm combines several simpler models (also called weak students) to generate the final result (also called strong student).
Now would you think about how to identify weak students?
To identify weak students, we use machine learning algorithms with a different distribution for each iteration and for each algorithm, generates a new weak prediction rule. After many iterations, the boost algorithm combines all vulnerable learners to form a single chain prediction rule.
Another essential thing to pay attention here is, ‘How do we determine a different distribution for each round??’
There are three steps we must consider to select the correct distribution:
- The weak student considers all distributions and then assigns equal weight to each observation, after
- If the error is generated by the forecast of the first weak learning algorithm, more attention is paid to the prediction error of the observations. The following weak learning algorithm applies.
- Finally, repeat the second step until the base learning algorithm reaches its limit or the desired precision is achieved.
Finally, due, the boost algorithm combines all the weak student outputs. Presents with a stronger and more powerful student, which eventually improves the accuracy of the model forecast (como se ve en la figure"Figure" is a term that is used in various contexts, From art to anatomy. In the artistic field, refers to the representation of human or animal forms in sculptures and paintings. In anatomy, designates the shape and structure of the body. What's more, in mathematics, "figure" it is related to geometric shapes. Its versatility makes it a fundamental concept in multiple disciplines.... anterior).
By boosting, instead of just combining the isolated classifiers, uses the mechanism of raising the weights of misclassified data points in the above classifiers.
Impulse algorithm typess
It's time to discuss some of the essential types of momentum algorithms now.
1. Aumento de gradientGradient is a term used in various fields, such as mathematics and computer science, to describe a continuous variation of values. In mathematics, refers to the rate of change of a function, while in graphic design, Applies to color transition. This concept is essential to understand phenomena such as optimization in algorithms and visual representation of data, allowing a better interpretation and analysis in...
In the gradient increase algorithm, we train multiple models sequentially, and for each new model, el modelo minimiza gradualmente la Loss functionThe loss function is a fundamental tool in machine learning that quantifies the discrepancy between model predictions and actual values. Its goal is to guide the training process by minimizing this difference, thus allowing the model to learn more effectively. There are different types of loss functions, such as mean square error and cross-entropy, each one suitable for different tasks and... usando el método Gradient Descent. the Gradient tree augmentation algorithm you accept decision trees like the weak thin because the nodes in a decision tree consider a different branch of characteristics to choose the best division, which means that all trees are not the same. Therefore, can capture different data outputs all the time.
The gradient tree augmentation algorithm is built sequentially because, for each new tree, the model considers the errors of the last tree, and the decision of each successive tree is based on the errors made by the previous tree.
Gradient Boosting algorithms are mainly used for classification and regression problems.
Python code:
from sklearn.ensemble importar GradientBoostingClassifier #For classification
from sklearn.ensemble import GradientBoostingRegressor #For regression
cl = GradientBoostingClassifier (n_estimators = 100, learning_rate = 1.0, max_depth = 1)
cl.fit (Xtrain, ytrain)
where:
n_estimators The parameter is used to control the number of weak students,
learning rate The parameter controls the contribution of all vulnerable students in the final result,
Maximum depth The parameter is for the maximum depth of the individual regression estimators to limit the number of nodes in the tree.
2. AdaBoost (adaptive reinforcement)
The AdaBoost algorithm, short for Adaptive drive, is a boost technique in machine learning that is used as Set method. In Adaptive drive, all weights are reassigned to each instance where higher weights are assigned to incorrectly classified models, and fits the sequence of weak students at different weights.
Adaboost starts with make predictions about the original data set in plain language, and then give the same weight to each observation. If the forecast made with the first student is incorrect, assigns the higher relevance for incorrectly predicted statement and iterative procedure. Continue adding new students until the limit in the model is met.
Podemos utilizar cualquier algoritmo de aprendizaje automático con Adaboost como estudiantes débiles si acepta pesos en el conjunto de datos de trainingTraining is a systematic process designed to improve skills, physical knowledge or abilities. It is applied in various areas, like sport, Education and professional development. An effective training program includes goal planning, regular practice and evaluation of progress. Adaptation to individual needs and motivation are key factors in achieving successful and sustainable results in any discipline.... y se utiliza tanto para problemas de regresión como de clasificación.
Python code:
from sklearn.ensemble import AdaBoostClassifier #For classification
from sklearn.ensemble import AdaBoostRegressor #For Regression
from sklearn.tree import DecisionTreeClassifier
dtree = DecisionTreeClassifier ()
cl = AdaBoostClassifier (n_estimators = 100, base_estimator = dtree, learning_rate = 1)
cl.fit (xtrain, ytrain)
where:
n_estimators and the learning_rate parameter has the same purpose as in the case of the Gradient Boosting algorithm,
base_estimator The parameter helps to specify different machine learning algorithms.
3. XGBoost
The XGBoost algorithm, abreviatura de Extreme Gradient Boosting, It is simply an impromptu version of the gradient increase algorithm, and the working procedure of both is almost the same. A crucial point in XGBoost is that Implementa procesamiento paralelo a nivel de nodeNodo is a digital platform that facilitates the connection between professionals and companies in search of talent. Through an intuitive system, allows users to create profiles, share experiences and access job opportunities. Its focus on collaboration and networking makes Nodo a valuable tool for those who want to expand their professional network and find projects that align with their skills and goals...., making it more powerful and faster than the gradient increase algorithm.. XGBoost reduces overfitting and improves overall performance a través de la inclusión de varias técnicas de regularizationRegularization is an administrative process that seeks to formalize the situation of people or entities that operate outside the legal framework. This procedure is essential to guarantee rights and duties, as well as to promote social and economic inclusion. In many countries, Regularization is applied in migratory contexts, labor and tax, allowing those who are in irregular situations to access benefits and protect themselves from possible sanctions.... a través de el establecimiento de los hiperparámetros del algoritmo XGBoost.
An important point to pay attention to XGBoost is that you don't need to worry about missing values in the dataset because, throughout the training procedure, the model itself learns where to fit missing values, In other words, the left node or the right node.
XGBoost is mainly used for sorting problems, but can be used for regression problems.
Python code:
import xgboost as xgb
xgb_model = xgb.XGBClassifier (learning_rate = 0,001, max_depth = 1, n_estimators_100)
xbg_model.fit (x_train, y_train)
FINAL NOTES
This post looked at impulse algorithms in machine learning, explained what momentum algorithms are and types of impulse algorithms: Adaboost, Gradient Boosting y XGBoost. Además miramos sus respectivos códigos y parametersThe "parameters" are variables or criteria that are used to define, measure or evaluate a phenomenon or system. In various fields such as statistics, Computer Science and Scientific Research, Parameters are critical to establishing norms and standards that guide data analysis and interpretation. Their proper selection and handling are crucial to obtain accurate and relevant results in any study or project.... de Python involucrados.
If you have any doubts, you can reach me on my LinkedIn @Mrinalwalia.
The media shown in this post is not the property of DataPeaker and is used at the author's discretion.





