
The challenge of making machines understand text
“Language is a wonderful means of communication”
You and I would have understood that phrase in a split second. But machines just can't process text data in raw form. They need us to break down the text into a numeric format that the machine can easily read (the idea behind Natural language processing!).
This is where Bag-of-Words concepts come into play. (BoW) y TF-IDF. Both BoW and TF-IDF are techniques that help us convert text sentences into numerical vectors.
I will talk about Bag-of-Words and TF-IDF in this article. We will use an intuitive and general example to understand each concept in detail.
New to Natural Language Processing (NLP)? We have the perfect courses to get you started:
Let's take an example to understand the bag of words (BoW) y TF-IDF
I'll take a popular example to explain Bag-of-Words (BoW) and TF-DF in this article.
We all love to watch movies (to varying degrees). I usually always look at the reviews of a movie before committing to see it.. I know many of you do the same! Then, i will use this example here.
Here's a sample of reviews on a particular horror movie:
- Revision 1: this movie is very scary and long
- Revision 2: this movie is not scary and it is slow
- Revision 3: this movie is creepy and good
You can see that there are some contrasting reviews about the movie, as well as the length and pace of the film. Imagine looking at thousands of reviews like these. Clearly, there are many interesting insights that we can extract from and develop to assess how well the film performed.
But nevertheless, as we saw previously, we can't just give these sentences to a machine learning model and ask it to tell us if a review was positive or negative. We need to perform certain text preprocessing steps.
Bag-of-Words and TF-IDF are two examples of how to do this. Let's understand in detail.
Create vectors from text
Can you think of some techniques we could use to vectorize a sentence at the beginning? The basic requirements would be:
- It should not result in a sparse matrix as sparse matrices result in high computational cost
- We should be able to retain most of the linguistic information present in the sentence.
Word embedding is one of those techniques in which we can represent text using vectors. The most popular forms of word inlays are:
- BoW, what does bag of words mean
- TF-IDF, What does Term Frequency-Reverse Document Frequency mean
Now, let's see how we can render previous movie reviews as inlays and prepare them for a machine learning model.
Word bag model (BoW)
El modelo Bag of Words (BoW) is the simplest way to represent text in numbers. Like the term itself, we can represent a sentence as a bag of words vector (a string of numbers).
Recall the three types of movie reviews we saw earlier:
- Revision 1: this movie is very scary and long
- Revision 2: this movie is not scary and it is slow
- Revision 3: this movie is creepy and good
We will first build a vocabulary from all the unique words in the previous three revisions. The vocabulary consists of these 11 words: 'This', 'film', 'it is', 'very', 'scary', 'and', 'long', ‘no’, 'slow', ‘Creepy’, 'well '.
Now we can take each of these words and mark their appearance in the three previous movie reviews with 1 Y 0. This will give us 3 vectors for 3 reviews:
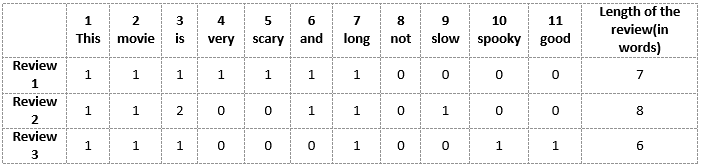
Review vector 1: [1 1 1 1 1 1 1 0 0 0 0]
Review vector 2: [1 1 2 0 0 1 1 0 1 0 0]
Review vector 3: [1 1 1 0 0 0 1 0 0 1 1]
And that's the central idea behind the Bag of Words model. (BoW).
Disadvantages of using a bag of words model (BoW)
In the example above, we can have vectors of length 11. But nevertheless, we start to face problems when we find new sentences:
- If the new sentences contain new words, then the size of our vocabulary would increase and, Thus, the length of the vectors would also increase.
- What's more, the vectors would also contain many zeros, which would result in a sparse matrix (what we would like to avoid)
- We do not retain information about the grammar of sentences or the order of words in the text.
Term Frequency-Inverse frequency of documents (TF-IDF)
Let's first put a formal definition around TF-IDF. This is how Wikipedia puts it:
“The frequency of the terms, the inverse frequency of documents, it is a numerical statistic that tries to reflect the importance of a word for a document in a collection or corpus”.
Term frequency (TF)
First let's understand Frequent Term (TF). It is a measure of how often a term appears, t, in a document, d:

Here, in the numerator, n is the number of times the term appears “t” in the document “d”. Therefore, each document and term would have its own TF value.
Again we will use the same vocabulary that we had built in the Bag-of-Words model to show how to calculate the TF for the Review # 2:
Revision 2: this movie is not scary and it is slow
Here,
- Vocabulary: 'This', 'film', 'it is', 'very', ‘Terrifying’, 'and', 'Long', ‘no’, 'slow', ‘Creepy’, 'good’
- Number of words in the Review 2 = 8
- TF for the word 'this’ = (number of times' this appears’ in review 2) / (number of terms in the review 2) = 1/8
Similar,
- TF ('film') = 1/8
- TF ('it is') = 2/8 = 1/4
- TF ('very') = 0/8 = 0
- TF ('scary') = 1/8
- TF ('and') = 1/8
- TF ('long') = 0/8 = 0
- TF (‘no’) = 1/8
- TF ('slow') = 1/8
- TF (‘Creepy’) = 0/8 = 0
- TF ('well') = 0/8 = 0
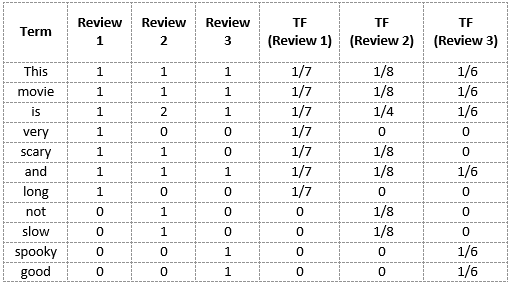
We can calculate the term frequencies for all terms and all revisions in this way:
Reverse document frequency (IDF)
IDF is a measure of the importance of a term. We need the IDF value because calculating the TF alone is not enough to understand the importance of the words:
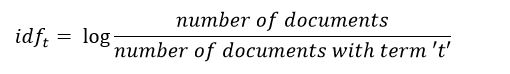
We can calculate the IDF values for all the words in the Review 2:
IDF ('this') = log (number of documents / number of documents containing the word 'this') = log (3/3) = log (1) = 0
Similar,
- IDF ('film',) = log (3/3) = 0
- IDF ('it is') = log (3/3) = 0
- IDF (‘no’) = log (3/1) = log (3) = 0.48
- IDF ('scary') = log (3/2) = 0.18
- IDF ('and') = log (3/3) = 0
- IDF ('slow') = log (3/1) = 0.48
We can calculate the IDF values for each word in this way. Therefore, the IDF values for the entire vocabulary would be:
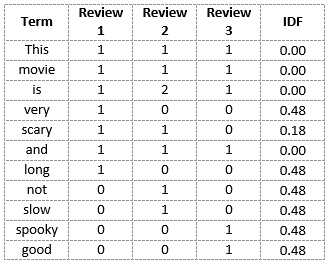
Therefore, we see that words like "es", "this", "and", etc., are reduced to 0 and they have little importance; while words like "scary", "long", "well", etc. are words with more importance and therefore have greater value.
Now we can calculate the TF-IDF score for each word in the corpus. Words with a higher score are more important and those with a lower score are less important:
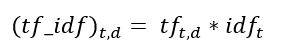
Now we can calculate the TF-IDF score for each word in the Review 2:
TF-IDF ('this', Revision 2) = TF ('this', Revision 2) * IDF ('this') = 1/8 * 0 = 0
Similar,
- TF-IDF ('film', Revision 2) = 1/8 * 0 = 0
- TF-IDF ('it is', Revision 2) = 1/4 * 0 = 0
- TF-IDF (‘no’, Revision 2) = 1/8 * 0.48 = 0.06
- TF-IDF ('scary', Revision 2) = 1/8 * 0.18 = 0.023
- TF-IDF ('and', Revision 2) = 1/8 * 0 = 0
- TF-IDF ('slow', Revision 2) = 1/8 * 0.48 = 0.06
In the same way, we can calculate TF-IDF scores for all words against all reviews:
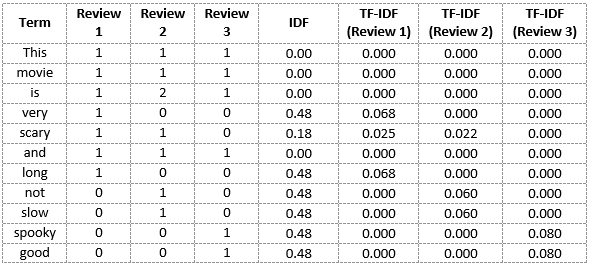
We have now obtained the TF-IDF scores for our vocabulary. TF-IDF also provides larger values for less frequent words and is high when IDF and TF values are high, namely, the word is rare in all documents combined but frequent in a single document.
Final notes
Let me summarize what we have covered in the article:
- Bag of Words simply creates a set of vectors containing the count of occurrences of words in the document (reviews), while the TF-IDF model contains information on the most important and least important words as well.
- Bag of Words vectors are easy to interpret. But nevertheless, TF-IDF usually works best in machine learning models.
While both Bag-of-Words and TF-IDF have been popular in their own sense, there was still a gap in understanding the context of the words. Detect the similarity between the words' creepy’ and ‘scary’, or translate our given documents to another language, requires much more information in the docs.
This is where word embedding techniques like Word2Vec come into play., Continuous Bag of Words (CBOW), Skipgram, etc. You can find a detailed guide to these techniques here:





