
Introduction:
One of the most important steps as part of data preprocessing is detecting and dealing with outliers, since they can negatively affect the statistical analysis and the process of trainingTraining is a systematic process designed to improve skills, physical knowledge or abilities. It is applied in various areas, like sport, Education and professional development. An effective training program includes goal planning, regular practice and evaluation of progress. Adaptation to individual needs and motivation are key factors in achieving successful and sustainable results in any discipline.... of a machine learning algorithm, resulting in lower precision.
1. What are outliers? 🤔
We've all heard of the idiom ‘strange, which means something unusual compared to others in a group.
Similarly, an outlier is an observation in a given data set that is far from the rest of the observations. That means an outlier is much larger or smaller than the remaining values in the set..
2. Why do they occur?
An outlier can occur due to variability in the data, or due to experimental error / human error.
May indicate experimental error or large skew in the data (heavy glue distribution).
3. That affect?
In statistics, we have three measures of central tendency: Media, MedianThe median is a statistical measure that represents the central value of a set of ordered data. To calculate it, the data is organized from lowest to highest and the number in the middle is identified. If there are an even number of observations, the two core values are averaged. This indicator is especially useful in asymmetric distributions, since it is not affected by extreme values.... & Fashion. Help us describe the data.
The mean is the precise measure to describe the data when we do not have outliers present..
The median is used if there is an outlier in the data set.
The mode is used if there is an outlier AND about half or more of the data is equal.
The “media” is the only measure of central tendency that is affected by outliers, which in turn affects the standard deviation.
Example:
Consider a small data set, sample = [15, 101, 18, 7, 13, 16, 11, 21, 5, 15, 10, 9]. Looking at it, you can quickly say that '101’ is an outlier that is much larger than the other values.
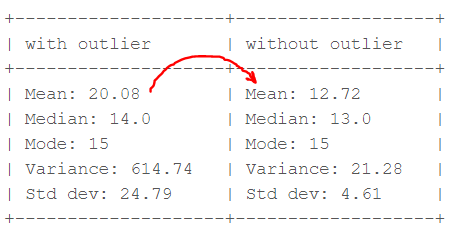
From the above calculations, we can clearly say that the Average is more affected than the Median.
4. Detection of atypical values
If our data set is small, we can detect the outlier just by looking at the dataset. But, What if we have a large data set, how we identify outliers? We need to use visualization techniques and mathematics.
Here are some of the techniques to detect outliers.
- Box plotsBox Diagrams, Also known as box and whisker diagrams, are statistical tools that represent the distribution of a dataset. These diagrams show the median, quartiles and outliers, allowing data variability and symmetry to be visualized. They are useful in comparison between different groups and in exploratory analysis, making it easier to identify trends and patterns in the data....
- Z score
- Interval between quantiles (IQR)
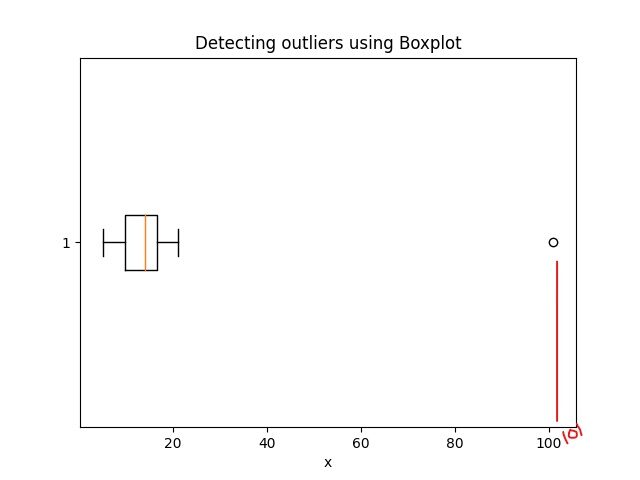
4.1 Detection of atypical values using Boxplot:
The Python code for the box plot is:
import matplotlib.pyplot as plt
plt.boxplot(sample, vert=False)
plt.title("Detecting outliers using Boxplot")
plt.xlabel(Sample)
4.2 Outlier detection using Z scores
Criteria: any data point whose Z-score falls outside the 3rd standard deviation is an outlier.
Steps:
- loop through all the data points and calculate the Z score using the formula (Xi-mean) / std.
- set a threshold value of 3 and mark the data points whose absolute value of Z-score is greater than the threshold as outliers.
import numpy as np
outliers = []
def detect_outliers_zscore(data):
    thres = 3
    mean = np.mean(data)
    std = e.g. std(data)
    # print(mean, std)
    for i in data:
        z_score = (i-mean)/std
        if (np.abs(z_score) > thres):
            outliers.append(i)
    return outliers# Driver code
sample_outliers = detect_outliers_zscore(sample)
print("Outliers from Z-scores method: ", sample_outliers)
The results of the above code: Outliers of the Z-score method: [101]
4.3 Outlier detection using the range between quantiles (IQR)
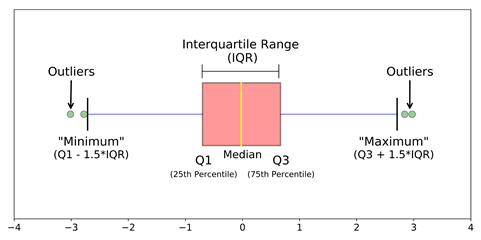
Criteria: the data points found 1,5 times the IQR above Q3 and below Q1 are outliers.
Steps:
- Sort the dataset in ascending order
- calculate the first and third quartiles (Q1, Q3)
- calculate IQR = Q3-Q1
- calculate lower limit = (Q1–1.5 * IQR), upper limit = (Q3 + 1.5 * IQR)
- loop through the dataset values and check those that fall below the lower limit and above the upper limit and mark them as outliers
Python code:
outliers = []
def detect_outliers_iqr(data):
    data = sorted(data)
    q1 = np.percentile(data, 25)
    q3 = np.percentile(data, 75)
    # print(q1, q3)
    IQR = q3-q1
    lwr_bound = q1-(1.5*IQR)
    upr_bound = q3+(1.5*IQR)
    # print(lwr_bound, upr_bound)
    for i in data:
        if (i<lwr_bound or i>upr_bound):
            outliers.append(i)
    return outliers# Driver code
sample_outliers = detect_outliers_iqr(sample)
print("Outliers from IQR method: ", sample_outliers)
The results of the above code: IQR method outliers: [101]
5. Handling of outliers
So far we learned about outlier detection. The main question is WHAT do we do with the outliers?
Here are some of the methods to deal with outliers.
- Trim / remove outlier
- Quantile-based coatings and pavements
- Average imputation / median
5.1 Cutout / Outlier removal
In this technique, we remove outliers from the data set. Although it is not a good practice to follow.
Python code to remove the outlier and copy the rest of the elements to another array.
# Trimming
for i in sample_outliers:
    a = np.delete(sample, np.where(sample==i))
print(a)
# print(len(sample), len(a))
The outlier '101’ is removed and the rest of the data points are copied into another array 'a'.
5.2 Quantile-based coverings and pavements
In this technique, the outlier is limited to a certain value above the percentile value 90 or is reduced by a factor below the percentile value 10.
Python code:
# Computing 10th, 90th percentiles and replacing the outliers
tenth_percentile = np.percentile(sample, 10)
ninetieth_percentile = np.percentile(sample, 90)
# print(tenth_percentile, ninetieth_percentile)b = np.where(sample<tenth_percentile, tenth_percentile, sample)
b = np.where(b>ninetieth_percentile, ninetieth_percentile, b)
# print("Sample:", sample)
print("New array:",b)
The results of the above code: New matrix: [15, 20.7, 18, 7.2, 13, 16, 11, 20.7, 7.2, 15, 10, 9]
Data points that are less than the percentile 10 are replaced with the percentile value 10 and data points that are greater than the percentile 90 are replaced with the percentile value 90.
5.3 mean imputation / median
As the mean value is heavily influenced by outliers, it is recommended to replace outliers with the median value.
Python code:
median = np.median(sample)# Replace with median
for i in sample_outliers:
    c = np.where(sample==i, 14, sample)
print("Sample: ", sample)
print("New array: ",c)
# print(x.dtype)
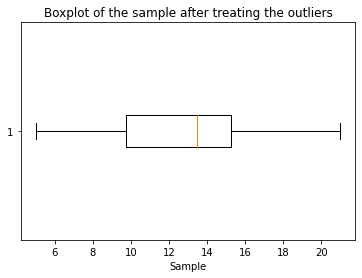
Viewing the data after treating the outlier
plt.boxplot(c, vert=False)
plt.title("Boxplot of the sample after treating the outliers")
plt.xlabel("Sample")
Summary:
In this blog, We learned about an important phase of data preprocessing which is the handling of outliers. Now we know different methods to detect and treat outliers.
References:
IQR for detection of atypical values
GitHub repository for consulting the Jupyter notebook
Hope this blog helps you understand the concept of outliers. Please, vote for if you like it. Happy learning !! 😊
The media shown in this article is not the property of DataPeaker and is used at the author's discretion.





