
Introduction
“Data is the fuel for machine learning algorithms”.
Before looking for information from the data, we first have to perform preprocessing tasks which then only allow us to use that data for further observation and train our machine learning model.
Missing value correction is required to reduce bias and produce powerful suitable models. Most algorithms cannot handle missing data, so you have to act in some way to just not let your code crash. Then, let's start with the methods to solve the problem.
Methods for dealing with missing values
Example 1, Let's have a dummy data set in which there are three independent characteristics (predictors) and a dependent characteristic (answer).
| Feature-1 | Feature-2 | Feature-3 | Production |
| Masculine | 23 | 24 | Yes |
| – – – – | 24 | 25 | No |
| Woman | 25 | 26 | Yes |
| Masculine | 26 | 27 | Yes |
Here, we have a missing value in the row 2 for Feature-1.
Popular methods that the machine learning community uses to handle the missing value of categorical variables in the dataset are as follows:
1. Delete the observations: If there are a large number of observations in the data set, where all classes to be predicted are sufficiently represented in the training data, try to remove missing value observations, which would not generate significant changes to your feed from your model.
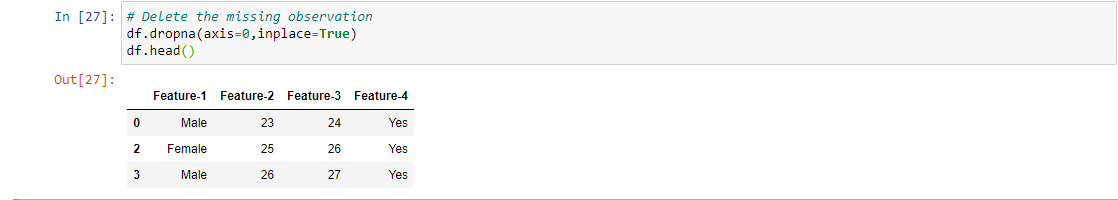
For instance, 1, Implement this method on a given dataset, we can remove the entire row containing the missing values (delete row-2).
2. Replace missing values with the most frequent value: You can always charge them based on Way in the case of categorical variables, make sure you don't have very skewed class distributions.
NOTE: But in some cases, this strategy can make the data unbalanced in the wrt classes if there are a lot of missing values present in our dataset.
– Generally, replace missing values with mean / medianThe median is a statistical measure that represents the central value of a set of ordered data. To calculate it, the data is organized from lowest to highest and the number in the middle is identified. If there are an even number of observations, the two core values are averaged. This indicator is especially useful in asymmetric distributions, since it is not affected by extreme values.... / fashion is a crude way of dealing with missing values. Depending on the context, as if the variation is low or if the variableIn statistics and mathematics, a "variable" is a symbol that represents a value that can change or vary. There are different types of variables, and qualitative, that describe non-numerical characteristics, and quantitative, representing numerical quantities. Variables are fundamental in experiments and studies, since they allow the analysis of relationships and patterns between different elements, facilitating the understanding of complex phenomena.... has low leverage on response, such a rough approximation is acceptable and could give satisfactory results. In this case, since you are saying that it is a categorical variable, this step may not be applicable.
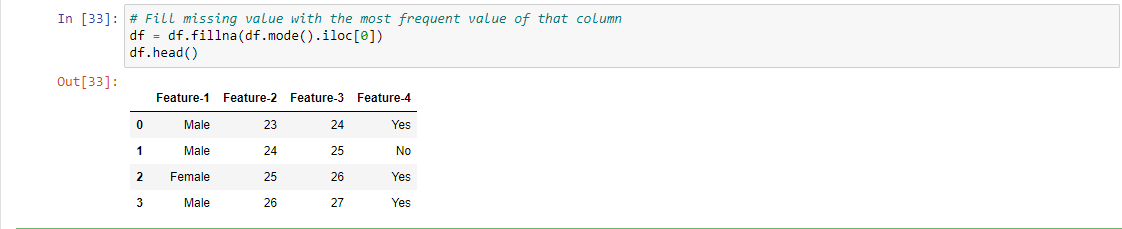
For instance, 1, To implement this method, we replace the missing value with the most frequent value for that particular column, here we replace the missing value by Male since the count of Male is greater than Female (male = 2 and Feminine = 1).
3. Develop a model to predict missing values: A smart way to do this could be to train a classifier on your missing value columns as a dependent variable against other characteristics in your dataset and try to impute based on the newly trained classifier.
Here is the algorithm you can follow:
– Divide the data into two parts. One part will have the current values of the column, including original output column, the other part will have the rows with the missing values.
– Divide the 1st part (current values) in a cross-validation set for model selection.
– Train your models and test your metrics with cross-validated data. You can also perform a grid search or a random search to get the best results.
– Finally, with the model, predicts unknown values missing from our problem.
NOTE: Since you are trying to impute missing values, things will be more pleasant this way, since they are not biased and you get the best predictions from the best model.
For instance, 1, To implement the given strategy, first we will consider the column Characteristic-2, Feature-3 and Output for our new classifier, what does it mean that you are 3 Columns are used as independent characteristics for our new classifier and Characteristic-1 is considered a result and an objective note that here we consider only the rows that are not missing, since our train data and observations that have a missing value will become our test data. We have to make the prediction using our model on the test data and, after predictions, we have the data set with no missing value.
4. Eliminating the variable: If there is an exceptionally larger set of missing values, try excluding the variable itself for additional model, but you have to make sure that it is not very significant to predict the target variable, namely, the correlation between the discarded variable and the target variable is very low or redundant.
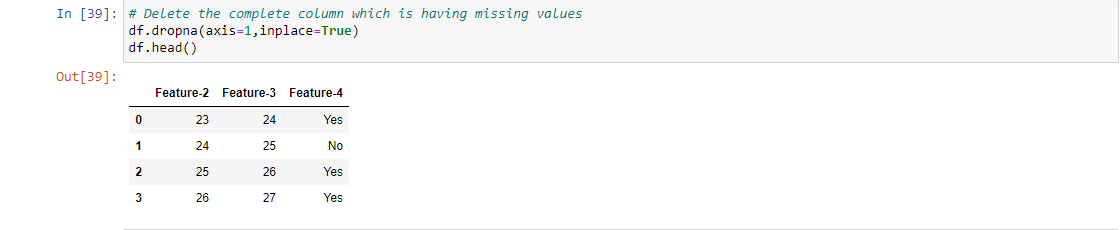
For instance, 1, To implement this strategy to handle missing values, we have to remove the entire column that contains the missing values, so for a given dataset we remove Characteristic-1 completely and use only the characteristics on the left to predict our target variable.
5. Apply unsupervised machine learning techniques: In this approach, we use unsupervised techniques such as K-means, Hierarchical grouping, etc. The idea is that you can skip those columns that have missing values and consider all other columns except the target column and try to create as many as no clusters of independent characteristics (after removing missing value columns), finally find the category in which the missing row falls.
For instance, 1, To implement this strategy, we drop the Characteristic-1 column and then we use Characteristic-2 and Characteristic-3 as our characteristics for the new classifier and then, Finally, after the formation of the clusterA cluster is a set of interconnected companies and organizations that operate in the same sector or geographical area, and that collaborate to improve their competitiveness. These groupings allow for the sharing of resources, Knowledge and technologies, fostering innovation and economic growth. Clusters can span a variety of industries, from technology to agriculture, and are fundamental for regional development and job creation...., we try to look at which cluster the missing record is in and we are ready with our final dataset for further analysis.
Python implementation
Import the required dependencies.

Load and read the dataset.

Find the number of missing values per column.
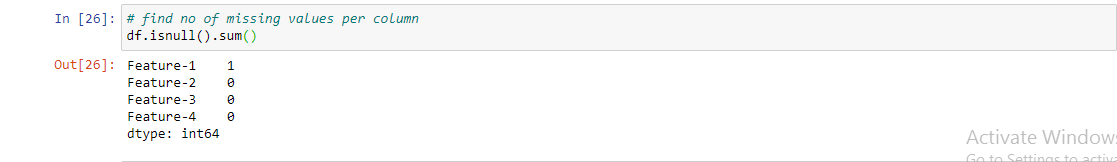
Apply strategy-1 (remove missing observations).
Apply Strategy-2 (Replace missing values with the most frequent value).
Apply Strategy-3 (Remove the variable that has missing values).
Apply the strategy 4 (Develop a model to predict missing values).
For this strategy, first we encode our independent categorical columns using "One Hot Encoder" and dependent categorical columns using "Label Encoder".
– Read and load the encoded data set.
– Make missing records like our test data.
– Make records that are not missing like our data trainingTraining is a systematic process designed to improve skills, physical knowledge or abilities. It is applied in various areas, like sport, Education and professional development. An effective training program includes goal planning, regular practice and evaluation of progress. Adaptation to individual needs and motivation are key factors in achieving successful and sustainable results in any discipline.....
– Separate independent and dependent variables.

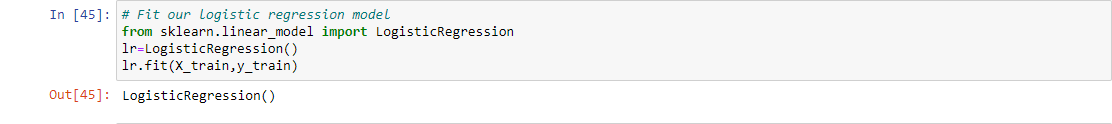
– Fit our Logistic Regression model.
– Predict the class of missing records.

This completes our implementation part!!
Final notes
Thank you for reading!
This article introduces you to different ways to approach the problem of having missing values for categorical variables..
If you liked this and want to know more, visit my other articles on data science and machine learning by clicking the link
Feel free to contact me at Linkedin, Email.
Anything not mentioned or do you want to share your thoughts? Feel free to comment below and I'll get back to you.
Until then, stay home, stay safe to prevent the spread of COVID-19, And keep learning!
About the Author
Chirag Goyal
Nowadays, I am pursuing my Bachelor of Technology (B.Tech) in Computer Science and Engineering from the Indian Institute of Technology, Jodhpur (IITJ). I am very excited about machine learning, the deep learningDeep learning, A subdiscipline of artificial intelligence, relies on artificial neural networks to analyze and process large volumes of data. This technique allows machines to learn patterns and perform complex tasks, such as speech recognition and computer vision. Its ability to continuously improve as more data is provided to it makes it a key tool in various industries, from health... and artificial intelligence.
The media shown in this article is not the property of DataPeaker and is used at the author's discretion.





