
Introduction
Machine learning is nothing more than building a 'machine’ that learns’ from your experience. And it improves with experience, just like humans. We also learn from our experiences. Right ? Companies like Google, Facebook, Microsoft are using machine learning techniques on a larger scale.
But nevertheless, a common mistake people make is that they need to learn to code to start machine learning. While coding becomes necessary for anyone serious about machine learning, but not to start it. You can look at a GUI driven tool like Weka or even Excel to get started with machine learning.
Here, i will introduce you to an easier way to get started with machine learning.
Do you find it difficult to understand the encoding?
Machine learning requires powerful coding skills / algorithms. And that's why people with a computer science degree find it relatively easier to be successful in the domain of machine learning..
But the scenery has changed. But nevertheless, can't escape encryption completely, you can still get started with machine learning. Once you start, you can improve your coding skills.
The good news is that now you can start machine learning using Microsoft Excel. Yes! you heard it right.
Frontline Solvers has introduced ‘XLMINER DATA MINING‘Add-in for MS Excel. It is an easy to use tool, made for professionals, for data visualization, forecasting and data mining. It is easy to use if:
- You have worked in MS Excel in the past
- Has work experience with SPSS
Read also: Simple but powerful tricks for analyzing data in Excel
What are the tasks that XLMiner can perform?
I knew this would come. Well! XLMiner can do many things that you do in R, Python or Julia. That too, without writing a code snippet. Offers a great deal on machine learning and data mining tasks. XLMiner is compatible with Excel 2007, Excel 2010 and excel 2013 (32 Y 64 bits). Here is the list of tasks that can be performed with XLMiner:
- Data exploration and visualization
- Function engineering
- Text extraction
- Time series analysis
- Machine learning
- Regression
- Classification
- Grouping
- Ensemble modeling
- Neural networks
Note: not available for free. You can download it in a trial period of 15 days and then buy a two-year license for $ 2495.
In this article, I will demonstrate the steps to perform regression, classification and groupingThe "grouping" It is a concept that refers to the organization of elements or individuals into groups with common characteristics or objectives. This process is used in various disciplines, including psychology, Education and biology, to facilitate the analysis and understanding of behaviors or phenomena. In the educational field, for instance, Grouping can improve interaction and learning among students by encouraging work.. in excel. I recommend that you work on small data sets in Excel, since it could fail. It's good to use it on data sets like Titanic.
To get the best of this article, should have / acquire basic knowledge of these algorithms. If you need a quick refresher on machine learning, I recommend that you check out these tutorials: Machine learning algorithm basics
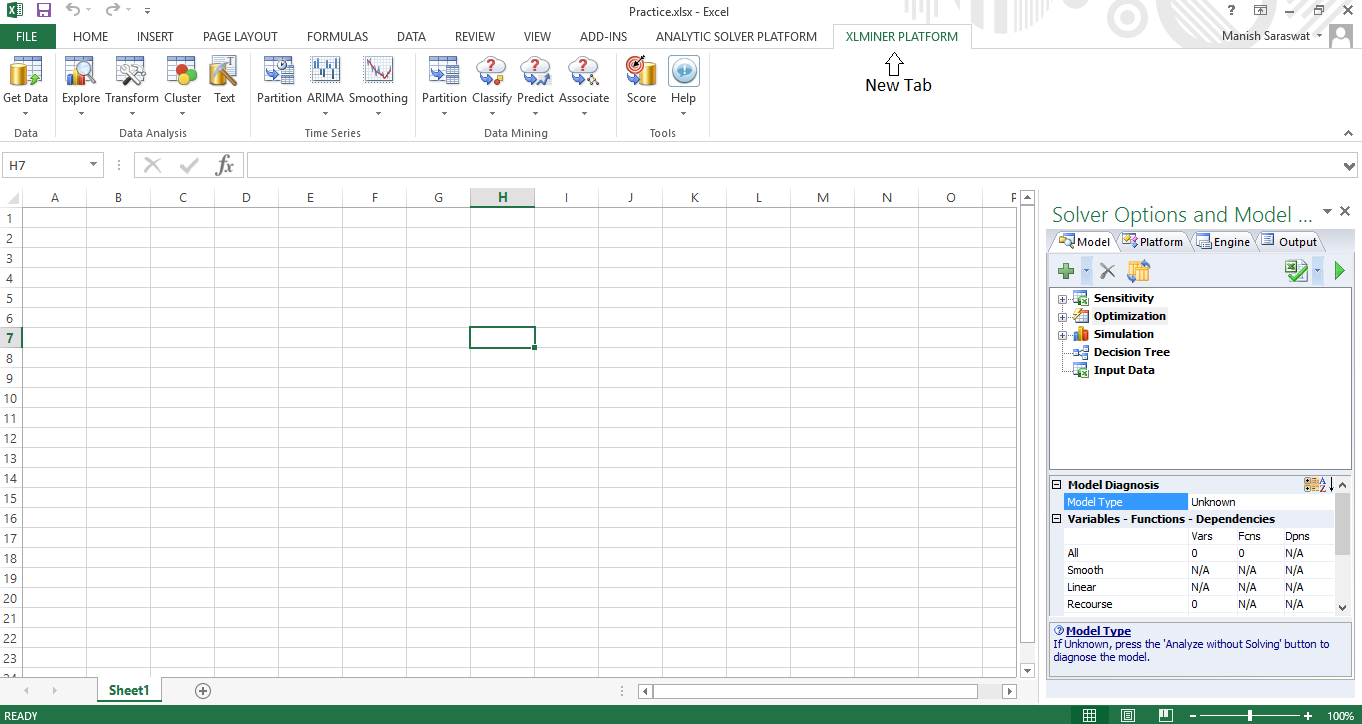
I have installed XLMiner. After installation, you will notice that XLMINER appears on the main tabs (picture below). You can also see this overview of the XLMiner platform.
Let us begin !
Tutorial: multiple linear regression
Regression is no big deal. You can also do it using the plugin ‘data analysis toolkit‘Available in Excel. It is good for statistical analysis. For machine learning, would need XLMiner. Here I have demonstrated multiple regression using XLMiner. For linear regression, all steps remain the same, except that it selects an variableIn statistics and mathematics, a "variable" is a symbol that represents a value that can change or vary. There are different types of variables, and qualitative, that describe non-numerical characteristics, and quantitative, representing numerical quantities. Variables are fundamental in experiments and studies, since they allow the analysis of relationships and patterns between different elements, facilitating the understanding of complex phenomena.... independent for modeling. Following are the steps:
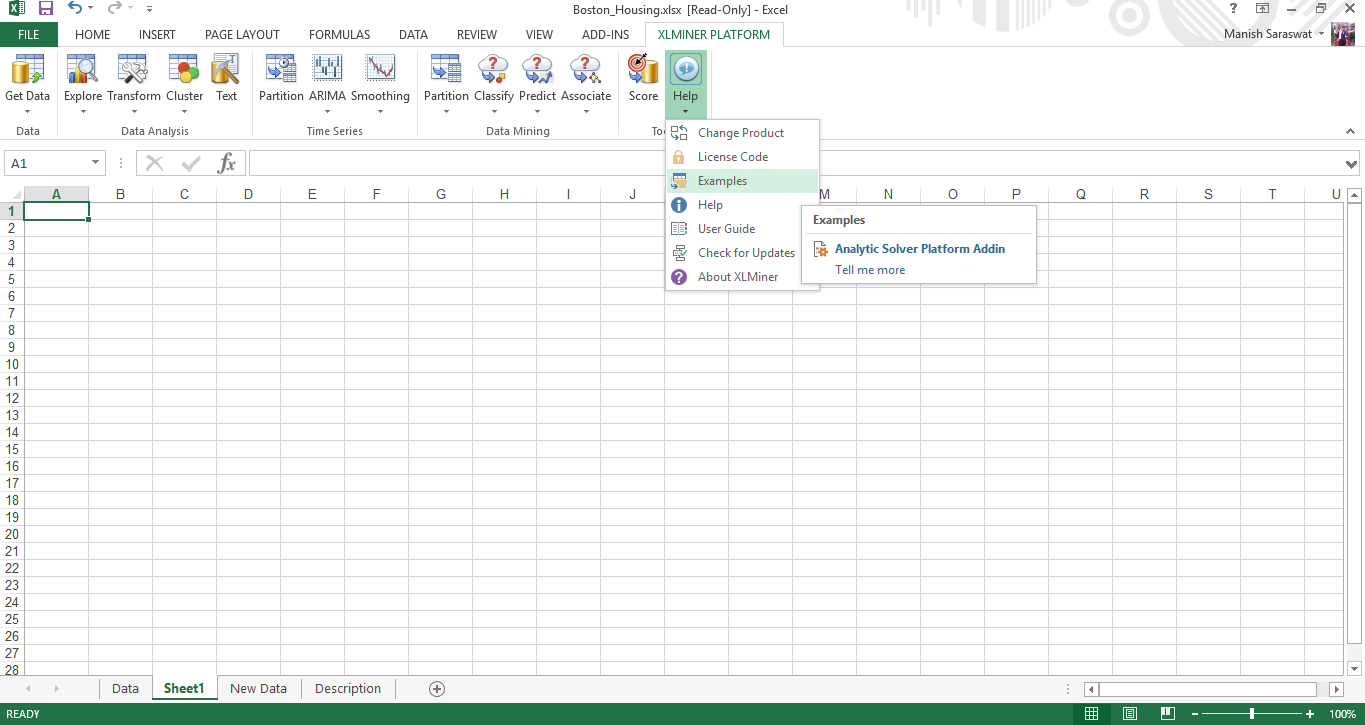
1. I have used the Boston housing dataset. This data represents house prices in Boston based on various factors that influence. You can load the dataset using: Help -> Examples -> Boston Housing.
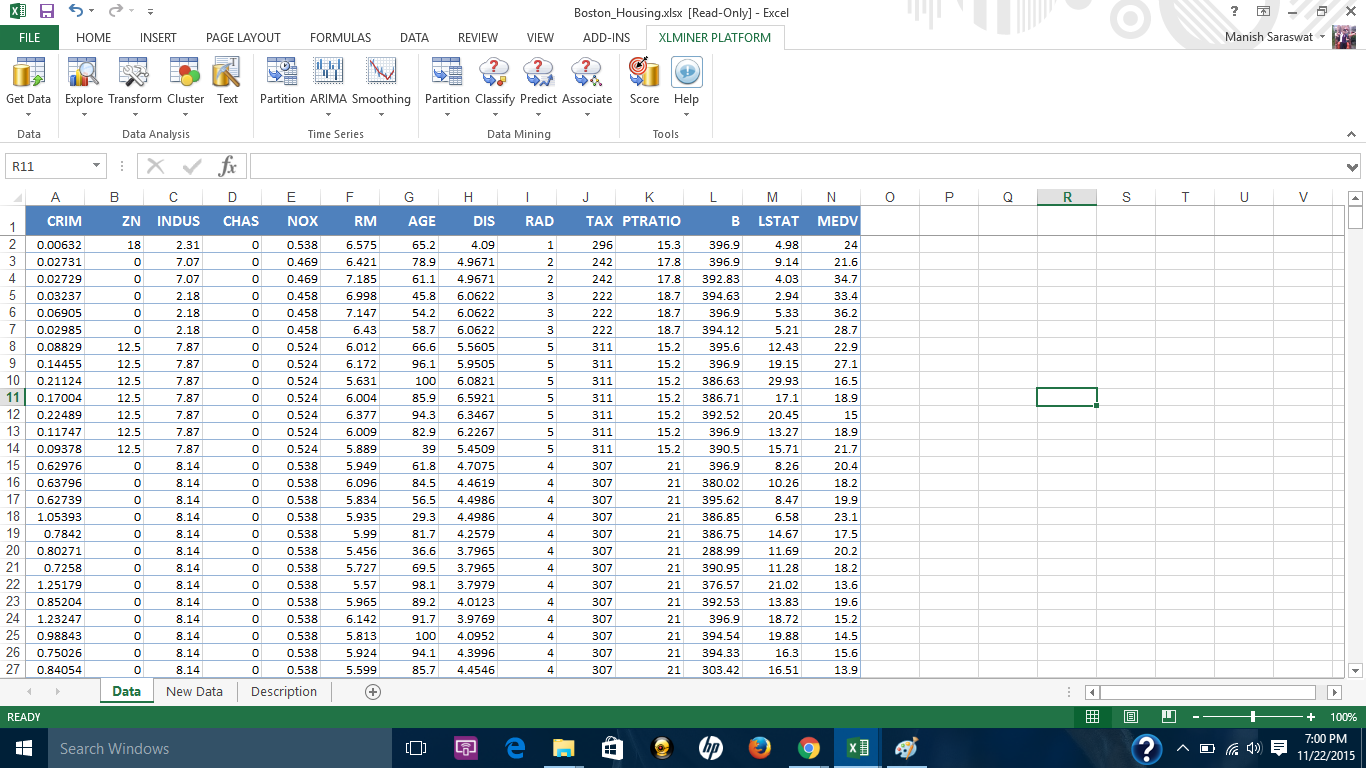
2. Here is the data set.
3. There are no missing values in this dataset. But nevertheless, this plugin provides a convenient option to deal with missing values. You can access this option from here.
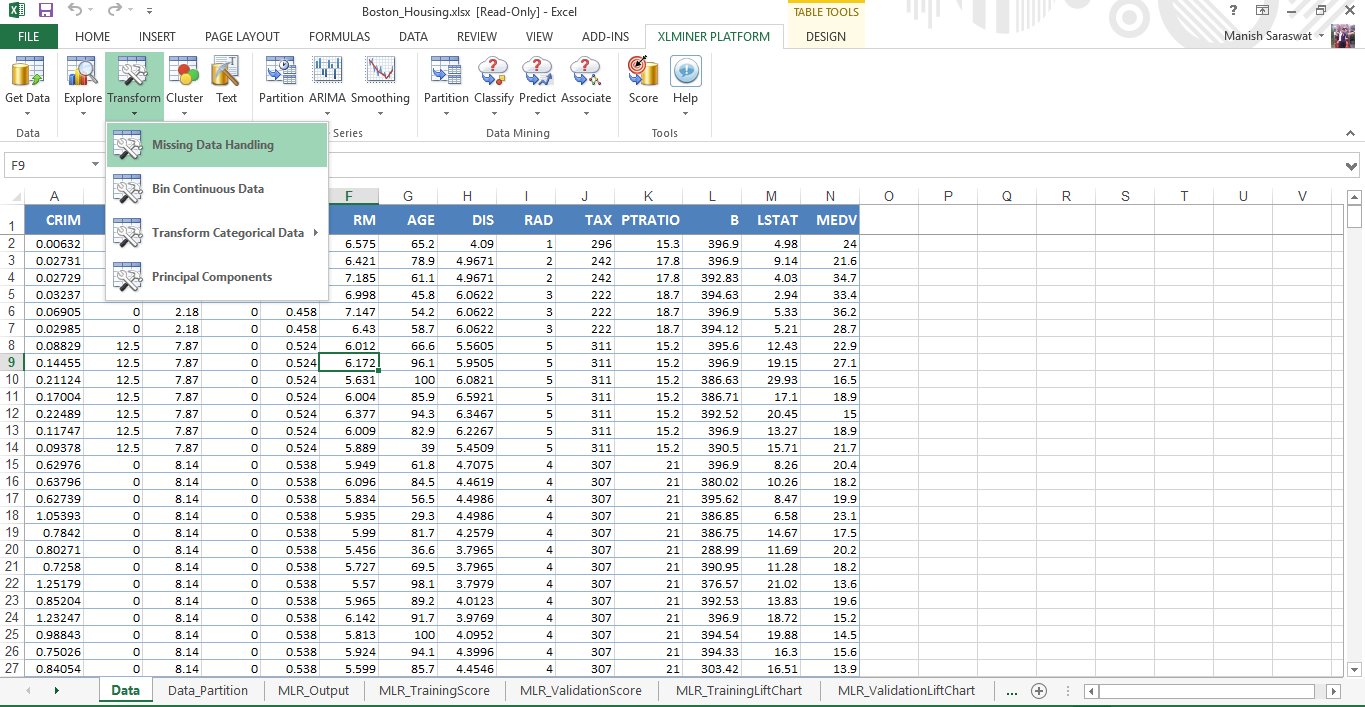
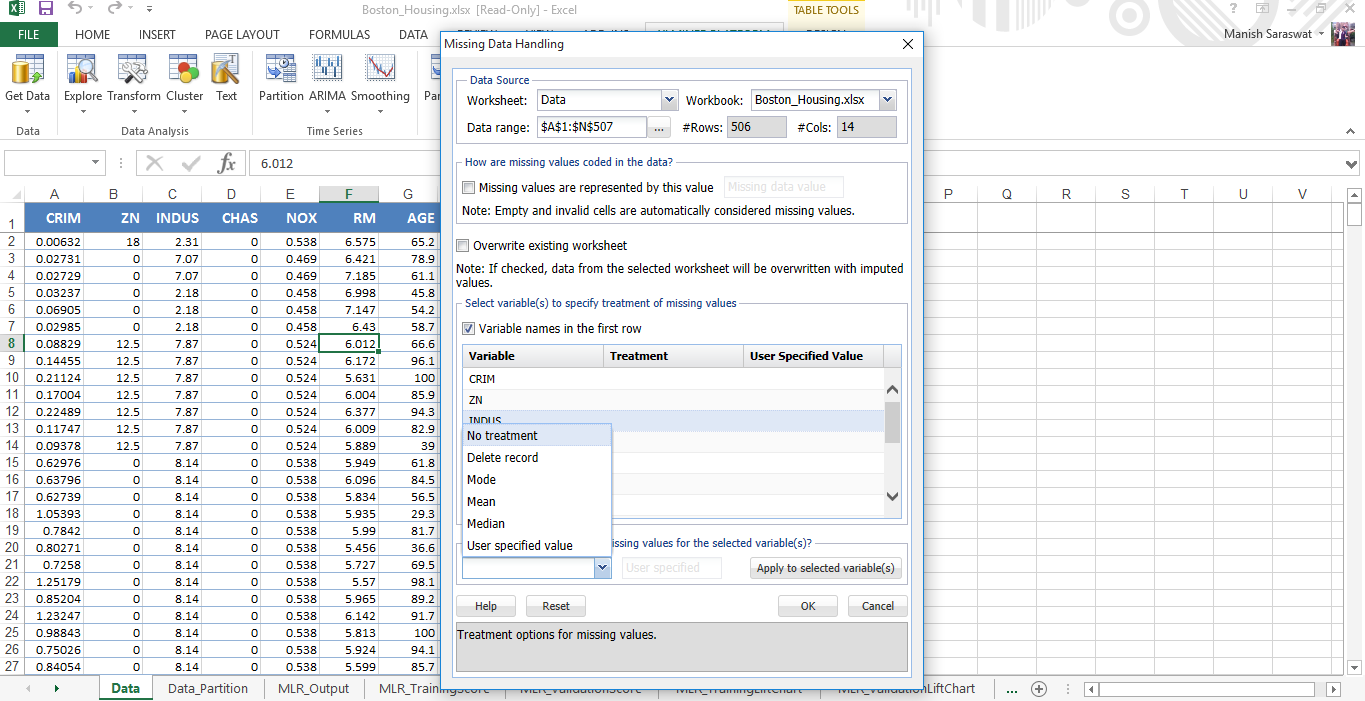
Simply, select the variables where you find the missing values. If the missing values are represented by 'null', ‘N / A’ or in any other way, mention it. Finally, you can choose the treatment method and voila.
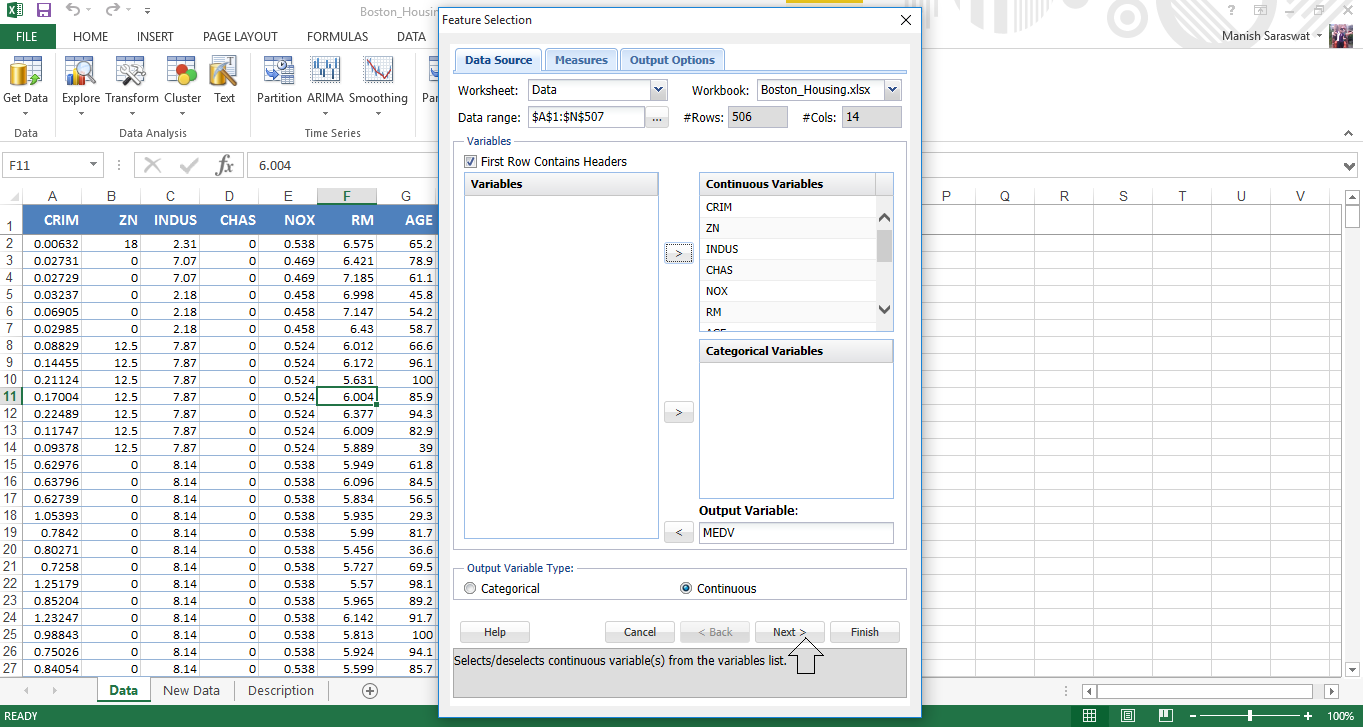
4. Now we will make the selection of functions. MEDV is the response variable. MEDV represents the median value of owner-occupied homes in $ 1000.
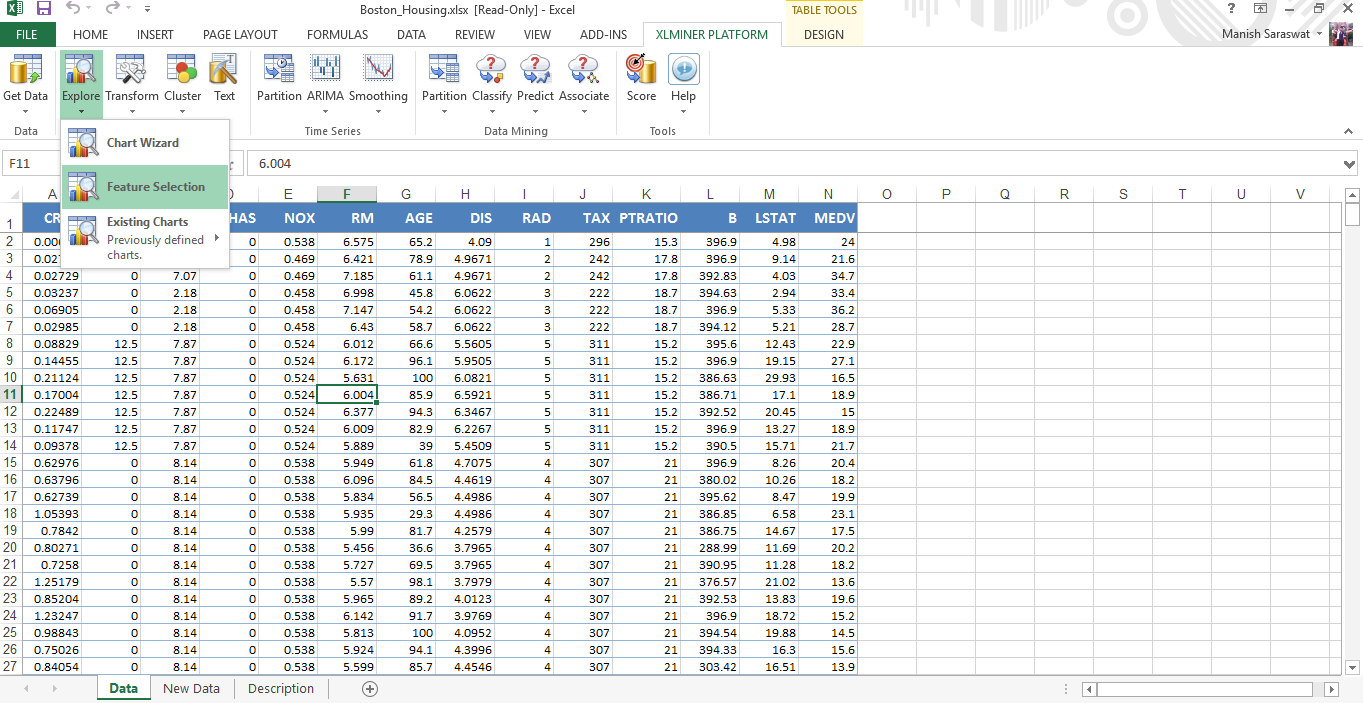
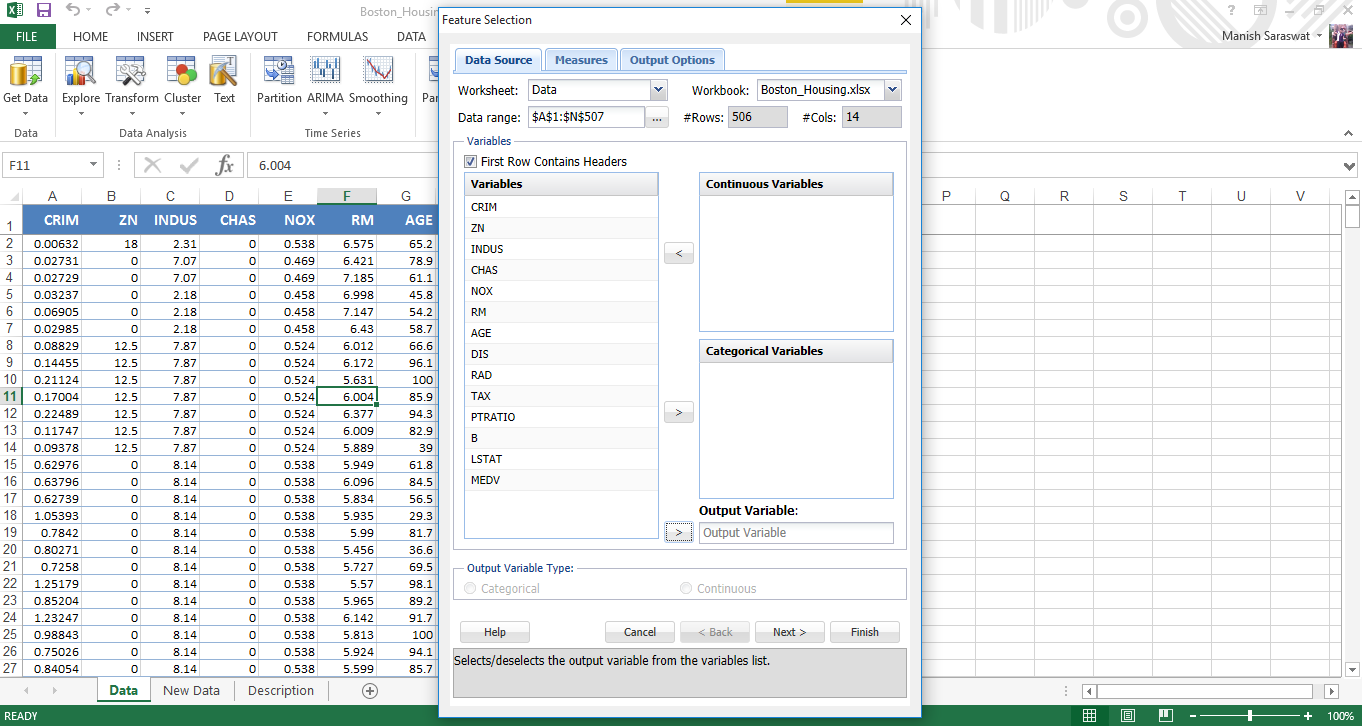
5. Use Shift + click to select all independent variables at once. Send MEDV to the output variable. Click Next.
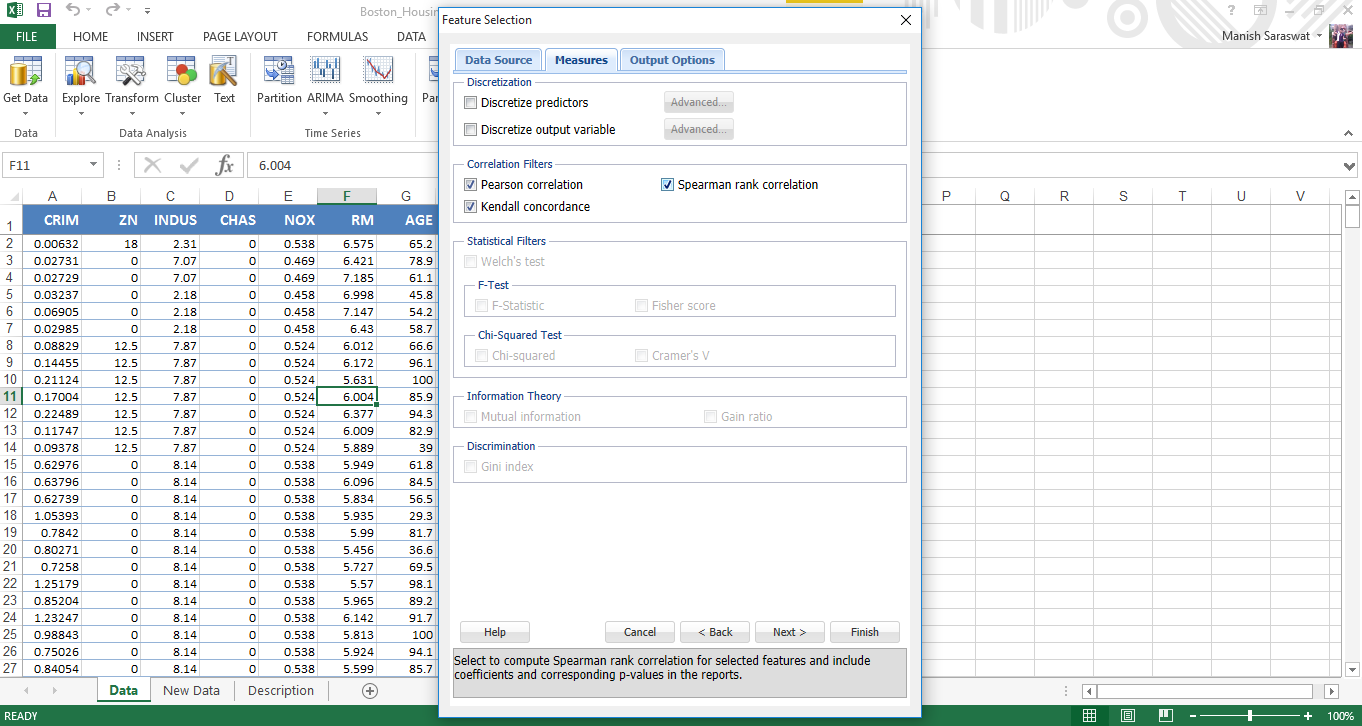
6. Select correlation filters. I have selected all three. Click Next
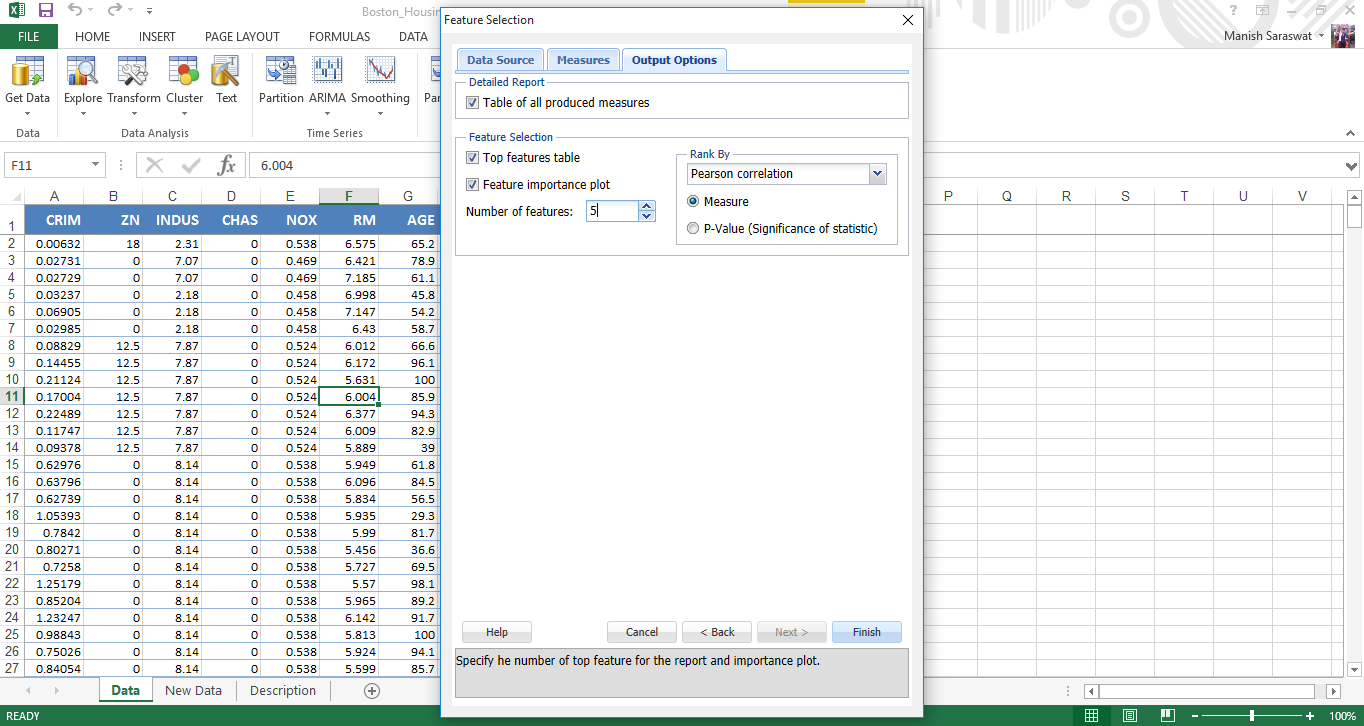
7. Now select the functions. Let's find out the 5 main important predictor variables. Click Finish.
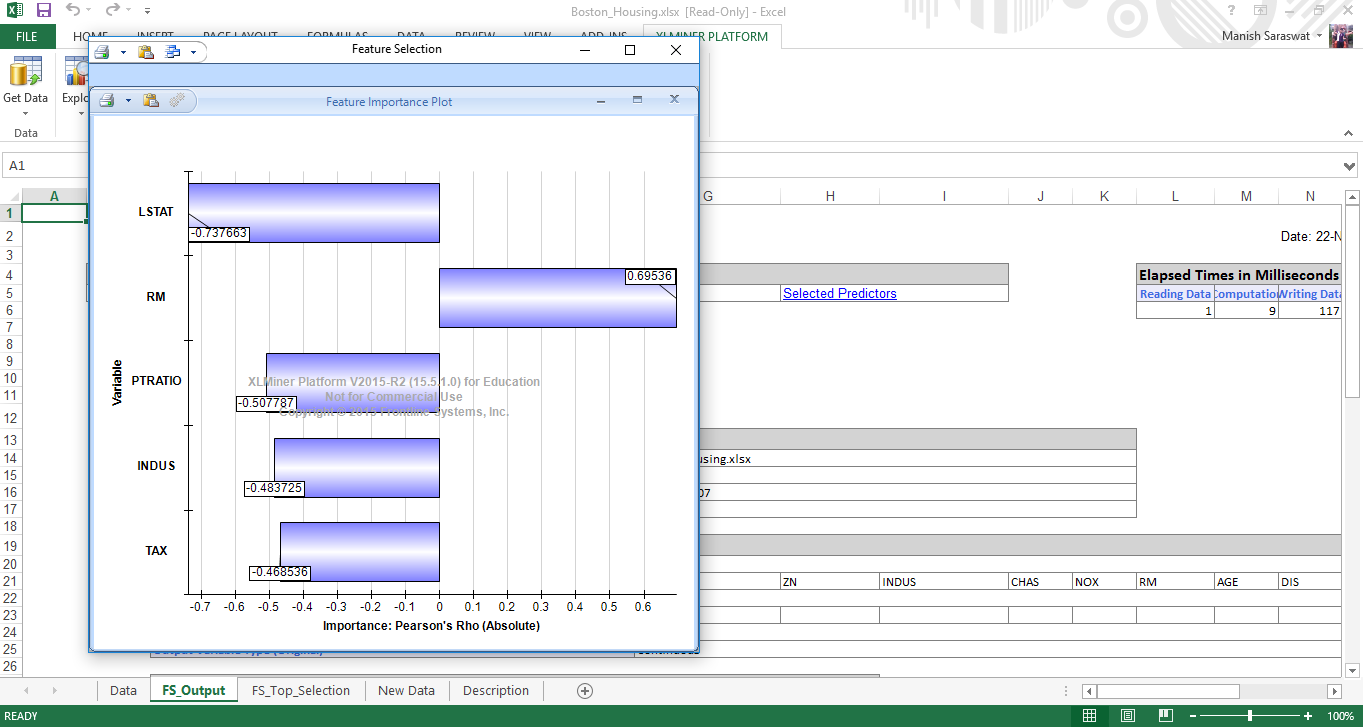
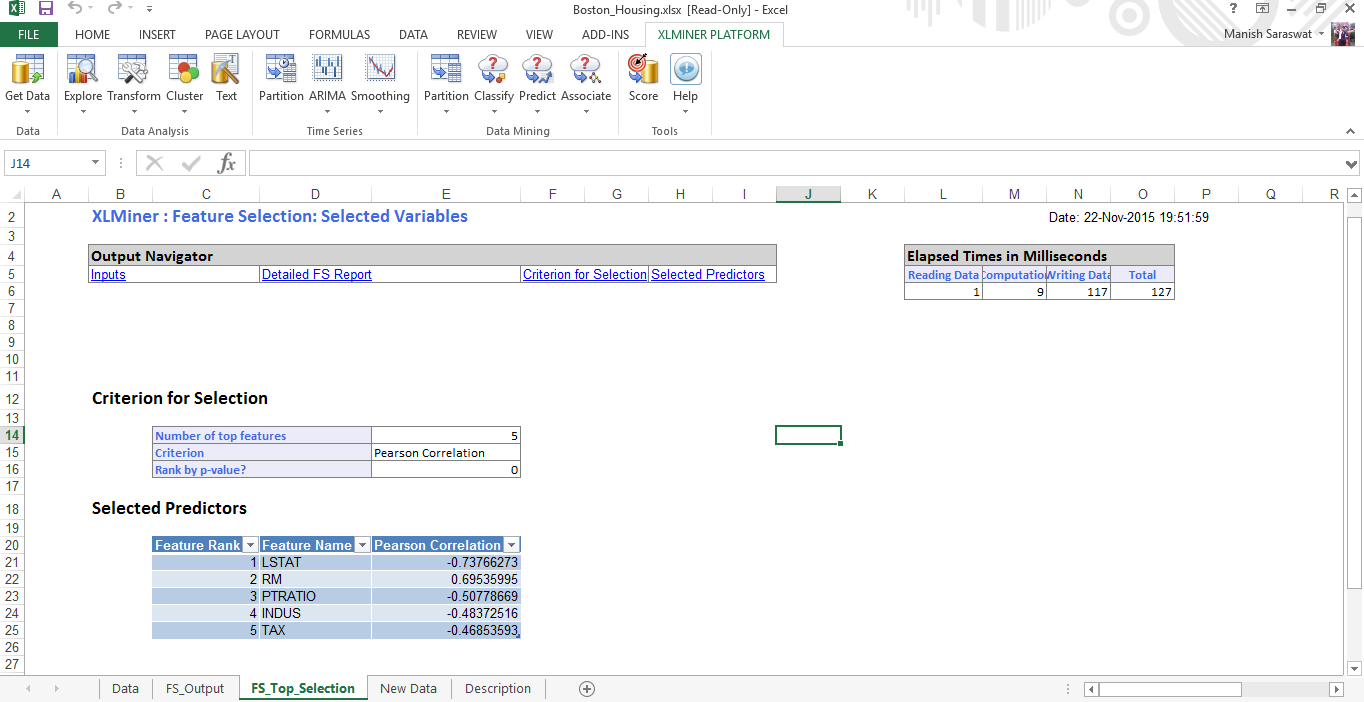
8. Here is the variable importance chart. We see, LSTAT is the most important variable, followed by RM, PRACTICE, INDUS e TAX.
9. Close this graph. Verá Output Navigator. This helps you navigate between multiple output sheets. Let's take a look at the 'selected predictors'.
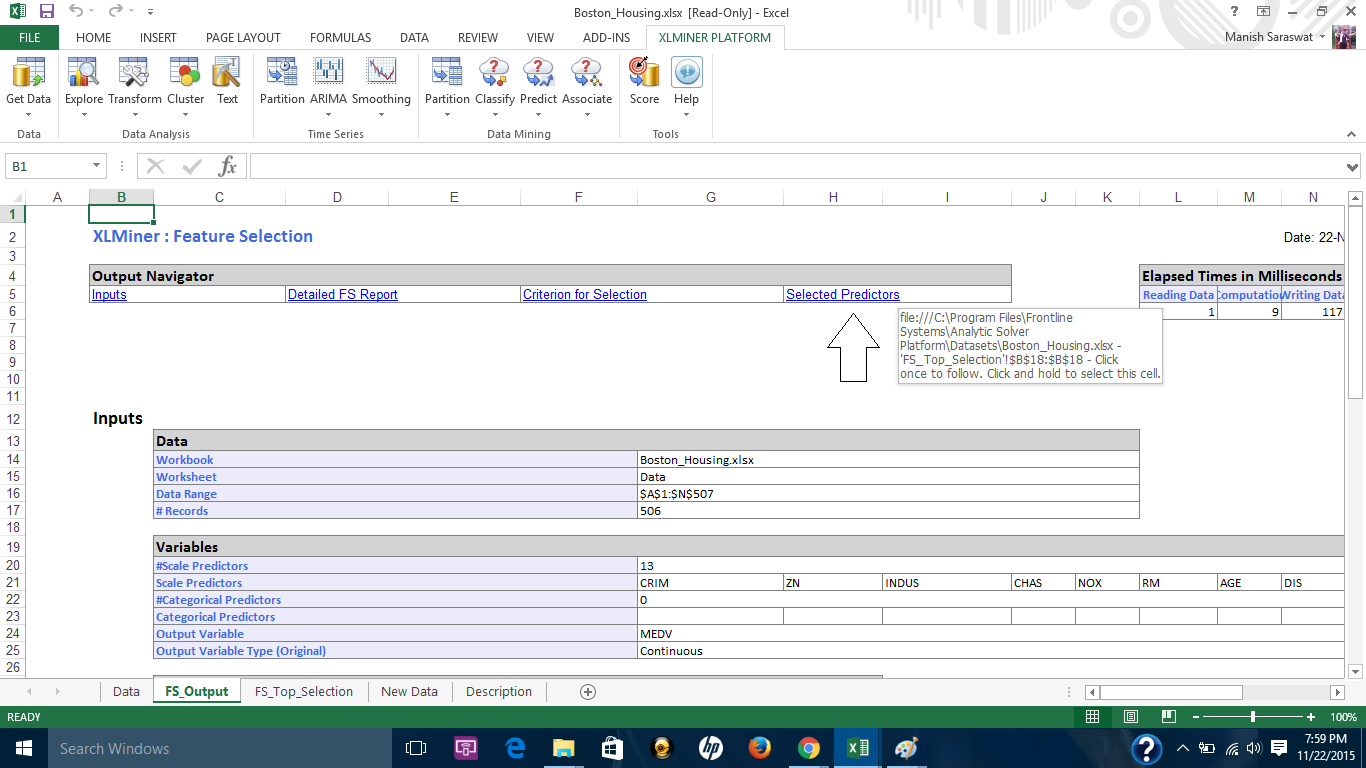
10. Here are the selected predictors. Let's proceed to build a regression model using these variables.
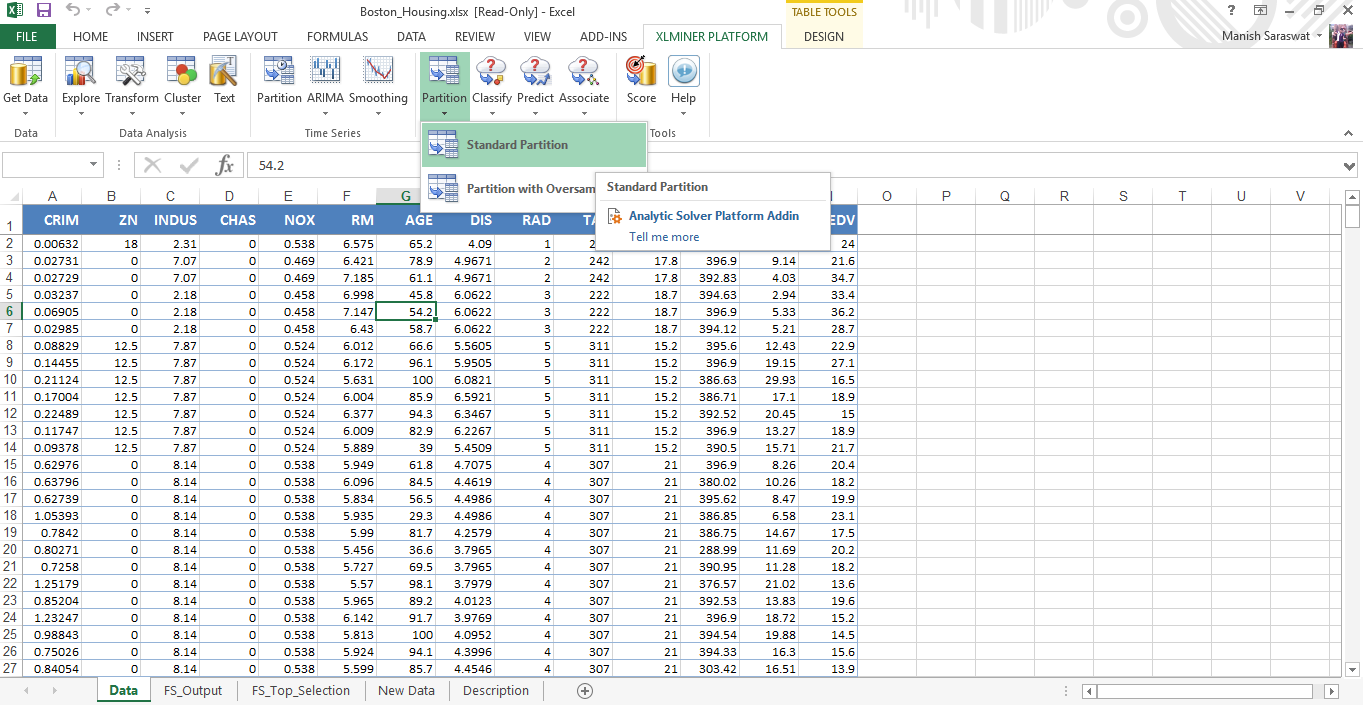
11. before modeling, divide (let's partition) these data in train and validation.
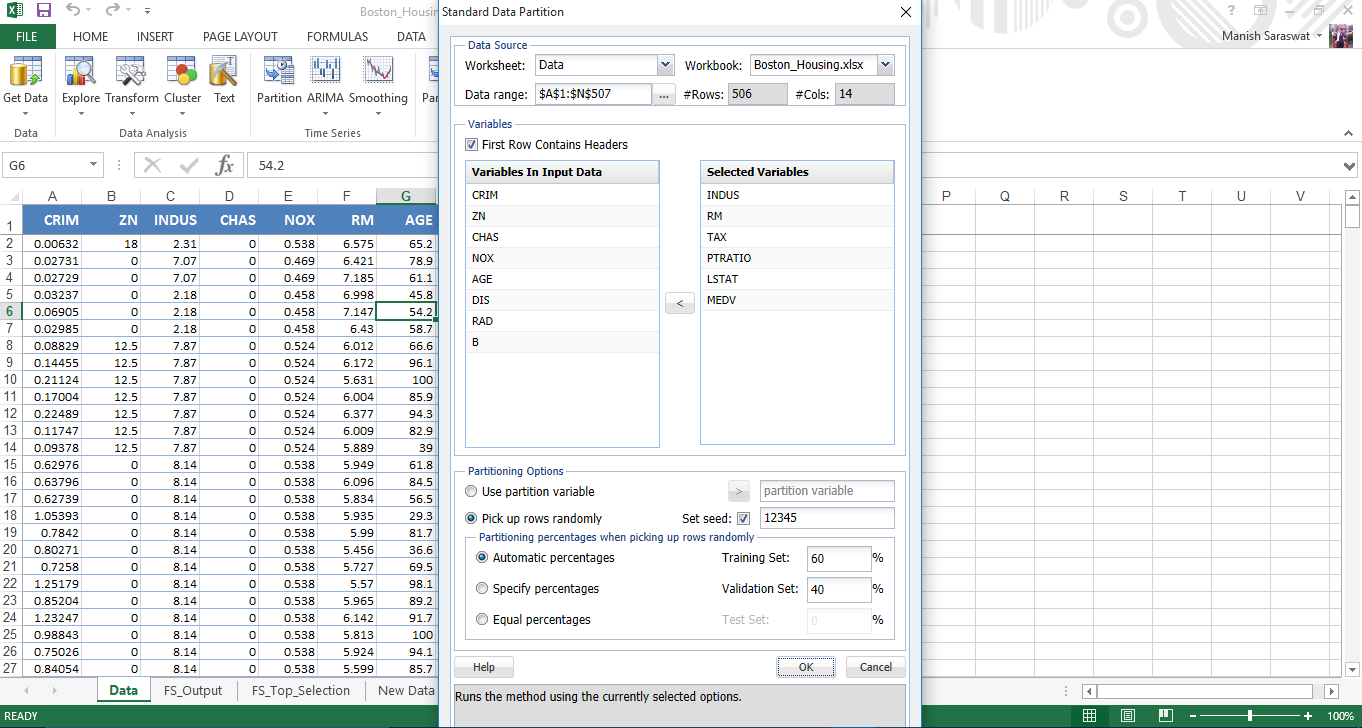
12. Based on the selection of characteristics, select the variables to include in the partition. Leave the rest as defaults and click OK.
13. And here we have the dataset of trainingTraining is a systematic process designed to improve skills, physical knowledge or abilities. It is applied in various areas, like sport, Education and professional development. An effective training program includes goal planning, regular practice and evaluation of progress. Adaptation to individual needs and motivation are key factors in achieving successful and sustainable results in any discipline.... ready for modeling.
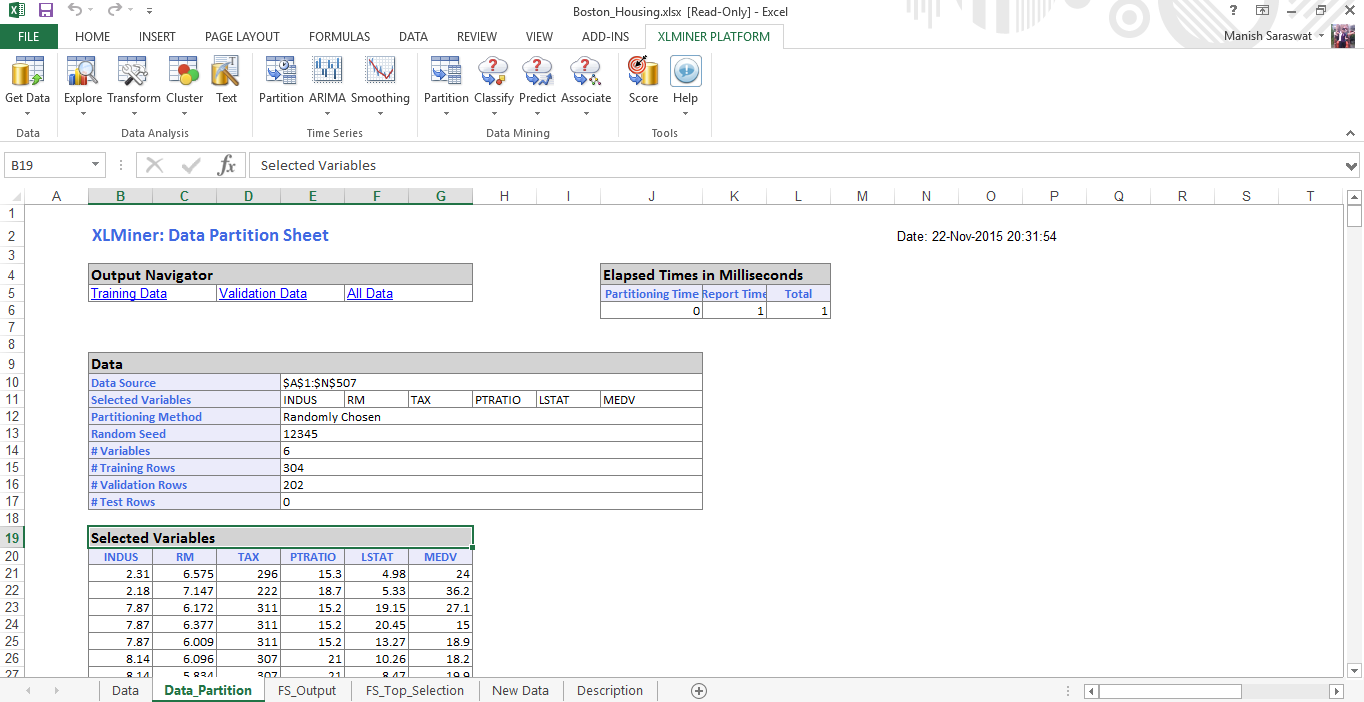
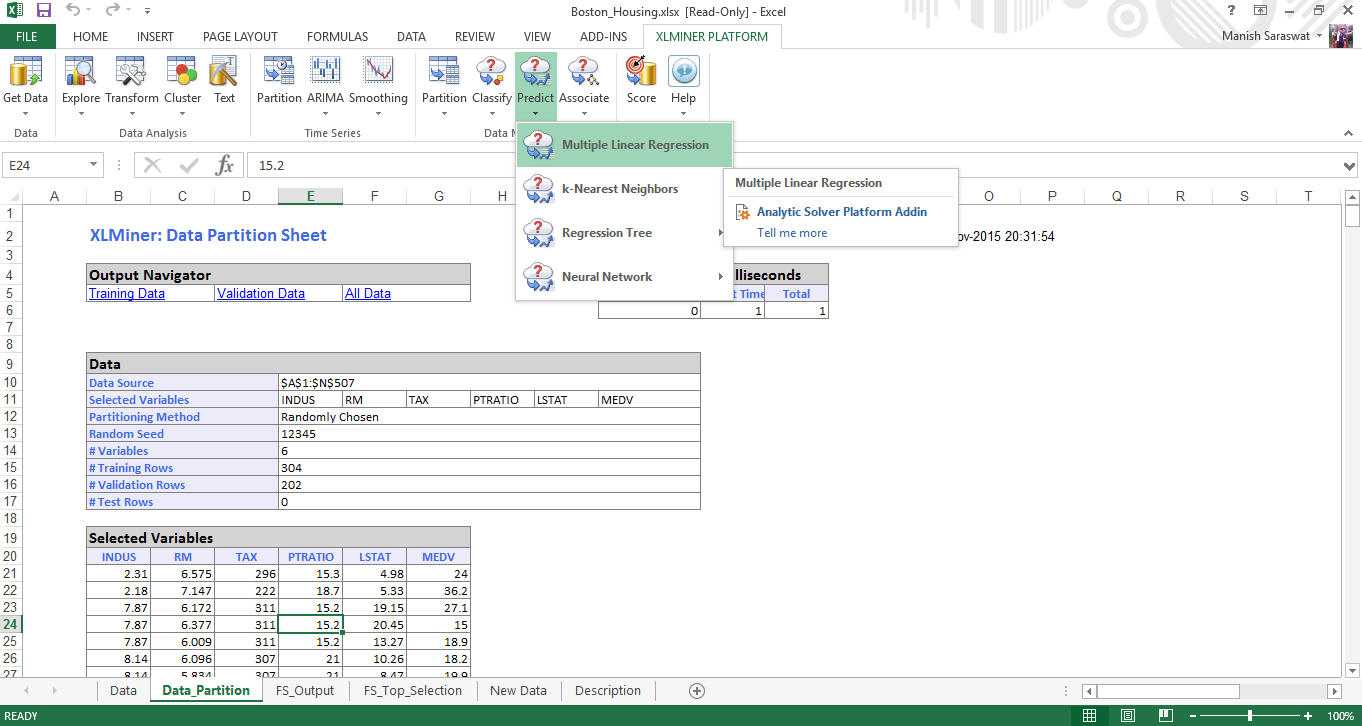
14. Click on any cell under Selected Variables and proceed to build the multiple regression model. Click Multiple Linear Regression
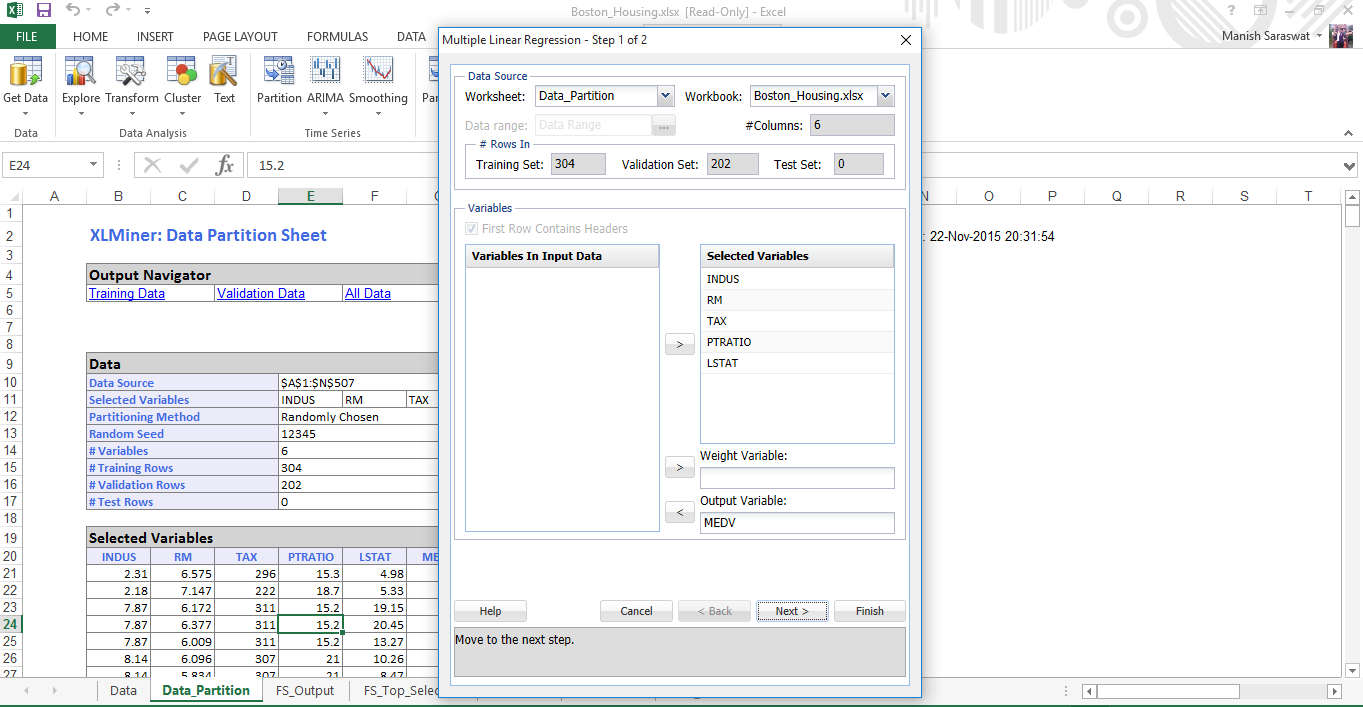
15. Select the set of predictor and response variables. Click Next
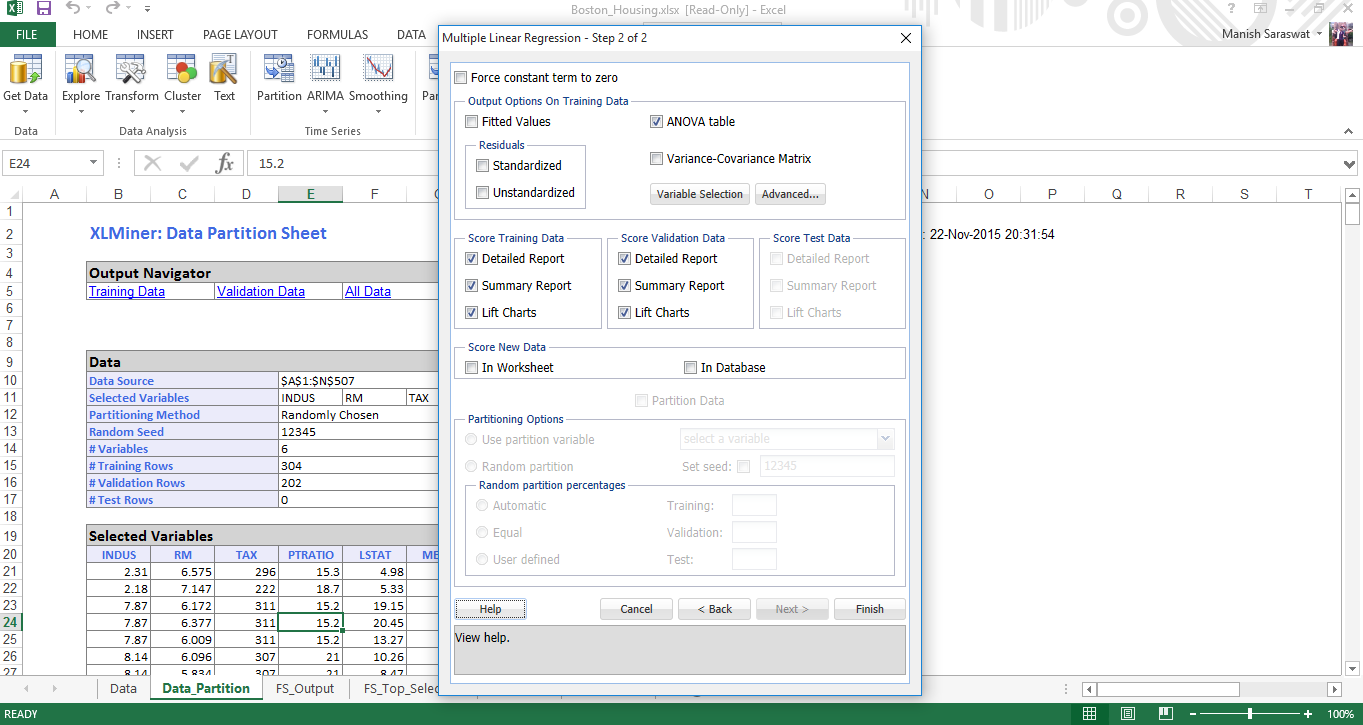
16. Select your required metrics. Click Finish
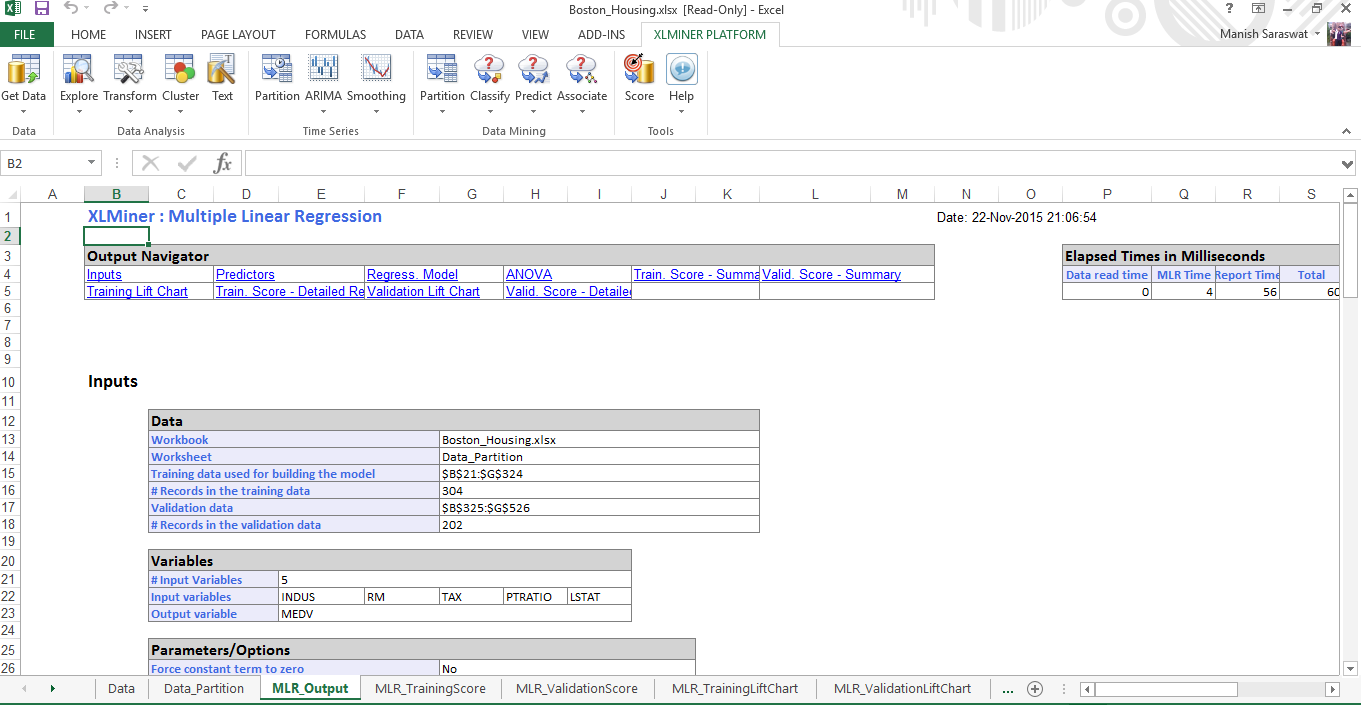
17. Your Multiple Linear Regression Model is Ready. Use the output browser to access different metrics and model precision.
Tutorial: Logistic regression
Logistic regression is a classic example of a classification algorithm. Similar to multiple linear regression, Below are the steps to build a logistic regression model. If you want to quickly update your logistic regression concepts, you can check this tutorial: Simple logistic regression guide
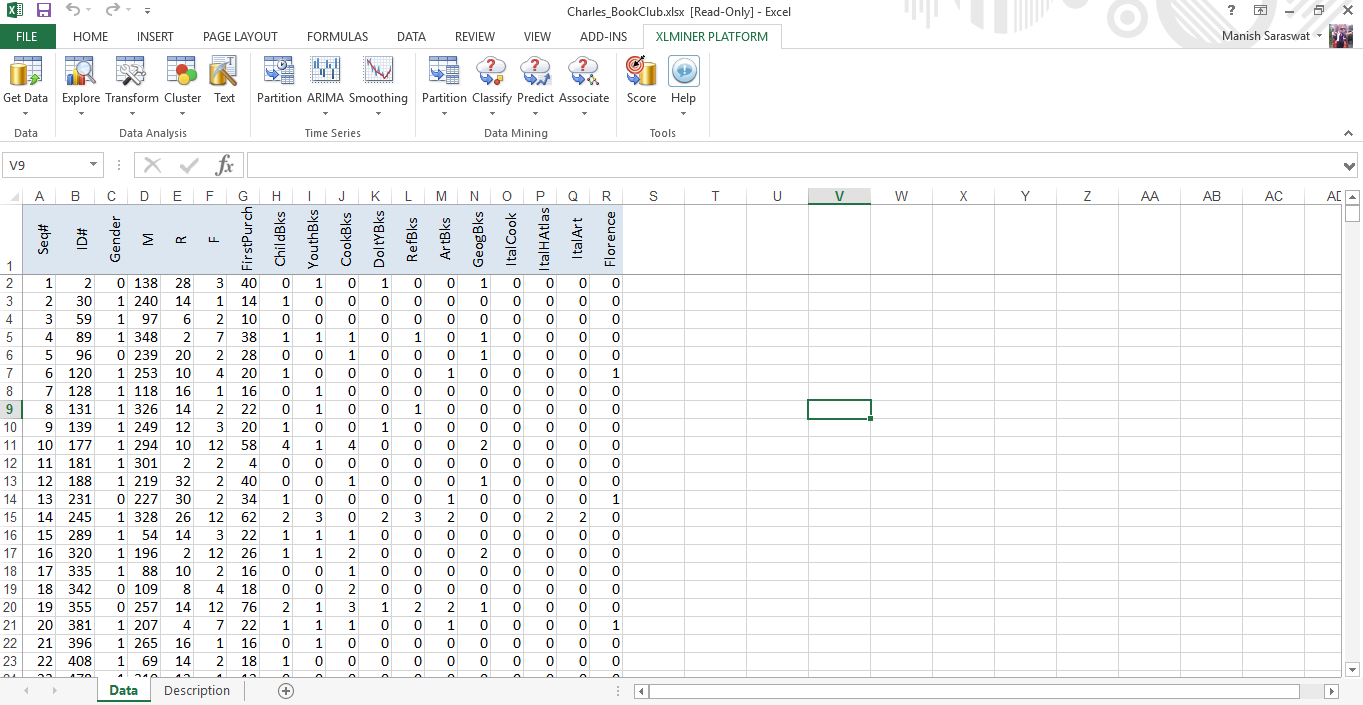
1. Load the dataset ‘Charles_bookclub’. An XLMiner Ribbon, click Help -> Example. Select this dataset. This data set represents information associated with people who are members of a book club. We will build a model to predict if a person will buy a book about the city of Florence based on previous purchases.
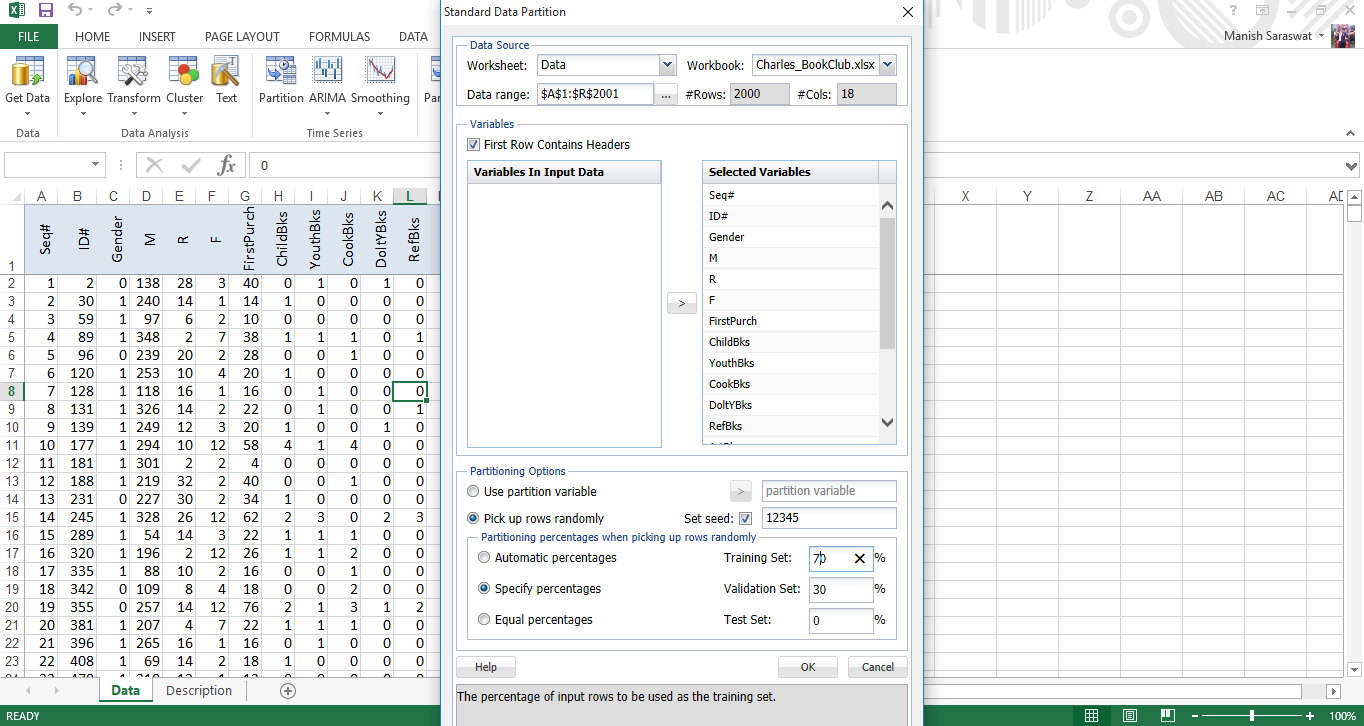
2. Now, we will divide the data set in training (70%) and validation (30%). This time you need to specify percentages for the partition. Click ok
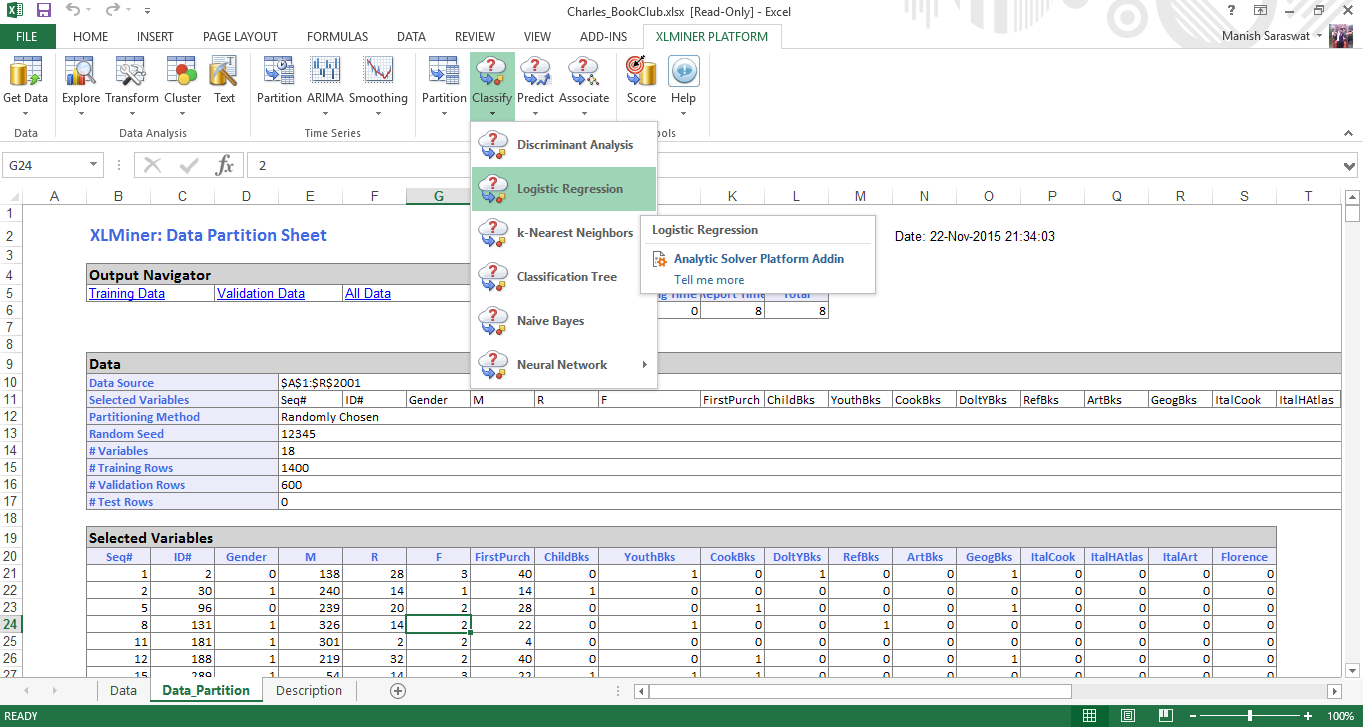
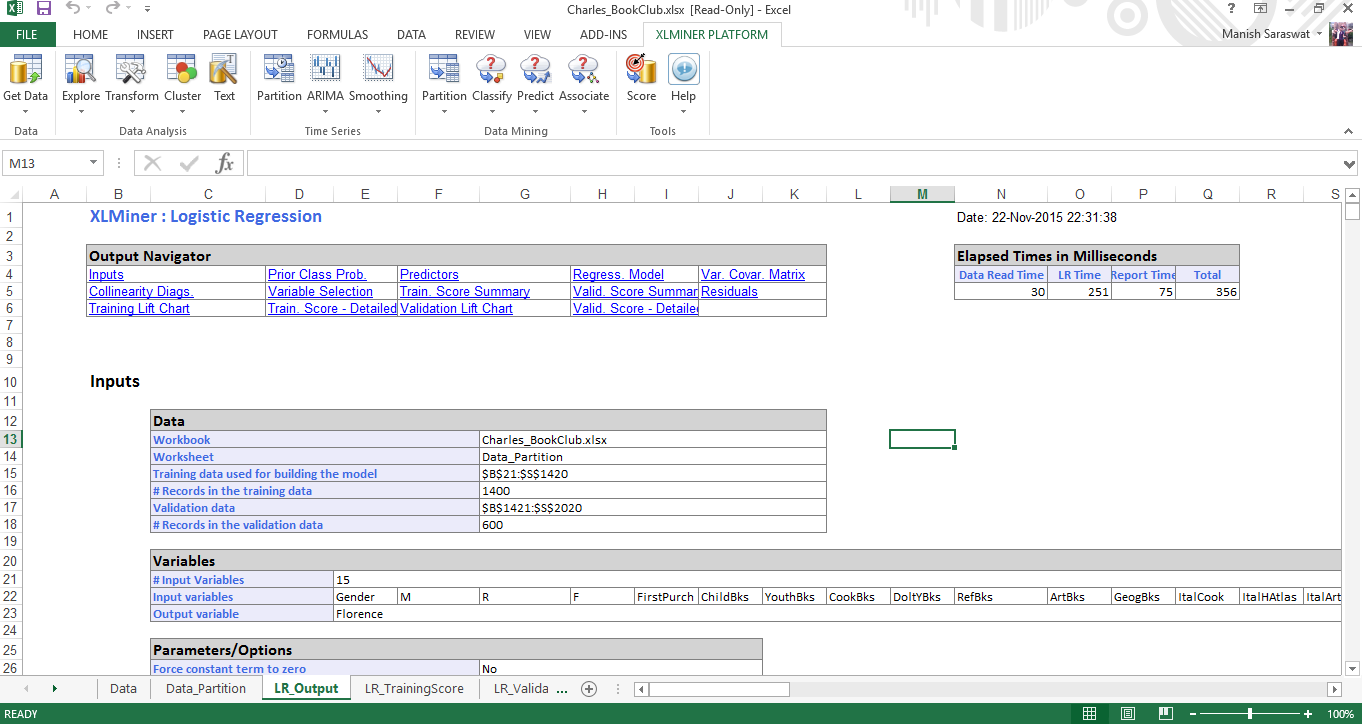
3. You will see a data partition sheet. Click on any cell in the 'selected variables table’ and click logistic regression as shown.
4. Here select the input and output variables. Florence is the output variable where you get 1 when a customer bought a book about the city of Florence and 0 otherwise. Here 1 is success. 0 it is an error as indicated in the following option. Leave the rest as defaults. Click Next
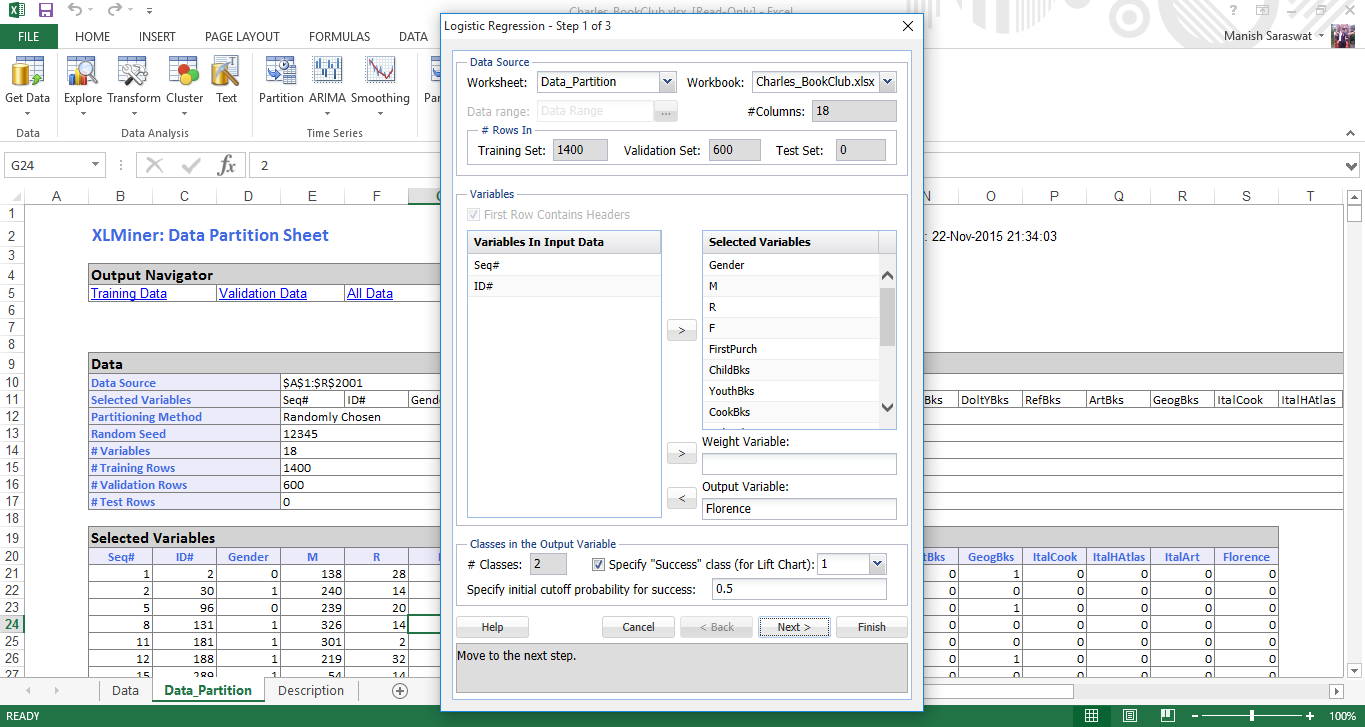
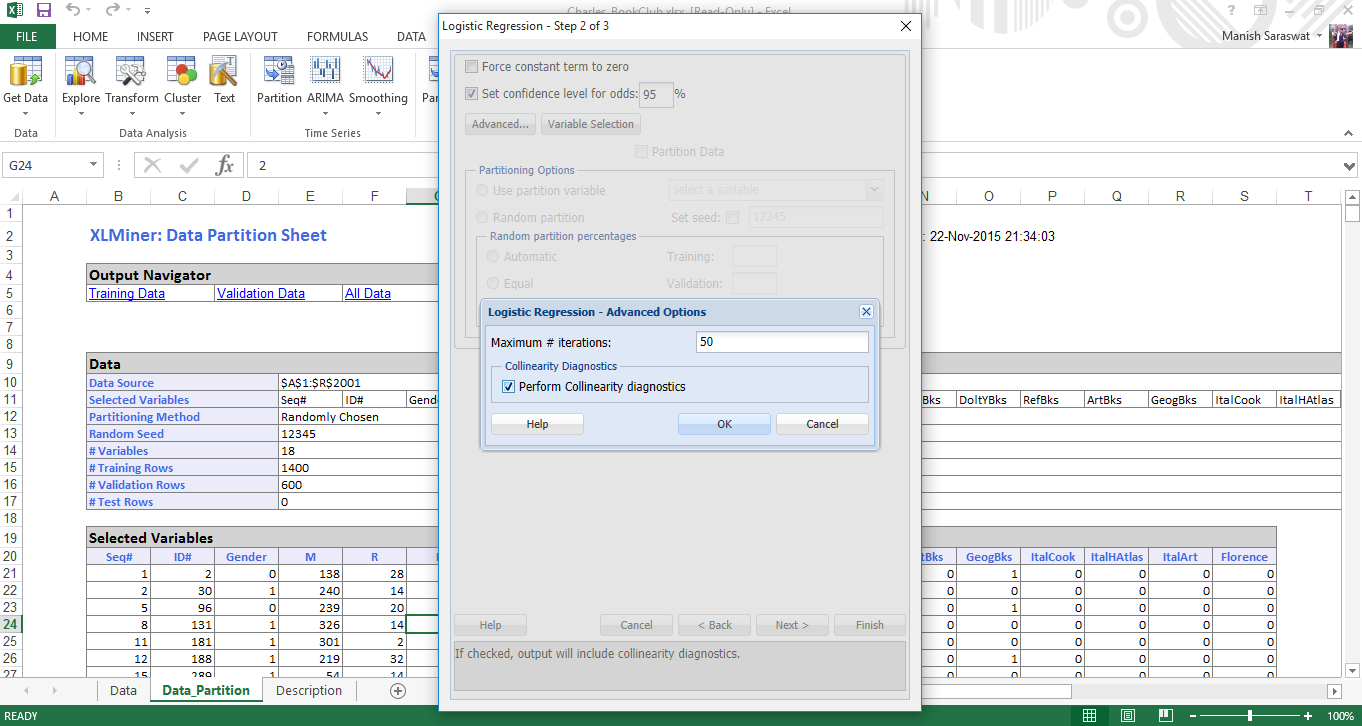
5. Select the confidence interval as 95%. If you check ‘Force constant term to zero’, will skip the constant term in the regression. Therefore, don't select it. Click on advanced and check ‘perform collinearity diagnostics’. Will display useful information when dealing with correlated variables that have large standard errors. Click ok. Now, click Variable Selection.
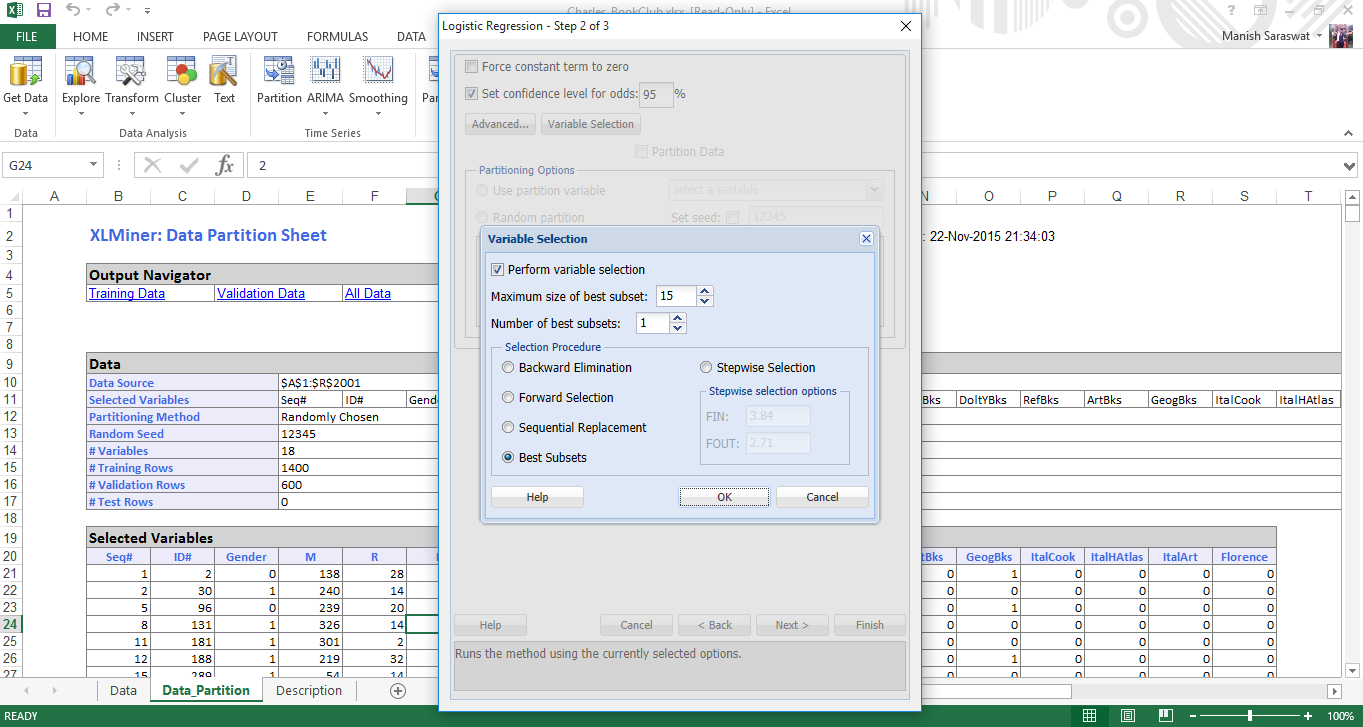
6. Variable selection helps us deal with a large number of predictor variables and find the best one among them.. ‘Maximum size of the best subset’ takes a value of 1 a N, where N is the number of input variables. We will not change this value. In the selection procedure, you can choose any according to your preferences. Choose ‘Best subsets’ because it searches all combinations of variables and selects only the ones that best fit. Click ok. Click Next.
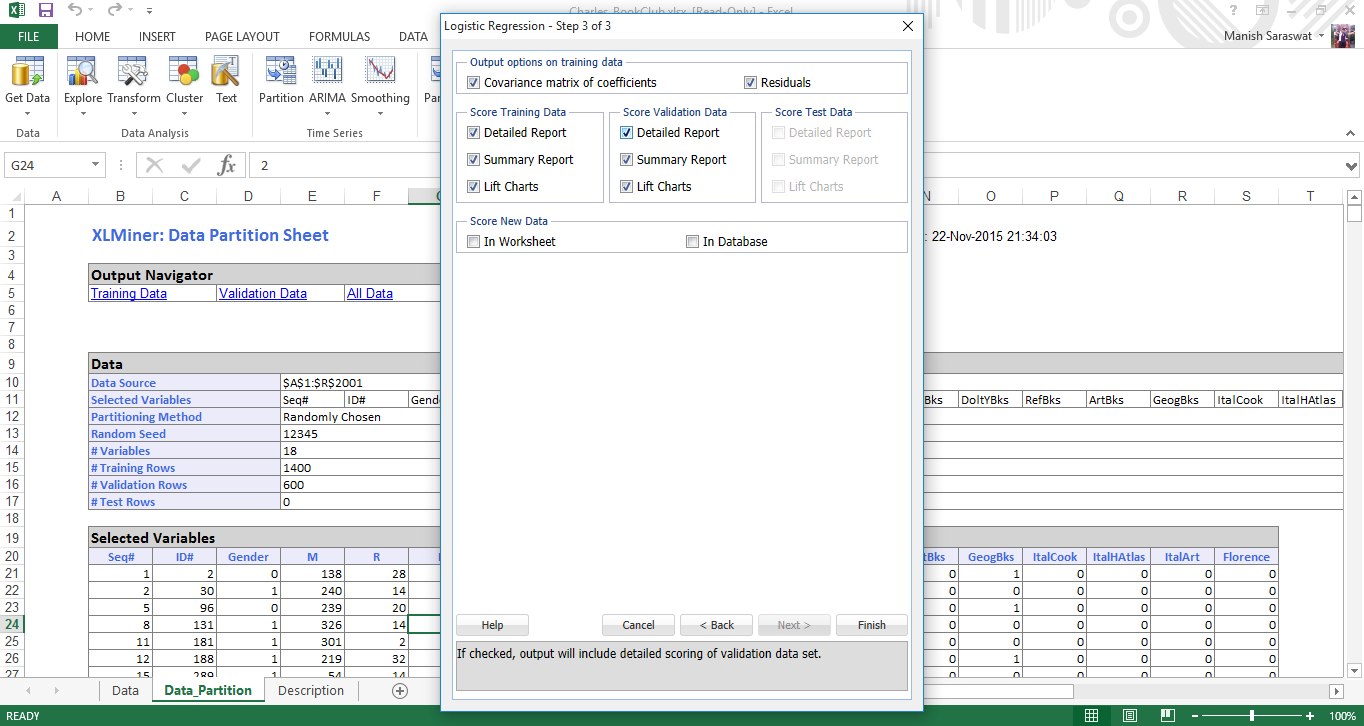
7. Now we will select the calculation coefficients necessary to evaluate the model. Select Covariance matrix of coefficients and residuals. The residuals will produce a table of fitted values and their residuals in the output. Click Finish.
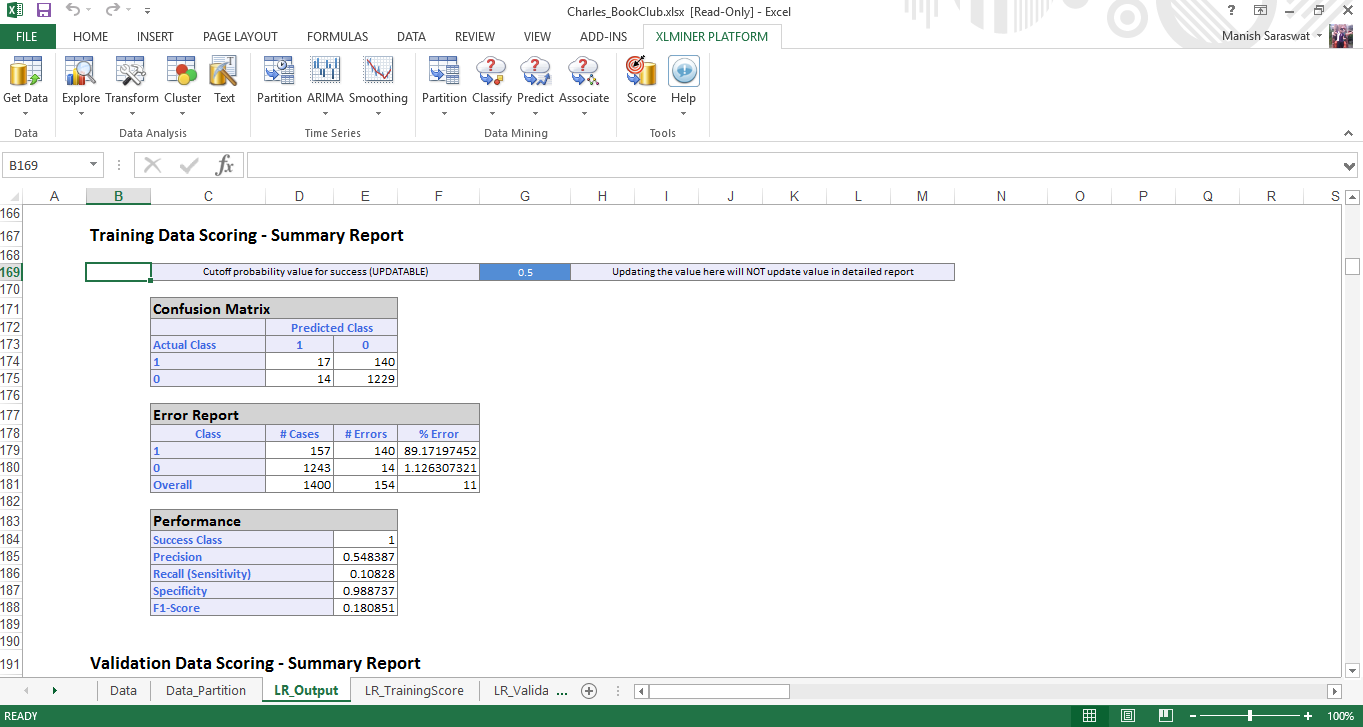
8. Here is your logistic regression model. If you scroll down this sheet, you will find several useful metrics to evaluate the performance of this model. A commonly used metric to verify the accuracy of the model is the confusion matrix. As it scrolls down, you will find this.
Tutorial: k – Grouping of means
If you are new to clustering, this is a quick refresher on cluster analysis. In simple words, clustering is a technique of grouping variables with similar attributes. This technique is generally used for profiling clients and creating products according to their needs..
Let's look at the steps to perform k-means clustering in XLMiner.
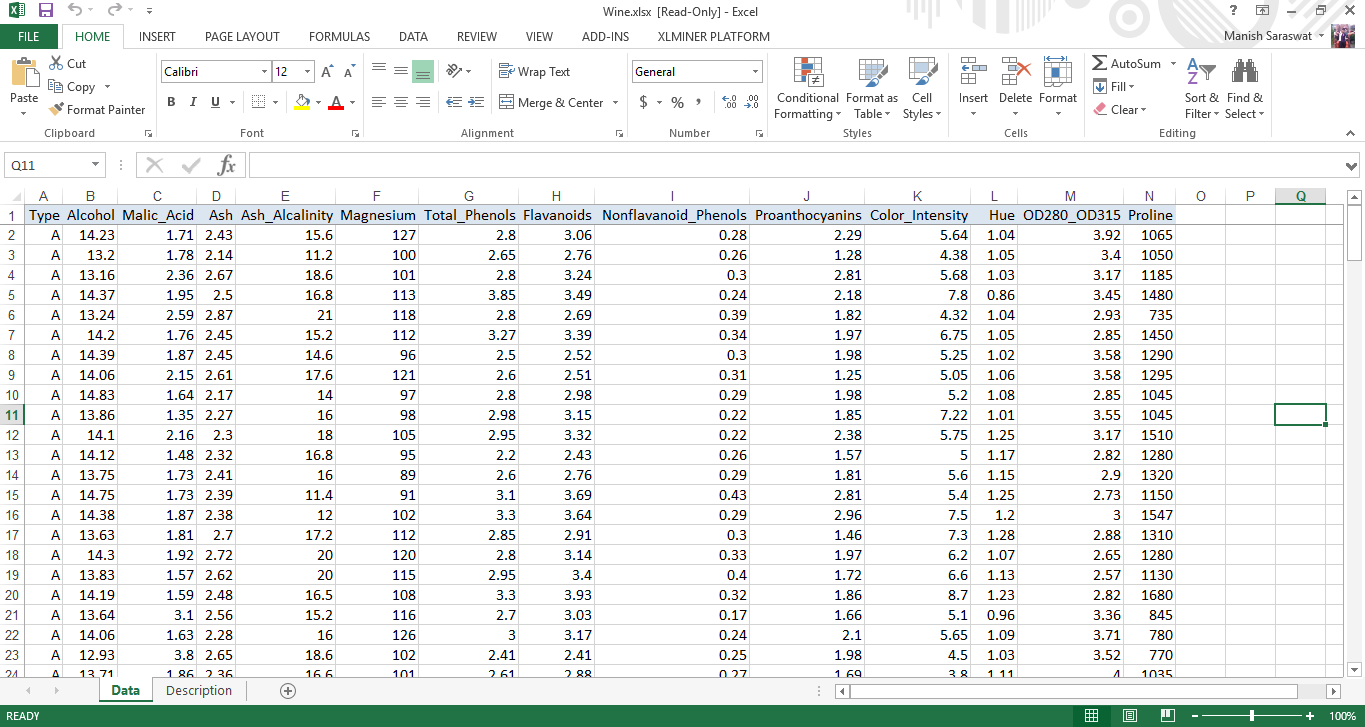
1. Load the Wine dataset. Go to the XLMiner ribbon, click Help -> Examples. Select Wine. In this data set, each row represents a sample of wine that belongs to 3 lessons (A, B y C). Based on these data, we will create a grouping model to determine the class of wine. Here is the data set.
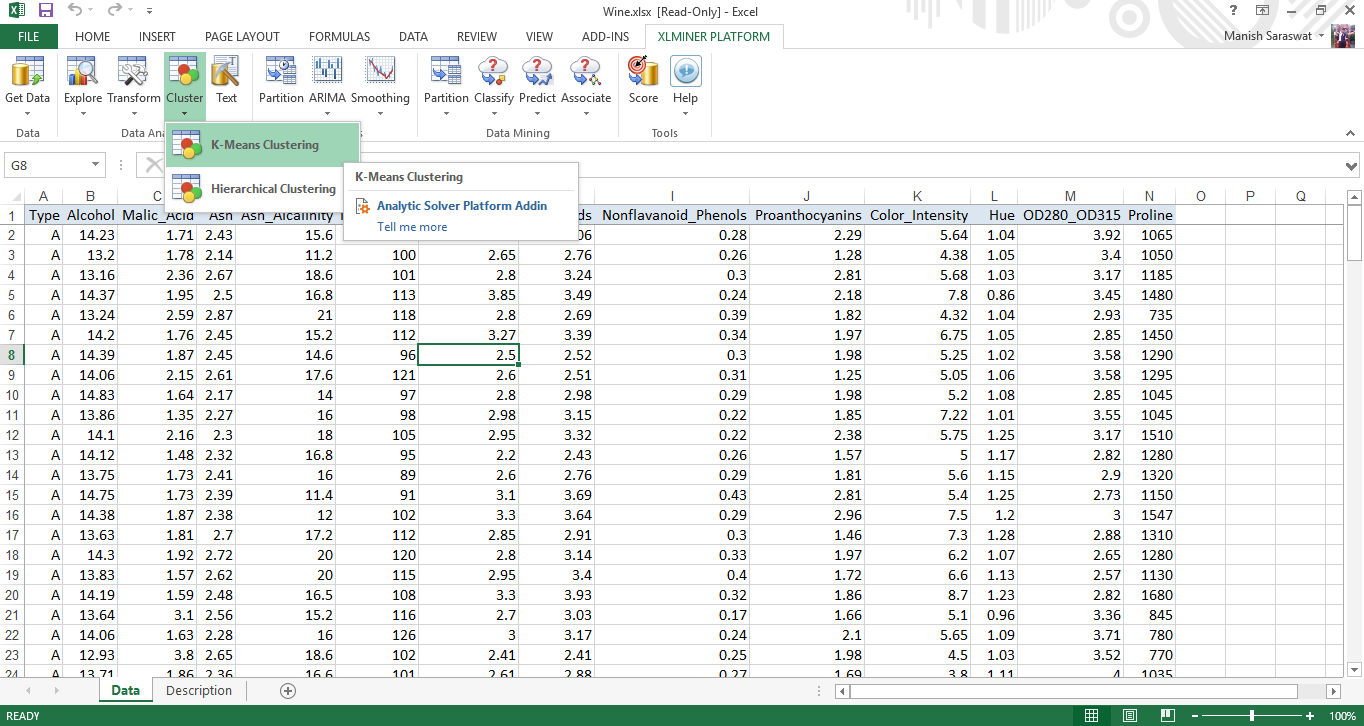
2. Click on any cell in the dataset. Later, click k-means clustering.
3. Type is the output variable. Therefore, we will select all variables except Type to use them in the grouping. Click Next.
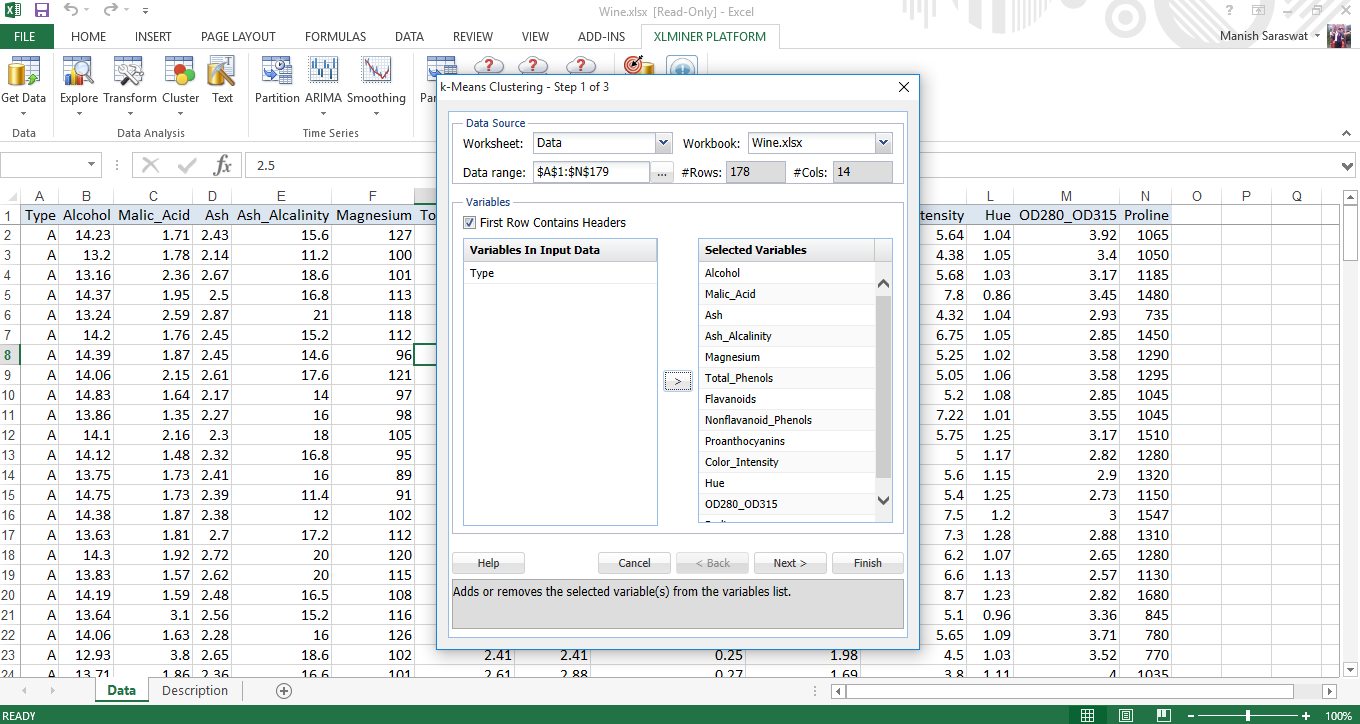
4. Take the number of clusters as 8. Why, with a large number of clusters, the sum of the squared error (SSE) still small. SSE is defined as the sum of the squared distance between each member of the group and its centroid. You can set any value of k and evaluate the output of each to check which is the best. Set a random value to say 5, will allow this algorithm to build the model from any random point. With this, XLMiner will generate 5 cluster sets and will generate the result of the best clusterA cluster is a set of interconnected companies and organizations that operate in the same sector or geographical area, and that collaborate to improve their competitiveness. These groupings allow for the sharing of resources, Knowledge and technologies, fostering innovation and economic growth. Clusters can span a variety of industries, from technology to agriculture, and are fundamental for regional development and job creation..... Leave the defaults to rest and click Next.
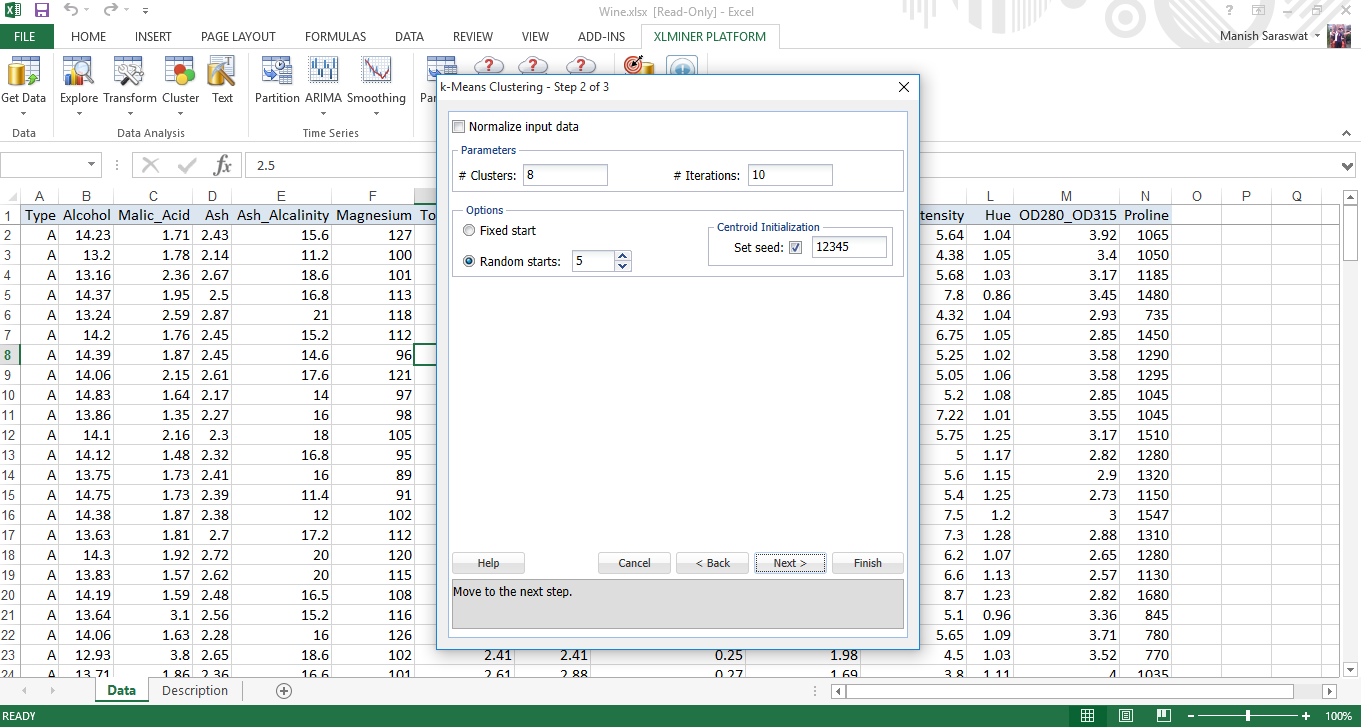
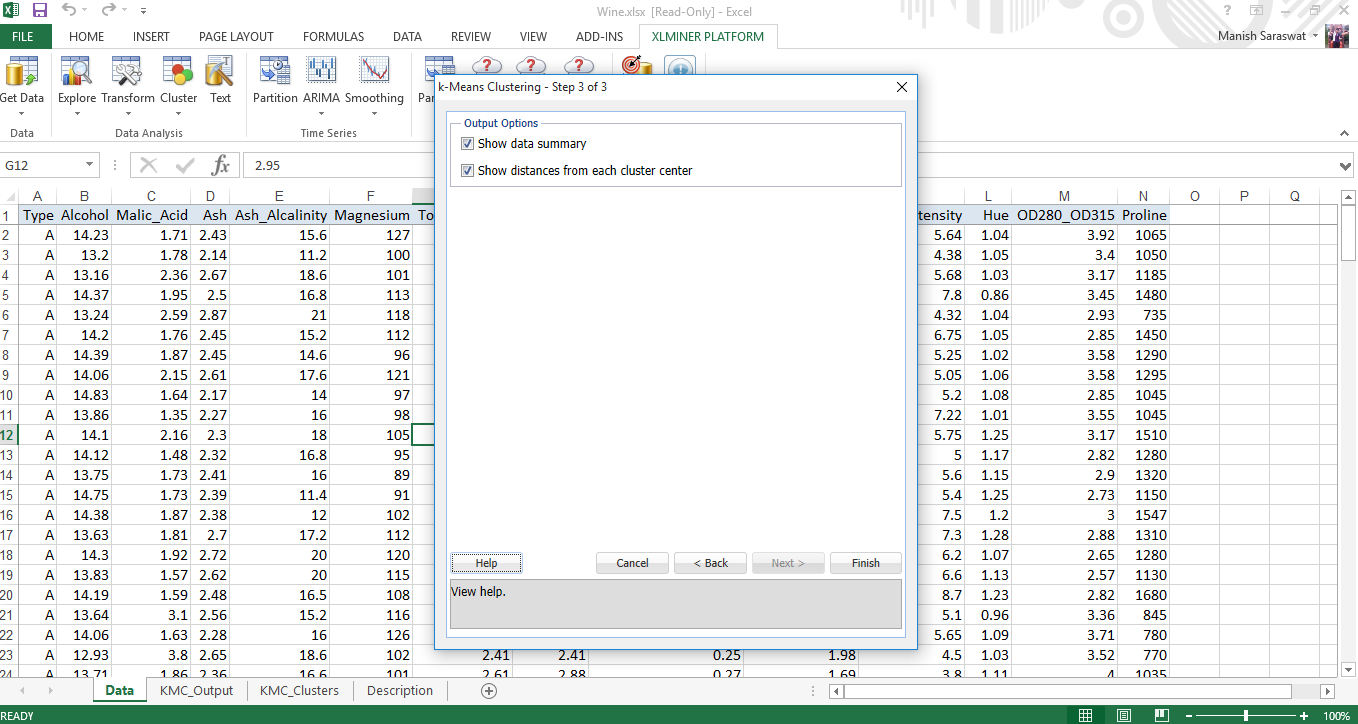
5. Leave the default values. Click Finish
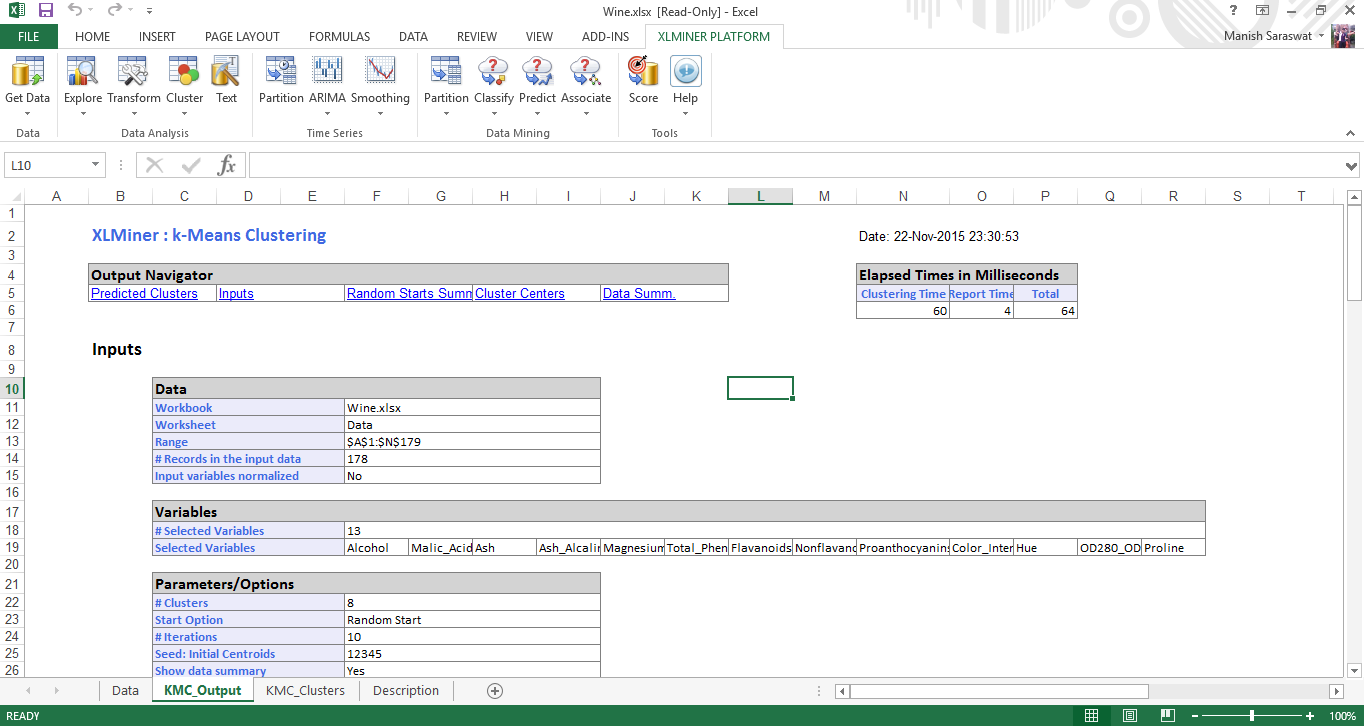
6. Here is your grouping model. Check out our various evaluation metrics to determine the accuracy of this model.
Random starts summary: This table determines the best start with the lowest sum of squares distance. In this case (# 1) is the best start. Once the best start is determined, the remaining output of the model is generated using the best start as the starting point.
Cluster centers: Here you will find two boxes. The bottom box shows the distance between the centroid of the clusters. The greater the distance, different will be the nature of the groups. For instance, the difference between the group 4 and the group 8 it is 1176,59. This suggests that these groups are very different. The upper table shows the values of the variables in the centers of the clusters.
Data summary: Represents the average distance of observations from the center of a group. We can infer that the cluster 2 has the lowest average distance from its centroid and the cluster 6 has the highest.
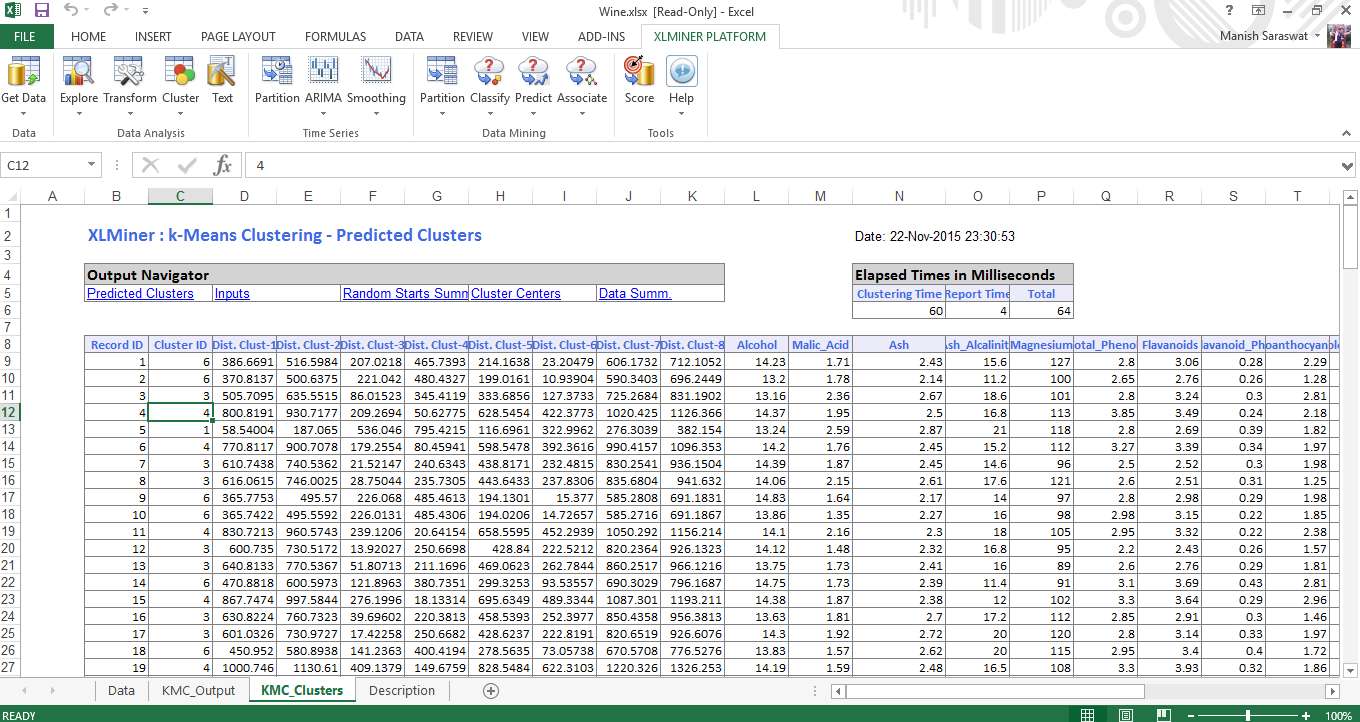
7. Click on the KMC_Clusters sheet. Here you will find the predicted groups. Check the registration ID 1. Has qualified in the group 6. Because the distance of this observation is minimal to the group 6. Similarly, all other observations have been ranked on the basis of their closest group.
Final notes
I wrote this tutorial just to get started with machine learning in Excel. Once you understand these algorithms, you can easily use them in R, Python or any other programming language. Since many of us have worked in Excel at some point, it would not be difficult to understand these concepts in Excel. If you get stuck, you can check the help option in XLMiner Ribbon. Documentation is helpful and easy to understand.
Now that you know the steps, I suggest you take time to interpret the model and repeat it to get the best fit. Excel can slow down with large data sets, so you should work with small data sets to save time learning.
Did you find this article useful? Have you ever worked on XLMiner? I'd love to hear your experiences and suggestions in the comment section below..





