
This post was made public as part of the Data Science Blogathon
Introduction
Natural language processing (PNL) is a field in which artificial intelligence and linguistics converge. The goal is to make computers understand real-world language or natural language so that they can perform tasks in response to questions., language translation and many more.
NLP has many applications in different fields.
1. NLP enables the accreditation and prognosis of diseases based on electronic medical records.
2. Used to get customer feedback.
3. To help identify fake news.
4. Chatbots.
5. Social media monitoring, etc.
What is transformer?
The architecture of the Transformer model was presented by Ashish Vaswani, Noam shazeer, Niki Parmar, Jakob Rękoreit, Llion Jones, Aidan N. Gomez, Lukasz Kaiser e Illia Polosukhin en su post “Attention Is All You Need”. [1]
The Transformer model extracts the characteristics of each word using a self-attention mechanism to know the relevance of each word in the sentence. No other recurring units are used to extract this feature, they are just activations and weighted sums, so they can be very efficient and parallelizable.
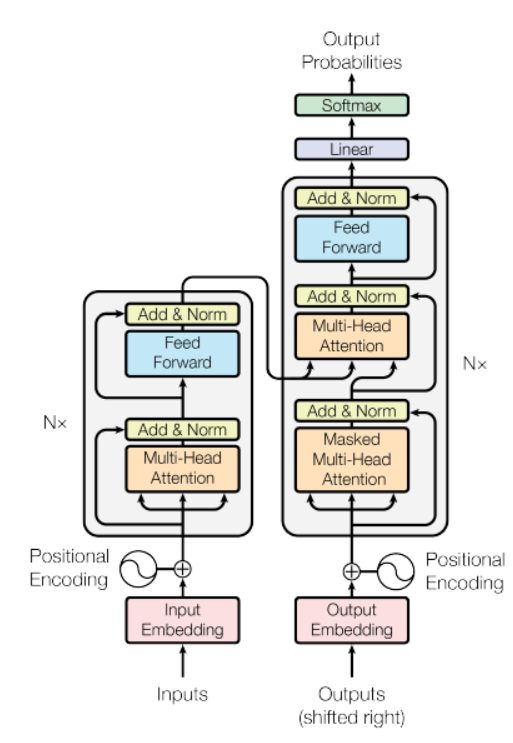
Source: document “Attention is all you need”
In the figure"Figure" is a term that is used in various contexts, From art to anatomy. In the artistic field, refers to the representation of human or animal forms in sculptures and paintings. In anatomy, designates the shape and structure of the body. What's more, in mathematics, "figure" it is related to geometric shapes. Its versatility makes it a fundamental concept in multiple disciplines.... anterior, there is an encoder model on the left side and the decoder on the right. Both the encoder and decoder contain a central block of attention and a feedback network repeated N number of times.
In the figure above, there is an encoder model on the left side and the decoder on the right. Both the encoder and the decoder contain a central attention block and a feedback network repeated N number of times.
It has a stack of 6 encoders and 6 decoders, the encoder contains two layers (sublayers), In other words, a multi-head self-care layer and a fully connected forward feed network. The decoder contains three layers (sublayers), a multi-head self-care layer, another multi-head self-care layer to realize self-care on the encoder outputs and a fully connected forward feed network. Cada subcapa en Decoder y Encoder dispone de una conexión residual con standardizationStandardization is a fundamental process in various disciplines, which seeks to establish uniform standards and criteria to improve quality and efficiency. In contexts such as engineering, Education and administration, Standardization makes comparison easier, interoperability and mutual understanding. When implementing standards, cohesion is promoted and resources are optimised, which contributes to sustainable development and the continuous improvement of processes.... de capa.
Let's start building a language translation model
Here we will use the Multi30k dataset. Do not worry, the dataset will be downloaded with a code snippet.
First, the data processing part we will use the Torch PyTorch module. the Torch has utilities to create data sets that can be easily iterated in order to create a language translation model. The following code will download the dataset and also tokenize a raw text, construirá el vocabulario y convertirá tokens en un tensorTensors are mathematical structures that generalize concepts such as scalars and vectors. They are used in various disciplines, including physics, Engineering and Machine Learning, to represent multidimensional data. A tensor can be visualized as a multi-dimensional matrix, which allows complex relationships between different variables to be modeled. Their versatility and ability to handle large volumes of information make them fundamental tools in data analysis and processing.....
import math
import torchtext
import torch
import torch.nn as nn
from torchtext.data.utils import get_tokenizer
from collections import Counter
from torchtext.vocab import Vocab
from torchtext.utils import download_from_url, extract_archive
from torch.nn.utils.rnn import pad_sequence
from torch.utils.data import DataLoader
from torch import Tensor
from torch.nn import (TransformEncode, TransformerDecoder,TransformerEncoderLayer, TransformerDecoderLayer)
import io
import time
url_base ="https://raw.githubusercontent.com/multi30k/dataset/master/data/task1/raw/"
train_urls = ('train.de.gz', 'train.en.gz')
val_urls = ('val.de.gz', 'val.en.gz')
test_urls = ('test_2016_flickr.de.gz', 'test_2016_flickr.en.gz')

train_filepaths = [extract_archive(download_from_url(url_base + url))[0] for url address in train_urls]
val_filepaths = [extract_archive(download_from_url(url_base + url))[0] for url address in val_urls]
test_filepaths = [extract_archive(download_from_url(url_base + url))[0] for url address in test_urls]

de_tokenizer = get_tokenizer('spacy', language="de_core_news_sm")
en_tokenizer = get_tokenizer('spacy', language="en_core_web_sm")

def build_vocab(filepath, tokenizer):
counter = Counter()
with io.open(filepath, encoding="utf8") as f:
for string_ in f:
counter.update(tokenizer(string_))
return Vocab(counter, specials=['<unk>', '<pad>', '<bunch>', '<eos>'])

de_vocab = build_vocab(train_filepaths[0], de_tokenizer)
en_vocab = build_vocab(train_filepaths[1], en_tokenizer)

def data_process(filepaths):
raw_de_iter = iter(io.open(filepaths[0], encoding="utf8"))
raw_en_iter = iter(io.open(filepaths[1], encoding="utf8"))
data = []
for (raw_de, raw_en) in zip(raw_de_iter, raw_en_iter):
de_tensor_ = torch.tensor([de_vocab[token] for token in de_tokenizer(raw_de.rstrip("n"))],
dtype=torch.long)
en_tensor_ = torch.tensor([en_vocab[token] for token in en_tokenizer(raw_en.rstrip("n"))],
dtype=torch.long)
data.append((de_tensor_, en_tensor_))
return data


train_data = data_process(train_filepaths)
val_data = data_process(val_filepaths)
test_data = data_process(test_filepaths)
device = torch.device('cuda' if torch.cuda.is_available() else 'cpu')


BATCH_SIZE = 128
PAD_IDX = de_vocab['<pad>']
BOS_IDX = de_vocab['<bunch>']
EOS_IDX = de_vocab['<eos>']
Then we will use the PyTorch DataLoader module that combines a data set and a sampler, and enables us to iterate over the given data set. The DataLoader supports iterable and map style data sets with single or multithreaded procedure loading, we can also customize the load order and memory fixation.
# DataLoader
def generate_batch(data_batch):
  de_batch, en_batch = [], []
  for (de_item, en_item) in data_batch:
    de_batch.append(torch.cat([torch.tensor([BOS_IDX]), de_item, torch.tensor([EOS_IDX])], dim=0))
    en_batch.append(torch.cat([torch.tensor([BOS_IDX]), en_item, torch.tensor([EOS_IDX])], dim=0))
  de_batch = pad_sequence(de_batch, padding_value=PAD_IDX)
  en_batch = pad_sequence(en_batch, padding_value=PAD_IDX)
  return de_batch, en_batch
train_iter = DataLoader(train_data, batch_size=BATCH_SIZE,
shuffle=True, collate_fn=generate_batch)
valid_iter = DataLoader(val_data, batch_size=BATCH_SIZE,
shuffle=True, collate_fn=generate_batch)
test_iter = DataLoader(test_data, batch_size=BATCH_SIZE,
shuffle=True, collate_fn=generate_batch)
So we are designing the transformer. Here, the encoder processes the input stream propagating it through a series of feed-forward, multi-head care network layers. The output of this encoder is called memory below and is fed to the decoder along with the target tensors. Encoder and decoder are trained end-to-end.
# transformer
class Seq2SeqTransformer(nn.Module):
    def __init__(self, num_encoder_layers: int, num_decoder_layers: int,
                 emb_size: int, src_vocab_size: int, tgt_vocab_size: int,
                 dim_feedforward:int = 512, dropout:float = 0.1):
        super(Seq2SeqTransformer, self).__init__()
        encoder_layer = TransformerEncoderLayer(d_model=emb_size, nhead=NHEAD,
                                                dim_feedforward=dim_feedforward)
        self.transformer_encoder = TransformerEncoder(encoder_layer, num_layers=num_encoder_layers)
        decoder_layer = TransformerDecoderLayer(d_model=emb_size, nhead=NHEAD,
                                                dim_feedforward=dim_feedforward)
        self.transformer_decoder = TransformerDecoder(decoder_layer, num_layers=num_decoder_layers)
        self.generator = nn.Linear(emb_size, tgt_vocab_size)
        self.src_tok_emb = TokenEmbedding(src_vocab_size, emb_size)
        self.tgt_tok_emb = TokenEmbedding(tgt_vocab_size, emb_size)
        self.positional_encoding = PositionalEncoding(emb_size, dropout=dropout)

    def forward(self, src: Tensor, trg: Tensor, src_mask: Tensor,
                tgt_mask: Tensor, src_padding_mask: Tensor,
                tgt_padding_mask: Tensor, memory_key_padding_mask: Tensor):
        src_emb = self.positional_encoding(self.src_tok_emb(src))
        tgt_emb = self.positional_encoding(self.tgt_tok_emb(trg))
        memory = self.transformer_encoder(src_emb, src_mask, src_padding_mask)
        outs = self.transformer_decoder(tgt_emb, memory, tgt_mask, None,
                                        tgt_padding_mask, memory_key_padding_mask)
        return self.generator(outs)

    def encode(self, src: Tensor, src_mask: Tensor):
        return self.transformer_encoder(self.positional_encoding(
                            self.src_tok_emb(src)), src_mask)

    def decode(self, tgt: Tensor, memory: Tensor, tgt_mask: Tensor):
        return self.transformer_decoder(self.positional_encoding(
                          self.tgt_tok_emb(tgt)), memory,
                          tgt_mask)
Text that is converted to tokens is rendered through token embeds. The positional encoding function is added to the token embedding so that we can get the notions of word order.
class PositionalEncoding(nn.Module):
    def __init__(self, emb_size: int, dropout, maxlen: int = 5000):
        super(PositionalEncoding, self).__init__()
        den = torch.exp(- torch.arange(0, emb_size, 2) * math.log(10000) / emb_size)
        pos = torch.arange(0, maxlen).reshape(maxlen, 1)
        pos_embedding = torch.zeros((maxlen, emb_size))
        pos_embedding[:, 0::2] = torch.sin(pos * the)
        pos_embedding[:, 1::2] = torch.cos(pos * the)
        pos_embedding = pos_embedding.unsqueeze(-2)
        self.dropout = nn.Dropout(dropout)
        self.register_buffer('pos_embedding', pos_embedding)

    def forward(self, token_embedding: Tensor):
        return self.dropout(token_embedding +
                            self.pos_embedding[:token_embedding.size(0),:])

class TokenEmbedding(nn.Module):
    def __init__(self, vocab_size: int, emb_size):
        super(TokenEmbedding, self).__init__()
        self.embedding = nn.Embedding(vocab_size, emb_size)
        self.emb_size = emb_size
    def forward(self, tokens: Tensor):
        return self.embedding(tokens.long()) * math.sqrt(self.emb_size)
Here, in the following code, a trailing word mask is created to prevent a target word from paying attention to its trailing words. Here the masks are also created, to mask source and destination padding tokens.
def generate_square_subsequent_mask(sz):
    mask = (torch.triu(torch.ones((sz, sz), device=DEVICE)) == 1).transpose(0, 1)
    mask = mask.float().masked_fill(mask == 0, float('-inf')).masked_fill(mask == 1, float(0.0))
    return mask
def create_mask(src, tgt):
    src_seq_len = src.shape[0]
    tgt_seq_len = tgt.shape[0]

    tgt_mask = generate_square_subsequent_mask(tgt_seq_len)
    src_mask = torch.zeros((src_seq_len, src_seq_len), device=DEVICE).type(torch.bool)

    src_padding_mask = (src == PAD_IDX).transpose(0, 1)
    tgt_padding_mask = (tgt == PAD_IDX).transpose(0, 1)
    return src_mask, tgt_mask, src_padding_mask, tgt_padding_mask
Después defina los parametersThe "parameters" are variables or criteria that are used to define, measure or evaluate a phenomenon or system. In various fields such as statistics, Computer Science and Scientific Research, Parameters are critical to establishing norms and standards that guide data analysis and interpretation. Their proper selection and handling are crucial to obtain accurate and relevant results in any study or project.... del modelo y cree una instancia del modelo.
SRC_VOCAB_SIZE = len(de_vocab)
TGT_VOCAB_SIZE = len(en_vocab)
EMB_SIZE = 512
NHEAD = 8
FFN_HID_DIM = 512
BATCH_SIZE = 128
NUM_ENCODER_LAYERS = 3
NUM_DECODER_LAYERS = 3
NUM_EPOCHS = 50
DEVICE = torch.device('cuda:0' if torch.cuda.is_available() else 'cpu')
transformer = Seq2SeqTransformer(NUM_ENCODER_LAYERS, NUM_DECODER_LAYERS,
                                 EMB_SIZE, SRC_VOCAB_SIZE, TGT_VOCAB_SIZE,
                                 FFN_HID_DIM)

for p in transformer.parameters():
    if p.dim() > 1:
        nn.init.xavier_uniform_(p)

transformer = transformer.to(device)

loss_fn = torch.nn.CrossEntropyLoss(ignore_index=PAD_IDX)

optimizer = torch.optim.Adam(
    transformer.parameters(), lr=0.0001, betas=(0.9, 0.98), eps = 1st-9th
)
Define two different functions, In other words, for training and evaluation.
def train_epoch(model, train_iter, optimizer):
    model.train()
    losses = 0
    for idx, (src, tgt) in enumerate(train_iter):
        src = src.to(device)
        tgt = tgt.to(device)
        tgt_input = tgt[:-1, :]

        src_mask, tgt_mask, src_padding_mask, tgt_padding_mask = create_mask(src, tgt_input)

        logits = model(src, tgt_input, src_mask, tgt_mask,
                       src_padding_mask, tgt_padding_mask, src_padding_mask)

        optimizer.zero_grad()

        tgt_out = tgt[1:, :]
        loss = loss_fn(logits.reshape(-1, logits.shape[-1]), tgt_out.reshape(-1))
        loss.backward()

        optimizer.step()
        losses += loss.item()
    torch.save(model, PATH)

    return losses / len(train_iter)


def evaluate(model, val_iter):
    model.eval()
    losses = 0
    for idx, (src, tgt) in (enumerate(valid_iter)):
        src = src.to(device)
        tgt = tgt.to(device)

        tgt_input = tgt[:-1, :]

        src_mask, tgt_mask, src_padding_mask, tgt_padding_mask = create_mask(src, tgt_input)

        logits = model(src, tgt_input, src_mask, tgt_mask,
                       src_padding_mask, tgt_padding_mask, src_padding_mask)
        tgt_out = tgt[1:, :]
        loss = loss_fn(logits.reshape(-1, logits.shape[-1]), tgt_out.reshape(-1))
        losses += loss.item()
    return losses / len(val_iter)
Now training the model.
for epoch in range(1, NUM_EPOCHS+1):
    start_time = time.time()
    train_loss = train_epoch(transformer, train_iter, optimizer)
    end_time = time.time()
    val_loss = evaluate(transformer, valid_iter)
    print((f"Epoch: {epoch}, Train loss: {train_loss:.3f}, Val loss: {val_loss:.3f}, "
           f"Epoch time = {(end_time - start_time):.3f}s"))
This model is trained using transformer architecture in such a way that it trains faster and at the same time converges to less loss of validation compared to other RNN models..
def greedy_decode(model, src, src_mask, max_len, start_symbol):
    src = src.to(device)
    src_mask = src_mask.to(device)
    memory = model.encode(src, src_mask)
    ys = torch.ones(1, 1).fill_(start_symbol).type(torch.long).to(device)
    for i in range(max_len-1):
        memory = memory.to(device)
        memory_mask = torch.zeros(ys.shape[0], memory.shape[0]).to(device).type(torch.bool)
        tgt_mask = (generate_square_subsequent_mask(ys.size(0))
                                    .type(torch.bool)).to(device)
        out = model.decode(ys, memory, tgt_mask)
        out = out.transpose(0, 1)
        prob = model.generator(out[:, -1])
        _, next_word = torch.max(prob, dim = 1)
        next_word = next_word.item()

        ys = torch.cat([ys,
                        torch.ones(1, 1).type_as(src.data).fill_(next_word)], dim=0)
        if next_word == EOS_IDX:
          break
    return ys


def translate(model, src, src_vocab, tgt_vocab, src_tokenizer):
    model.eval()
    tokens = [BOS_IDX] + [src_vocab.stoi[took] for tok in src_tokenizer(src)] + [EOS_IDX]
    num_tokens = len(tokens)
    src = (torch.LongTensor(tokens).reshape(num_tokens, 1))
    src_mask = (torch.zeros(num_tokens, num_tokens)).type(torch.bool)
    tgt_tokens = greedy_decode(model, src, src_mask, max_len=num_tokens + 5, start_symbol=BOS_IDX).flatten()
    return " ".join([tgt_vocab.itos[took] for tok in tgt_tokens]).replace("<bunch>", "").replace("<eos>", "")
Now, Let's test our translation model.
output = translate(transformer, "A group of people stands in front of an igloo .", de_vocab, en_vocab, de_tokenizer)
print(output)
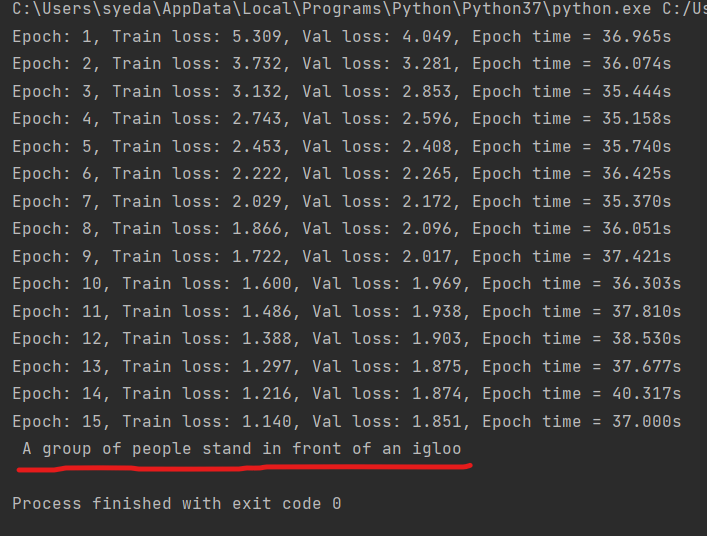
Above the red line is the result of the translation model. You can also compare it with the Google translator.
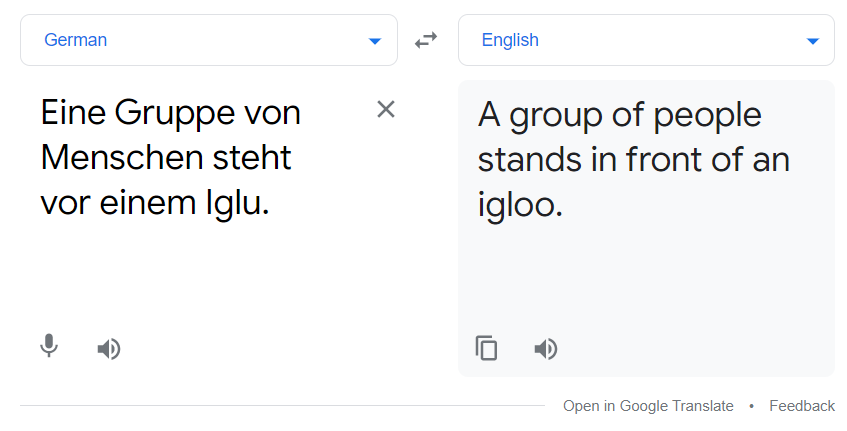
The above translation and the output of our model matched. The model is not the best, but it still works up to a point.
Reference
[1]. Ashish Vaswani, Noam shazeer, Niki Parmar, Jakob Rękoreit, Llion Jones, Aidan N. Gomez, Lukasz Kaiser and Illia Polosukhin: attention is all you need, December of 2017, DOI: https://arxiv.org/pdf/1706.03762.pdf
Also for more information, see https://pytorch.org/tutorials/
Thanks
The media shown in this post is not the property of DataPeaker and is used at the author's discretion.





