
While working on Spark app tuning issue, I spent a considerable amount of time trying to make sense of the Spark web UI visualizations. Spark Web UI is a very useful tool for this task. For beginners, it becomes very difficult to get insights into a problem just from these visualizations. Although there are very good resources on Spark performance, the information was scattered. Therefore, I felt the need to document and share my learnings.
Target audience and conclusions
This post assumes that readers have a basic understanding of Spark concepts.. This post will help beginners identify potential performance issues in their applications running from a Spark web UI.. The focus is only on the information that is not obvious from the user interface and the inferences that can be drawn from this non-obvious information. Note that it does not contain an exhaustive list of information to interpret from Spark Web UI, but only those that I found relevant to my project and, but nevertheless, general enough for the audience to know.
Spark web user interface
Spark's web UI is only available when the application is running. To analyze past executions, the history server must be enabled to store event logs which can then be used to populate the web UI.
Spark Web UI displays useful information about your application in tabs, namely
- Executors
- Environment
- Works
- Etapas
- Storage
The remaining post describes the intuitions of each of the tabs, in the order mentioned.
Executors tab
Gives information about the tasks executed by each executor.
Fig 1: Executor tab summary
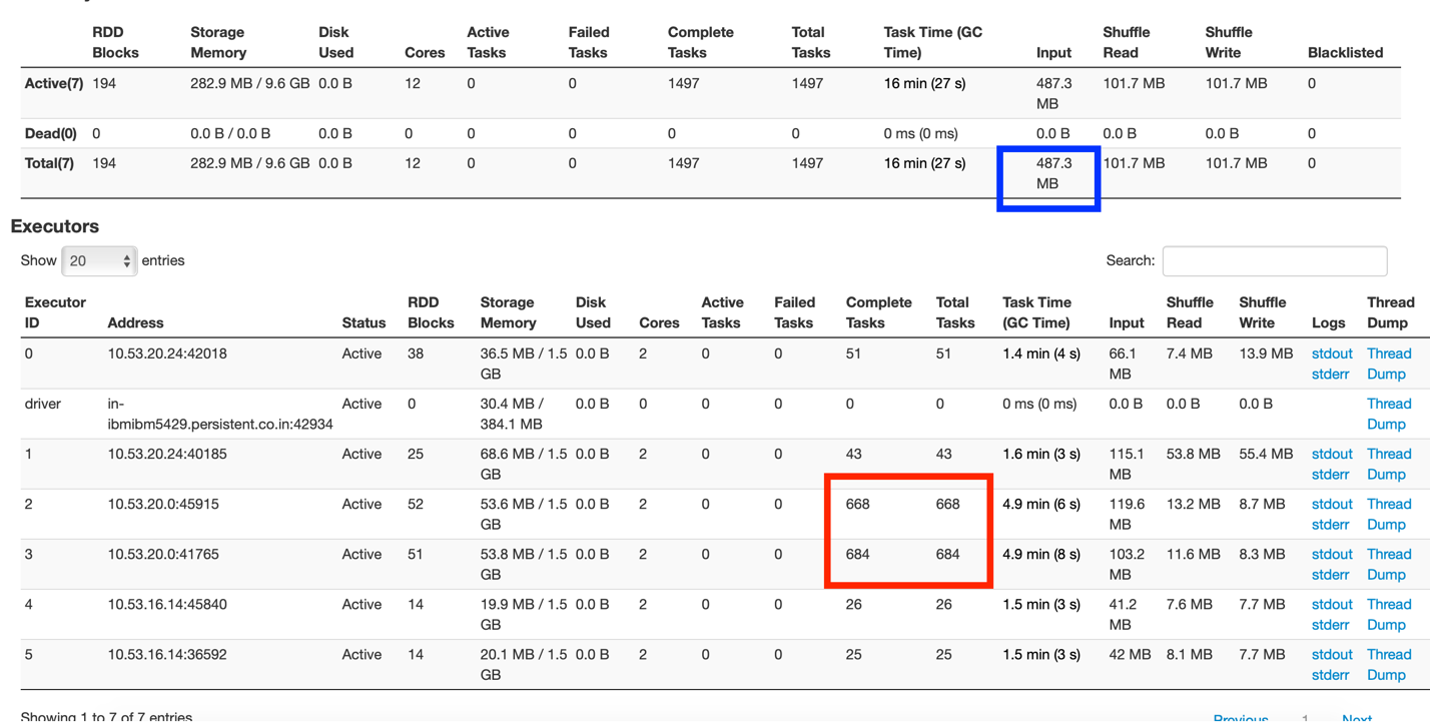
A partir de la figure"Figure" is a term that is used in various contexts, From art to anatomy. In the artistic field, refers to the representation of human or animal forms in sculptures and paintings. In anatomy, designates the shape and structure of the body. What's more, in mathematics, "figure" it is related to geometric shapes. Its versatility makes it a fundamental concept in multiple disciplines.... 1, it can be understood that there is a controller and 5 executors, each of which runs with 2 cores and 3 GB of memory.
The box marked in Red muestra la distribución desigual de las tareas en las que un nodeNodo is a digital platform that facilitates the connection between professionals and companies in search of talent. Through an intuitive system, allows users to create profiles, share experiences and access job opportunities. Its focus on collaboration and networking makes Nodo a valuable tool for those who want to expand their professional network and find projects that align with their skills and goals.... of the clusterA cluster is a set of interconnected companies and organizations that operate in the same sector or geographical area, and that collaborate to improve their competitiveness. These groupings allow for the sharing of resources, Knowledge and technologies, fostering innovation and economic growth. Clusters can span a variety of industries, from technology to agriculture, and are fundamental for regional development and job creation.... está exagerando las tareas, while others are relatively inactive.
The box marked in blue shows that the size of the input data was 487,3 MB. Now, this application ran on a dataset size of 83 MB. The size of the input data comprises the reading of the original data set and the random data transfers between the nodes. This shows that a lot of data has been shuffled (about 400+ MB) in the app.
Environment tab
There are many spark properties to control and adjust the application. These properties can be set when submitting the job or when creating the context object. Unless the property is explicitly added, does not apply. We are wrong to assume that the properties are applied with their default values, when not explicitly stated. All applied properties can be seen in the Environment tab. If the property is not seen there, means that the property has not been applied at all.
Jobs tab
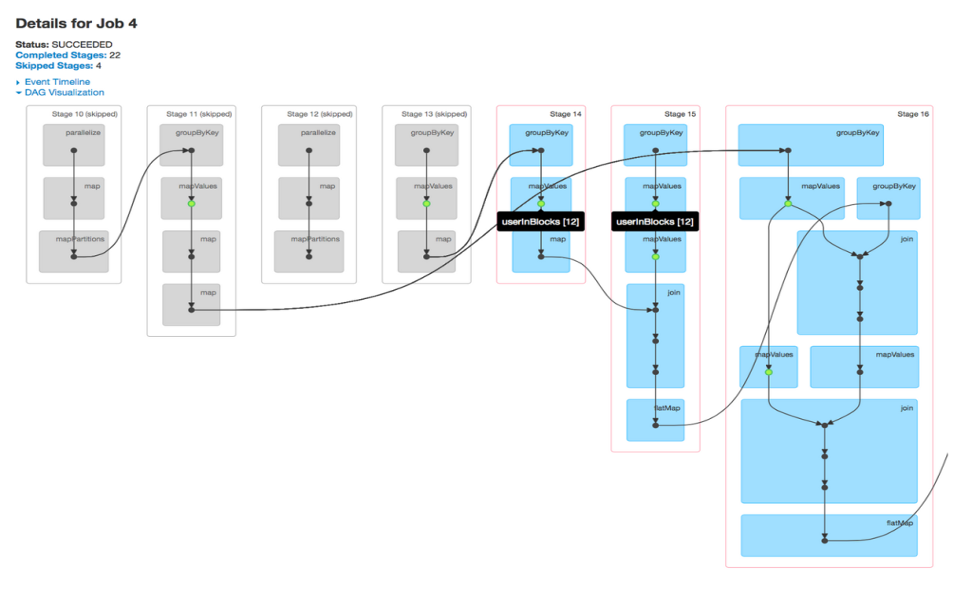
Un trabajo está asociado con una cadena de dependencias Resilient Distributed means fault tolerance so they can recalculate missing or damaged partitions due to node failuresa "dataset" or dataset is a structured collection of information, which can be used for statistical analysis, Machine learning or research. Datasets can include numerical variables, categorical or textual, and their quality is crucial for reliable results. Its use extends to various disciplines, such as medicine, economics and social science, facilitating informed decision-making and the development of predictive models.... organizadas en un direct acyclic chart (DAY) which looks like Fig. 2. From the DAG visualizations, you can find the executed stages and the number of skipped stages. By default, spark does not reuse its calculated steps in stages, unless persisted or explicitly cached. Skipped stages are cached stages marked in gray, donde los valores de cálculo se almacenan en la memoria y no se vuelven a calcular después de acceder a HDFSHDFS, o Hadoop Distributed File System, It is a key infrastructure for storing large volumes of data. Designed to run on common hardware, HDFS enables data distribution across multiple nodes, ensuring high availability and fault tolerance. Its architecture is based on a master-slave model, where a master node manages the system and slave nodes store the data, facilitating the efficient processing of information... A glance at the DAG display is enough to know if RDD calculations are performed repeatedly or if cached stages are used.
Fig 2: DAG display of a job
Stages tab
Provides a deeper insight into the application running at the task level. A stage represents a segment of work performed in parallel by individual tasks. There is a mapping 1-1 between tasks and data partitions, namely, 1 task per data partition. One can delve into a job, in specific stages and up to each task in a stage from the Spark web UI.
The stage provides a good overview of the executions: DAG displays, event timelines, summary metrics / aggregation of your tasks.
I prefer to look at the timelines of the events to analyze the tasks. They give a pictorial representation of the details of the time invested in the execution of the stage. With a single glance, we could make quick inferences about how well the stage performed and how we could further improve the execution time.
Fig 3 – Event timeline sample
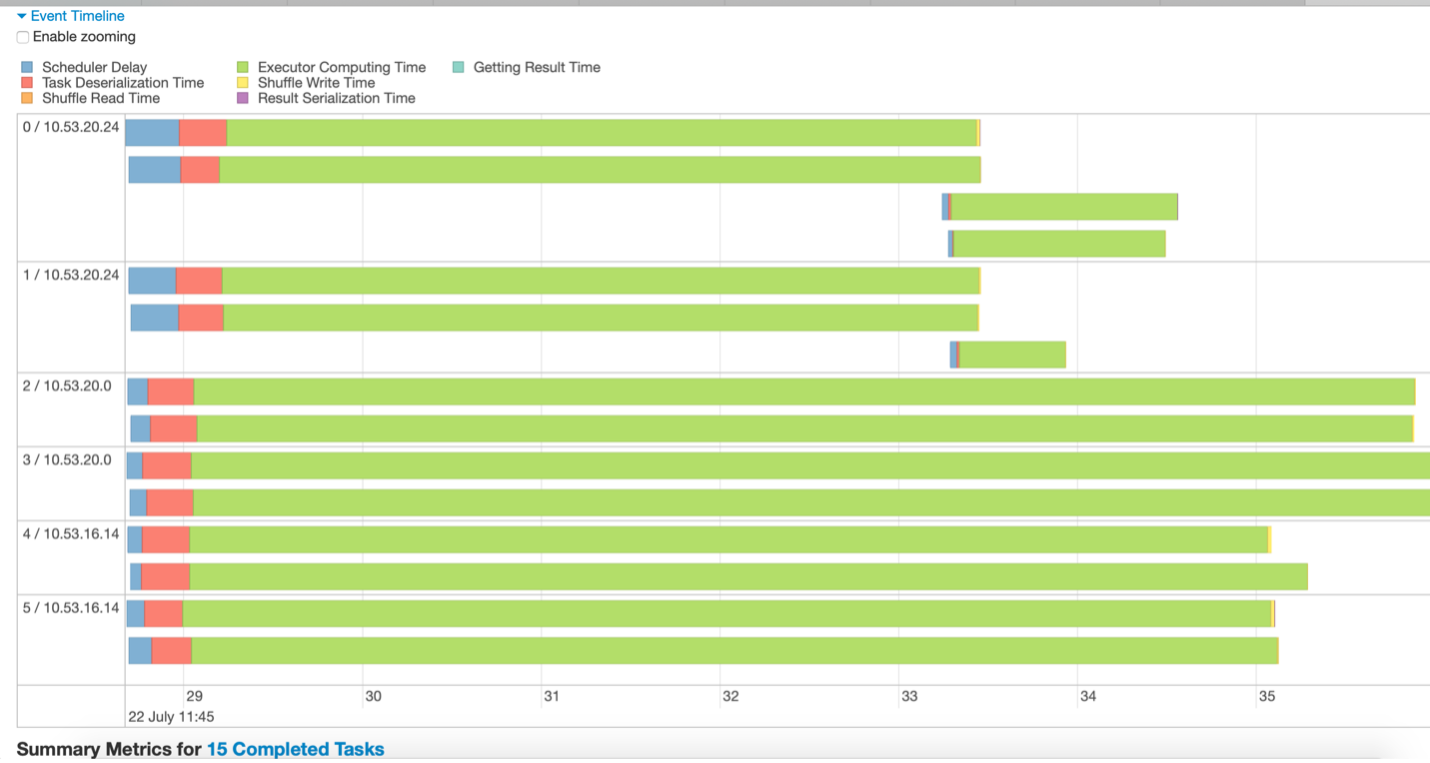
For instance, the inferences drawn from the figure 3 they could be:
- The data is divided into 15 partitions. Therefore, They are running 15 homework (represented with 15 green lines).
- Tasks run in 3 nodes, each one with 2 executors
- The stage completes only when the longest running task ends. Other executors remain inactive until the longest task is finished.
- Few long-running tasks, while few tasks run for a very short time, indicating that the data is not well partitioned.
- Not much time has been spent on delaying the scheduler or serialization at this stage, which is good.
Fig. 4 – One-stage event timeline with many data partitions.
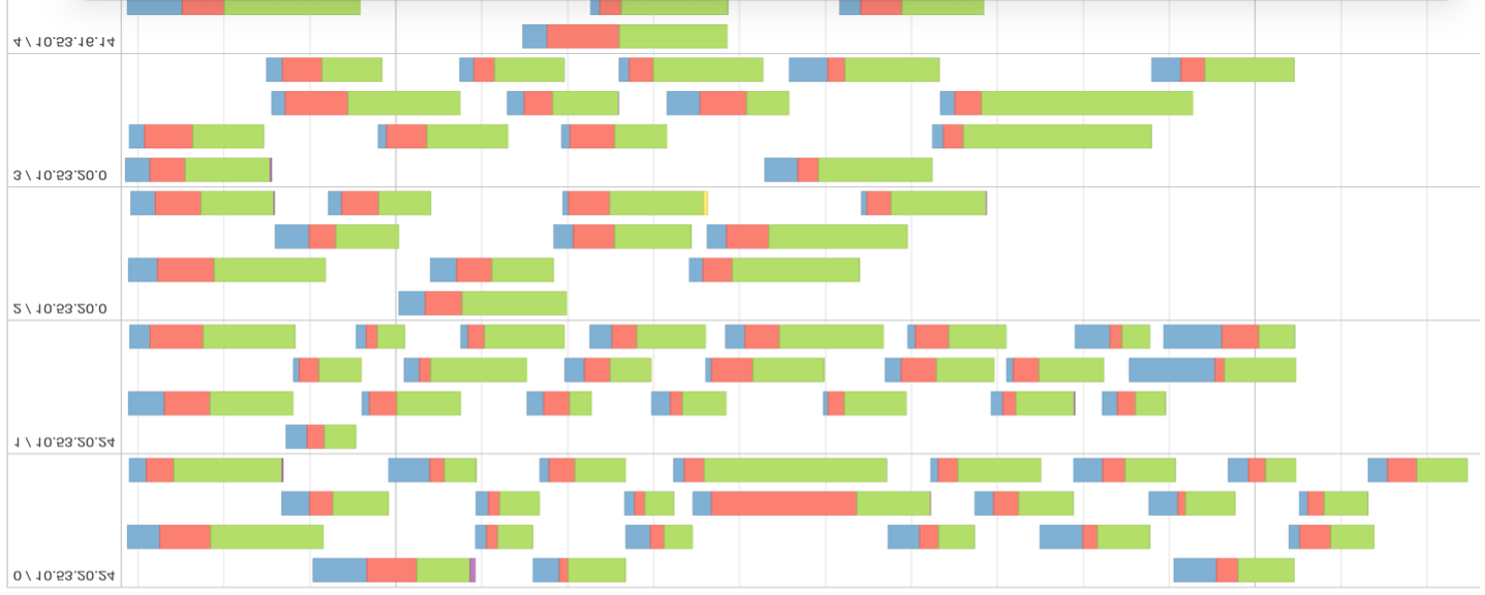
Observing the figure 4, we can infer that the data is not well distributed and unnecessarily partitioned. From the evaluation metric, it can be confirmed that the task scheduling took longer than the actual execution time. The higher the percentage of green in the timeline, the more efficient will be the calculation of the stage.
It is desirable to have fewer stages in the work. Whenever data is mixed, a new stage is created. Shuffling is expensive and, Thus, try to reduce the number of stages your program needs.
Input data size
Another important information is to observe the input size of the data that has been shuffled. One of the goals is also to reduce the size of this random data.
Fig. 5 – Stages tab overview.
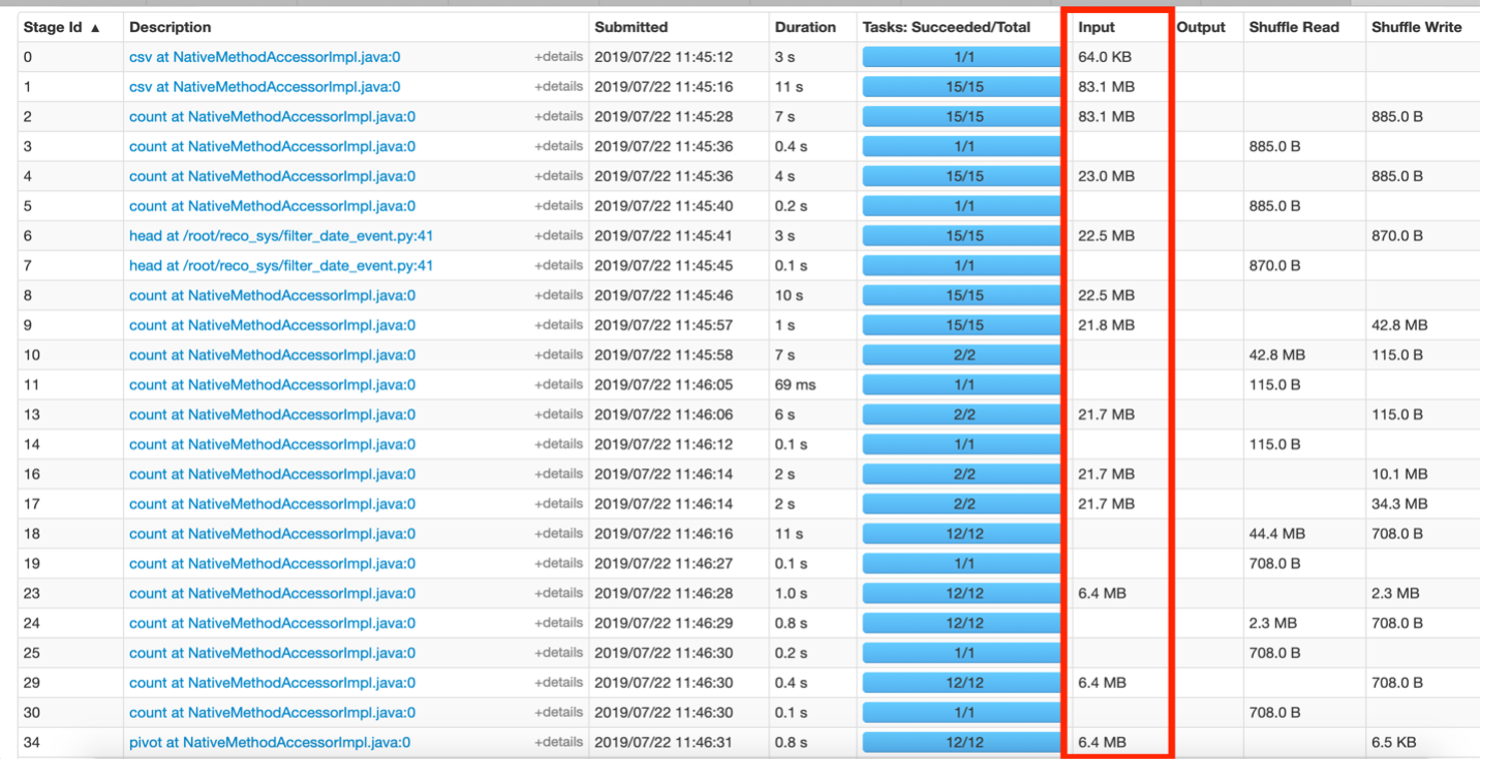
The figure 5 above shows the stages in which the data moves in MB. This suggests that the code can be improved to reduce the size of the data that has been exchanged between the stages. For instance, Let's say if a filter was applied on some data for an 'x event’ dice, then in the resulting RDD, the column "event" becomes redundant since technically all the rows are from the event 'x'. This column could be removed from future RDDs created from this filtered data to save additional information transferred during shuffle operations.
TokenThe "Token" It is a term used in various contexts, usually to refer to a document or card that contains specific information on a topic, person or product. In academic settings, It is used to record relevant data on research or bibliographic sources. In the business environment, Cards can be useful tools for organizing customer or product data, facilitating the management and access to information.... de almacenamiento
Shows only RDDs that have been preserved, namely, who use persist () o hide (). To make it more readable, you can name the RDD while storing it using setName (). Only the RDDs you want to keep should be displayed on the Storage tab and could be easily recognizable with the custom names provided.
Summary
This article helps provide information to identify Spark web UI issues, as the size of the data that has been shuffled, the execution time of the stages, RDD recalculation due to lack of caching. If one understands its data and its application, then the ideal data distribution and the desired number of partitions could be measured by inferring from the running UI. The overhead of one node versus others in the cluster is another area for improvement that could be seen in this user interface. The resolutionThe "resolution" refers to the ability to make firm decisions and meet set goals. In personal and professional contexts, It involves defining clear goals and developing an action plan to achieve them. Resolution is critical to personal growth and success in various areas of life, as it allows you to overcome obstacles and keep your focus on what really matters.... de algunos de estos problemas se discute más en el Apache Spark Performance Tuning Article.
The media shown in this article is not the property of DataPeaker and is used at the author's discretion.





