
This article was published as part of the Data Science Blogathon
Introduction:
Technology. This data set consists of handwritten digits from the 0 al 9 and provides a pavement for testing image processing systems. This is considered the ‘hello world program in Machine Learning’ que involucra Deep Learning.
The steps involved are:
- Import dataset
- Split the dataset into test and trainingTraining is a systematic process designed to improve skills, physical knowledge or abilities. It is applied in various areas, like sport, Education and professional development. An effective training program includes goal planning, regular practice and evaluation of progress. Adaptation to individual needs and motivation are key factors in achieving successful and sustainable results in any discipline....
- Construction of the model
- Train the model
- Predict accuracy
1) Dataset import:
To continue with the code, we need the data set. Then, we think of various sources as data sets, FIA, kaggle, etc. But since we are using Python with its vast built-in modules, has the MNIST data in the keras.datasets module. Therefore, we don't need to download and store the data externally.
from keras.datsets import mnist
data = mnist.load_data()
Therefore, from the keras.datasets module we import the mnist function that contains the data set.
Later, the dataset is stored in the variable data using the mnist.load_data function () which loads the dataset into variable data.
Then, let's see the type of data that we find something unusual since it is of the type tuple. We know that the mnist dataset contains images of handwritten digits, stored in the form of tuples.
data
type(data)
2) Divide the dataset into train and test:
We directly divide the data set into train and test. Then, For that, we initialize four variables X_train, y_train, X_test, y_test to damage the train and test the data for the dependent and independent values respectively.
(X_train, y_train), (X_test, y_test) = data
X_train[0].shape
X_train.shape
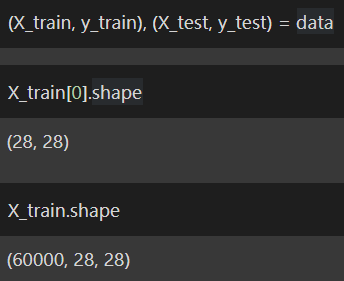
By printing the shape of each image we can find that it has a size of 28 × 28. Which means the image has 28 pixels x 28 pixels.
Now, we have to reshape in such a way that we can access every pixel of the image. The reason for accessing each pixel is that only then can we apply ideas from deep learningDeep learning, A subdiscipline of artificial intelligence, relies on artificial neural networks to analyze and process large volumes of data. This technique allows machines to learn patterns and perform complex tasks, such as speech recognition and computer vision. Its ability to continuously improve as more data is provided to it makes it a key tool in various industries, from health... and we can assign a color code to each pixel. Then we store the reshaped array in X_train, X_test respectively.
X_train = X_train.reshape((X_train.shape[0], 28*28)).astype('float32')
X_test = X_test.reshape((X_test.shape[0], 28*28)).astype('float32')
We know the RGB color code where different values produce various colors. It is also difficult to remember all the color combinations. Then, refer to this Link to get a brief idea about RGB color codes.
We already know that each pixel has its unique color code and we also know that it has a maximum value of 255. Para realizar Machine Learning, it is important to convert all values of 0 a 255 for each pixel to a range of values of 0 a 1. The simplest way is to divide the value of each pixel by 255 to get the values in the range of 0 a 1.
X_train = X_train / 255
X_test = X_test / 255
Now we have finished dividing the data into test and training, as well as preparing the data for later use. Therefore, now we can move on to the pass 3: Model building.
3) Train the model:
To perform model building, we have to import the required functions, namely, sequential and dense to run deep learning, which is available in the Keras library.
But this is not directly available, so we must understand this simple line graphThe line chart is a visual tool used to represent data over time. It consists of a series of points connected by lines, which allows you to observe trends, Fluctuations and patterns in the data. This type of chart is especially useful in areas such as economics, Meteorology and scientific research, making it easier to compare different data sets and identify behaviors across the board..:
1) Hard -> Models -> Sequential
2) Hard -> Covers -> Denso
Let's see how we can import the functions with the same logic as a Python code.
from keras.models import Sequential
from keras.layers import Dense
model = Sequential()
model.add(Dense(32, input_dim = 28 * 28, activation= 'relu'))
model.add(Dense(64, activation = 'relu'))
model.add(Dense(10, activation = 'softmax'))
We then store the function in the variableIn statistics and mathematics, a "variable" is a symbol that represents a value that can change or vary. There are different types of variables, and qualitative, that describe non-numerical characteristics, and quantitative, representing numerical quantities. Variables are fundamental in experiments and studies, since they allow the analysis of relationships and patterns between different elements, facilitating the understanding of complex phenomena...., as it makes it easy to access the function every time instead of typing the function every time, we can use the variable and call the function.
Later, turn the image into a dense group of layers and stack each layer on top of each other and use 'relu’ like our wake functionThe activation function is a key component in neural networks, since it determines the output of a neuron based on its input. Its main purpose is to introduce nonlinearities into the model, allowing you to learn complex patterns in data. There are various activation functions, like the sigmoid, ReLU and tanh, each with particular characteristics that affect the performance of the model in different applications..... The explanation of ‘relu’ is beyond the scope of this blog. To get more information about it, you can consult that.
Besides, we stack a few more layers with ‘softmax’ as our activation function. For more information on the 'softmax' function, you can refer to this article, as it is beyond the scope of this blog again, since my main goal is to get as accurate as possible with the MNIST dataset.
Later, finally we compile the full model and use cross entropy like our Loss functionThe loss function is a fundamental tool in machine learning that quantifies the discrepancy between model predictions and actual values. Its goal is to guide the training process by minimizing this difference, thus allowing the model to learn more effectively. There are different types of loss functions, such as mean square error and cross-entropy, each one suitable for different tasks and..., to optimize the use of our model Adam as our optimizer and we use precision as metrics to evaluate our model.
For an overview of our model, usamos ‘model.summary ()’, which provides brief details about our model.
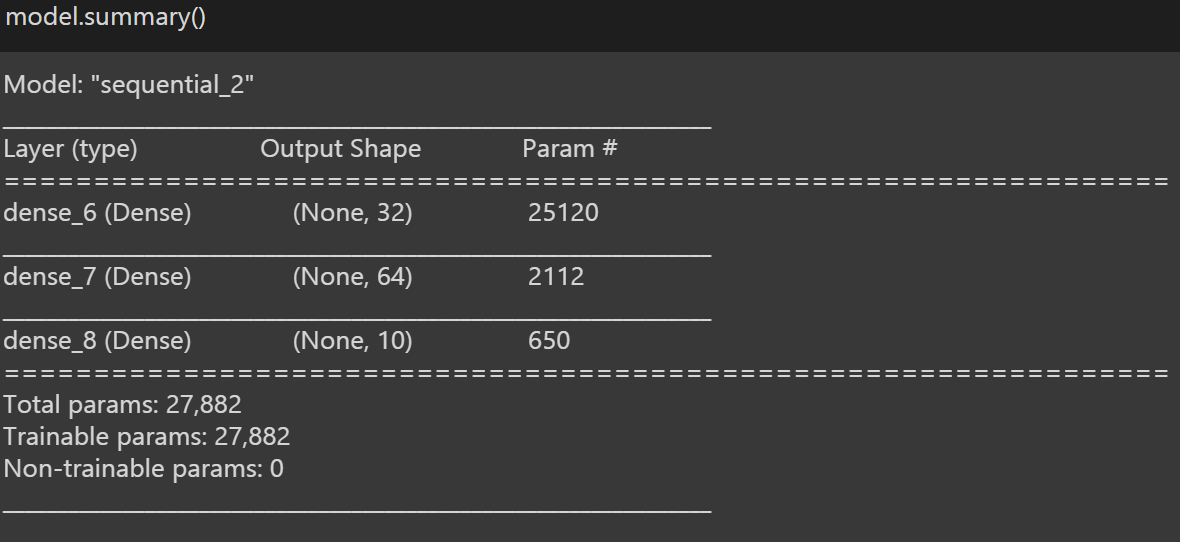
Now we can move on to the Pass 4: Train the model.
4) Train the model:
This is the penultimate step in which we are going to train the model with a single line of code. Then, For that, we are using the .fit function () which takes the set of trains of the dependent variable and the independent and dependent variable as input, and set epochs = 10, and set batch_size as 100.
Train set => X_train; y_train
Epochs => An epoch means training the red neuronalNeural networks are computational models inspired by the functioning of the human brain. They use structures known as artificial neurons to process and learn from data. These networks are fundamental in the field of artificial intelligence, enabling significant advancements in tasks such as image recognition, Natural Language Processing and Time Series Prediction, among others. Their ability to learn complex patterns makes them powerful tools.. with all training data for a cycle. An epoch is made up of one or more batches, where we use a part of the dataset to train the neural network. Which means we send the model to train 10 times to obtain high precision. You can also change the number of epochs based on the performance of the model.
Lot Size => Batch size is a term used in machine learning and refers to the number of training examples used in one iteration. Then, basically, we send 100 images to train as a batch per iteration.
Let's see the coding part.
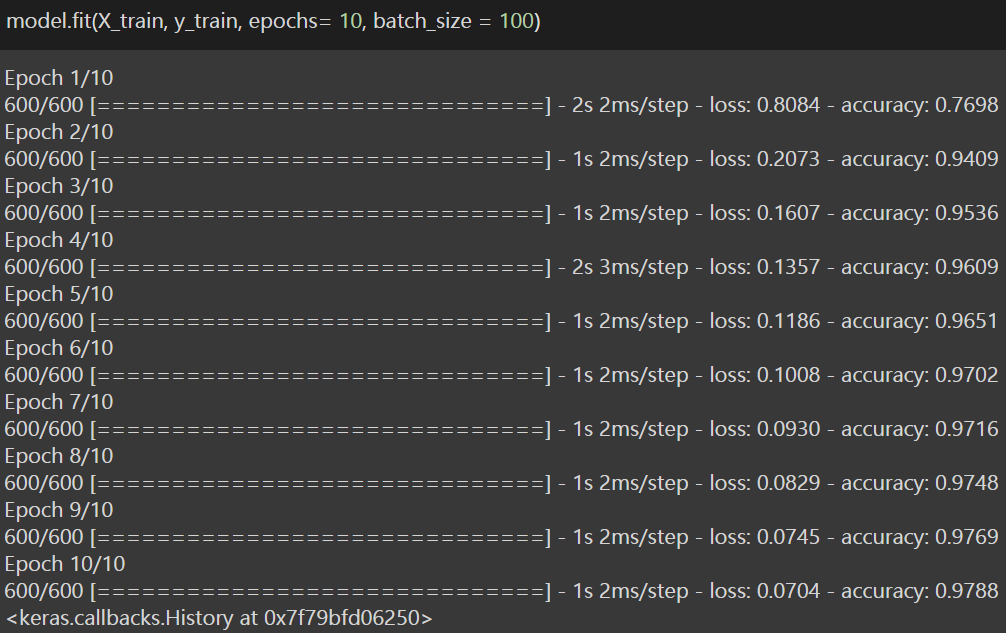
Therefore, after training the model, we have achieved a precision of 97,88% for training data set. Now is the time to see how the model works in the test set and see if we have achieved the required accuracy. Therefore, now we go to the last step or step 5: Predict accuracy.
5) Prediction accuracy:
Then, to find out how well the model works on the test dataset, I use the scores variable to store the value and use the .evaluate function () which takes the test set of the dependent and independent variables as input. This calculates the loss and precision of the model in the test set. How we focus on precision, we print only the precision.
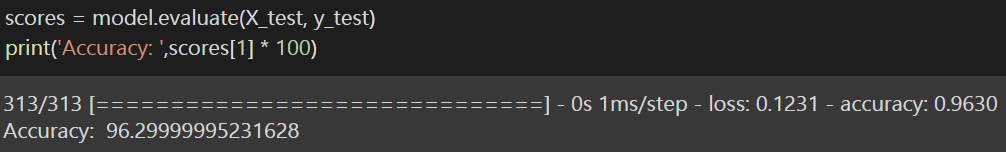
Finally, we have achieved the result and ensure an accuracy of more than 96% in the test set which is very appreciable, and the blog motive is achieved. I have written the link to laptop for your reference (readers).
Please, feel free to connect with me through Linkedin as well as. And thanks for reading the blog.
The media shown in this article is not the property of DataPeaker and is used at the author's discretion.





