
Introduction
Table of Contents
- Why should we use function engineering in data science?
- Feature selection
- Handling missing values
- Handling unbalanced data
- Handling of outliers
- Binning
- Coding
- Function scale
1. Why should we use function engineering in data science?
En Data Science, model performance depends on preprocessing and data handling. Suppose that if we build a model without Data handling, we obtain a precision of around 70%. By applying function engineering on the same model, there is the possibility to increase the performance of the 70% to more.
Simply, when using function engineering, we improve the performance of the model.
2. Feature selection
The selection of functions is nothing more than a selection of necessary independent functions. Selecting the important independent characteristics that are most related to the dependent characteristic will help to build a good model.. There are some methods for selecting functions:
2.1 Correlation matrix with heat map
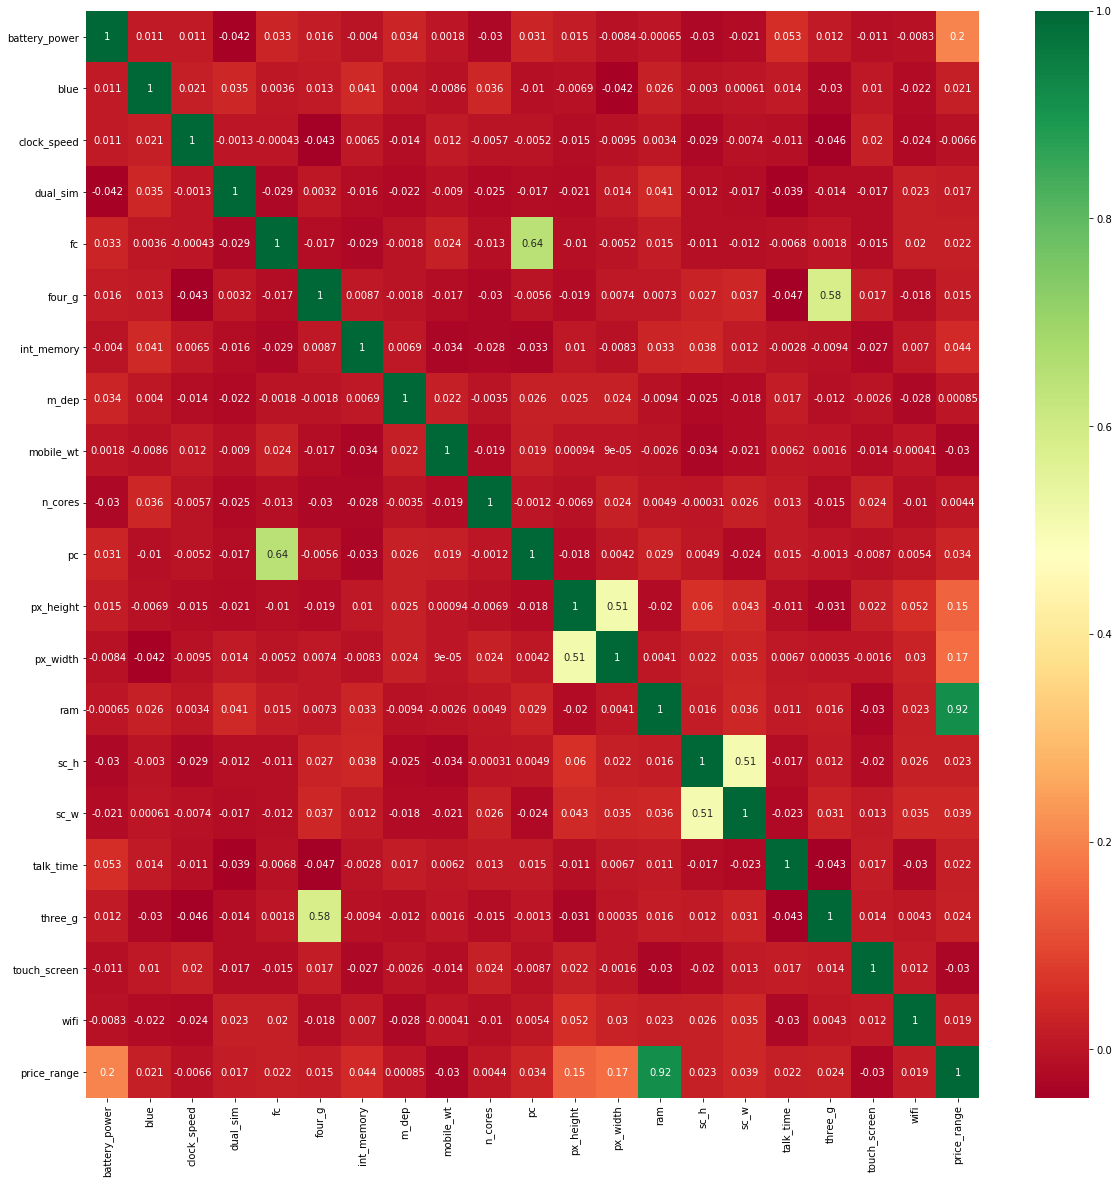
The heat mapa "heat map" is a graphical representation that uses colors to show the density of data in a specific area. Commonly used in data analytics, Marketing and behavioral studies, This type of visualization allows you to identify patterns and trends quickly. Through chromatic variations, Heat maps make it easier to interpret large volumes of information, helping to make informed decisions.... es una representación gráfica de datos 2D (two-dimensional). Each data value is represented in an array.
First, draw the pair graph between all independent characteristics and dependent characteristics. Will give the relationship between dependent and independent characteristics. The relationship between the independent characteristic and the dependent characteristic is less than 0.2, then choose that independent feature to build a model.
2.2 Univariate selection
In this, statistical tests can be used to select the independent characteristics that have the strongest relationship with the dependent characteristic. Select KBest The method can be used with a set of different statistical tests to select a specific number of characteristics.
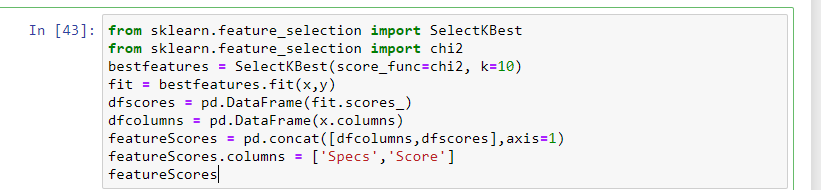
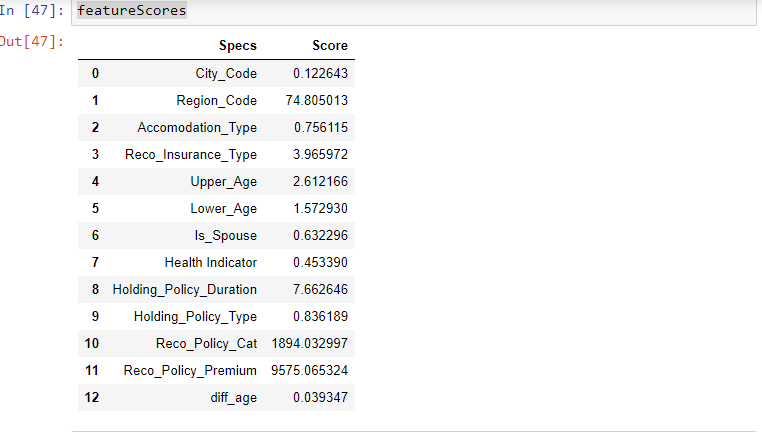
- The characteristic that has the highest score will be more related to the dependent characteristic, and choose those characteristics for the model.
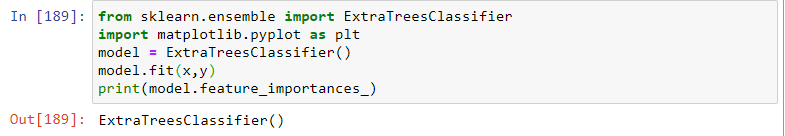
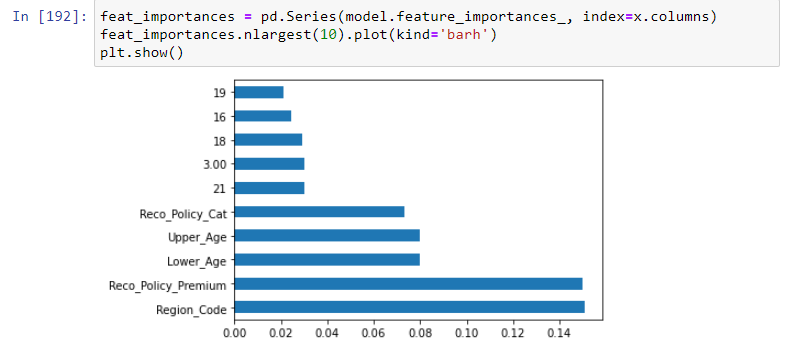
2.3 ExtraTreesClassifier method
In this method, the ExtraTreesClassifier method will help to give the importance of each independent characteristic with a dependent characteristic. Role Importance will give you a score for each role in your data, the higher the score, más importante o relevante para la función con respecto a su variableIn statistics and mathematics, a "variable" is a symbol that represents a value that can change or vary. There are different types of variables, and qualitative, that describe non-numerical characteristics, and quantitative, representing numerical quantities. Variables are fundamental in experiments and studies, since they allow the analysis of relationships and patterns between different elements, facilitating the understanding of complex phenomena.... de salida.
3. Handling missing values
In some data sets, we obtained the NA values in the characteristics. They are just missing data. Handling this type of data there are many ways:
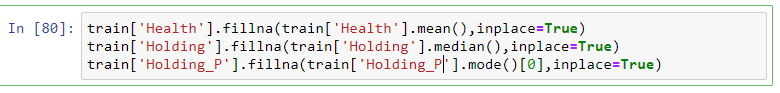
- In the places of lost values, para reemplazar los valores perdidos con la media o medianThe median is a statistical measure that represents the central value of a set of ordered data. To calculate it, the data is organized from lowest to highest and the number in the middle is identified. If there are an even number of observations, the two core values are averaged. This indicator is especially useful in asymmetric distributions, since it is not affected by extreme values.... en los datos numéricos y para los datos categóricos con la moda.
- Eliminate NA values in entire rows.

- Eliminate NA values for full features. (helps if NA values are more than 50% in a function)

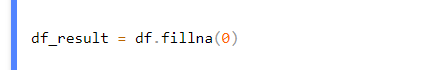
- Replace the NA values with 0.
If you choose to discard options, there is the possibility of losing important information from them. So it is better to choose to replace the options.
4. Handling unbalanced data
Why is it necessary to handle unbalanced data? Due to reduce the problem of overfitting and misfitting.
suppose a characteristic has a factor level2 (0 Y 1). consists of 1 it is 5% Y 0 it is 95%. It's called unbalanced data.
Example:-
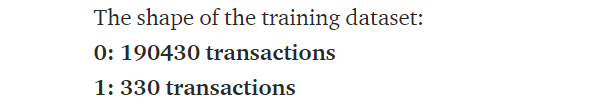
To prevent this problem, there are some methods:
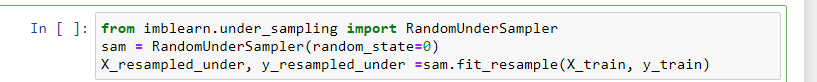
4.1 Subsampled Majority Class
A subsampling of the majority class will resample the points of the majority class in the data to make them equal to the minority class.
4.2 Duplication oversampling minority class
Oversampling the minority class will resample the minority class points in the data to make them equal to the majority class.

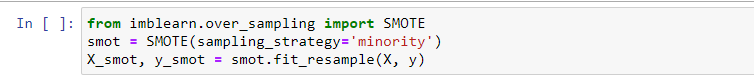
4.3 Oversampling the minority class using the synthetic minority oversampling technique (SMOTE)
In this method, synthetic samples are generated for the minority class and equal to the majority class.
5. Handling of outliers
First, Calculate the skewness of the features and check if they are positively biased, negatively or normally biased. Another method is to plot the box plot on the characteristics and check if any value is out of bounds or not.. if they exist, are called outliers.
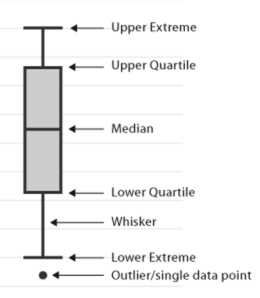
how to handle these outliers: –
First, compute quantile values at 25% Y 75%.
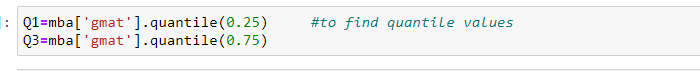
- then, calculate the interquartile range
IQR = Q3 – Q1

- Then, calculate the values of the upper and lower extremes.
lower end = Q1 – 1,5 * IQR
upper end = Q3– 1,5 * IQRe
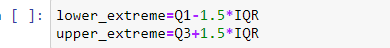
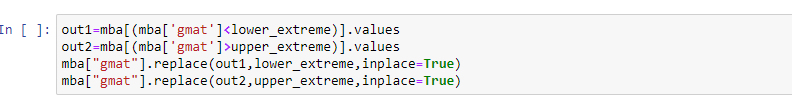
- finally, check that the values are above the upper limit or below the lower limit. if it is presented, remove or replace them with the stocking, the median or any quantile value.
- Replace outliers with mean

- Replace outliers with quantile values

6. Binning
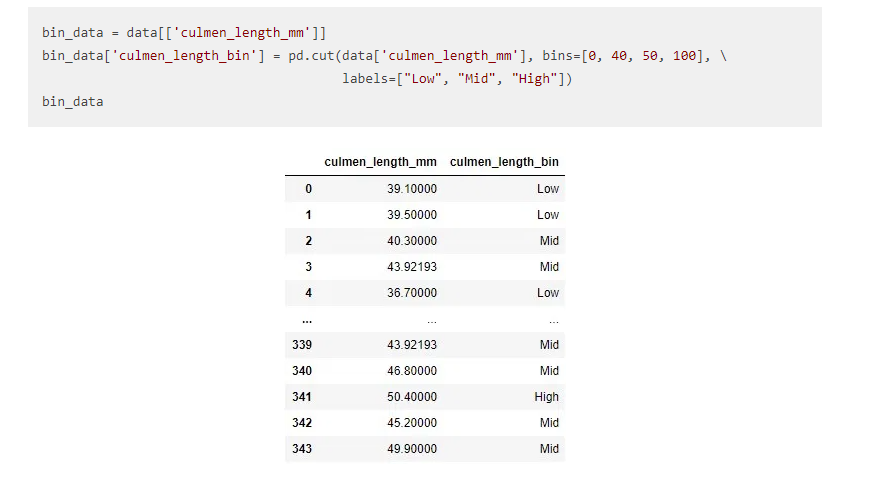
Binning is nothing more than any data value within the range that fits the bin. It is important in your data exploration activity. We normally use it to transform continuous variables into discrete variables..
Suppose that if we have the AGE function continuously and we need to divide the age into groups as a function, then it will be useful.
7. Coding:
Why will this apply? because in data sets we can contain data types of objects. to build a model, we need all features to be in integer data types. Thus, Label Encoder and OneHotEncoder are used to convert the data type of the object to an integer data type.
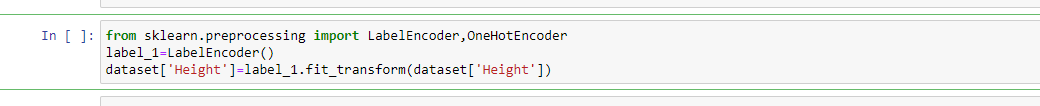
Before applying tag encoding
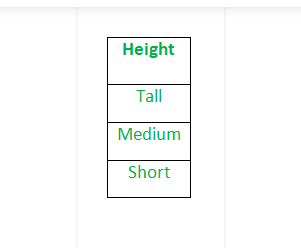
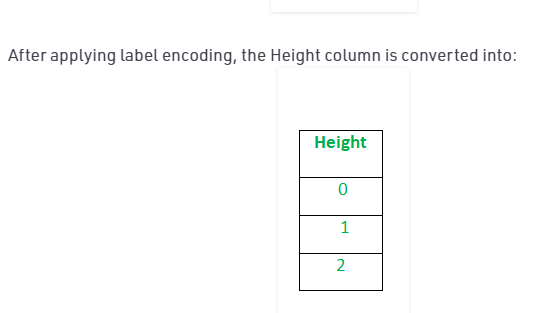
After applying tag encoding, apply column transformer method to convert labels to 0 Y 1
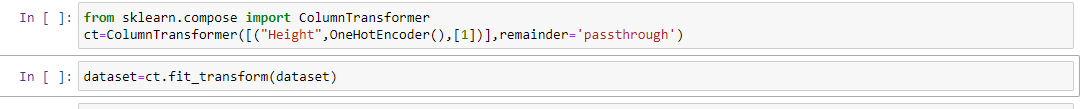
Al aplicar get_dummies, we directly convert categorical to numeric

8. Function scale
Why is this scale applied? because to reduce the variance effect and overcome the fit problem. there are two types of scaling methods:
8.1 Standardization
When is this method used ?. when all characteristics have high values, no 0 Y 1.
It is a technique to standardize the independent characteristics that occur in a fixed range to bring all the values to the same magnitudes..
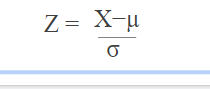
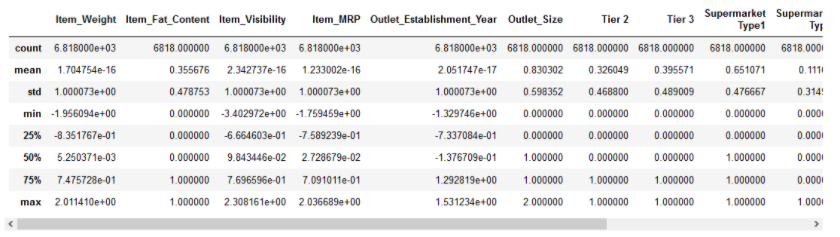
In standardization, the mean of the independent characteristics is 0 and the standard deviation is 1.
Method 1:

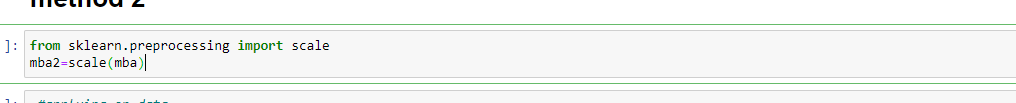
Method 2:
After encoding, feature labels are on 0 Y 1. This can affect standardization. To get over this, we use NormalizationStandardization is a fundamental process in various disciplines, which seeks to establish uniform standards and criteria to improve quality and efficiency. In contexts such as engineering, Education and administration, Standardization makes comparison easier, interoperability and mutual understanding. When implementing standards, cohesion is promoted and resources are optimised, which contributes to sustainable development and the continuous improvement of processes.....
8.2 Normalization
La normalización también hace que el proceso de trainingTraining is a systematic process designed to improve skills, physical knowledge or abilities. It is applied in various areas, like sport, Education and professional development. An effective training program includes goal planning, regular practice and evaluation of progress. Adaptation to individual needs and motivation are key factors in achieving successful and sustainable results in any discipline.... sea menos sensible por la escala de las características. This results in obtaining better coefficients after training..
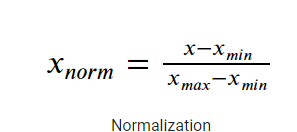
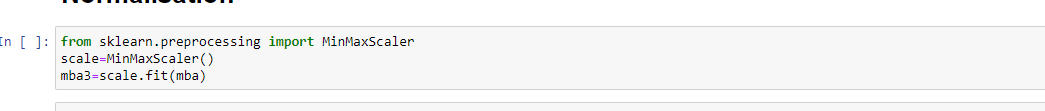
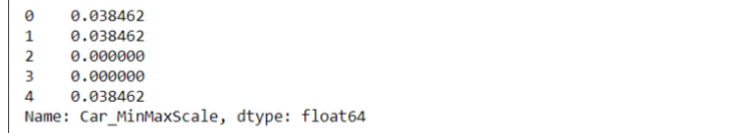
Method 1: -MinMaxScaler
It is a method of rescaling the characteristic to a fast and strict range of [0,1] subtracting the minimum value of the characteristic and then dividing by the range.
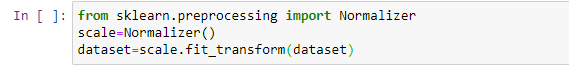
Method 2: – Average normalization
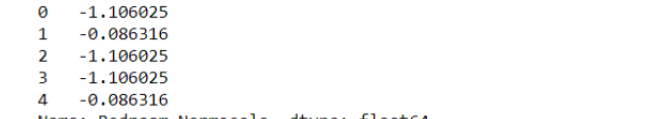
It is a method of rescaling the characteristic to a fast and strict range of [-1,1] with mean = 0.
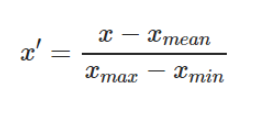
Final notes: –
In this article, I covered the function engineering process step by step. This is most useful for increasing the accuracy of the prediction..
Please note that there are no particular methods to increase the accuracy of your prediction. It all depends on your data and applies multiple methods.
As next step, I encourage you to try different data sets and analyze them. And don't forget to share your ideas in the comment section below!!
About the Author:
Soy Pavan Kumar Reddy Elluru. I completed my graduation from G.Pullareddy Engineering College in the year 2020. I am a certified data scientist in the year 2021 y me apasiona el aprendizaje automático y los proyectos de deep learningDeep learning, A subdiscipline of artificial intelligence, relies on artificial neural networks to analyze and process large volumes of data. This technique allows machines to learn patterns and perform complex tasks, such as speech recognition and computer vision. Its ability to continuously improve as more data is provided to it makes it a key tool in various industries, from health....
Please, write me in case of any query or just to say hello.
Email identification:- [email protected]
Linkedin identification: – www.linkedin.com/in/elluru-pavan-kumar-reddy-a1b183197
ID de Github: – pawankumarreddy1999 (Pavan Kumar Reddy Elluru) (github.com)





