
Introduction
Let's solve Cartpole environments, OpenAI's Lunar Lander and Pong with the STRENGTH algorithm.
The reinforcement learningReinforcement learning is an artificial intelligence technique that allows an agent to learn to make decisions by interacting with an environment. Through feedback in the form of rewards or punishments, The agent optimizes their behavior to maximize the accumulated rewards. This approach is used in a variety of applications, from video games to robotics and recommendation systems, standing out for his ability to learn complex strategies.... es posiblemente la rama más genial de la inteligencia artificial. Has already demonstrated its prowess: amaze the world, beat the world champions in Chess games, Go and include DotA 2.
In this article, I would analyze a rather rudimentary algorithm and show how even this can achieve a superhuman level of performance in certain games.
Reinforcement learning offers with designing “Agents” that interacts with a “Environment” and learn for yourself how “sort out” the environment by systematic trial and error. An environment could be a game like chess or racing, or it could even be a task like solving a maze or achieving a goal. The agent is the bot that performs the activity.
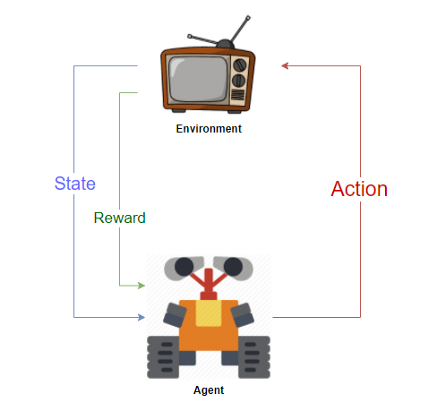
An agent receives “rewards” when interacting with the environment. The agent learns to perform the “Actions” necessary to maximize the reward you receive from the environment. An environment is considered resolved if the agent accumulates some predefined reward threshold. This nerdy talk is how we teach bots to play superhuman chess or biped androids to walk.
STRENGTHEN Algorithm
REINFORCE pertenece a una clase especial de algoritmos de aprendizaje por refuerzo llamados algoritmos de gradientGradient is a term used in various fields, such as mathematics and computer science, to describe a continuous variation of values. In mathematics, refers to the rate of change of a function, while in graphic design, Applies to color transition. This concept is essential to understand phenomena such as optimization in algorithms and visual representation of data, allowing a better interpretation and analysis in... de políticas. A simple implementation of this algorithm would involve creating a Politics: a model that takes a state as input and generates the probability of performing an action as output. A policy is essentially a guide or cheat sheet for the agent that tells what action to take in each state.. Later, the policy is repeated and slightly modified at each step until we get a policy that resolves the environment.
La política suele ser una red neuronalNeural networks are computational models inspired by the functioning of the human brain. They use structures known as artificial neurons to process and learn from data. These networks are fundamental in the field of artificial intelligence, enabling significant advancements in tasks such as image recognition, Natural Language Processing and Time Series Prediction, among others. Their ability to learn complex patterns makes them powerful tools.. que toma el estado como entrada y genera una distribución de probabilidad en el espacio de acción como salida.
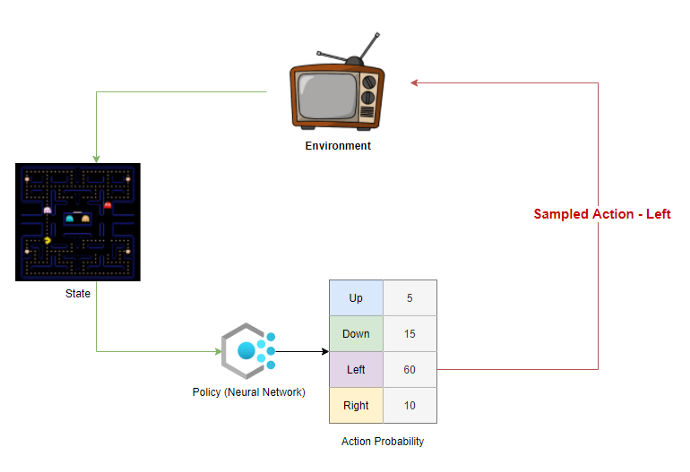
The goal of the policy is to maximize the "Expected reward".
Each policy generates the probability of taking an action in each station in the environment.
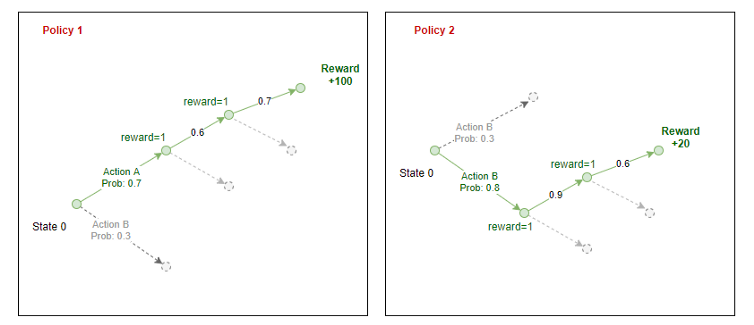
The agent samples these probabilities and selects an action to take in the environment. At the end of an episode, we know the total rewards the agent can get if they follow that policy. We repropagate the reward through the route the agent took to estimate the “expected reward” in each state for a given policy.
Here the discounted reward is the sum of all the rewards that the agent receives in that future discounted by a Gamma factor.
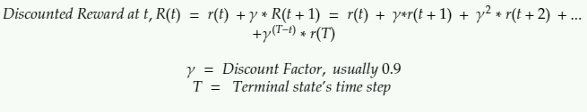
The discounted reward at any stage is the reward you receive in the next step + a discounted sum of all rewards the agent receives in the future.
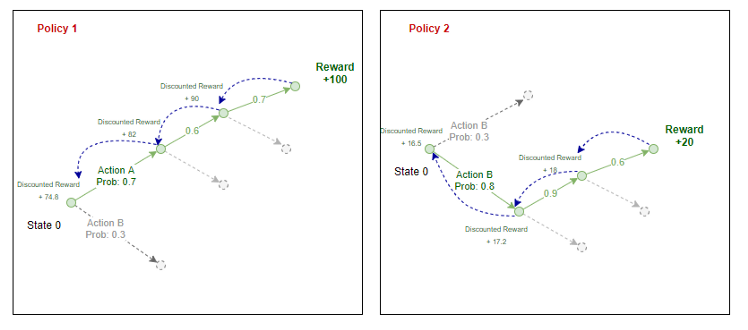
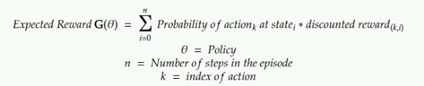
For the above equation, this is how we calculate the expected reward:
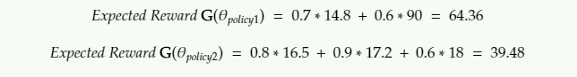
According to the original implementation of the STRENGTH algorithm, the expected reward is the sum of the products of a record of discounted odds and rewards.
Algorithm steps
The steps involved in the implementation of REINFORCE would be the following:
- Initialize a random policy (an NN that takes the state as input and returns the probability of actions)
- Use politics to play N steps of the game: record probabilities of action, of politics, the reward of the environment, the action, sampled by agent
- Calculate the discounted reward for each step by backpropagation
- Calculate the expected reward G
- Adjust the policy weights (reverse propagation error in NN) to increase G
- Repeat from 2
See the implementation using Pytorch in my Github.
Population
I have tested the algorithm in Pong, CartPole and Lunar Lander. It takes forever to train in Pong and Lunar Lander: more of 96 horas de trainingTraining is a systematic process designed to improve skills, physical knowledge or abilities. It is applied in various areas, like sport, Education and professional development. An effective training program includes goal planning, regular practice and evaluation of progress. Adaptation to individual needs and motivation are key factors in achieving successful and sustainable results in any discipline.... cada uno en una GPU en la nube. There are several updates to this algorithm that can make it converge faster, which I have not discussed or implemented here. Check out Critical Actor Models and Upcoming Policy Optimization if you are interested in learning more.
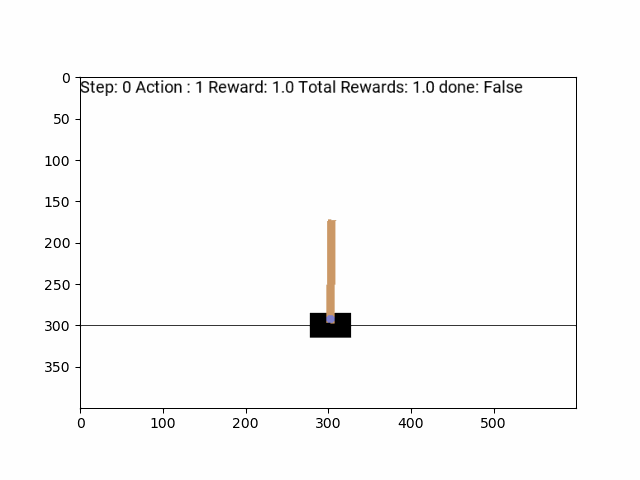
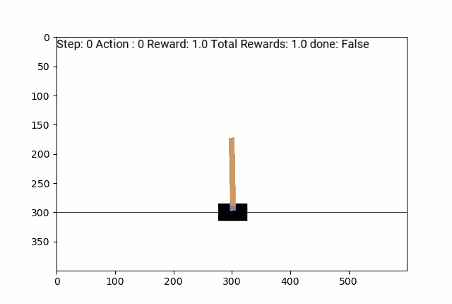
Trolley
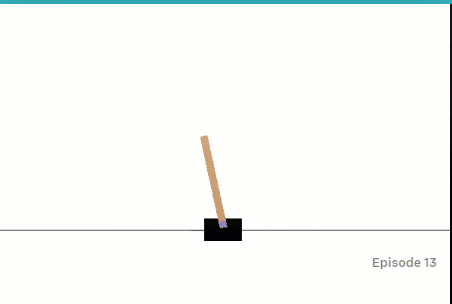
Condition:
Horizontal position, horizontal speed, pole angle, angular velocity
Behaviour:
Push the carriage to the left, Push the carriage to the right
Random politics game:
Policy of agents trained with REINFORCE:
Lander lunar
Random game agent
Condition:
The state is a matrix of 8 vector. I'm not sure what they represent.
Behaviour:
0: do nothing
1: left fire engine
2: Fire engine
3: right fire engine
Policy of agents trained with REINFORCE:
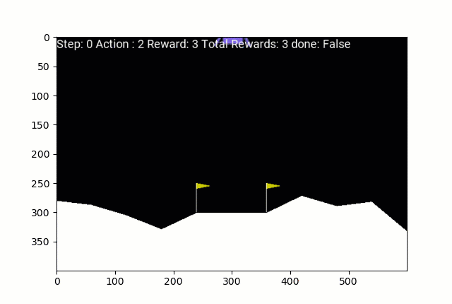
Lunar Lander trained with REINFORCE
Stink
This was much more difficult to train. Trained on a GPU cloud server for days.
Condition: Image
Behaviour: Move palette left, move palette right
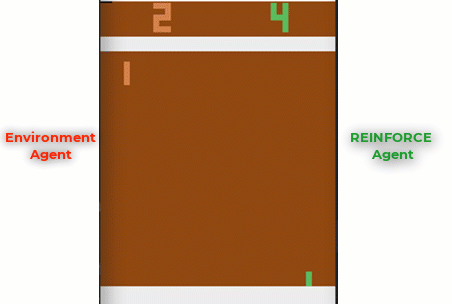
Trained agent
Reinforcement learning has progressed by leaps and bounds beyond REINFORCEMENT. My goal in this article was 1. learn the basics of reinforcement learning and 2. show how powerful even such simple methods can be to solve complex problems. I would love to try them on some “games” to make money like stock trading … I guess that's the holy grail among data scientists.
Github repository: https://github.com/kvsnoufal/reinforce
Shoulders of giants:
- Policy gradient algorithms (https://lilianweng.github.io/lil-log/2018/04/08/policy-gradient-algorithms.html)
- Deriving REINFORCE (https://medium.com/@thechrisyoon/deriving-policy-gradients-and-implementing-reinforce-f887949bd63)
- Udacity Reinforcement Learning Course (https://github.com/udacity/deep-reinforcement-learning)
About the Author
Noufal kvs
Work at Dubai Holding, UAE as a data scientist. You can contact me at [email protected] O https://www.linkedin.com/in/kvsnoufal/





