
Topic to cover
- What is exploratory data analysis?
- What is the need to automate exploratory data analysis?
- Python Libraries to Automate Exploratory Data Analysis
Exploratory data analysis
is a data exploration technique to understand various aspects of data. It's kind of data summary. It is one of the most important steps before performing any machine learning task or deep learningDeep learning, A subdiscipline of artificial intelligence, relies on artificial neural networks to analyze and process large volumes of data. This technique allows machines to learn patterns and perform complex tasks, such as speech recognition and computer vision. Its ability to continuously improve as more data is provided to it makes it a key tool in various industries, from health....
Data scientists perform exploratory data analysis procedures to explore, dissect and summarize the fundamental qualities of data sets, regularly using information representation approaches. EDA procedures take into account convincing control of information sources, enabling data scientists to discover the right answers they need when finding information designs, detect inconsistencies, verify assumptions or test speculations.
Data scientists use exploratory data analysis to see what data sets they can discover beyond the conventional display of information or speculation test assignments. This allows them to acquire top-to-bottom information about the factors in the data sets and their connections.. Exploratory Data Analysis Can Help Recognize Clear Errors, distinguish exceptions in data sets, get connections, discover significant elements, discover insider designs and provide new insights.
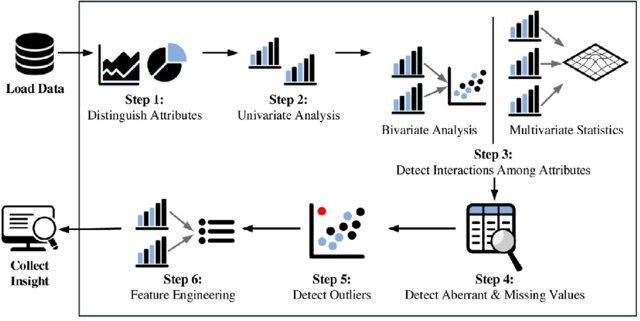
Steps in exploratory data analysis
Need to automate exploratory data analysis
The expanded movement of customers on the web, the refined tools to control web traffic, the multiplication of mobile phones, web-enabled devices and IoT sensors are the essential elements accelerating the pace of today's information age. In this computerized age, associations of all sizes understand that information can play a crucial role in improving their competence, profitability and dynamic skills, which generates greater agreements, income and benefits.
Today, most organizations approach huge data sets, but nevertheless, just having large measures of information does not improve business, except if companies research accessible data and push for authorized development.
In the life cycle of a data science project or any machine learning project, more than 60% of your time get into things like data analysis, feature selection, feature engineering, etc. Because it is the most important part or the backbone of a data science project, it is that particular part where you have to do a lot of activities like cleaning the data, handle missing values , handle outliers, handle unbalanced data sets, how to handle categorical characteristics and much more. So if you want save your time in exploratory data analysis, we can use Python libraries like dtale, pandas profile, sweetviz and autoviz to automate our tasks.
Libraries automate exploratory data analysis
In this blog, we discuss four important Python libraries. These are listed below:
- story
- pandas profile
- sweetviz
- autoviz
D-tale
It is a library that has been launched in February 2020 which allows us to easily visualize the pandas data frame. It has many features that are very useful for exploratory data analysis. It is made using the flask backend and reacts to the frontend. Supports interactive graphics, 3D graphics, heat maps, the correlation between characteristics, create custom columns and many more. He is the most famous and the favorite of all.
Installation
dtale can be installed using the following code:
pip install dtale
Exploratory data analysis with D-tale
Let's dive deeper into exploratory data analysis using this library. First, we have to write a code to launch the interactive d-tale application locally:
import dtale
import pandas as pd
df = pd.read_csv(‘data.csv’)
d = dtale.show(df)
d.open_browser()
Here we are importing pandas and give it. We are reading the dataset using the read_csv function () and finally we show the data in the browser locally using the function show and open the browser.
Display data the same way pandas do, but it has an additional feature, it has a menu in the upper left corner that allows us to do a lot of things and shows a count of columns and rows in our dataset.
The output of the above code is shown below:
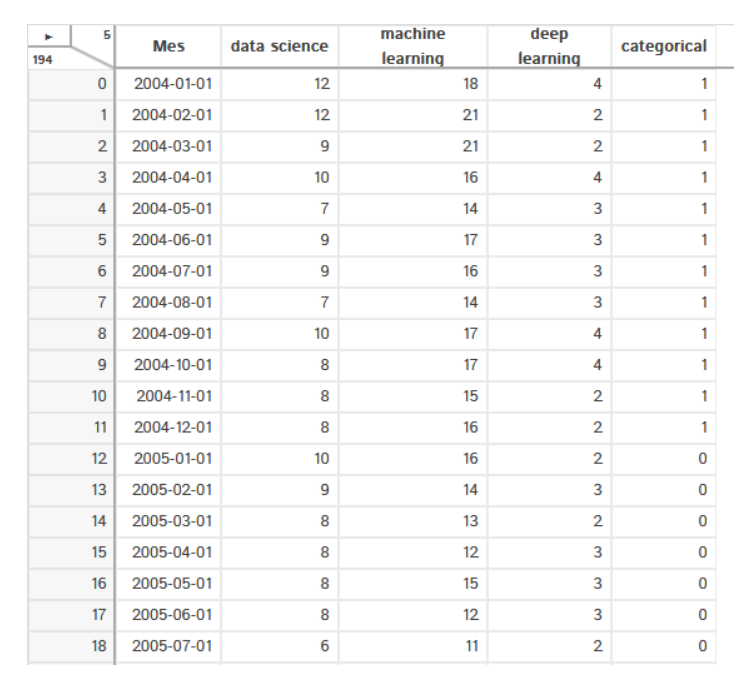
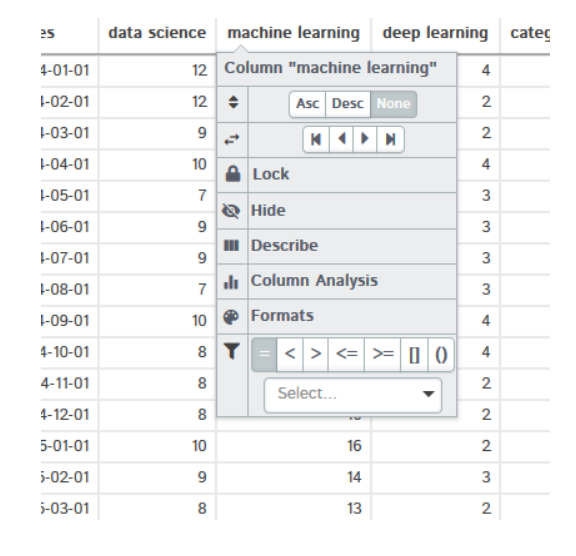
If you click on any column heading, drop-down menu will appear. It will give you many options, how to sort the data, describe the data set, column analysis and many more. You can also check this function on your own
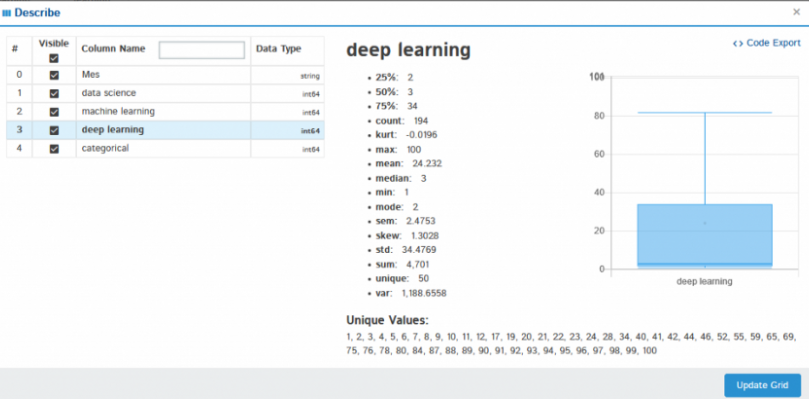
If you click Describe, shows the statistical analysis of the selected column as the mean, medianThe median is a statistical measure that represents the central value of a set of ordered data. To calculate it, the data is organized from lowest to highest and the number in the middle is identified. If there are an even number of observations, the two core values are averaged. This indicator is especially useful in asymmetric distributions, since it is not affected by extreme values...., maximum, minimum variance, standard deviation, quartiles and many more.
In the same way, you can try other functions on your own, as column analysis, formats, filters.
Magic of dtale: click the menu button and you will find all the available options
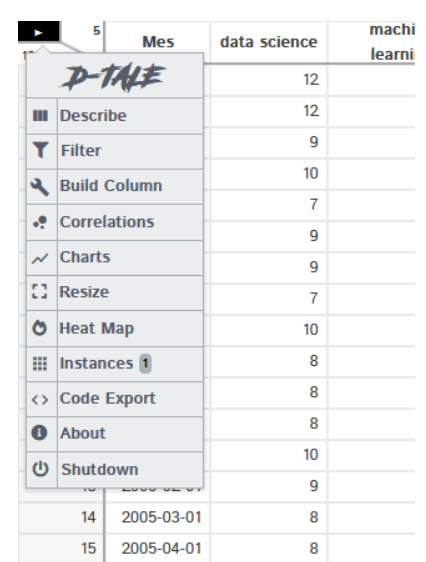
Not all features can be covered, but I am covering the most interesting.
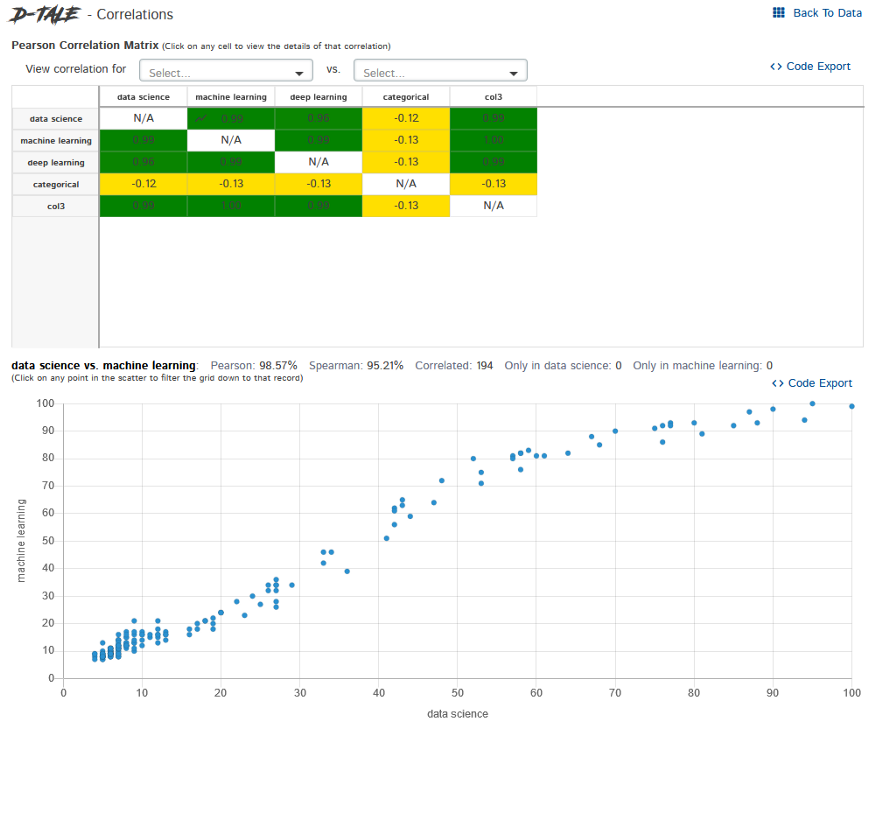
Correlations – It shows us how the columns are correlated with each other.
Graphics– Create customs charts as line charts, bar graphs, pie charts, stacked graphics, scatter diagrams, geological maps, etc.
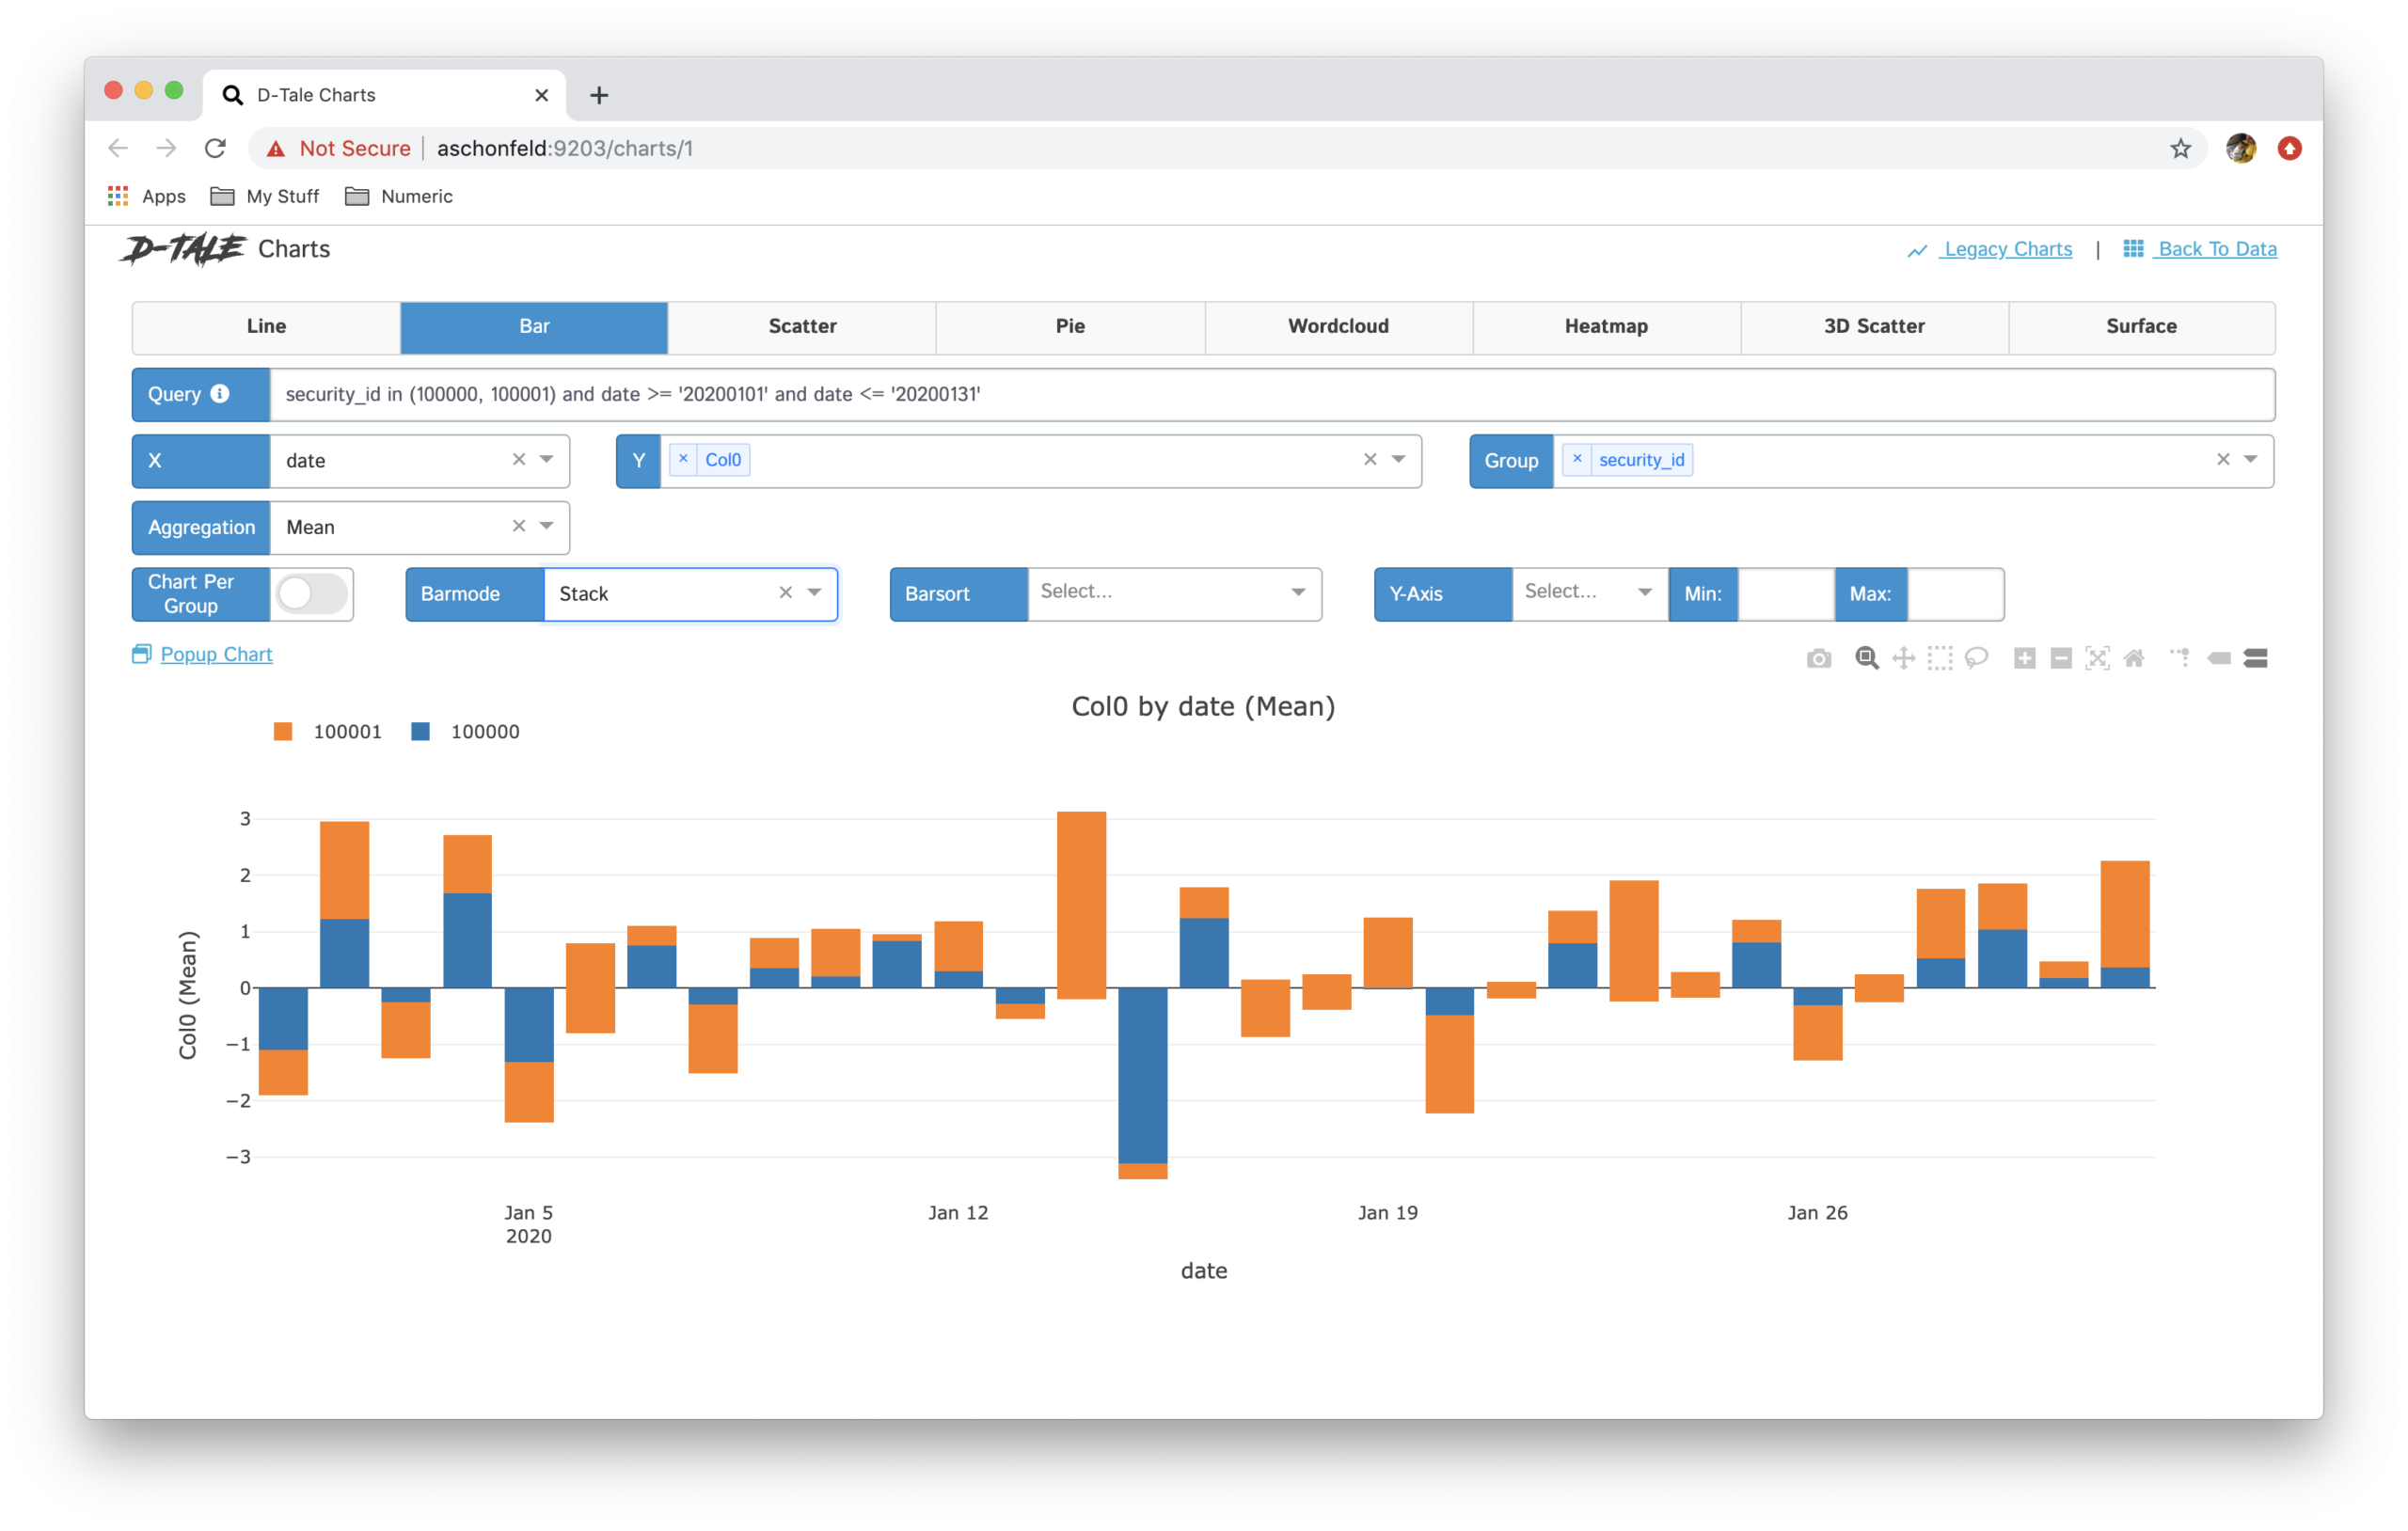
There are many options available in this library for data analysis. This tool is very useful and makes exploratory data analysis much faster compared to using traditional machine learning libraries like pandas, matplotlib, etc.
To obtain official documentation, check this link:
Pandas profiling
It is an open source library written in Python and generated interactive HTML reports and describes various aspects of the dataset. Key functionalities include handling of missing values, data set statistics as mean, fashion, median, asymmetry, standard deviation, etc., Charts such as histogramasHistograms are graphical representations that show the distribution of a dataset. They are constructed by dividing the range of values into intervals, O "Bins", and counting how much data falls in each interval. This visualization allows you to identify patterns, trends and variability of data effectively, facilitating statistical analysis and informed decision-making in various disciplines.... and correlations as well.
Installation
Pandas profiling can be installed using the following code:
pip install pandas-profiling
Exploratory Data Analysis Using Pandas Profiling
Let's dive deeper into exploratory data analysis using this library. I am using a sample dataset to get started with pandas profiling, check the following code:
#importing required packages
import pandas as pd
import pandas_profiling
import numpy as np

#importing the data
df = pd.read_csv('sample.csv')

#descriptive statistics
pandas_profiling.ProfileReport(df)
Below is the magic output of the above code
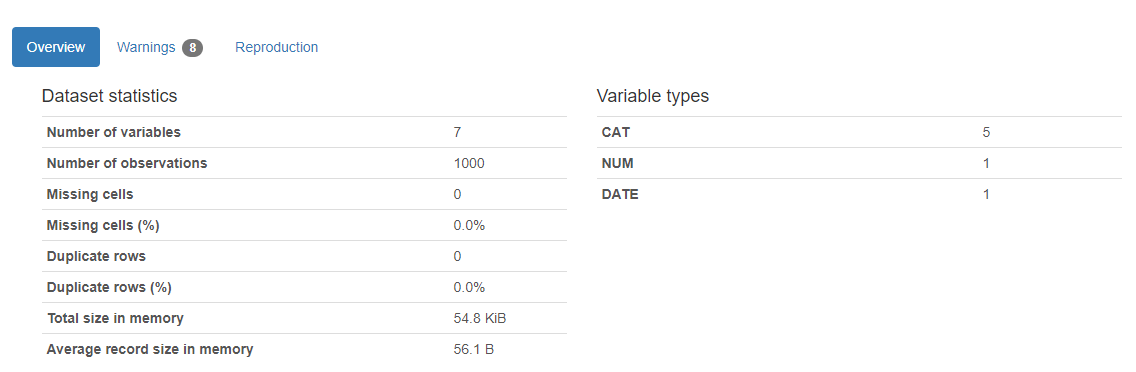
Here is the result. A report will appear and return how many variables are in our dataset, the number of rows, the missing cells in the dataset, the percentage of cells missing, the number and percentage of duplicate rows. Missing and duplicate cell data is very important to our analysis, as they describe the larger picture of the data set. The report also shows the total memory size. It also shows the types of variables on the right hand side of the output.
The variables section shows the analysis of a particular column. For example for the variableIn statistics and mathematics, a "variable" is a symbol that represents a value that can change or vary. There are different types of variables, and qualitative, that describe non-numerical characteristics, and quantitative, representing numerical quantities. Variables are fundamental in experiments and studies, since they allow the analysis of relationships and patterns between different elements, facilitating the understanding of complex phenomena.... Categorical, the following output will appear.
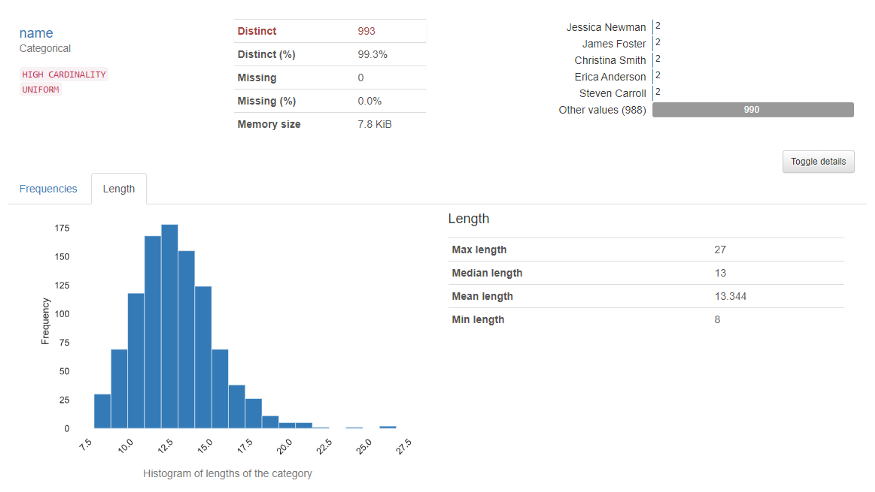
For him numeric variable, the following output will appear
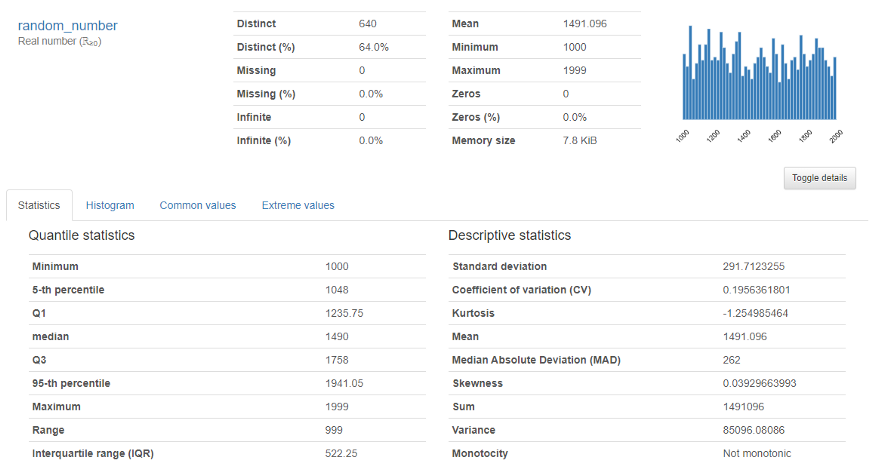
Provides in-depth analysis of numeric variables as quantile, media, median sum, variance, monotonicity, rank, curtosis, interquartile range and many more.
Correlations and interaction: Describe how variables are correlated with each other using. This data is badly needed by data scientists.
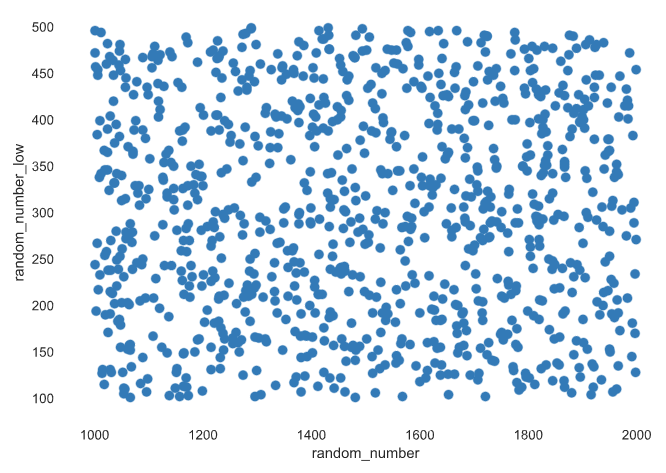
For more information, consult the official documentation:
Sweetviz
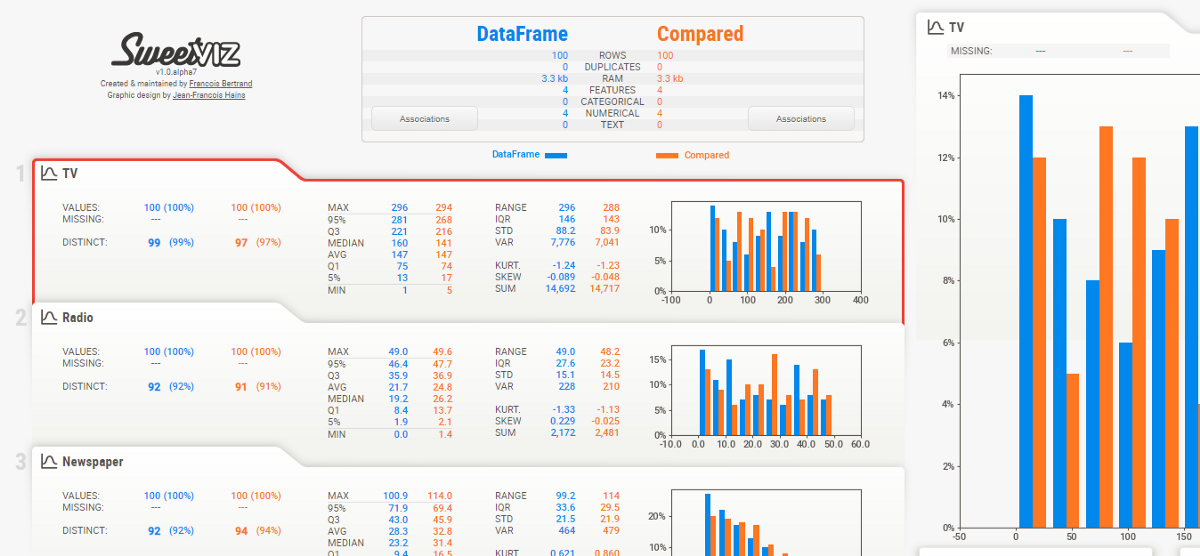
It is an open source Python library that used to get visualizations, which is useful in exploratory data analysis with just a few lines of code. The library can be used to visualize the variables and compare the data set.
Installation
This library can be installed using the following code:
pip install sweetviz
Exploratory data analysis with SweetViz
Let's dive deeper into exploratory data analysis using this library. I am using a sample dataset to get started, check the following code
import sweetviz
import pandas as pd
df = pd.read_csv('sample.csv')
my_report  = sweetviz.analyze([df,'Train'], target_feat="SalePrice")
my_report.show_html('FinalReport.html')
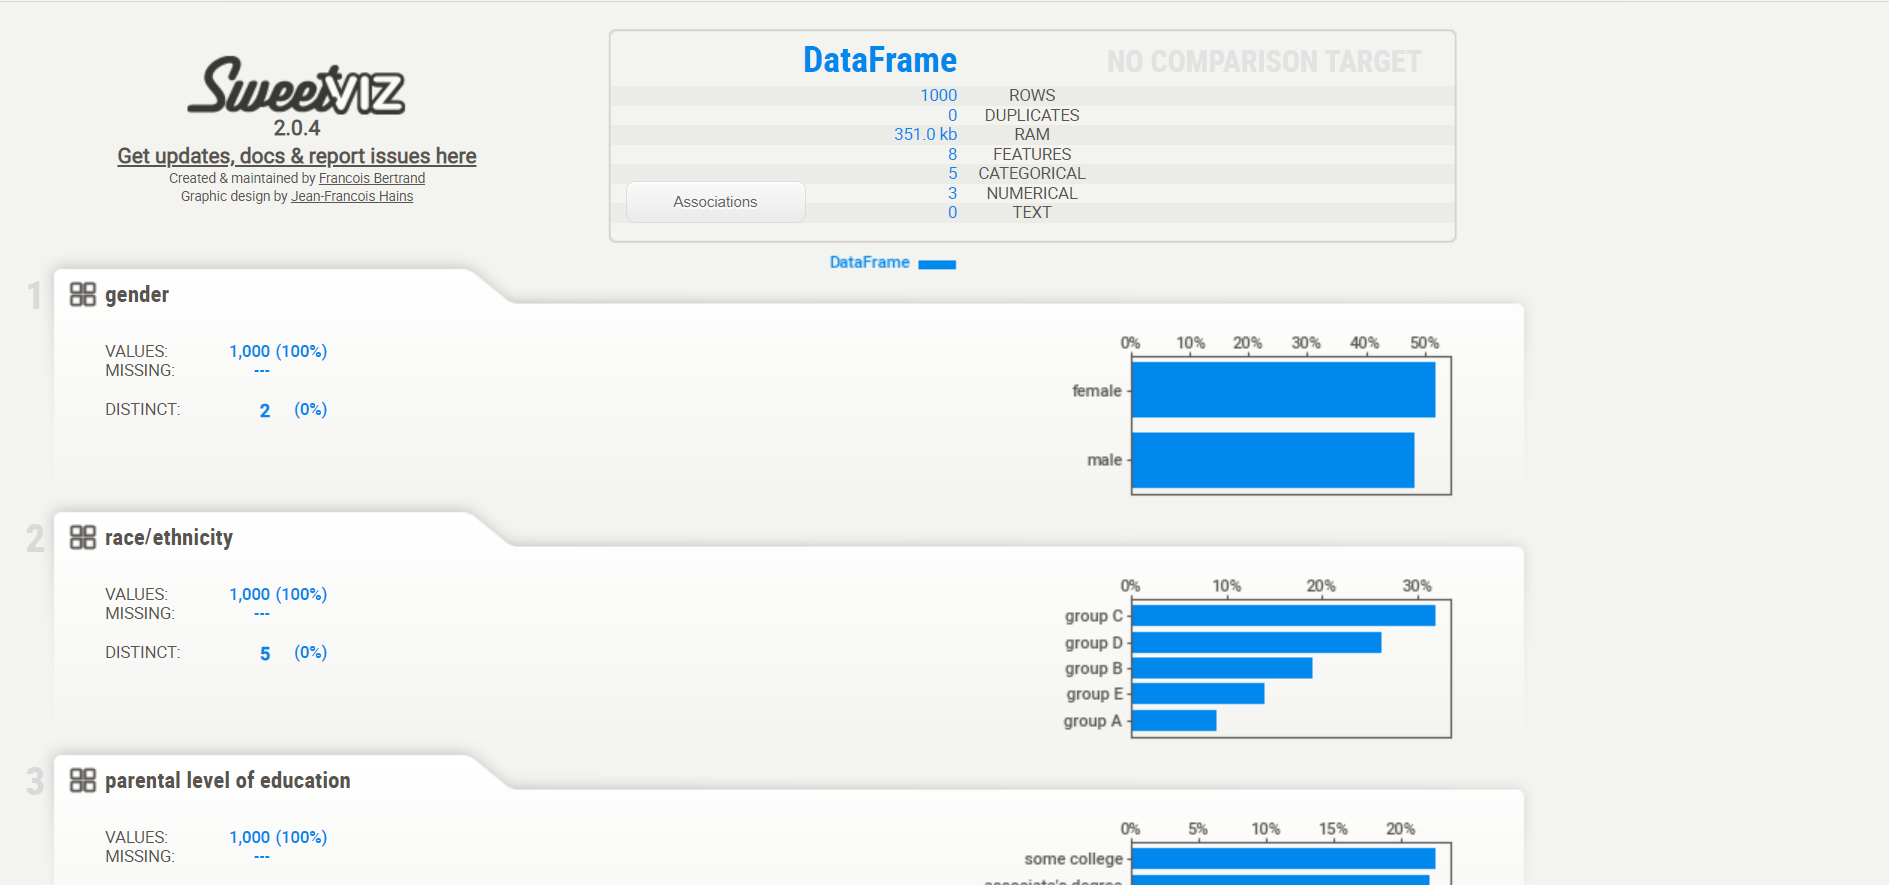
Final report:
For more information, consult the official documentation:
Autoviz
Means Display automatically. Visualization is possible with any size of the dataset with a few lines of code.
Installation
pip install autoviz
Display
Sample code:
from autoviz.AutoViz_Class import AutoViz_Class
AV = AutoViz_Class()
df = AV.AutoViz('sample.csv')
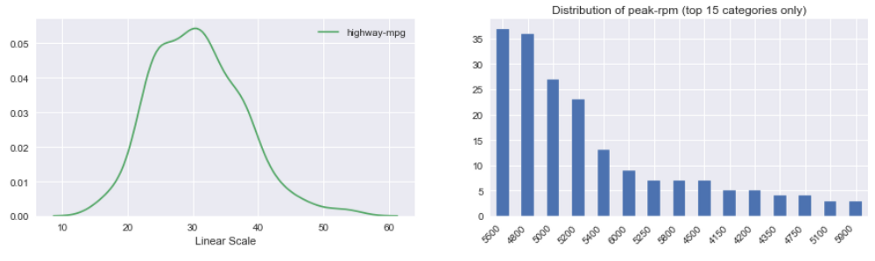
Continuous variable histogram:
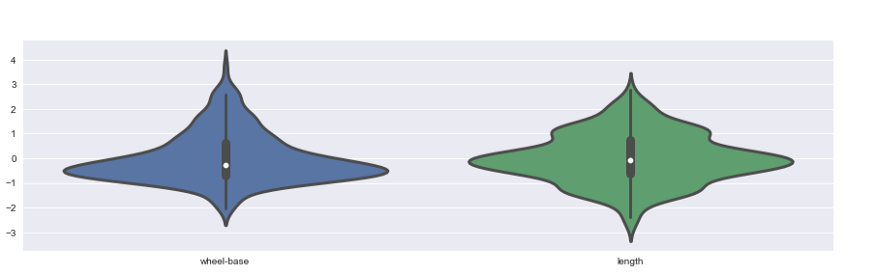
Violin frames:
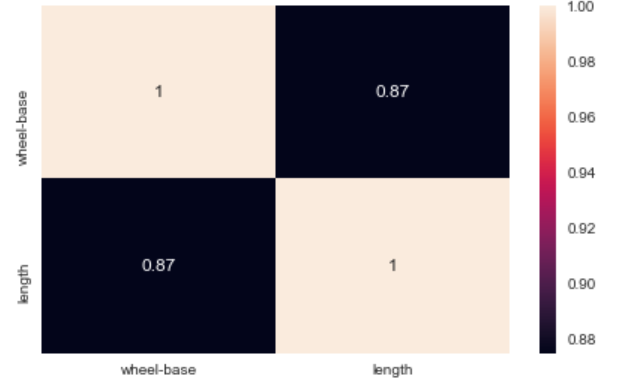
Heat mapa "heat map" is a graphical representation that uses colors to show the density of data in a specific area. Commonly used in data analytics, Marketing and behavioral studies, This type of visualization allows you to identify patterns and trends quickly. Through chromatic variations, Heat maps make it easier to interpret large volumes of information, helping to make informed decisions....:
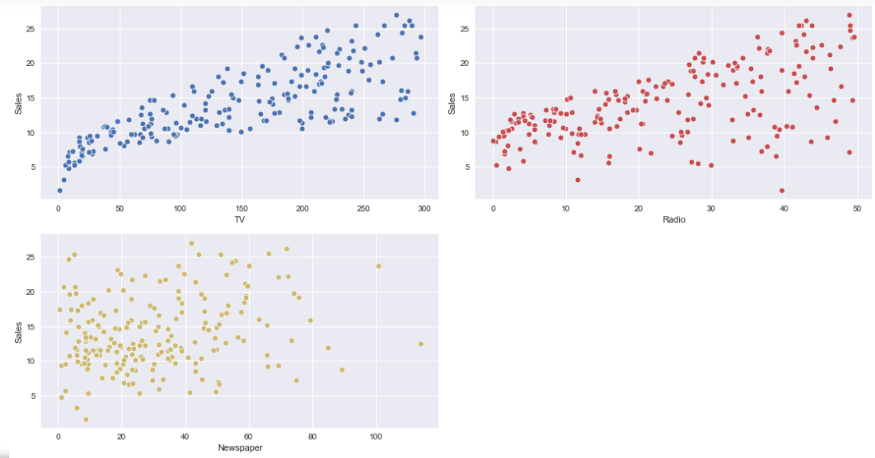
Scatter plotA scatter plot is a visual representation that shows the relationship between two numerical variables using points on a Cartesian plane. Each axis represents a variable, and the location of each point indicates its value in relation to both. This type of chart is useful for identifying patterns, Correlations and trends in the data, facilitating the analysis and interpretation of quantitative relationships....:
For more information, consult the official documentation:
Thanks for reading this. If you like this article, Share it with your friends. In case of any suggestion / doubt, comment below.
Email identification: [email protected]
Follow me on LinkedIn: LinkedIn
The media shown in this article is not the property of DataPeaker and is used at the author's discretion.





