
Overview
- Hadoop is among the most popular tools in the data engineering and Big Data space
- Here's an introduction to everything you need to know about the Hadoop ecosystem.
Introduction
Nowadays, we have more than 4 1 billion Internet users. In terms of raw data, this is what the picture looks like:
9.176 Tweets per second
1.023 Instagram images uploaded per second
5.036 Skype calls per second
86,497 Google searches per second
86,302 YouTube videos viewed per second
2.957.983 Emails sent per second
and much more…
That is the amount of data we are dealing with at the moment: amazing! It is estimated that at the end of 2020 will have produced 44 zettabytes of data. That's 44 * 10 ^ 21!
This huge amount of data generated at a fierce rate and in all kinds of formats is what today we call Big Data. But it is not feasible to store this data in the traditional systems that we have been using for more than 40 years. To handle this big data, we need a much more complex framework consisting of not just one, but in multiple components that handle different operations.
We refer to this framework as Hadoop and along with all of its components, call Ecosistema HadoopEl ecosistema Hadoop es un marco de trabajo de código abierto diseñado para el procesamiento y almacenamiento de grandes volúmenes de datos. Se compone de varios componentes clave, como Hadoop Distributed File System (HDFS) para almacenamiento y MapReduce para procesamiento. What's more, incluye herramientas complementarias como Hive, Pig y HBase, que facilitan la gestión, análisis y consulta de datos. Este ecosistema es fundamental en el ámbito del Big Data y la.... But because there are so many components within this Hadoop ecosystem, sometimes it can be really challenging to really understand and remember what each component does and where it fits in this big world.
Then, in this article, we will try to understand this ecosystem and break down its components.
Table of Contents
- Problem with traditional systems
- What is Hadoop?
- Components of the Hadoop ecosystem
- HDFSHDFS, o Hadoop Distributed File System, It is a key infrastructure for storing large volumes of data. Designed to run on common hardware, HDFS enables data distribution across multiple nodes, ensuring high availability and fault tolerance. Its architecture is based on a master-slave model, where a master node manages the system and slave nodes store the data, facilitating the efficient processing of information.. (Distributed File SystemA distributed file system (DFS) Allows storage and access to data on multiple servers, facilitating the management of large volumes of information. This type of system improves availability and redundancy, as files are replicated to different locations, reducing the risk of data loss. What's more, Allows users to access files from different platforms and devices, promoting collaboration and... Hadoop)
- Small map
- HILO
- HBaseHBase is a NoSQL database designed to handle large volumes of data distributed in clusters. Based on the column model, Enables fast, scalable access to information. HBase easily integrates with Hadoop, making it a popular choice for applications that require massive data storage and processing. Its flexibility and ability to grow make it ideal for big data projects....
- Pork
- Hive
- SqoopSqoop es una herramienta de código abierto diseñada para facilitar la transferencia de datos entre bases de datos relacionales y el ecosistema Hadoop. Permite la importación de datos desde sistemas como MySQL, PostgreSQL y Oracle a HDFS, así como la exportación de datos desde Hadoop a estas bases de datos. Sqoop optimiza el proceso mediante la paralelización de las operaciones, lo que lo convierte en una solución eficiente para el...
- Artificial canal
- Kafka
- Zookeeper
- Spark – spark
- Stages of Big Data processing
Problem with traditional systems
By traditional systems, I mean systems like relational databases and data warehouses. Organizations have been using them for the past 40 years to store and analyze your data. But the data that is generated today cannot be handled by these databases for the following reasons:
- Most of the data generated today is semi-structured or unstructured. But traditional systems have been designed to handle only structured data that has well-designed rows and columns.
- Relationship databases are vertically scalable, which means you need to add more processing, memory and storage to the same system. This can be very expensive
- The data stored today is in different silos. Collecting them and analyzing them for patterns can be a very difficult task.
Then, How do we handle Big Data? This is where Hadoop comes in!!
What is Hadoop?
People at Google also faced the challenges mentioned above when they wanted to rank pages on the internet.. They found relational databases to be very expensive and inflexible. Then, came up with their own novel solution. They created the Google file system (GFS).
GFS is a distributed file system that overcomes the drawbacks of traditional systems. Runs on inexpensive hardware and provides parallelization, scalability and reliability. This set the springboard for the evolution of Apache Hadoop.
Apache Hadoop is an open source framework based on Google's filesystem that can handle big data in a distributed environment.. This distributed environment is made up of a group of machines working closely together to give the impression of a single machine in operation..
Here are some of the important Hadoop properties you should know about:
- Hadoop is highly scalable because it handles the data in a distributed way
- Compared to vertical scaling in RDBMS, Hadoop offers horizontal scale
- Create and save data replicas by doing so fault tolerant
- Is economic ya que todos los nodos del clusterA cluster is a set of interconnected companies and organizations that operate in the same sector or geographical area, and that collaborate to improve their competitiveness. These groupings allow for the sharing of resources, Knowledge and technologies, fostering innovation and economic growth. Clusters can span a variety of industries, from technology to agriculture, and are fundamental for regional development and job creation.... son hardware básico que no es más que máquinas económicas
- Hadoop uses the data locality concept to process the data on the nodes where it is stored instead of moving the data across the network, thus reducing traffic
- May handle any kind of data: structured, semi-structured and unstructured. This is extremely important today because most of our data (emails, Instagram, Twitter, IoT devices, etc.) do not have a defined format.
Now, Let's look at the components of the Hadoop ecosystem.
Components of the Hadoop ecosystem
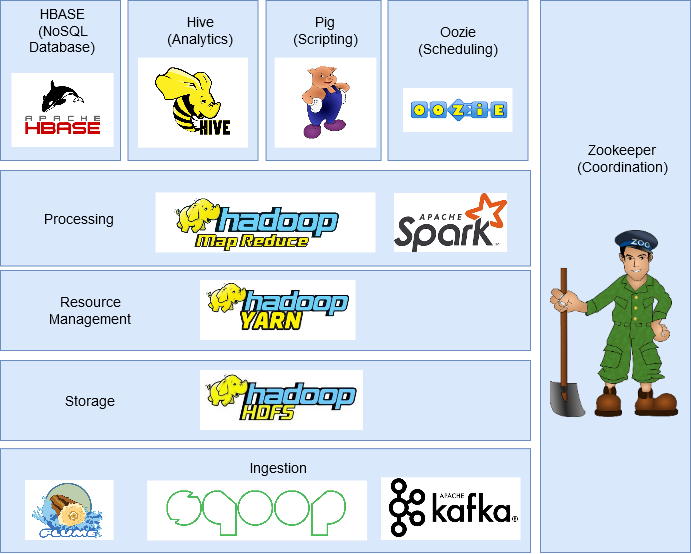
In this section, we will discuss the different components of the Hadoop ecosystem.
HDFS (Hadoop distributed file system)
It is the storage component of Hadoop that stores data in the form of files.
Each file is divided into blocks of 128 MB (configurable) and stores them on different machines in the cluster.
It has a master-slave architecture with two main components: NodeNodo is a digital platform that facilitates the connection between professionals and companies in search of talent. Through an intuitive system, allows users to create profiles, share experiences and access job opportunities. Its focus on collaboration and networking makes Nodo a valuable tool for those who want to expand their professional network and find projects that align with their skills and goals.... de nombre y Nodo de datos.
- Name node is the main node and there is only one per cluster. Your task is to know where each block that belongs to a file is located in the cluster.
- Data node is he Slave NodeThe "Slave Node" is a concept used in networks and distributed systems that refers to a device or component that operates under the direction of a main node or "Master Node". This type of architecture allows for centralized management, where the slave node executes specific tasks, collecting data or running processes, while the master node coordinates the operations of the entire system to optimize performance and efficiency.... que almacena los bloques de datos y hay más de uno por clúster. Your task is to retrieve the data when necessary. Stays in constant contact with the Name node through heartbeats.
Small map
To handle Big Data, Hadoop is based on Algoritmo MapReduce introduced by Google and facilitates the distribution of a job and its execution in parallel in a cluster. Basically, splits a single task into multiple tasks and processes them on different machines.
In simple terms, works in a divide and conquer way and runs processes on machines to reduce network traffic.
It has two important phases: Map and Zoom Out.
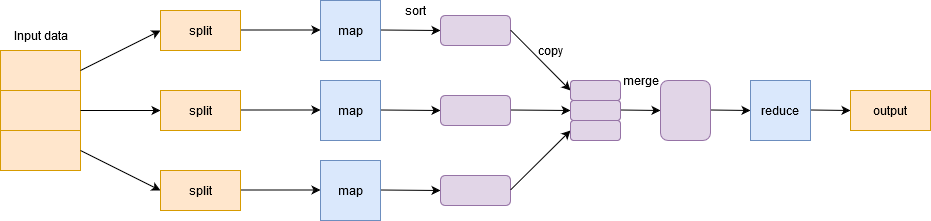
Cartographic phase filter, group and order the data. The input data is divided into multiple divisions. Each map task works on a parallel data slice on different machines and generates a key-value pair. The output of this phase is actuated by the reduce homework and is known as the Reduce phase. Add the data, summarizes the result and stores it in HDFS.
HILO
YARNYARN is a package manager for JavaScript that allows the efficient installation and management of dependencies in development projects. Powered by Facebook, It is characterized by its speed and security compared to other managers. YARN uses a cache system to optimize installations and provides a lock file to ensure consistency of dependency versions across different development environments.... o Yet Another Resource Negotiator administra los recursos en el clúster y administra las aplicaciones a través de Hadoop. Allows data stored in HDFS to be processed and executed by various data processing engines, as batch processing, flow processing, interactive processing, graphics processing and many more. This increases efficiency with the use of YARN.
HBase
HBase is a NoSQL databaseNoSQL databases are data management systems that are characterized by their flexibility and scalability. Unlike relational databases, use unstructured data models, as documents, key-value or graphics. They are ideal for applications that require handling large volumes of information and high availability, such as in the case of social networks or cloud services. Its popularity has grown in... basada en columnas. It runs on HDFS and can handle any type of data. Allows real-time processing and read operations / random writes performed on the data.
Pork
PigThe Pig, a domesticated mammal of the Suidae family, It is known for its versatility in agriculture and food production. Native to Asia, Its breeding has spread all over the world. Pigs are omnivores and have a high capacity to adapt to various habitats. What's more, play an important role in the economy, Providing meat, leather and other derived products. Their intelligence and social behavior are also ... fue desarrollado para analizar grandes conjuntos de datos y supera la dificultad de escribir mapas y reducir funciones. It consists of the components: Pig Latin y Pig Engine.
Pig Latin is SQL-like scripting language. Pig Engine is the runtime that Pig Latin runs on. Internally, el código escrito en Pig se convierte en funciones de MapReduceMapReduce is a programming model designed to efficiently process and generate large data sets. Powered by Google, This approach breaks down work into smaller tasks, which are distributed among multiple nodes in a cluster. Each node processes its part and then the results are combined. This method allows you to scale applications and handle massive volumes of information, being fundamental in the world of Big Data.... and makes it very easy for programmers who are not proficient in Java.
Hive
HiveHive is a decentralized social media platform that allows its users to share content and connect with others without the intervention of a central authority. Uses blockchain technology to ensure data security and ownership. Unlike other social networks, Hive allows users to monetize their content through crypto rewards, which encourages the creation and active exchange of information.... is a distributed data storage system developed by Facebook. Allows easy reading, writing and managing files in HDFS. It has its own query language for the purpose known as Hive Querying Language (HQL), which is very similar to SQL. This makes it very easy for programmers to write MapReduce functions using simple HQL queries..
Sqoop
Many applications still store data in relational databases, which makes them a Data SourceA "Data Source" refers to any place or medium where information can be obtained. These sources can be both primary and, such as surveys and experiments, as secondary, as databases, academic articles or statistical reports. The right choice of a data source is crucial to ensure the validity and reliability of information in research and analysis.... very important. Therefore, Sqoop plays an important role in bringing data from relational databases to HDFS.
Commands written in Sqoop are internally converted into MapReduce tasks that run in HDFS. Works with almost all relational databases like MySQL, Postgres, SQLite, etc. Can also be used to export data from HDFS to RDBMS.
Artificial canal
FlumeFlume is an open-source software designed for data collection and transport. Use a flow-based approach, allowing data to be moved from various sources to storage systems such as Hadoop. Its modular and scalable architecture makes it easy to integrate with multiple data sources, which makes it a valuable tool for the processing and analysis of large volumes of information in real time.... is an open-source service, reliable and available that is used to collect, efficiently add and move large amounts of data from multiple data sources to HDFS. Can collect data in real time and in batch mode. Has a flexible architecture and is fault tolerant with multiple recovery mechanisms.
Kafka
There are many applications that generate data and a proportional number of applications that consume that data. But connecting them individually is a difficult task. That's where Kafka comes in. It is among the applications that generate data (producers) and applications that consume data (consumers).
Kafka is distributed and partitioned, replicationReplication is a fundamental process in biology and science, which refers to the duplication of molecules, cells or genetic information. In the context of DNA, Replication ensures that each daughter cell receives a complete copy of the genetic material during cell division. This mechanism is crucial for growth, Development and maintenance of the organisms, as well as for the transmission of hereditary characteristics in future generations.... with built-in fault tolerance. It can handle streaming data and also allows companies to analyze data in real time.
Oozie
OozieOozie is a workflow management system oriented to data flows, designed to coordinate jobs in Hadoop. Allows users to define and schedule complex jobs, integrating MapReduce tasks, Pig, Hive and others. Oozie uses an XML-based approach to describe workflows and their execution, facilitating the orchestration of processes in big data environments. Its functionality enhances efficiency in processing.. it is a workflow programming system that allows users to link jobs written in various platforms like MapReduce, Hive, Pig, etc. With Oozie you can schedule a job in advance and can create a pipeline of individual jobs to run sequentially or in parallel to accomplish a larger task.. For instance, you can use Oozie to perform ETL operations on data and then save the output to HDFS.
Zookeeper
In a Hadoop cluster, coordinating and synchronizing nodes can be a challenging task. Therefore, Zookeeper"Zookeeper" is a simulation video game released in 2001, where players take on the role of a zookeeper. The main mission is to manage and care for various species of animals, ensuring your well-being and the satisfaction of visitors. Throughout the game, Users can design and customize their zoo, facing challenges including food, the habitat and health of animals.... it is the perfect tool to solve the problem.
It is an open source service, distributed and centralized to maintain configuration information, to name, provide distributed synchronization and provide group services across the cluster.
Spark – spark
Spark is an alternative framework to Hadoop built in Scala, but it supports various applications written in Java, Python, etc. Compared to MapReduce, provides in-memory processing that represents faster processing. In addition to the batch processing offered by Hadoop, can also handle real-time processing.
What's more, Spark has its own ecosystem:
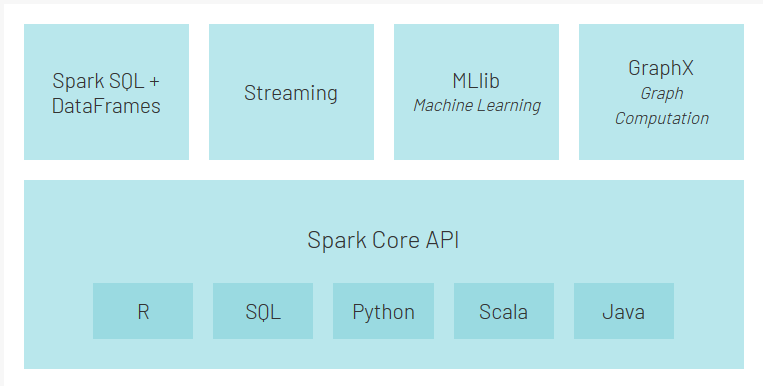
- Spark Core is the main runtime for Spark and other APIs built on top of it
- API de Spark SQL allows you to query structured data stored in DataFrames or Hive tables
- Streaming API allows Spark to handle data in real time. It can be easily integrated with a variety of data sources such as Flume, Kafka y Twitter.
- MLlib is a scalable machine learning library that will allow you to perform data science tasks while taking advantage of Spark properties at the same time
- GraphX is a graphics calculation engine that allows users to build, interactively transform and reason on structured data into scaled graphs and comes with a library of common algorithms
Stages of Big Data processing
With so many components within the Hadoop ecosystem, can be quite intimidating and difficult to understand what each component does. Therefore, it's easier to group some of the components based on where they are in the Big Data processing stage.
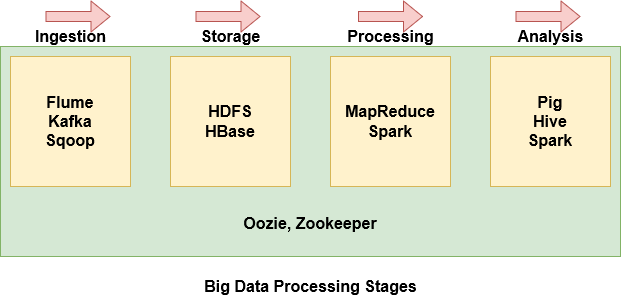
- Flume, Kafka and Sqoop are used to ingest data from external sources into HDFS
- HDFS is Hadoop's storage drive. Even data imported from Hbase is stored in HDFS
- MapReduce and Spark are used to process the data in HDFS and perform various tasks
- Pig, Hive and Spark are used to analyze the data.
- Oozie helps schedule tasks. Since it works with various platforms, used in all stages.
- Zookeeper synchronizes the cluster nodes and is also used in all stages.
Final notes
I hope this article has been useful to understand Big Data, why traditional systems can't handle it and what are the important components of the Hadoop ecosystem.
I encourage you to check out some more articles on Big Data that you may find helpful:





