
This article was published as part of the Data Science Blogathon
Introduction
Data is everywhere in today's data world and we can only benefit from it if we can extract information from the data. Data visualization is the most visually appealing aspect of data analysis because it allows us to interact with the data. It is that magical technique to convey information to large groups of people with a single glance and create interesting stories from data.. Pandas is one of the most popular and widely used data analysis tools in Python. It also has a built-in plotting feature for samples. But nevertheless, when it comes to interactive visualization, Python users who don't have front-end engineering skills may have some challenges, like many libraries, as D3, chart.js, requiring some JavaScript knowledge. Plotly and Twins are helpful at this point.
When there is a large amount of data and companies have difficulty extracting critical information from it, data visualization plays an important role in making critical business decisions.
Plotly is a graphics library built on top of d3.js that can be used directly with Pandas data frames thanks to another library called Cufflinks.
We will show you how to use Plotly interactive charts with Pandas data frames in this quick tutorial.. To keep things simple, we will use Jupyter Notebook (installed using Anaconda Distribution with Python) and the famous Titanic dataset.
Data visualization in Python
After completing data cleaning and manipulation, the next step in the data analysis process is to extract meaningful insights and conclusions from the data, what can be achieved by graphs and tables. Python has several libraries that can be used for this purpose. As usual, we are only taught about the two libraries matplotlib and seaborn. These libraries include tools for creating line charts, pie charts, bar charts, box plotsBox Diagrams, Also known as box and whisker diagrams, are statistical tools that represent the distribution of a dataset. These diagrams show the median, quartiles and outliers, allowing data variability and symmetry to be visualized. They are useful in comparison between different groups and in exploratory analysis, making it easier to identify trends and patterns in the data.... y una variedad de otros diagramas. You are probably wondering why we need other libraries for data visualization if we already have matplotlib and seaborn. When I first heard about the plot and the twins, I had the same question in my head.
Plotly
Plotly's most recent release was 5.1.0, while the one with twins was 0.17.5. Because older versions of cufflinks are not compatible with newly released plotting versions, it is essential to update both packages at the same time or find compatible versions. In Anaconda Prompt, run the following commands to install plotly (o en Terminal itself uses OS or Ubuntu)
Plotly is an open source and graphics library that enables interactive plotting. Python, R, MATLAB, Arduino and REST, among others, are among the programming languages supported by the library.
Cufflink is a Python library that connects plotly and pandas, allowing us to draw graphs directly on data frames. It is essentially a plugin.
Chart charts are interactive, which allows us to scroll above the values, zoom in and out of charts and identify outliers in the dataset. The Matplotlib and Seaborn Letters, Secondly, they are static; we can't zoom in or out the image, and all the values in the chart are not detailed. The most important feature of Plotly is that it allows us to create dynamic web graphics directly from Python, what is not possible with matplotlib. We can also make interactive graphics and animations from geographic data, scientists, statistics and financials using plotly.
Install on pc “plot “ Y “Twins“ using an anaconda environment
conda install -c plotly plotly
conda install -c conda-forge cufflinks-py
o using pip
pip install plotly --upgrade
pip install cufflinks --upgrade
Loading Libraries
Pandas Libraries, Plotly and Cufflinks will load first. Because plotly is an online platform, requiere una credencial de inicio de we can apply transformations once for the whole cluster and not for different partitions separatelyThe "Session" It is a key concept in the field of psychology and therapy. Refers to a scheduled meeting between a therapist and a client, where thoughts are explored, Emotions and behaviors. These sessions can vary in length and frequency, and its main purpose is to facilitate personal growth and problem-solving. The effectiveness of the sessions depends on the relationship between the therapist and the therapist.. para usarla en línea. We will use offline mode in this article, which is enough for Jupyter Notebook.
#importing Pandas
import pandas as pd
#importing plotly and cufflinks in offline mode
import cufflinks as cf
import plotly.offline
cf.go_offline()
cf.set_config_file(offline=False, world_readable=True)
Loading dataset
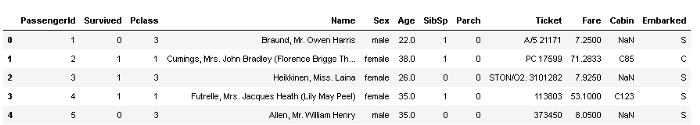
We mentioned that we will use the Titanic dataset, what can you get from this kaggle_link. Only the train.csv file will be used.
df=pd.read_csv("train.csv")
df.head()
Histogram
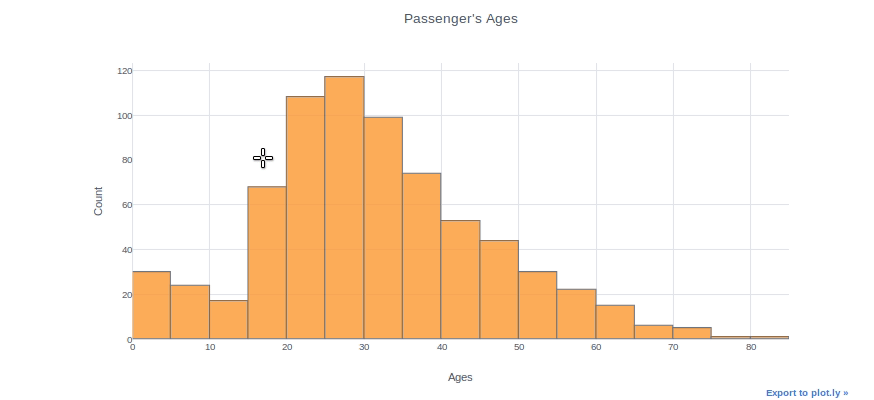
The histogramasHistograms are graphical representations that show the distribution of a dataset. They are constructed by dividing the range of values into intervals, O "Bins", and counting how much data falls in each interval. This visualization allows you to identify patterns, trends and variability of data effectively, facilitating statistical analysis and informed decision-making in various disciplines.... se pueden utilizar para inspeccionar las distribuciones de una característica, as the feature “Age” in this case. We simply use the (dataframe[“column name”]) to select a column and then add the iplot function. As an example, we can specify the size of the container, the topic, the title and names of the axes. With the command “help (df.iplot)”, puede ver todos los parametersThe "parameters" are variables or criteria that are used to define, measure or evaluate a phenomenon or system. In various fields such as statistics, Computer Science and Scientific Research, Parameters are critical to establishing norms and standards that guide data analysis and interpretation. Their proper selection and handling are crucial to obtain accurate and relevant results in any study or project.... del parámetro iplot.
df["Age"].iplot(kind="histogram", bins=20, theme="white", title="Passenger's Ages",xTitle="Ages", yTitle ="Count")
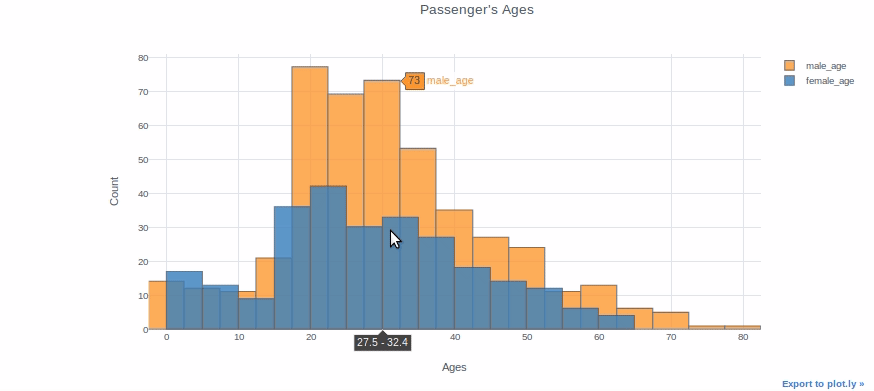
You can plot two different distributions as two different columns if you want to compare them. For instance, we will plot the ages of the male and female passengers on the same parcel.
df["male_age"]=df[df["Sex"]=="male"]["Age"]
df["female_age"]=df[df["Sex"]=="female"]["Age"]df[["male_age","female_age"]].iplot(kind="histogram", bins=20, theme="white", title="Passenger's Ages",
         xTitle="Ages", yTitle ="Count")
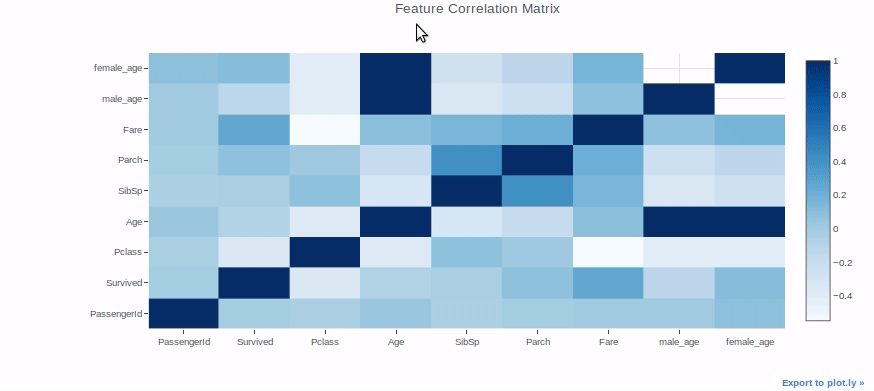
Heat mapa "heat map" is a graphical representation that uses colors to show the density of data in a specific area. Commonly used in data analytics, Marketing and behavioral studies, This type of visualization allows you to identify patterns and trends quickly. Through chromatic variations, Heat maps make it easier to interpret large volumes of information, helping to make informed decisions....
Heatmaps can be used for a variety of purposes, but we will use them to check the correlation between features in a data set as an example.
Box plot
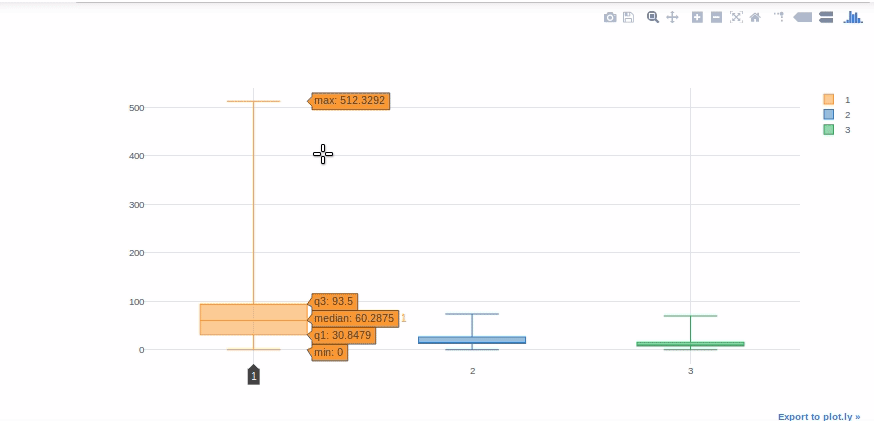
Box plots are extremely useful for quickly interpreting skewness in data, outliers and quartile ranges. We will now use a box plot to show the distribution of “Rate” for each class of Titanic.
#we will get help from pivot tables to get Fare values in different columns for each class.
df[['Pclass', 'Fare']].pivot(columns="Pclass", values="Fare").iplot(kind='box')
Scatter plotA scatter plot is a visual representation that shows the relationship between two numerical variables using points on a Cartesian plane. Each axis represents a variable, and the location of each point indicates its value in relation to both. This type of chart is useful for identifying patterns, Correlations and trends in the data, facilitating the analysis and interpretation of quantitative relationships....
Scatterplots are commonly used to visualize the relationship between two numerical variables. For variables “Rate” Y “Age”, we will use scatter diagrams. "Categories" allows us to show the variables of a selected characteristic in various colors (sex of the passengers in this case).
df.iplot(kind="scatter", theme="white",x="Age",y ="Fare",
            categories="Sex")
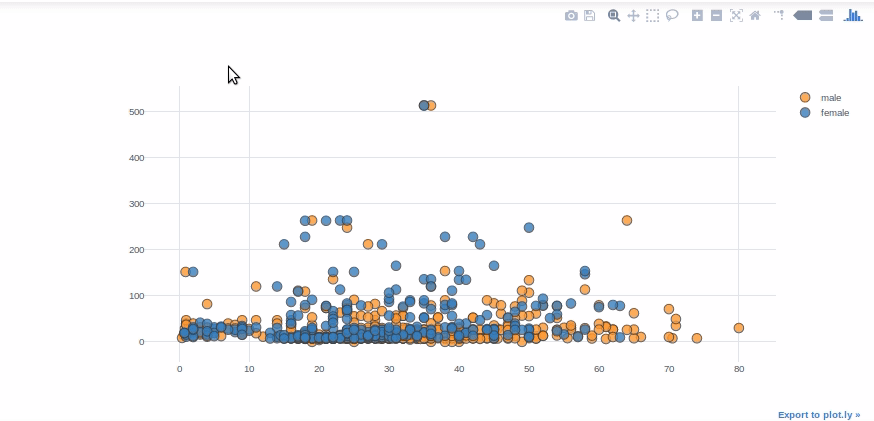
a quick reminder: the parameter “categories” must be a string or column of type float64. For instance, in the example of the bubble chart, should convert column “Survived” of type integer in float64 or string.
Bubble chart
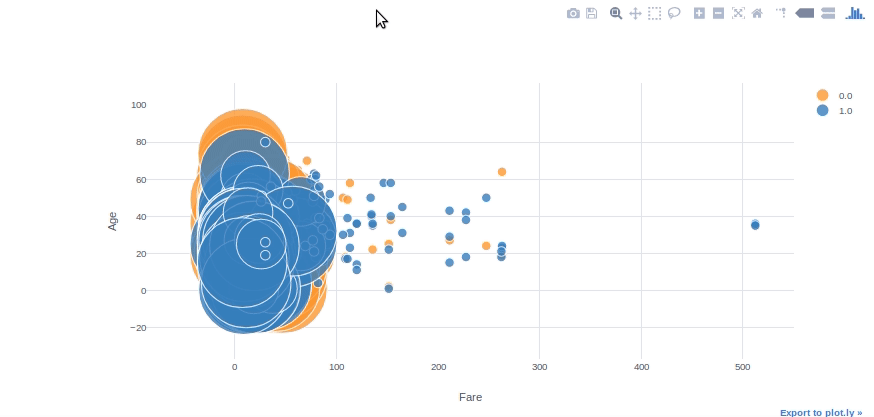
We can use bubble charts to see multiple variable relationships at the same time. With the parameters of “categories” Y “size” in the graph, we can easily adjust the color and size subcategories. With the parameter “text”, we can also specify the floating text column.
#converting Survived column to float64 to be able to use in plotly
df[['Survived']] = df[['Survived']].astype('float64', copy=False)df.iplot(kind='bubble', x="Fare",y ="Age",categories="Survived", size="Pclass", text="Name", xTitle="Fare", yTitle ="Age")
Bar graphicThe bar chart is a visual representation of data that uses rectangular bars to show comparisons between different categories. Each bar represents a value and its length is proportional to it. This type of chart is useful for visualizing and analyzing trends, facilitating the interpretation of quantitative information. It is widely used in various disciplines, such as statistics, Marketing and research, due to its simplicity and effectiveness....
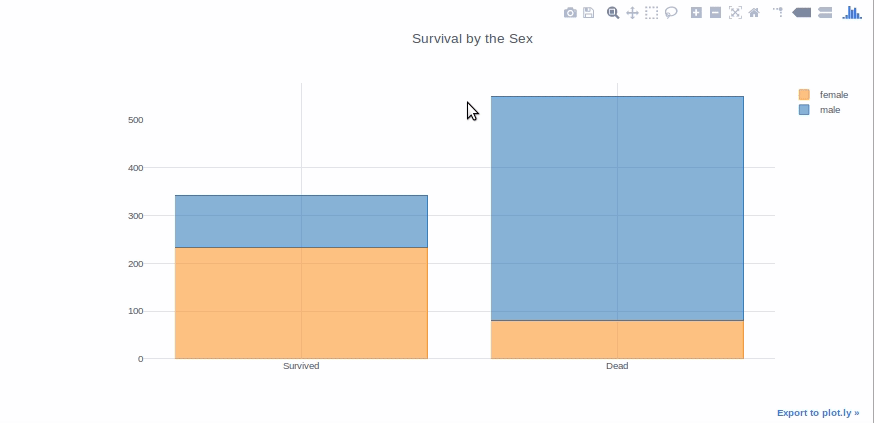
Bar charts are good for presenting data from different groups that are compared to each other. What's more, can be used stacked to show different variable effects. We will make a bar graph to show the count of surviving passengers by sex.
survived_sex = df[df['Survived']==1]['Sex'].value_counts()
dead_sex = df[df['Survived']==0]['Sex'].value_counts()
df1 = pd.DataFrame([survived_sex,dead_sex])
df1.index = ['Survived','Dead']
df1.iplot(kind='bar',bar fashion ="stack", title="Survival by the Sex")
I tried to explain everything as simple as possible. I hope it is easier for newcomers to understand the plot.
Plotly also provides scientific charts, 3D graphics, maps and animations. You can visit the documentation of plotly here for more details.
Take a look at EDA – Exploratory Data Analysis with Python Pandas and SQL CLICK TO READ
EndNote
Thank you for reading!
Hope you enjoyed the article and increased your knowledge.
Please feel free to contact me about Email
Anything not mentioned or do you want to share your thoughts? Feel free to comment below and I'll get back to you.
About the Author
Hardikkumar M. Dhaduk
Data analyst | Digital data analysis specialist | Data Science Student
Connect with me on Linkedin
Connect with me on Github
The media shown in this article is not the property of DataPeaker and is used at the author's discretion.





