
This article was published as part of the Data Science Blogathon
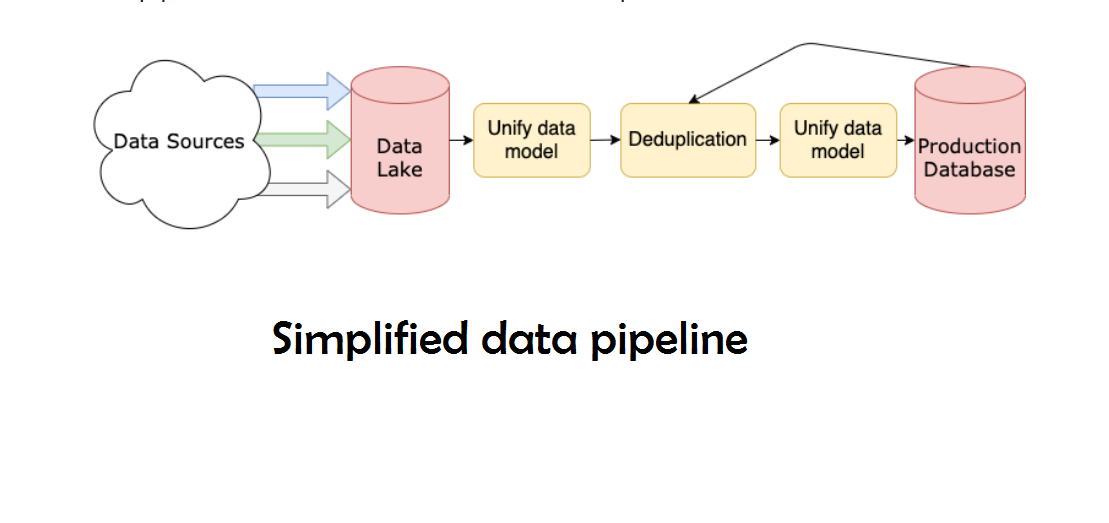
Take on the job of a data engineer, extracting data from multiple sources of file formats, transforming them into particular data types and loading them into a single source for analysis. Shortly after reading this article, with the help of several practical examples, you will be able to test your skills implementing web scraping and extracting data with API. With Python and data engineering, you can start collecting huge data sets from many sources and transform it into a single primary source or start crawling the web for useful business insights.
Synopsis:
- Why is data engineering more reliable?
- ETL cycle process
- Step by step Extract, to transform, charging function
- About data engineering
- About me
- Conclution
Why is data engineering more reliable?
It is a more reliable and fastest growing technological occupation in the current generation, as it concentrates more on web scraping and data set tracking.
Process (ETL cycle):
Ever wonder how data from many sources was integrated to create a single source of information? Batching is a way to collect data and learn more about “how to explore a type of batching” called Extract, Transform and Load.
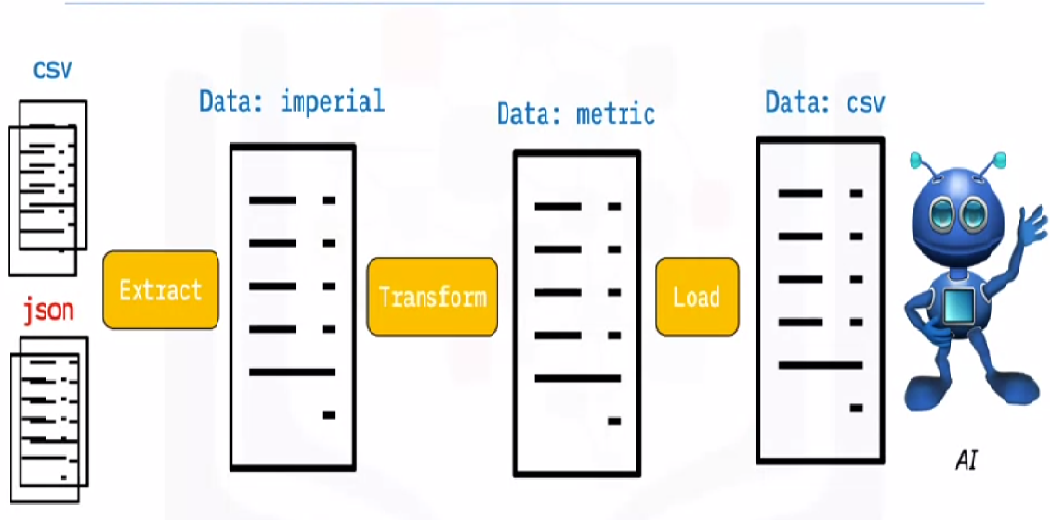
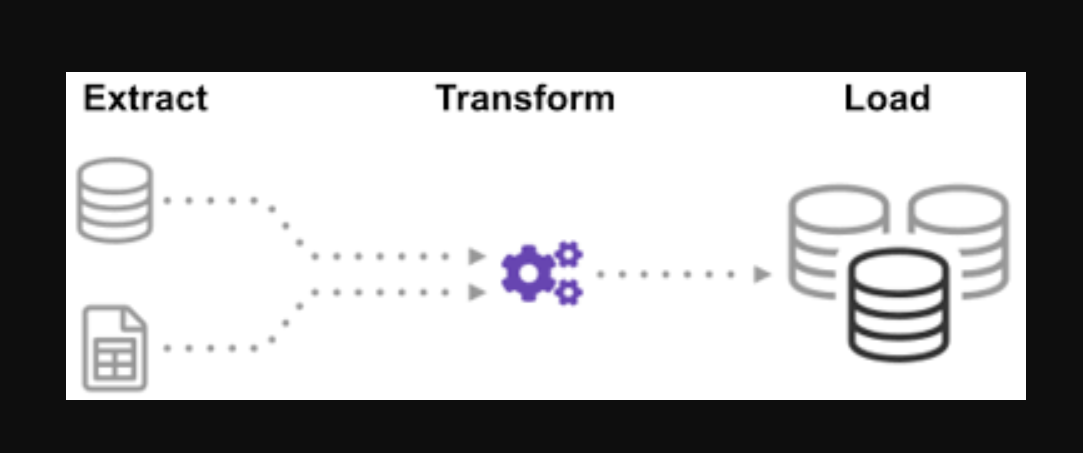
ETL is the process of extracting large volumes of data from a variety of sources and formats and converting them into a single format before placing them in a databaseA database is an organized set of information that allows you to store, Manage and retrieve data efficiently. Used in various applications, from enterprise systems to online platforms, Databases can be relational or non-relational. Proper design is critical to optimizing performance and ensuring information integrity, thus facilitating informed decision-making in different contexts.... or in a destination file.
Some of your data is stored in CSV files, while others are stored in files JSONJSON, o JavaScript Object Notation, It is a lightweight data exchange format that is easy for humans to read and write, and easy for machines to analyze and generate. It is commonly used in web applications to send and receive information between a server and a client. Its structure is based on key-value pairs, making it versatile and widely adopted in software development... You need to collect all this information in a single file for the AI to read. Because your data is in imperial units, but AI needs metric units, must convert them. Because AI can only read CSV data in a single large file, you must load it first. If the data is in CSV format, let's put the following ETL with python and take a look at the extraction step with some simple examples.
Looking at the list of .json files and .csv. The glob file extension is preceded by a star and a dot in the entry. A list of .csv files is returned. For .json files, we can do the same. We can create a file that extracts names, heights and weights in CSV format. the file name of the .csv file is the input and the output is a data frame. For JSON formats, we can do the same.
Paso 1:
Open the notebook and import the necessary functions and modules
import glob
import pandas as pd
import xml.etree.ElementTree as ET
from datetime import datetime
Data used:
The archives dealership_data contain CSV files, JSON and XML for used car data that contains features called car_model, year_of_manufacture, price, Y fuel. So let's extract the file from the raw data and transform it into a destination file and load it into the output.
Download the source file from the cloud:
!wget https://cf-courses-data.s3.us.cloud-object-storage.appdomain.cloud/IBMDeveloperSkillsNetwork-PY0221EN-SkillsNetwork/labs/module 6/Lab - Extract Transform Load/data/datasource.zip
Extract the zip file:
nzip datasource.zip -d dealership_data
Set the path of the destination files:
tmpfile = "dealership_temp.tmp"               # store all extracted data

logfile    = "dealership_logfile.txt"            # all event logs will be stored

targetfile = "dealership_transformed_data.csv"   # transformed data is stored
Paso 2 (EXTRACTThe extract is a substance obtained by concentrating compounds of plant origin, animal or mineral. Used in a variety of applications, such as the food industry, Pharmaceutical & Cosmetics. Extracts can be presented in liquid form, in powder form or as tinctures, and its production involves techniques such as maceration, distillation or solvent extraction. Its use allows to take advantage of the beneficial properties of the original ingredients in a more way..):
Function extract will extract large amounts of data from multiple sources in batches. When adding this feature, now it will discover and load all CSV file names, and the CSV files will be added to the date frame with each iteration of the loop, with the first iteration attaching first, followed by the second iteration, resulting in a list of extracted data. Once we have collected the data, we will pass the step “To transform” of process.
Note: If he “indexThe "Index" It is a fundamental tool in books and documents, which allows you to quickly locate the desired information. Generally, it is presented at the beginning of a work and organizes the contents in a hierarchical manner, including chapters and sections. Its correct preparation facilitates navigation and improves the understanding of the material, making it an essential resource for both students and professionals in various areas.... to ignore” is set to true, the order of each row will be the same as the order in which the rows were added to the data frame.
CSV extraction function
def extract_from_csv(file_to_process):
    dataframe = pd.read_csv(file_to_process)
    return dataframe
JSON extraction function
def extract_from_json(file_to_process):
    dataframe = pd.read_json(file_to_process,lines=True)
    return dataframe
XML extraction function
def extract_from_xml(file_to_process):

    dataframe = pd.DataFrame(columns=['car_model','year_of_manufacture','price', 'fuel'])

    tree = ET.parse(file_to_process)

    root = tree.getroot()

    for person in root:

        car_model = person.find("car_model").text

        year_of_manufacture = int(person.find("year_of_manufacture").text)

        price = float(person.find("price").text)

        fuel = person.find("fuel").text

        dataframe = dataframe.append({"car_model":car_model, "year_of_manufacture":year_of_manufacture, "price":price, "fuel":fuel}, ignore_index=True)

        return dataframe
Función de extracción ():
Ahora llame a la función de extracción usando su llamada de función para CSV, JSON, XML.
def extract():
       extracted_data = pd. DataFrame(columns=['car_model','year_of_manufacture','price', 'fuel'])
    #for csv files
      for csvfile in glob.glob("dealership_data/*.csv"):
          extracted_data = extracted_data.append(extract_from_csv(csvfile), ignore_index=True)
    #for json files
      for jsonfile in glob.glob("dealership_data/*.json"):
          extracted_data = extracted_data.append(extract_from_json(jsonfile), ignore_index=True)
    #for xml files
      for xmlfile in glob.glob("dealership_data/*.xml"):
          extracted_data = extracted_data.append(extract_from_xml(xmlfile), ignore_index=True)
      return extracted_data
Paso 3 (To transform):
Once we have collected the data, pasaremos a la fase “To transform” of process. Esta función convertirá la altura de la columna, que está en pulgadas, to millimeters and the pound column, which is in pounds, to kilogram, and it will return the results in the variable data. In the input data frame, the height of the column is in feet. Convert the column to meters and round to two decimal places.
def transform(data):
       data['price'] = round(data.price, 2)
       return data
Paso 4 (loading and registration):
Time to load the data into the destination file now that we have collected and specified it. We save the pandas data frame as a CSV in this scenario. Now we have gone through the extraction steps, transforming and loading data from multiple sources into a single destination file. We need to set a registry entry before we can finish our work. We will achieve this by writing a registry function.
Charging function:
def load(targetfile,data_to_load):
    data_to_load.to_csv(targetfile)
Registration function:
All data that is entered will be added to the current information when the “a”. We can then attach a timestamp to each phase of the process, indicating when it starts and when it ends, generating this type of input. Once we have defined all the necessary code to perform the ETL process on the data, the last step is to call all functions.
def log(message):
    timestamp_format="%H:%M:%S-%h-%d-%Y"
    #Hour-Minute-Second-MonthName-Day-Year
    now = datetime.now() # get current timestamp
    timestamp = now.strftime(timestamp_format)
    with open("dealership_logfile.txt","a") as f: f.write(timestamp + ',' + message + n)
Paso 5 (Running the ETL process):
First we start by calling the function extract_data. The data received from this step will then be transferred to the second step of transforming the data. Once this is completed, the data is loaded into the destination file. What's more, note that before and after each step the start and end time and date have been added.
The record that the ETL process has started:
log("ETL Job Started")
The record that started and completed the Extract step:
log("Extract phase Started")
extracted_data = extract()
log("Extract phase Ended")
The record that started and ended the Transformation Step:
log (“Transformation phase started”)
data_transformed = transform (data_extracted)
log("Transform phase Ended")
The record that started and ended the upload phase:
log("Load phase Started")
load(targetfile,transformed_data)
log("Load phase Ended")
The ETL cycle completion record:
log("ETL Job Ended")
Through this process, we discuss some basic extraction functions, transformation and loading
- How to write a simple Extract function.
- How to write a simple transform function.
- How to write a simple load function.
- How to write a simple register function.
“No big data, you're blind and deaf and you're in the middle of a highway “. – Geoffrey Moore.
At most, we have discussed all ETL processes. What's more, let's see, “What are the benefits of data engineering job?”.
About data engineering:
Data engineering is a vast field with many names. You may not even have a formal degree at many institutions. As a result, it is generally best to start by defining the objectives of the data engineering work that lead to the expected results. The users who rely on data engineers are as diverse as the talents and results of data engineering teams.. Your consumers will always define what problems you handle and how you solve them, regardless of the sector to which it is dedicated.
About me:
Hello there, my name is Lavanya and I am from Chennai. I am a passionate writer and enthusiastic content creator. The hardest problems always excite me. I am currently studying my B. Tech in Chemical Engineering and I have a keen interest in the fields of data engineering, machine learning, data science and artificial intelligence, and I am constantly looking for ways to integrate these fields with other disciplines such as science. and chemistry to further my research goals.
Conclution:
Hope you enjoyed my article and gained an understanding of what Python is in a nutshell, which will provide you with some guidance as you begin your journey to learn data engineering. This is just the tip of the iceberg in terms of possibilities.. There are many more sophisticated topics in data engineering, for instance, to learn. But nevertheless, before we can grasp such notions, I will expand in the next article. Thanks!
The media shown in this article is not the property of DataPeaker and is used at the author's discretion.





