
This article went through a series of changes!!
I was initially writing on a different topic (relacionado con la analyticsAnalytics refers to the process of collecting, Measure and analyze data to gain valuable insights that facilitate decision-making. In various fields, like business, Health and sport, Analytics Can Identify Patterns and Trends, Optimize processes and improve results. The use of advanced tools and statistical techniques is essential to transform data into applicable and strategic knowledge....). I was almost done writing it. I had invested approximately 2 hours and written an average article. If I had done it live, I would have done well! But something in me prevented me from making it live. I was just not satisfied with the result. The article does not convey how I feel about 2015 and how useful DataPeaker could be for your analytics learning this year.
Then, I put that article in the Trash and started to rethink what topic would do justice. This is what I ended up with: let me write amazing articles and guides on what was my biggest learning in 2014: Scikit-learn or sklearn library in Python. This was my biggest learning because now it is the tool I use for whatever machine learning project I work on.
Creating these articles would not only be immensely helpful to blog readers, it would also challenge me to write about something that I am still relatively new to. I would also love to hear from you about the same: What was your biggest learning in 2014 and you would like to share it with the readers of this blog?
What is scikit-learn or sklearn?
Scikit-learn is probably the most useful library for machine learning in Python. The sklearn library contains many efficient tools for machine learning and statistical modeling, that include classification, regression, grouping and dimensionality reduction.
Note that sklearn is used to create machine learning models. It should not be used to read the data, manipulate and summarize them. There are better libraries for that (for instance, NumPy, Pandas, etc.)
Componentes de scikit-learn:
Scikit-learn comes loaded with many features. Here are some of them to help you understand the spread:
- Algoritmos de supervised learningSupervised learning is a machine learning approach where a model is trained using a set of labeled data. Each input in the dataset is associated with a known output, allowing the model to learn to predict outcomes for new inputs. This method is widely used in applications such as image classification, speech recognition and trend prediction, highlighting its importance in...: Think of any supervised machine learning algorithm you've heard of and there's a good chance it's a part of scikit-learn. From generalized linear models (for instance, linear regression), support vector machines (SVM), decision trees and Bayesian methods, all of them are part of the scikit-learn toolbox. The spread of machine learning algorithms is one of the main reasons for the high use of scikit-learn. I started using scikit to solve supervised learning problems and would also recommend it to people new to scikit / machine learning.
- Cross validation: There are several methods to verify the accuracy of monitored models on unseen data using sklearn.
- Unsupervised learning algorithms: Again, there is a wide variety of machine learning algorithms on offer, from the pool, factor analysis, principal component analysis to unsupervised neural networks.
- Multiple toy data sets: This was useful while learning scikit-learn. I had learned SAS using various academic data sets (for instance, the IRIS data set, the Boston house price dataset). Having them on hand while learning a new library helped a lot..
- Feature extraction: Scikit-learn to extract features from images and text (for instance, bag of words)
Community / organizations using scikit-learn:
One of the main reasons behind the use of open source tools is the great community it has. The same goes for sklearn too. There are around of 35 scikit-learn contributors to date, the most notable is Andreas Mueller (PS Andy machine learning cheat sheet is one of the best visualizations to understand the spectrum of machine learning algorithms).
There are several organizations like Evernote, Inria and AWeber shown in scikit learn home page as users. But I really think that the actual use is much more.
In addition to these communities, there are several meetings around the world. There was also a Kaggle knowledge contest, which ended recently, but it still might be one of the best places to start playing with the library.
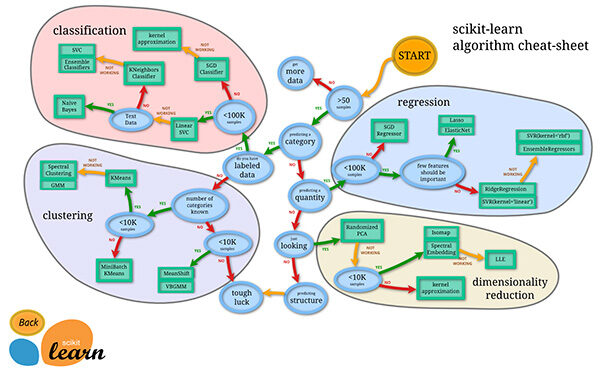
Machine Learning Cheat Sheet: consulte la imagen original para obtener una mejor resolutionThe "resolution" refers to the ability to make firm decisions and meet set goals. In personal and professional contexts, It involves defining clear goals and developing an action plan to achieve them. Resolution is critical to personal growth and success in various areas of life, as it allows you to overcome obstacles and keep your focus on what really matters....
Quick example:
Now that you understand the ecosystem at a high level, let me illustrate the use of sklearn with an example. The idea is simply to illustrate the simplicity of use of sklearn. We will look at various algorithms and the best ways to use them in one of the articles that follow..
We will construct a logistic regression on the IRIS dataset:
Paso 1: import the relevant libraries and read the dataset
import numpy as np
import matplotlib as plt
from sklearn import datasets
of sklearn import metrics
de sklearn.linear_model import LogisticRegression
We have imported all the libraries. Then, we read the data set:
dataset = datasets.load_iris ()
Paso 2: Understand the data set by looking at distributions and diagrams
I'm skipping these steps for now. You can read this article if you want to learn exploratory analysis.
Paso 3: build a logistic regression model on the data set and make predictions
model.fit (dataseta "dataset" or dataset is a structured collection of information, which can be used for statistical analysis, Machine learning or research. Datasets can include numerical variables, categorical or textual, and their quality is crucial for reliable results. Its use extends to various disciplines, such as medicine, economics and social science, facilitating informed decision-making and the development of predictive models.....data, dataset.target)
expected = dataset.target
predicted = model.predict (dataset.data)
Paso 4: Print the confusion matrix
print (metrics.classification_report (expected, foretold))
print (metrics.confusion_matrix (expected, foretold))
Final notes:
This was an overview of one of Python's most powerful and versatile machine learning libraries. It was also the biggest learning I did in 2014. What was your greatest learning in 2014? Share it with the group through the comments below.
Are you excited to learn and use Scikit-learn? If so, stay tuned for the remaining articles in this series.
A quick reminder: if you have not checked out Analytical Vidhya Discuss but nevertheless, you should do it now. Users are joining fast, so take whatever username you want before someone else picks it up.





