
R Are you ready? Let's learn to group in R.
http: // www.pags: //www.rstudio.com/products/rstudio/download/
Data visualization using R
In present times, pictures speak louder than numbers or word analysis. Yes, graphs and diagrams are more attractive and easy to identify for the human eye. This is where the importance of R data analysis comes in.. Clients better understand the graphical representation of their growth / evaluation / product distribution. Therefore, data science is booming nowadays and R is one of those languages that provides flexibility in plotting and graphics, as it has specific functions and packages for such tasks. RStudio is software where data and visualization happen side by side, which makes it very favorable for a data analyst. Scatter diagrams, box plotsBox Diagrams, Also known as box and whisker diagrams, are statistical tools that represent the distribution of a dataset. These diagrams show the median, quartiles and outliers, allowing data variability and symmetry to be visualized. They are useful in comparison between different groups and in exploratory analysis, making it easier to identify trends and patterns in the data...., bar graphs, line charts, line charts, heat maps, etc. are possible in R with just a simple function, for instance: the histogram can be plotted using the hist function (data name) with parametersThe "parameters" are variables or criteria that are used to define, measure or evaluate a phenomenon or system. In various fields such as statistics, Computer Science and Scientific Research, Parameters are critical to establishing norms and standards that guide data analysis and interpretation. Their proper selection and handling are crucial to obtain accurate and relevant results in any study or project.... as xlab (x tag), color, should, etc.
Taking advantage of this convenience, let's move to a method of Unsupervised learningUnsupervised learning is a machine learning technique that allows models to identify patterns and structures in data without predefined labels. Through algorithms such as k-means and principal component analysis, This approach is used in a variety of applications, such as customer segmentation, anomaly detection and data compression. Its ability to reveal hidden information makes it a valuable tool in the...: clustering.
Supervised and unsupervised learning
There are two types of learning in data analysis: supervised learningSupervised learning is a machine learning approach where a model is trained using a set of labeled data. Each input in the dataset is associated with a known output, allowing the model to learn to predict outcomes for new inputs. This method is widely used in applications such as image classification, speech recognition and trend prediction, highlighting its importance in... and unsupervised.
Supervised learning – The tagged data is an input to the learning machine. Regression, the classification, decision trees, etc. are supervised learning methods.
Supervised learning example:
Linear regression is where there is only one variableIn statistics and mathematics, a "variable" is a symbol that represents a value that can change or vary. There are different types of variables, and qualitative, that describe non-numerical characteristics, and quantitative, representing numerical quantities. Variables are fundamental in experiments and studies, since they allow the analysis of relationships and patterns between different elements, facilitating the understanding of complex phenomena.... dependent. Equation: y = mx + c, y depends on x.
For instance: the age and girth of a tree are the 2 labels as input dataset, the machine needs to predict the age of a tree with a circumference as input after knowing the data set that was fed. Age depends on circumference.
Therefore, learning is monitored on the basis of labels.
Unsupervised learning – The unlabeled data is sent to the machine to find a pattern on its own. Clustering is an unsupervised learning method that has models: KMeans, hierarchical grouping, DBSCAN, etc.
The visual representation of the clusters shows the data in an easily understandable format, as it groups elements of a large data set according to their similarities. This makes analysis easier. But nevertheless, unsupervised learning is not always accurate and is a complex process for the machine, since the data is not labeled.
Let's now continue with an example of groupingThe "grouping" It is a concept that refers to the organization of elements or individuals into groups with common characteristics or objectives. This process is used in various disciplines, including psychology, Education and biology, to facilitate the analysis and understanding of behaviors or phenomena. In the educational field, for instance, Grouping can improve interaction and learning among students by encouraging work.. using the Iris flower dataset.
Grouping
Clusters they are a group of the same elements or elements such as a cluster of stars or a cluster of grapes or a cluster of nets and so on …
Using clustering in the real world:
It is used in e-commerce sites to form customer groups based on their profile such as age, sex, spending, regularity, etc. It is useful in marketing and sales, as it helps to group the target audience of the product. Spam filtering in emails and many more are real-world clustering applications.
Clustering in R refers to the assimilation of the same type of data into groups or clusters to distinguish one group from the others. (collection of the same type of data). This can be represented in graphical format through R. We use the KMeans model in this process.
What is the K Means algorithm?
K Means is a clustering algorithm that repeatedly assigns a group among the k groups present to a data point according to the characteristics of the point. It is a grouping method based on centroids.
The number of clusters is decided, cluster centers are randomly selected farthest from each other, the distance between each data point and the center is calculated using the Euclidean distance, the data point is assigned to the cluster whose center is closest to that point. This process is repeated until the center of the groups does not change and the data points remain in the same group..
This is all theory, but in practice, R has a bundling package that calculates the steps above.
Paso 1
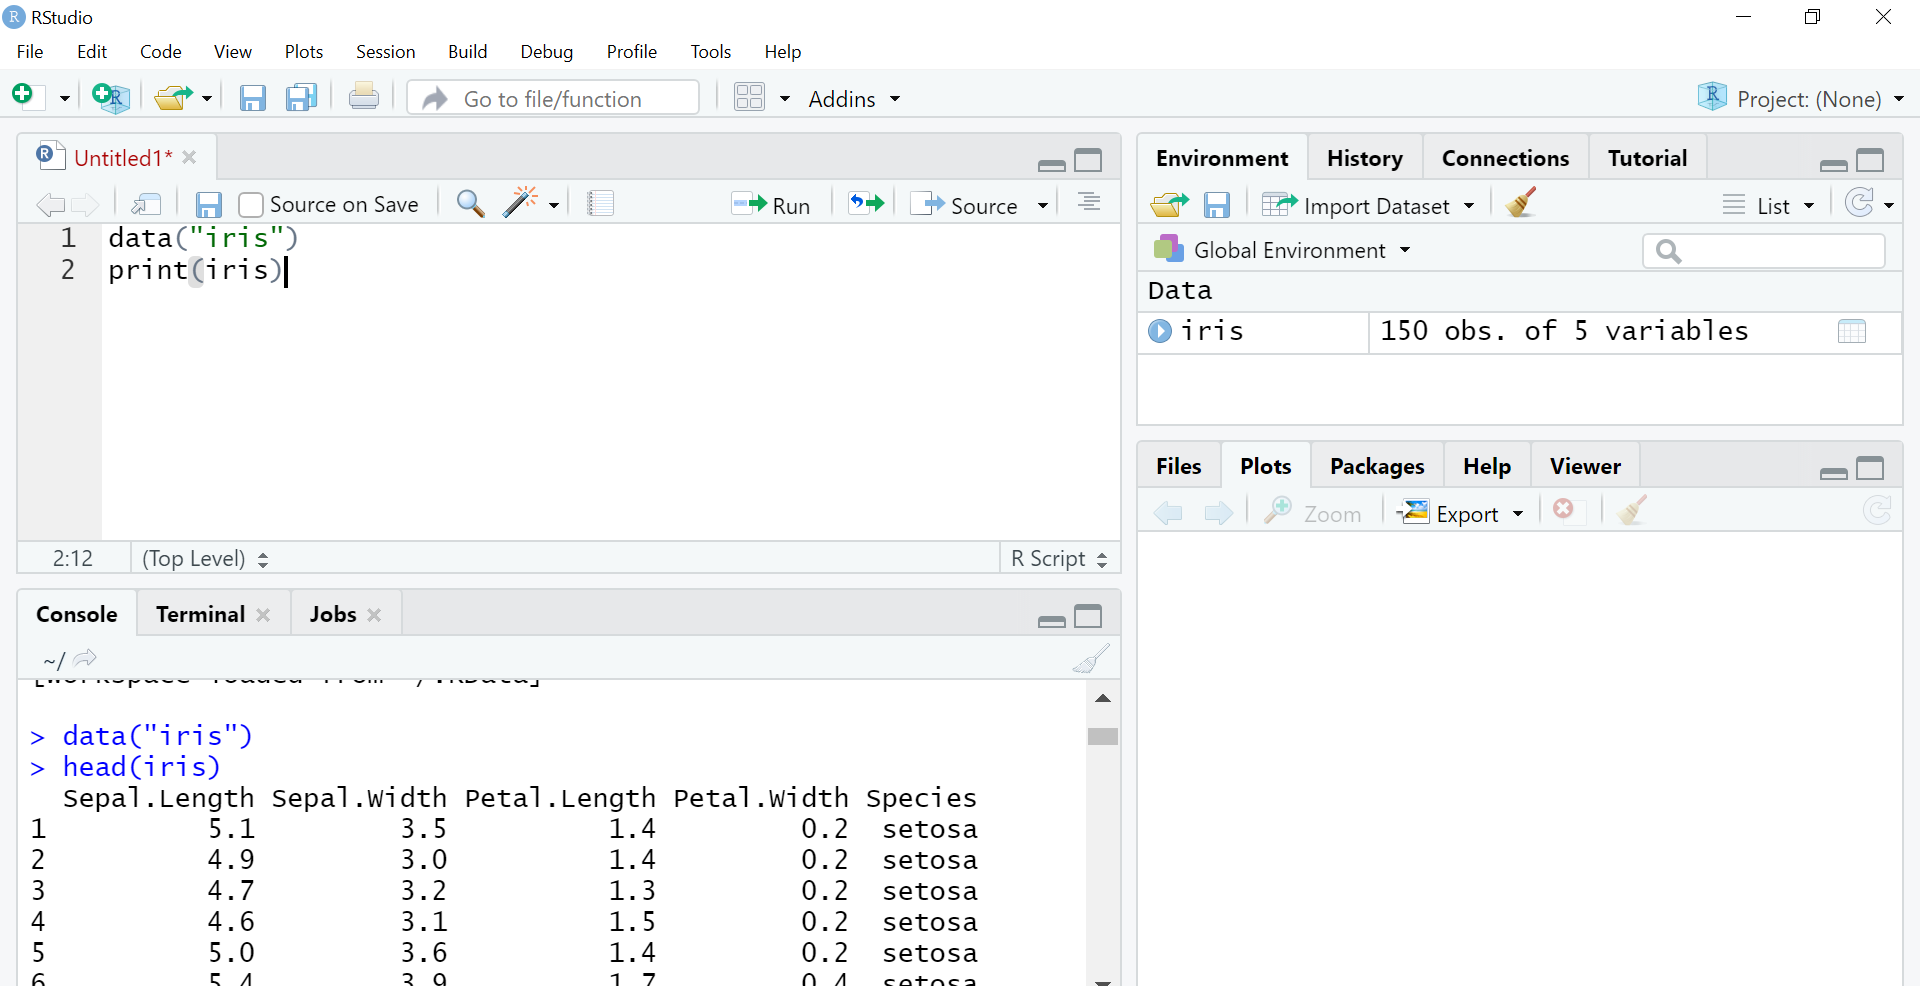
I will work on the Iris dataset, which is a built-in dataset in R using the Cluster package. Has 5 columns, namely: sepal length, sepal width, petal length, petal width and species. Iris is a flower and here in this dataset they are mentioned 3 of its species Setosa, Versicolor, Verginica. We will group the flowers according to their species. The code to load the dataset:
data("iris")
head(iris) #will show top 6 rows only
Paso 2
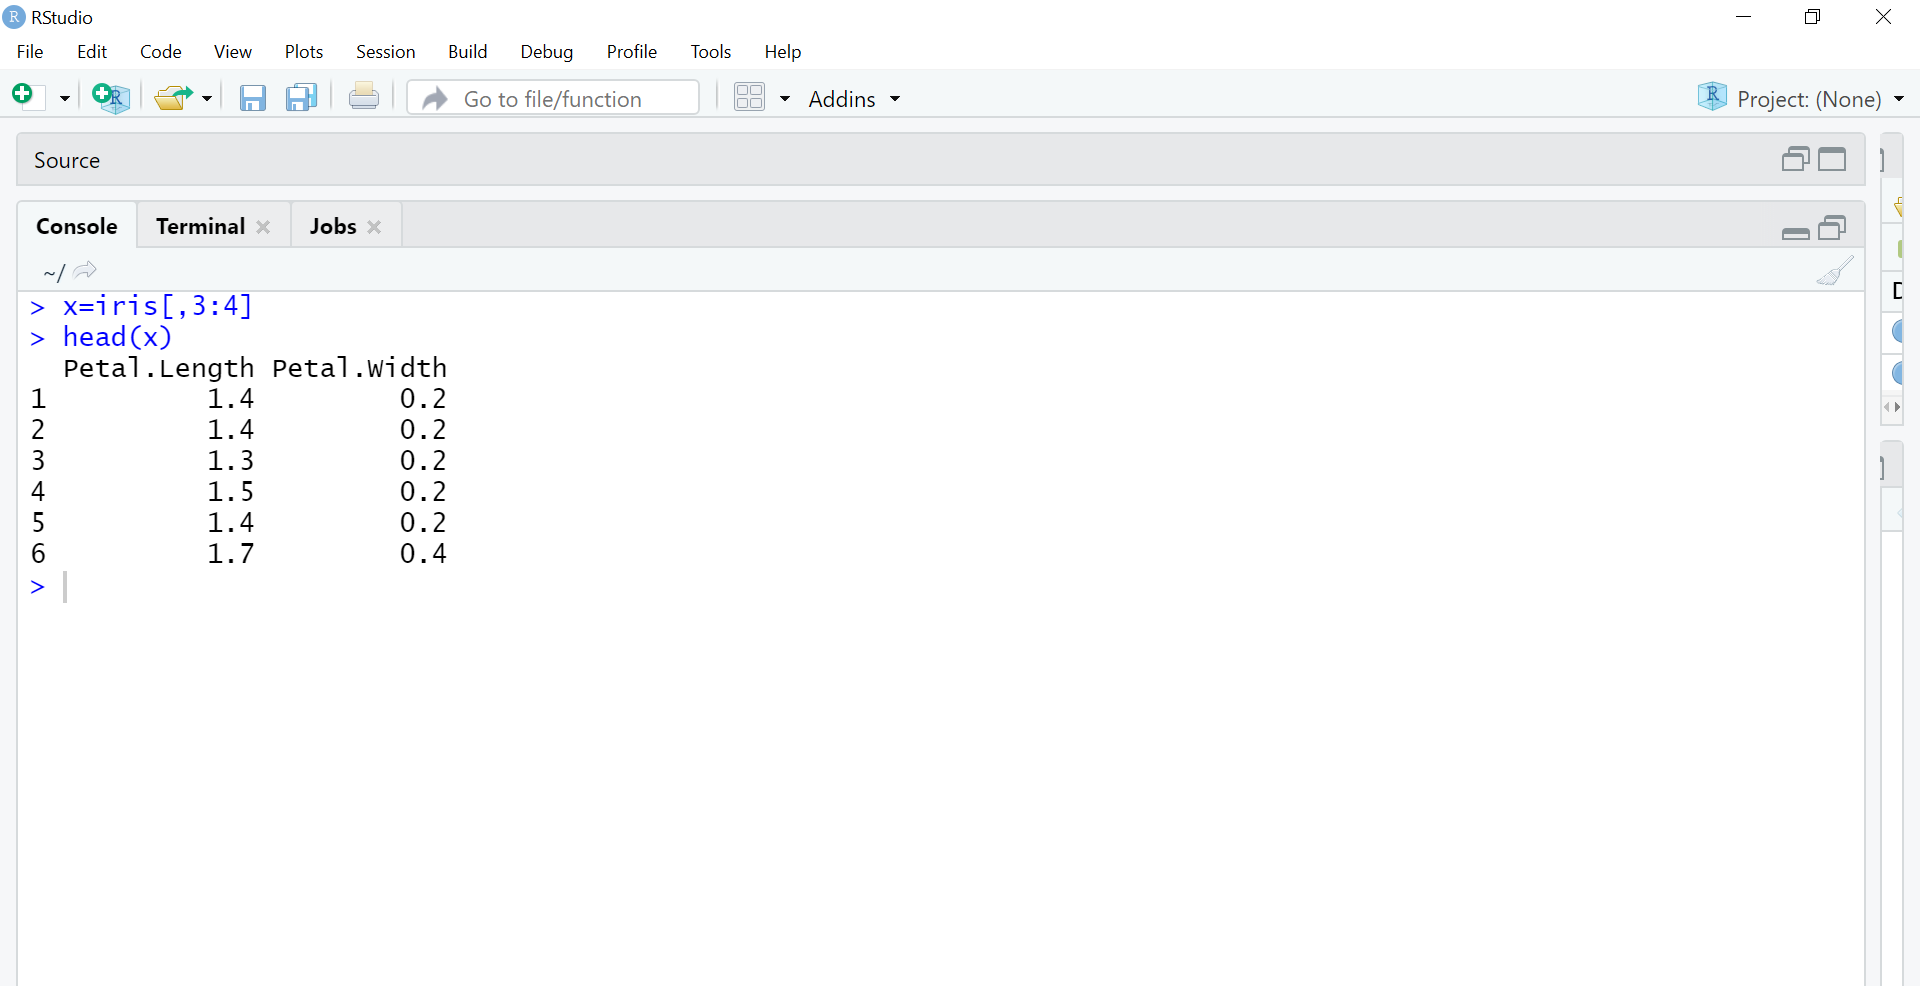
The next step is to separate the columns 3 Y 4 in a separate x object, since we are using the unsupervised learning method. We are removing labels for the machine to use the huge input of petal length and width columns for unattended grouping.
x = iris[,3:4] #using only petal length and width columns
head(x)
Paso 3
The next step is to use the K Means algorithm. K Means is the method we use that has parameters (data, no. From clusters to groups). Here our data is the object x and we will have k = 3 groups, since there are 3 species in the dataset.
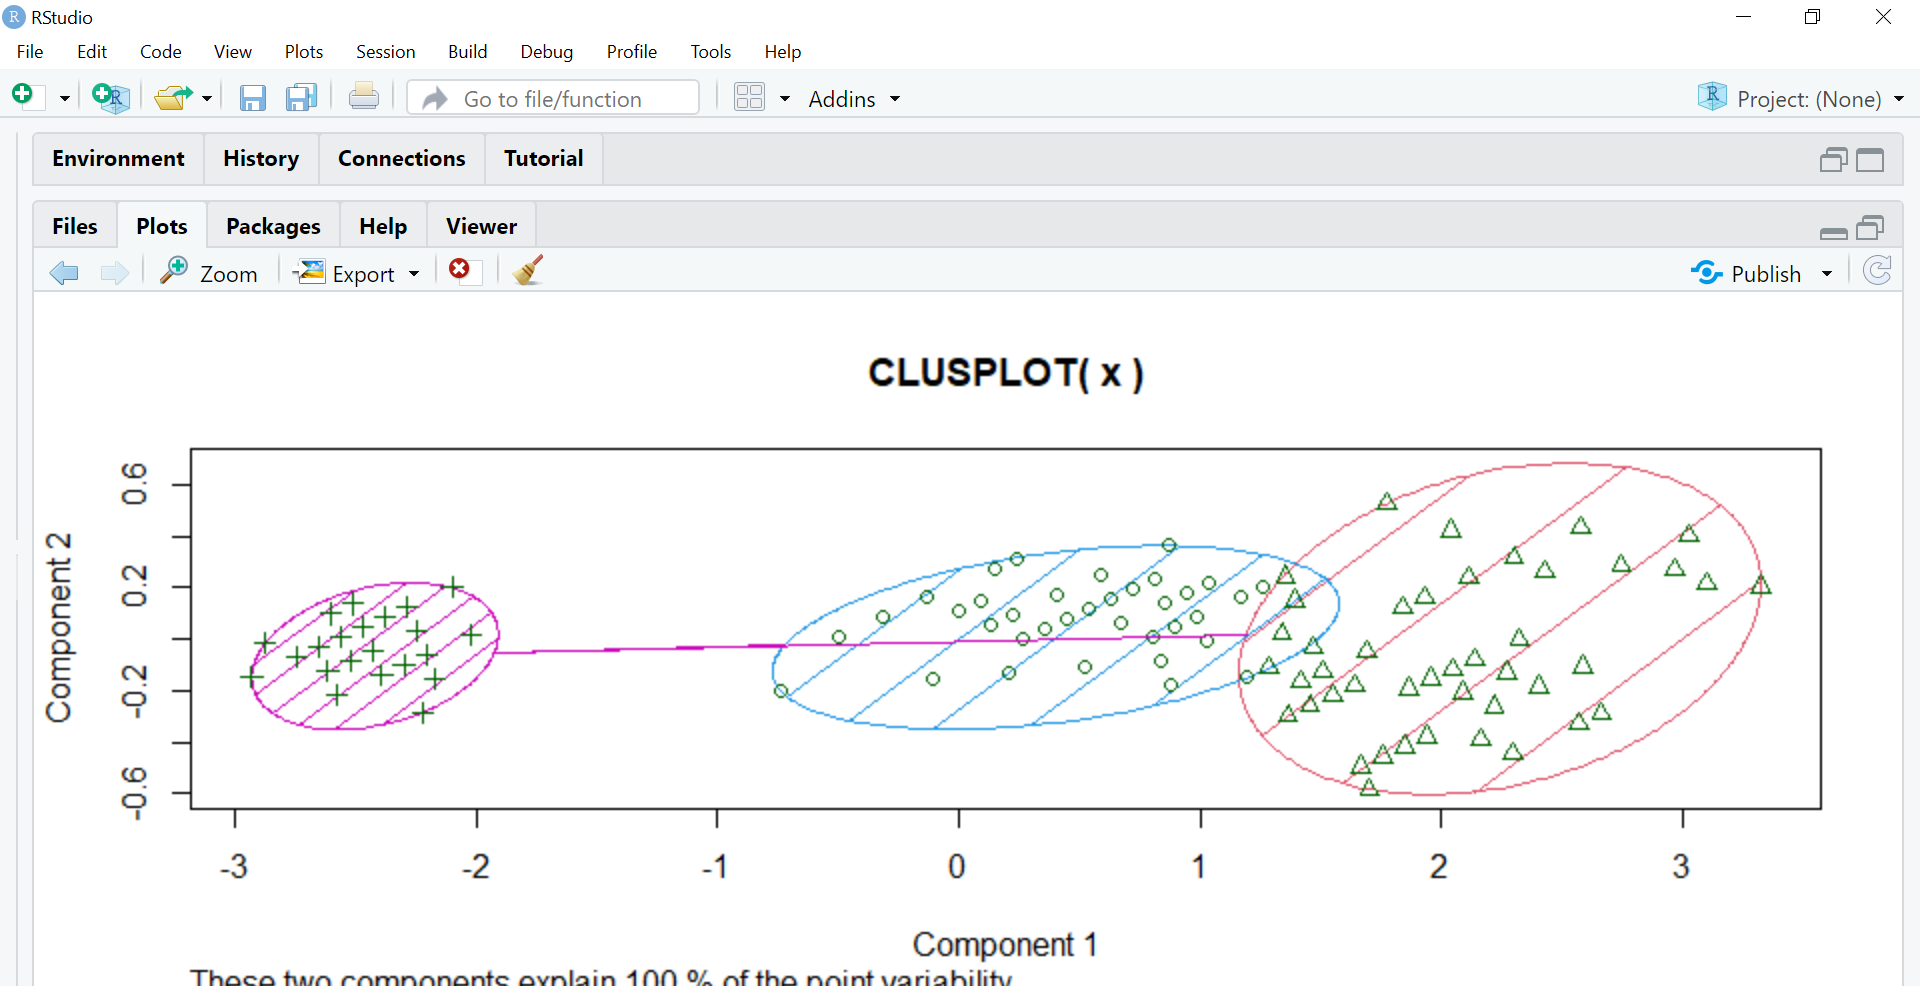
So he ‘cluster package is named. Clustering in R is done using this built-in package which will do all the math. The Clusplot function creates a 2D plot of the clusters.
model=kmeans(x,3)
 library(cluster)
clusplot(x,model$cluster)
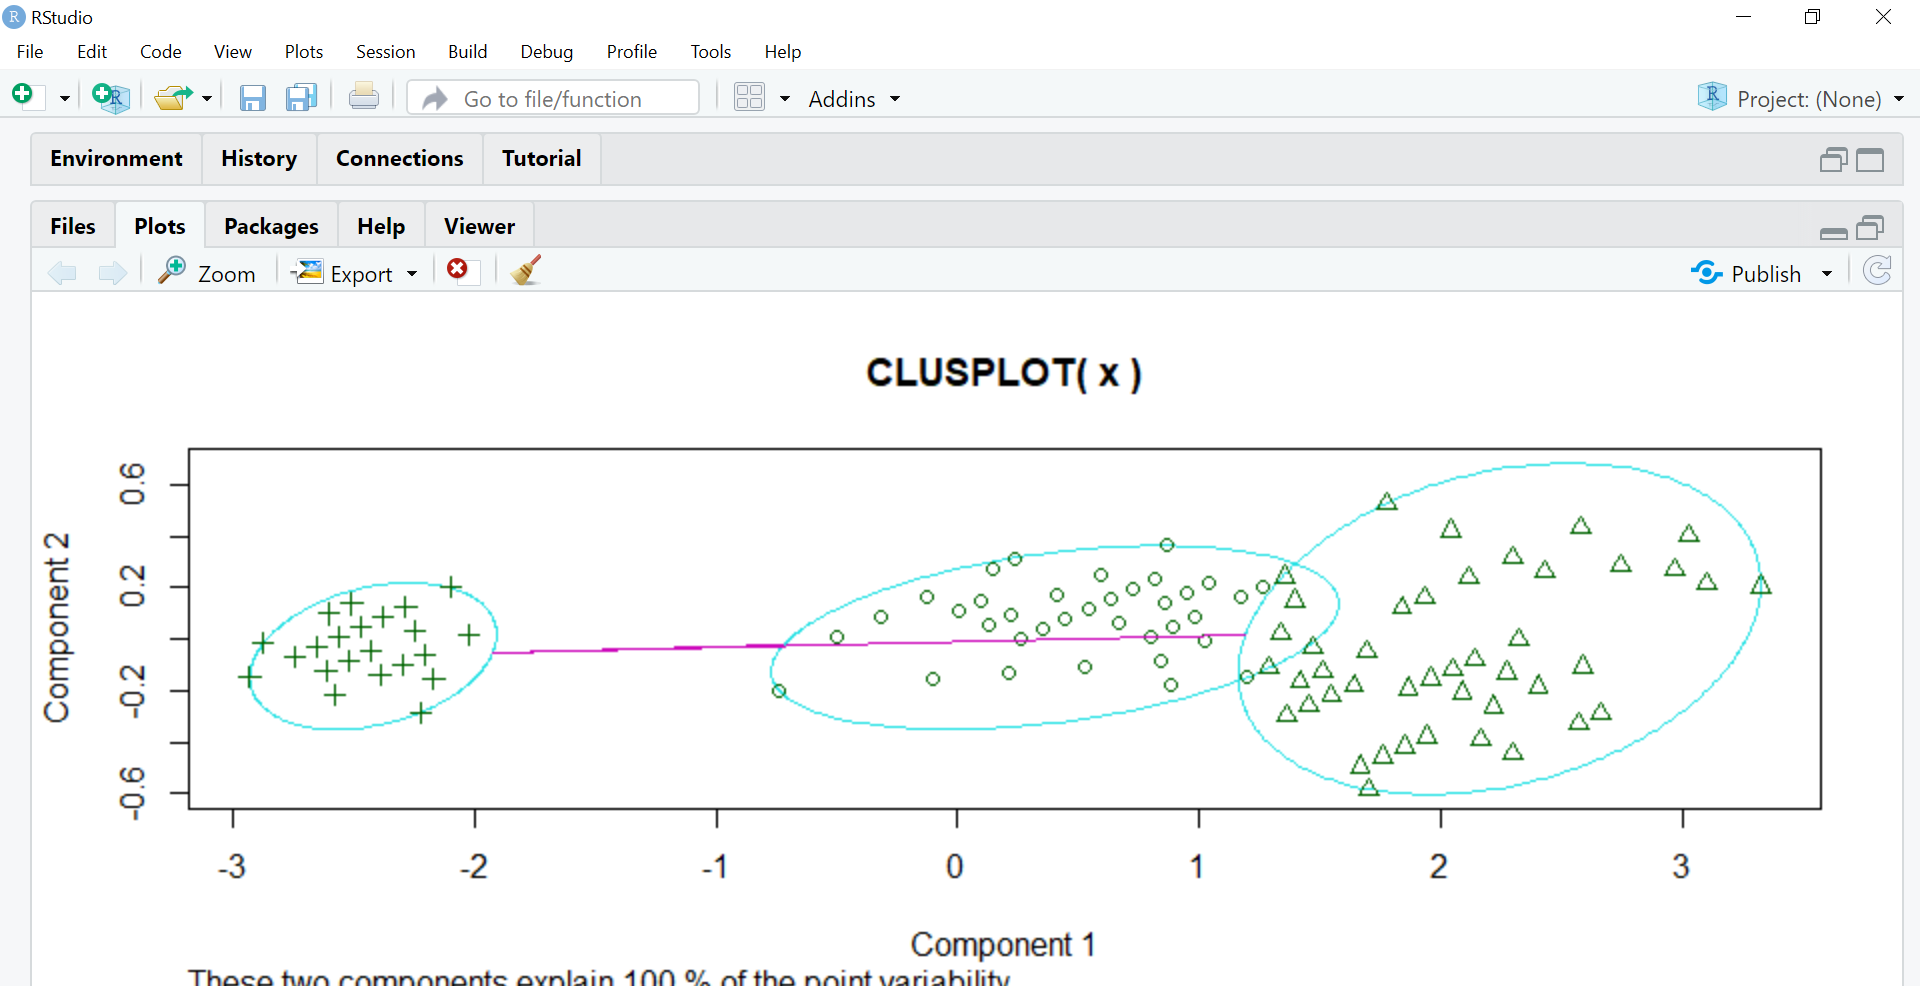
The component 1 and the component 2 seen in the graph are the two components of PCA (principal component analysis), which is basically a feature extraction method that uses the important components and removes the rest. Reduces the dimensionality of the data to facilitate the application of KMeans. All of this is done by the package of clusterA cluster is a set of interconnected companies and organizations that operate in the same sector or geographical area, and that collaborate to improve their competitiveness. These groupings allow for the sharing of resources, Knowledge and technologies, fostering innovation and economic growth. Clusters can span a variety of industries, from technology to agriculture, and are fundamental for regional development and job creation.... an R.
These two components explain the variability of the 100% at the exit, which means data object x fed to PCA was accurate enough to form clear groups using KMeans and there is minimal overlap (insignificant) among them.
Paso 4
The next step is to assign different colors to the groups and shade them, Thus, we use the color and shadow parameters by setting them to T, what true means.
clusplot(x,model$cluster,color=T,shade=T)
Conclution
This all sums up the basics of clustering in R. Here I use a built-in dataset, but imported datasets can also be used for clustering. For instance: group site users based on favored items, etc. It is very useful for making business comparisons.
Import datasets into R:
dataset <- read.csv("path.csv")
View(dataset)
attach(dataset)
Thanks for taking the time and reading this article.,Feel free to comment what can be improved, since learning is a daily process.aftereverybody..
ConnectwithmeaboutLinkedIn:https://www.linkedin.com/in/akansha-bose-149b14164/
The media shown in this article is not the property of DataPeaker and is used at the author's discretion.





